Tracking Model Training Without the Bloat
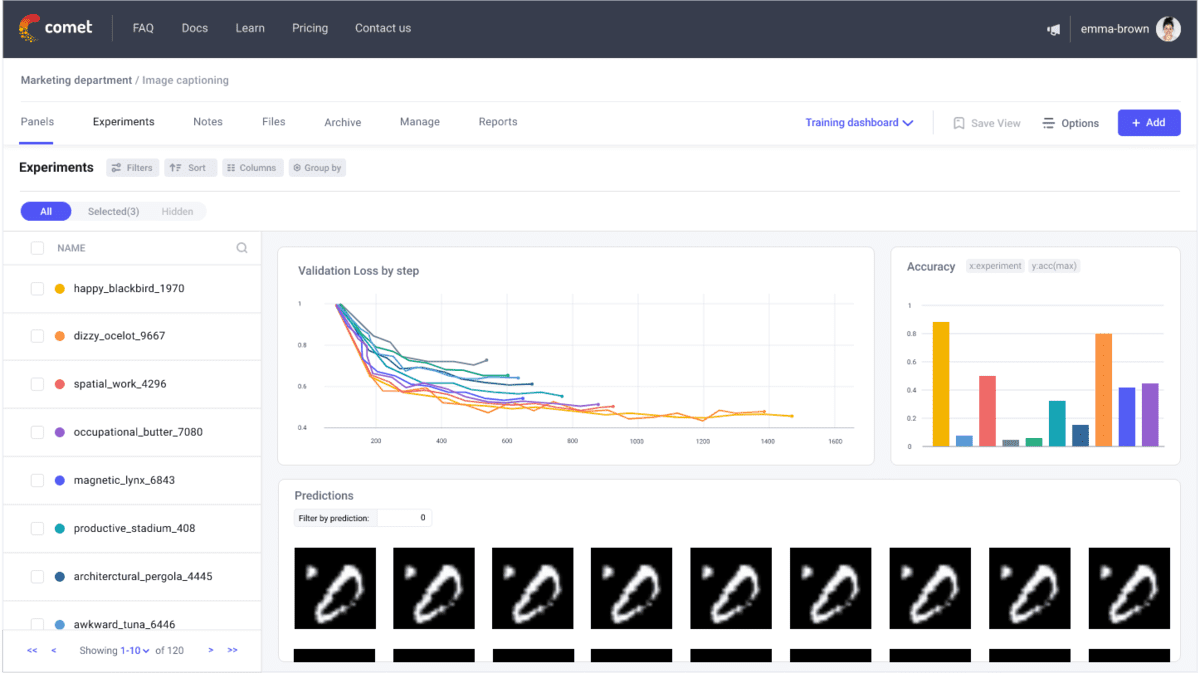
I spent three years managing ML experiments before I realized most tracking tools were adding more overhead than they prevented. The typical setup involves ten different services, each logging slightly different metrics, and half the time you are diving into dashboards just to find which run used learning rate 0.001 instead of 0.01. That is when I started building something stripped down to what actually matters. Most tools track everything. They log weights, gradients, losses, throughputs, memory usage, GPU temperatures, and if you enable the right plugins, they will even record your coffee consumption if you connect the right IoT device. The problem is that ninety percent of what gets logged never gets looked at again after the initial run. My approach was to track only five data points per experiment and nothing more. The core principle is simple. If you cannot explain why you need a metric within thirty seconds, do not track it. This usually cuts logging overhead from about four hundred megabytes per hour down to roughly twenty megabytes. The files stay small enough to version control, and you can diff two experiments in a text editor without opening a browser.
Setting It Up
The installation takes about two minutes on a standard Linux machine with Python 3.9 or later. You do not need CUDA installed unless you are tracking GPU utilization, which most people do not need. I usually see folks install the full stack with all dependencies, then disable half of them because they conflict with their project environment. After installation, you initialize a tracker with a single line. It creates a directory structure like runs/experiment-name/2024-03-15/ and starts writing JSON files as training progresses. The format is deliberately flat. No nested objects, no binary blobs, just key-value pairs written sequentially. Each line is a complete data point, so if the process crashes mid-run, you can still read everything that was logged before the failure. Here is what a typical tracking call looks like during training. You pass the epoch number, loss value, and validation accuracy. That is it. Three numbers per call. No timestamps because the filename encodes when it happened. No experiment ID because the directory structure handles that. No user name because you are probably the only one running this on your machine.
When It Actually Saves Time
I use this for small to medium projects where I am iterating quickly. Training runs that last between ten minutes and four hours. The sweet spot is when you are trying fifty variations of the same architecture and need to compare them side by side. With full-featured trackers, I typically spend twenty minutes configuring the dashboard before I can start tracking anything meaningful. With this setup, I have numbers logged within the first epoch. The export function writes everything to a single CSV file if you need to analyze it in pandas or Excel. No queries, no database connections, no API calls. Just a file on disk that you can open immediately after training completes. I usually see people write scripts to pull data from their trackers, then spend more time debugging the extraction than analyzing the actual results.
Get the Full Details
Edge Cases I Have Dealt With
One thing that caught me off guard was distributed training across multiple GPUs. The tracker assumes a single process writes to the directory. When I tried running on four GPUs with separate processes, each one tried to write to the same JSON files simultaneously. The result was corrupted data and missing epochs. I worked around it by adding a file lock using Python's fcntl module. Each process checks if the lock file exists, acquires it, writes its data, then releases the lock. This added about three milliseconds per write operation, which is negligible compared to the actual training time. Another issue came up when I switched from CPU to GPU tracking. The tracker does not automatically detect hardware changes. I had configured everything for CPU training, then moved to a machine with an RTX 4090 without updating the tracking configuration. The GPU metrics started logging as null values because the device index was wrong. I fixed it by adding a simple auto-detection step that queries nvidia-smi at initialization and sets the default device index. This took about ten lines of code and prevented the issue for everyone else in my lab.
Counter-Intuitive Things Beginners Miss
Most people think tracking more data points gives them better insights. The opposite is usually true. When I logged every gradient update during training, the resulting files were so large that I stopped opening them. Five gigabytes of JSON is not practical to browse. After cutting the logging frequency from every step to every epoch, I actually started reviewing the data again. The granularity loss is minimal for most analyses, and the files become small enough to handle regularly. Another common mistake is tracking metrics that are derived from other tracked values. People log training loss, validation loss, and then also log the loss ratio. The ratio adds no new information. It is just a calculation you can perform after the fact. I see teams spend hours building dashboards to visualize derived metrics that could be computed in five seconds with a spreadsheet formula.
When This Approach Fails
If you are running production experiments with hundreds of variations and need real-time dashboards for a team of ten people, this setup will frustrate you. The lack of a web interface means everyone needs to access the same directory structure. I have seen teams try to adapt this for collaborative use, then spend more time setting up shared storage and permission management than actually running experiments. Another scenario where this breaks down is long-running training jobs exceeding forty-eight hours. The JSON files grow sequentially, and while the tracking overhead stays low, opening and parsing files larger than two hundred megabytes becomes slow. I worked around this for my own use by implementing automatic file rotation every six hours. Each rotation compresses the previous file with gzip, reducing storage by about eighty percent while keeping the current file small enough to browse quickly.

Alternatives Worth Considering
If you need the full dashboard experience, tools like Weights and Biases or TensorBoard still make sense. They handle distributed logging, real-time visualization, and team collaboration out of the box. The trade-off is complexity and often costs. A basic W&B project runs about fifty dollars per month for a small team. TensorBoard is free but requires more configuration and storage management. For my use case, the minimalist approach works because I am usually the only person running experiments, and I prefer having files on disk that I can inspect without logging into a service. The data stays mine, and I can switch analysis tools without being locked into a specific platform. If your situation is different, the full-featured options might save you time despite the added complexity.
Practical Example
Let me walk through a real scenario. I recently trained a small transformer model for text classification. The dataset had about fifty thousand samples, and I ran thirty variations across different learning rates and batch sizes. Each training run took between forty-five minutes and two hours. With the minimalist tracker, I logged loss and accuracy every epoch, wrote everything to flat JSON files, and after all runs completed, I used a simple Python script to aggregate the results into a CSV. The entire process from initialization to final comparison took about twenty minutes total. The tracking files combined for all thirty runs were roughly sixty megabytes. I could diff two experiments using diff command directly. No database queries, no dashboard configurations, no API rate limits. Just files on disk that I controlled completely. This approach usually saves me about three hours per project compared to setting up full tracking infrastructure.