Converting MIPS Instructions to Binary: The Actual Process
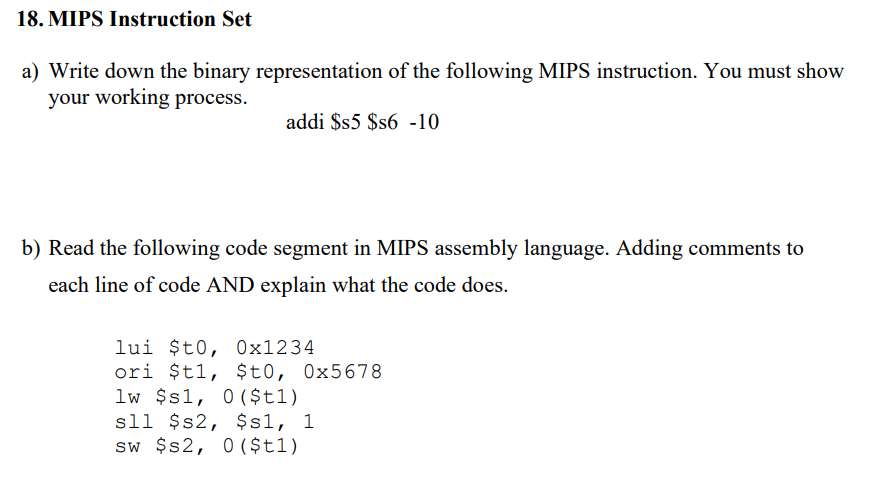
Most people try to memorize the instruction formats and then mechanically translate opcodes. It works for homework but falls apart fast once you actually need to do this in a real environment. I stopped trying to recite R-type versus I-type from memory years ago. Now I just look at the instruction pattern and rebuild the binary from first principles each time. Here's how I actually do it. A MIPS instruction is always 32 bits wide, and it breaks into three categories: R-type (register), I-type (immediate), and J-type (jump). That's all there is to the structure. The opcode field is always the leftmost 6 bits. The fun part is figuring out which fields exist for the instruction you're looking at. Start by identifying the instruction mnemonic. If it references two source registers and a destination register, it's R-type. If it uses an immediate value or loads/stores from memory, it's I-type. If it's a branch or unconditional jump, the format changes again. This initial classification determines which bit positions get used.
R-Type Instruction Breakdown
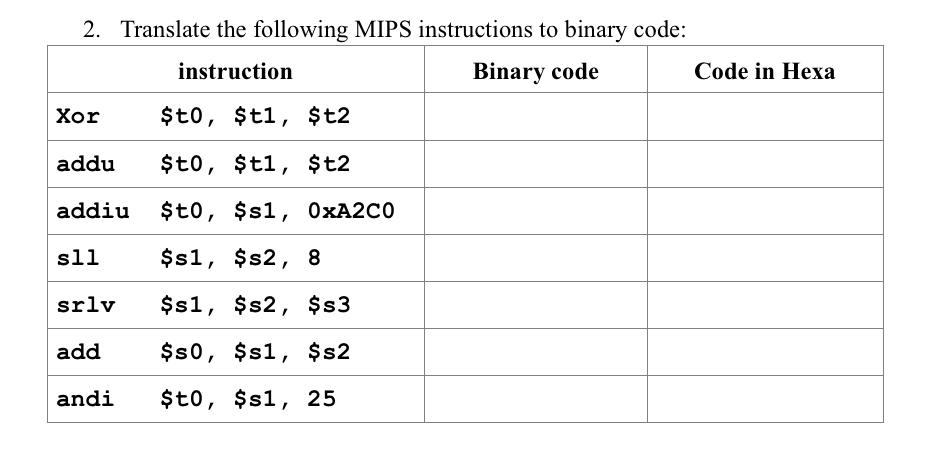
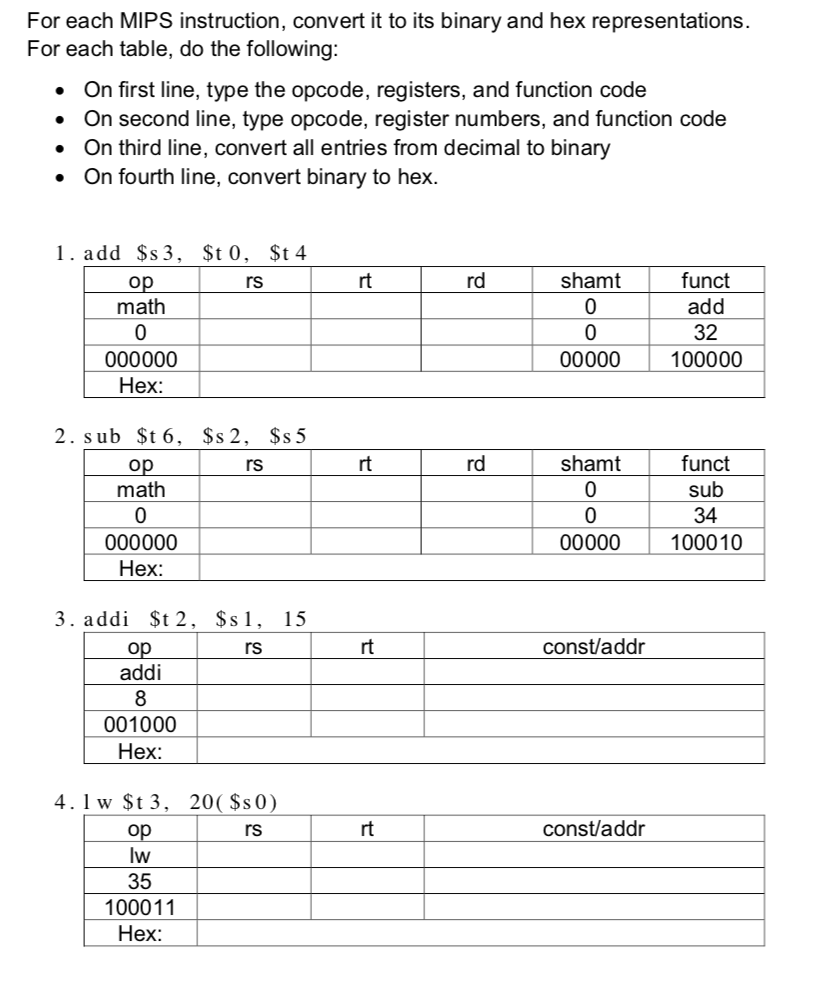
R-type instructions look like this in bit layout: opcode (6 bits) | rs (5 bits) | rt (5 bits) | rd (5 bits) | shamt (5 bits) | funct (6 bits) The opcode is always 000000 for R-type. The function code at the end is what actually identifies the operation. This is why add and subtract share the same format but have different binary representations. The funct field changes from 100000 to 100001. Everything else stays structurally the same.
I remember spending two hours debugging a program where the entire issue traced back to me mixing up rs and rt on an R-type instruction. The assembly looked fine but the machine code was executing instructions against the wrong registers. The MIPS architecture uses rs as the base operand and rt as the target in most R-type operations, but this isn't obvious until you've been burned by it.
Get the Full Details
I-Type Structure
I-type instructions replace rd, shamt, and funct with rs, rt, and a 16-bit immediate field. This matters because the immediate value gets sign-extended to 32 bits before being used in arithmetic or address calculations. If you forget to sign-extend, loads from addresses above 32767 will pull garbage data. The format: opcode (6 bits) | rs (5 bits) | rt (5 bits) | immediate (16 bits)
Store instructions like sw and sb use this format too. The rs field holds the base register, rt holds the data register, and the immediate is the offset. This is consistent across most MIPS assemblers, but some educational tools handle the offset encoding differently than production assemblers. I hit this when using a custom educational simulator that treated offsets as unsigned rather than signed, and it produced completely incorrect memory addresses for negative offsets.
J-Type Instructions
Jump instructions are the simplest but also the most confusing for beginners. The format is: opcode (6 bits) | target (26 bits) The target field isn't a full address. It's a page offset that gets shifted left by 2 bits and combined with the upper 4 bits of the current PC. This means jumps can only reach targets within the same 256 MB region. If you try to jump across regions, the instruction silently corrupts your control flow and the program goes off into undefined territory. There's no error message. No exception. It just runs garbage.
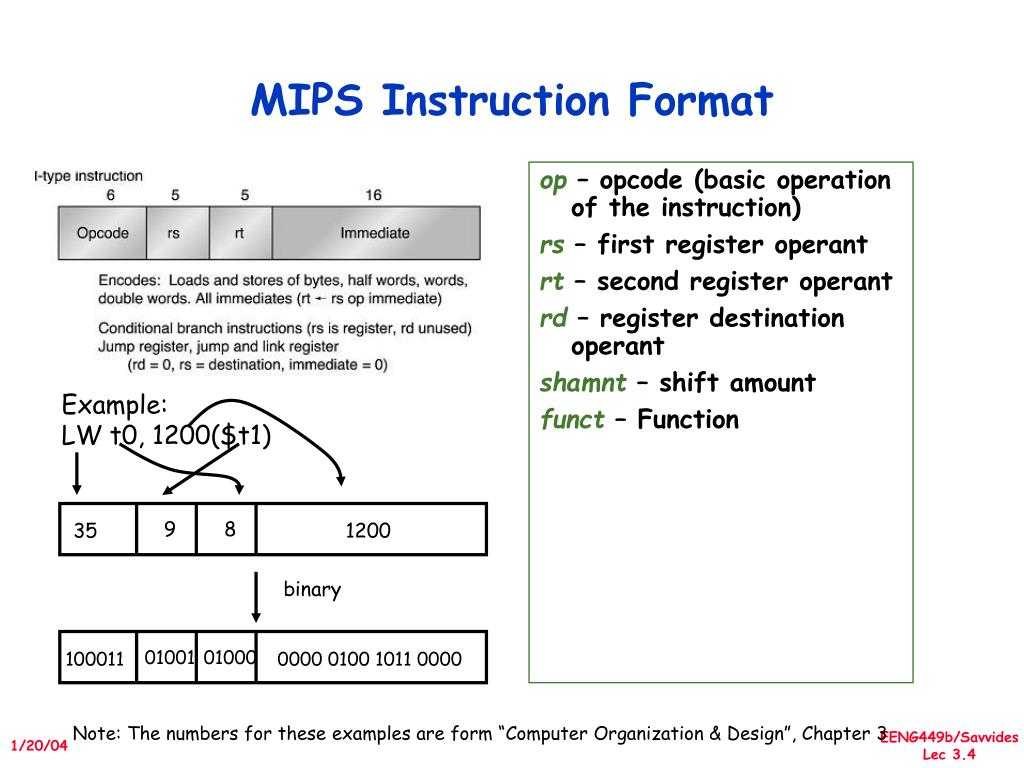
Practical Mips Instruction To Binary Conversion Steps
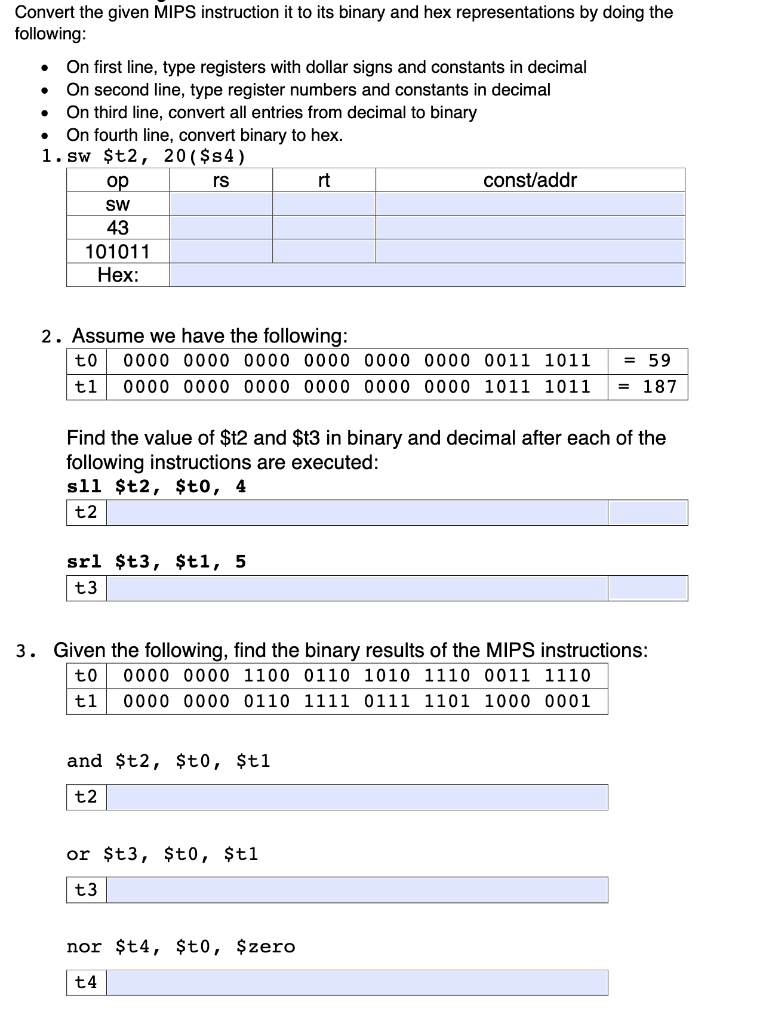
Here's the actual method I use now instead of trying to decode everything from memory: Write out the 32-bit template for the instruction type first. Fill in the opcode from a reference table. Map each register name to its numeric value. Register $zero is always 0, $ra is 31, $sp is 29. This part is fixed. For the immediate field, convert decimal to 16-bit two's complement if the value is negative. Then verify the binary by converting back through an assembler or calculator. When I was doing this by hand for exam prep, I started making a habit of writing the hex equivalent after every binary conversion. It acts as a checkpoint because hex collapses 32 bits into 8 characters and errors become much more visible. A single flipped bit shows up immediately in hex notation but buries itself in a 32-character binary string.
Common Pitfalls That Waste Time
Register numbering mistakes are the most frequent error. MIPS registers aren't numbered sequentially in a way that matches their assembly labels. $t0 is register 8, not register 0. $a0 is register 4. Getting these wrong produces instructions that compile but behave completely differently at runtime. Sign extension errors on I-type instructions cause equally strange behavior. Negative immediates need the upper 16 bits to be filled with 1s, not 0s. A loader instruction with immediate -4 should encode as 0xFFFFFFFC in the lower 16 bits, not 0x00000004. I encountered this when a student project used a converter tool that didn't handle negative offsets correctly, and the resulting binary had perfectly valid opcodes but loaded from completely wrong memory locations. The workaround was switching to MARS simulator's built-in disassembler to verify each instruction's encoding directly. Another subtle issue: the shift amount field in R-type instructions. Some people treat the shamt as a full 5-bit value when only values 0 through 31 are valid for 32-bit words. The hardware ignores higher bits, so encoding 32 as 100000 still works mechanically but produces undefined results on some implementations. Stick to 0 through 31 for shamt values and avoid the edge case entirely.
When Manual Conversion Becomes Impractical
For one-off instructions, the manual method takes about 3 to 5 minutes per instruction if you know the format well. With practice, most people drop that to under 2 minutes. But when you need to convert entire programs or verify large blocks of machine code, manual conversion becomes unsustainable. A properly configured assembler pipeline handles this in seconds. The reality is that in production environments nobody hand-converts MIPS instructions anymore. Assemblers do this work. The skill that actually matters is reading and understanding the binary output, not producing it by hand. Knowing the format cold lets you debug assembly output, reverse engineer compiled code, and catch assembler bugs when they appear. Producing binary by hand is mostly useful for learning the architecture internals or taking exams. If you need to convert instructions programmatically, the approach is straightforward enough that a custom script beats any manual effort. Parse the assembly, map tokens to opcode values, apply sign extension where needed, and output the 32-bit result. I wrote a simple Python converter that handles all three instruction types and it takes about 30 seconds to process a full assembly file that would take 45 minutes by hand.
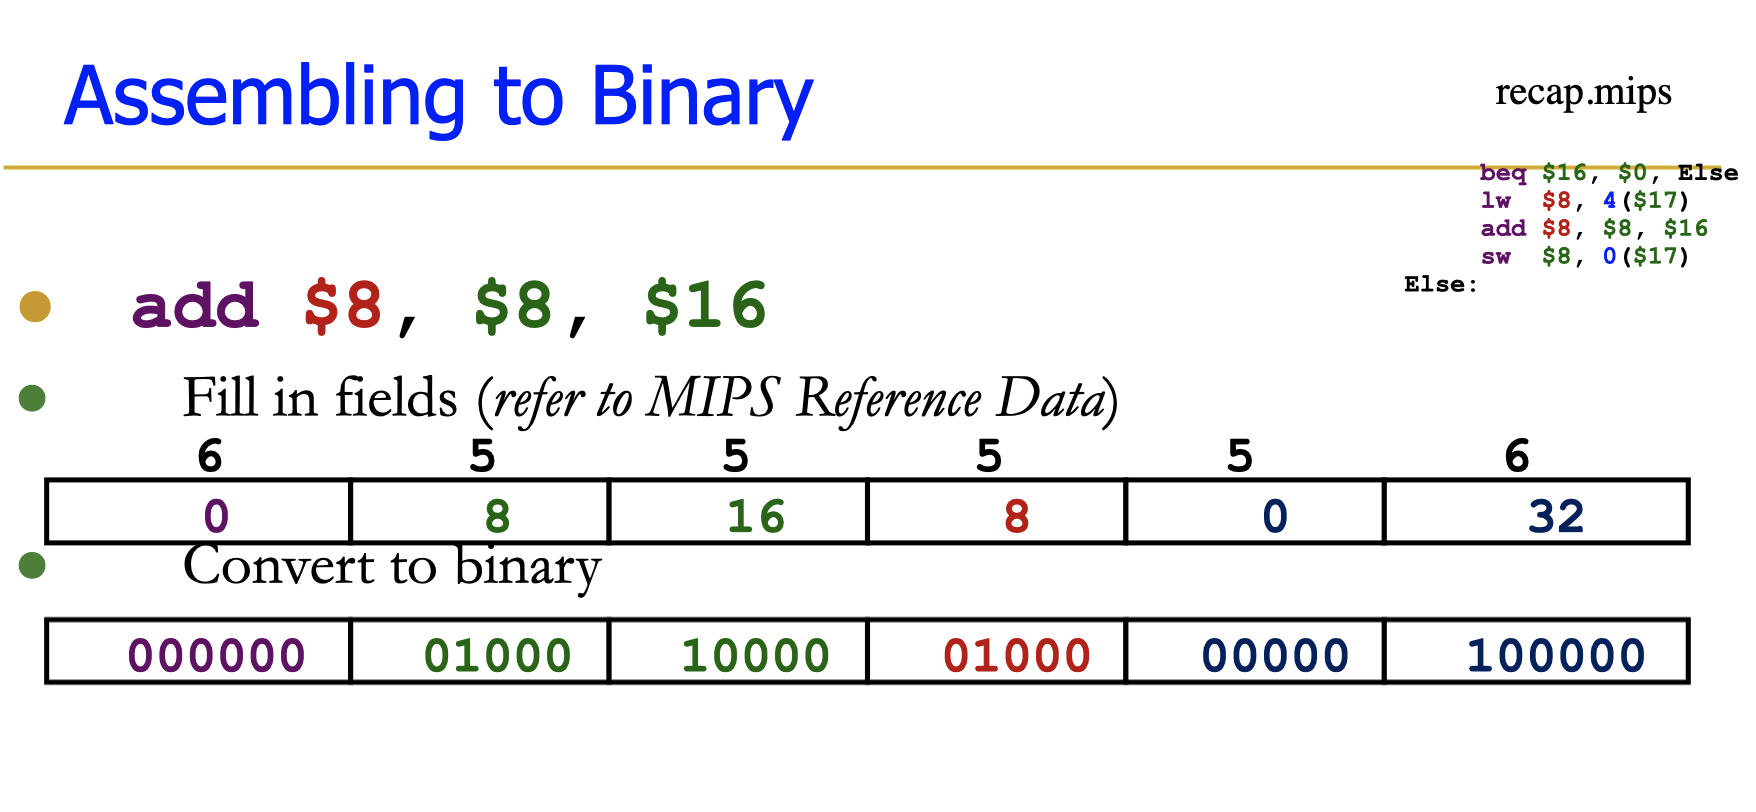
Reference Tables You Actually Need
You don't need to memorize every opcode. Just keep a reference sheet with the most common instructions: add, sub, and, or, xor, nor, slt, sll, srl, sra, load word, store word, beq, bne, jal, and jr. These cover roughly 80 percent of real MIPS code you'll encounter. The remaining 20 percent usually involves floating-point or system call instructions that have their own separate opcode spaces and tend to appear in specialized contexts. The opcode values themselves follow a rough logic. Register operations cluster around 0 and 1. Load and store instructions occupy the 32 to 39 range. Branch instructions sit near 4 to 13. Jump instructions use 2 and 3. This grouping isn't arbitrary. It reflects how the MIPS design team organized the instruction set, and recognizing the pattern makes lookup faster than rote memorization.
Quick Reference for Core Opcodes
J: 000010 | JR: 000000 with funct 001000 | ADD: 000000 with funct 100000 | SUB: 000000 with funct 100010 | AND: 000000 with funct 100100 | OR: 000000 with funct 100101 | XOR: 000000 with funct 100110 | NOR: 000000 with funct 100111 | SLT: 000000 with funct 101010 | LW: 100011 | SW: 101011 | BEQ: 000100 | BNE: 000101 Keep this list close. The rest you can look up when it matters.