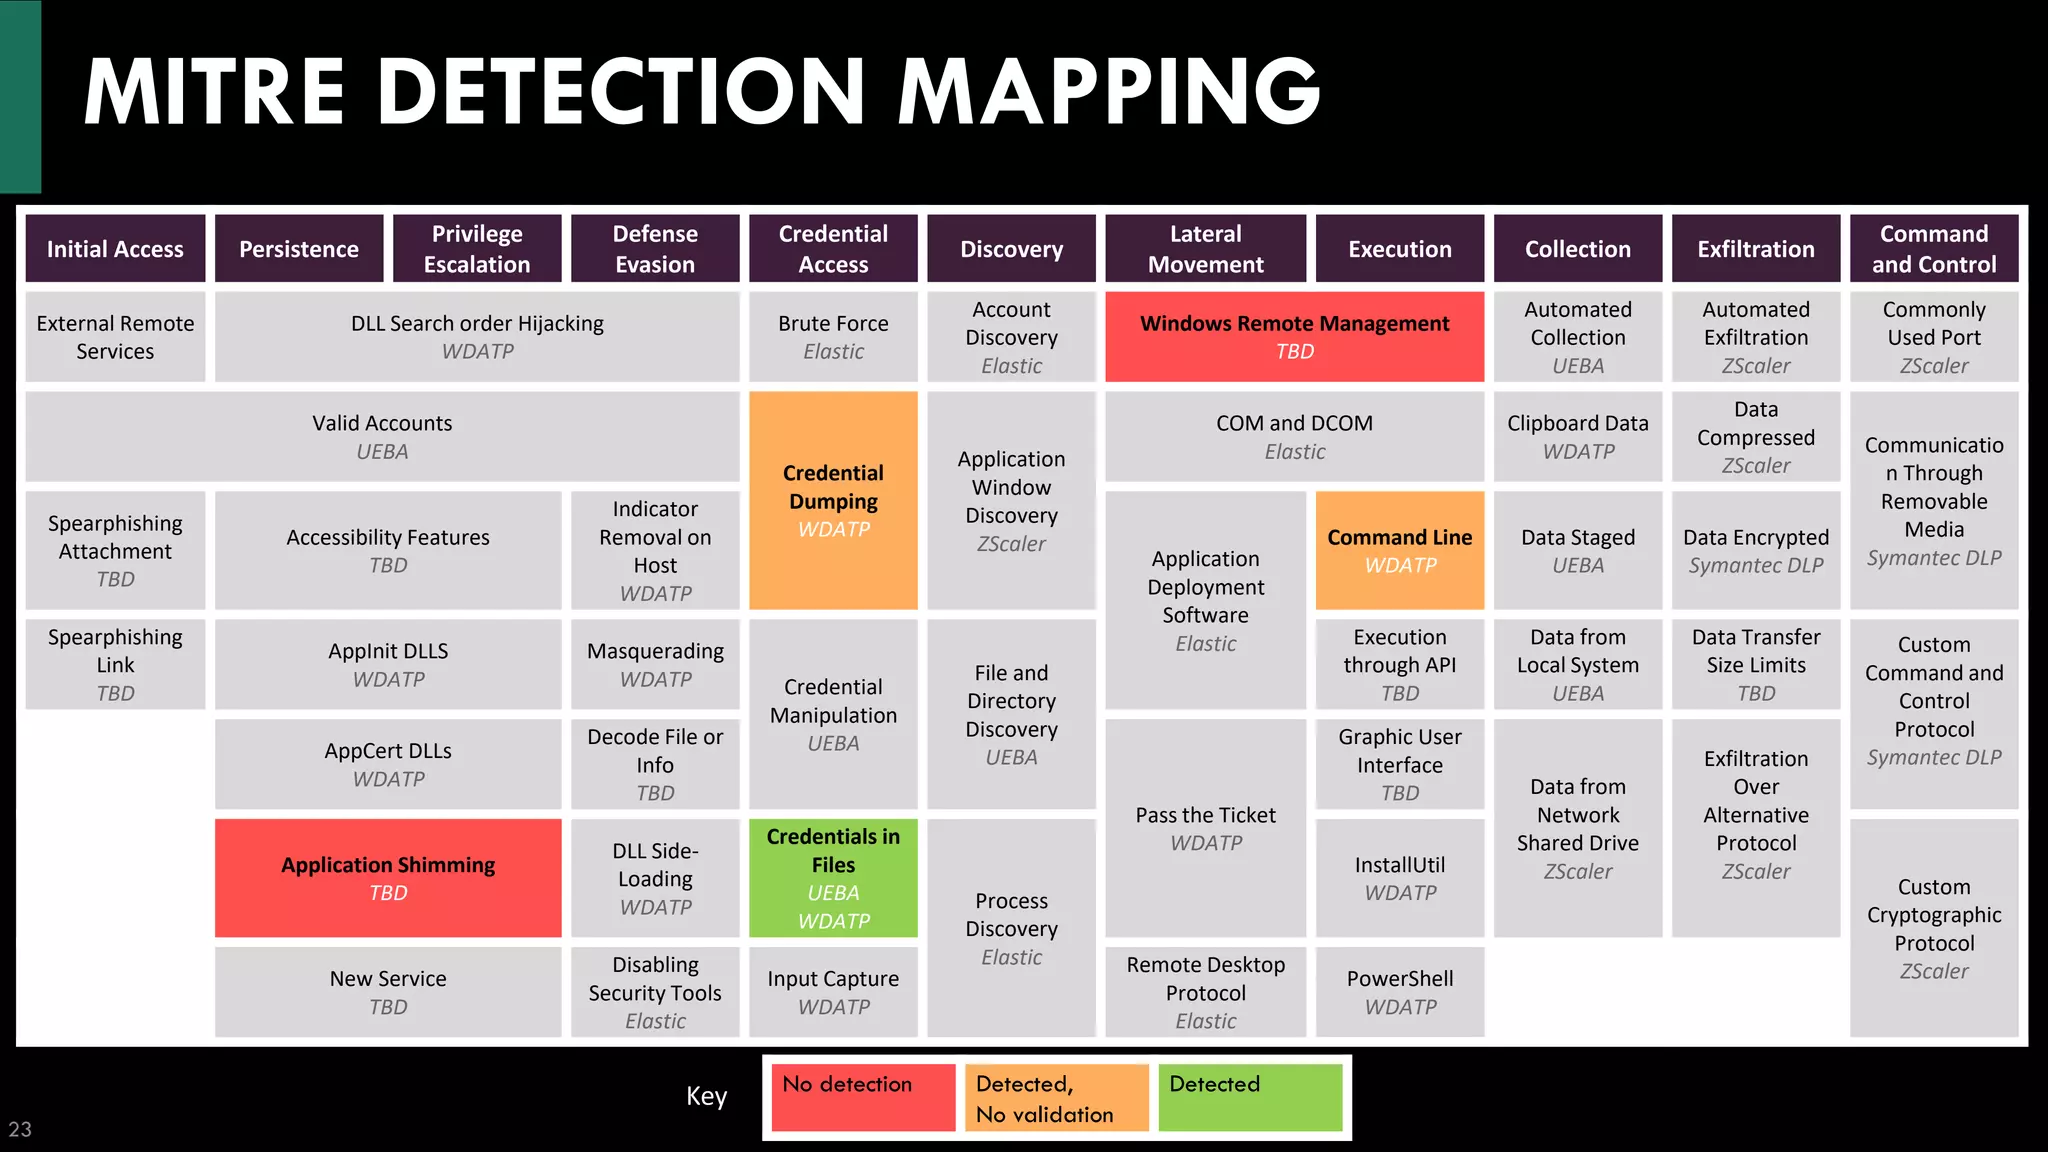
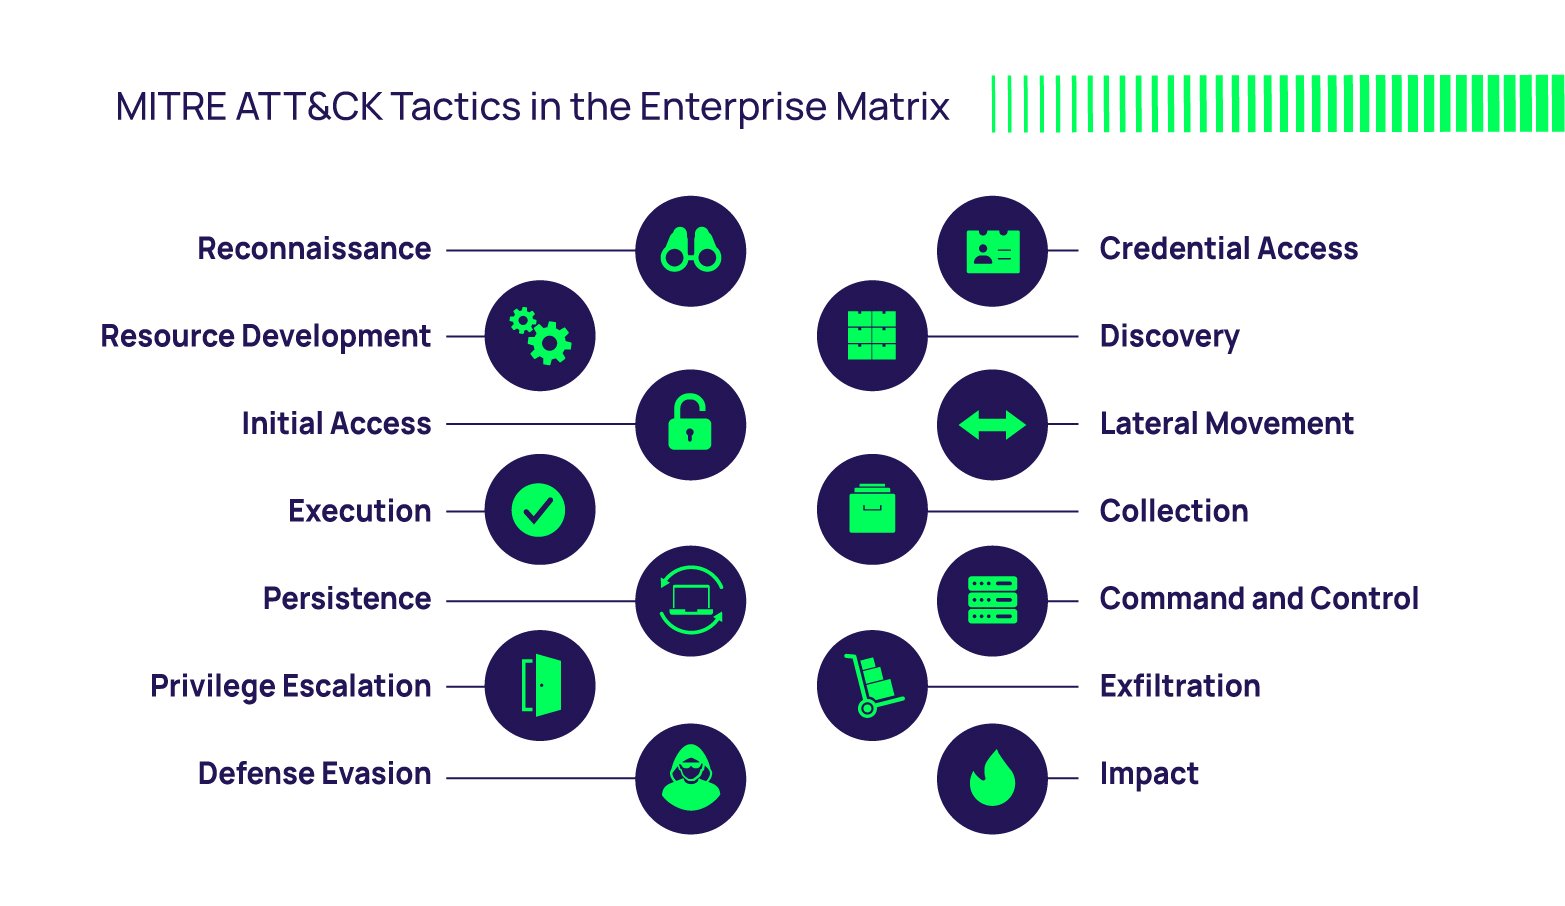
The actual process of mapping your detection data to the ATT&CK framework
Most people think mapping is just picking tactics and techniques from a drop-down menu. It's not. It's a translation exercise between your raw logs and a standardized taxonomy, and you're going to spend most of your time figuring out which technique actually fits a given alert. The ATT&CK matrix isn't a diagnostic tool. It's a language. Your job is to make your SIEM speak it. I've done this for probably a dozen environments across different industries, and the process is always the same ugly loop. You grab a detection rule, read the query, figure out what the underlying behavior actually is, then search the ATT&CK technique catalog for the closest match. Sometimes it's obvious. T1059 — Command and Scripting Interpreter — covers half the world. Most of the time it isn't obvious. Here's the workflow I actually use instead of whatever template the GRC team sent around.
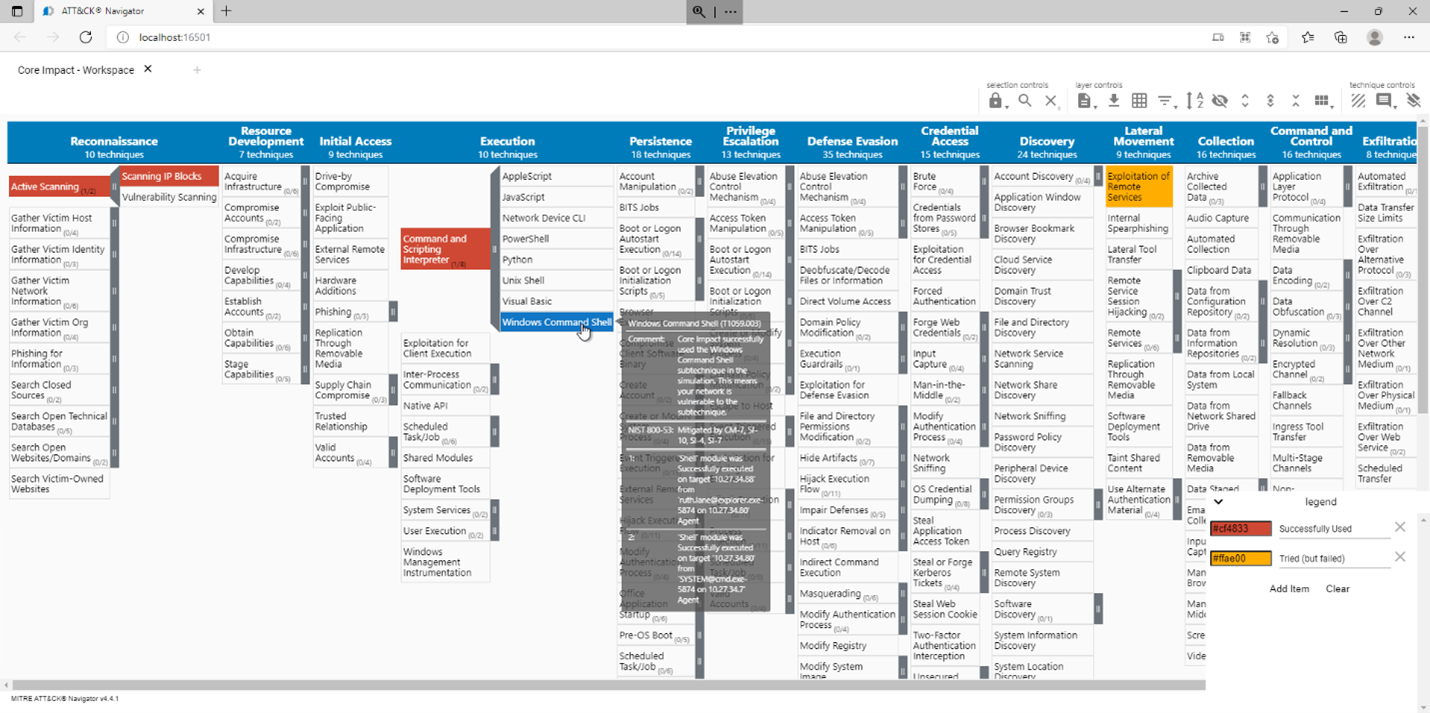
Start with your highest-severity detection rule. Not your most frequent alert. The one that actually matters when things go wrong. Pull the raw query from your SIEM. Read every field it references. A hunt for "powershell encodedcommand" tells you very different things than a hunt for "file creation in appdata." The fields matter more than the detection name your vendor gave it. Once you know what behavior you're looking for, go to the MITRE website directly. Don't use the ATT&CK Navigator unless you're doing a big-picture view. Search for the technique. Read the sub-technique descriptions. Half the techniques you pick by name will turn out to be wrong once you read the actual behavior descriptions, because the technique names are sometimes misleading. T1059.001 is PowerShell specifically, but T1059.003 is Windows CMD, and they require different detections even though they share the same parent tactic. Assign the narrowest technique that actually fits. I've seen too many mappings land on the parent technique because someone was lazy about reading the sub-technique descriptions. If your detection specifically looks for Python process creation, that's T1059.006. If it catches any scripting language, T1059 is correct. The difference matters when you're doing gap analysis or talking to an auditor who actually knows the framework.
The hardest part is handling detections that map to multiple techniques. A rule that catches suspicious network connections could be C2 communication (T1071), legitimate tool use (T1059), or data exfiltration (T1048) depending on what else you know about the environment. I always add context notes to the mapping. Without them, the attribution is basically useless six months later when you're trying to understand why a rule exists. I ran into a specific problem last year that takes way more time than it should. We had a detection rule for unusual scheduled task creation. On the surface, this is clearly T1053.005 — Scheduled Task. But the actual behavior we were catching wasn't a standard scheduled task. It was using schtasks.exe to register a task with a custom trigger that fired every 37 minutes instead of any standard interval. The nearest ATT&CK technique still mapped to T1053.005, but the description didn't cover this pattern at all. An auditor later asked why we were mapping this and I couldn't give a clean answer because the technique documentation was too broad. The workaround was straightforward but annoying. I documented the deviation in the technique note field within our mapping spreadsheet, linked to the specific detection rule ID, and flagged it as a partial match. Then I filed a potential technique enhancement through MITRE's public submission process. Nothing came back for about eight months. In the meantime, the note field became the source of truth whenever anyone questioned the mapping.
Get the Full Details
Tooling and automation realities
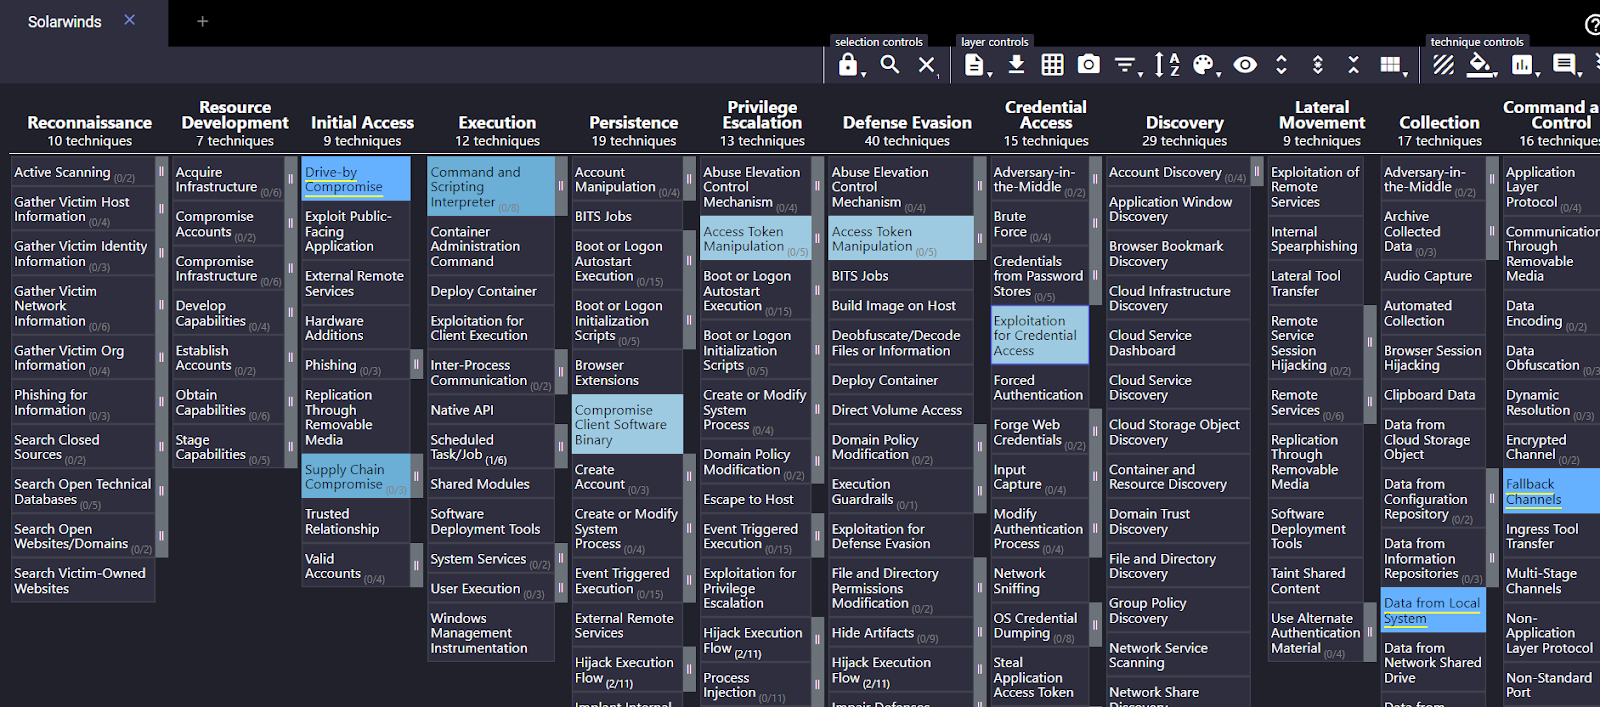
You can write scripts to automate this. Many teams use the MITRE CTI client library in Python. It lets you pull techniques, tactics, and software entries programmatically. But automation here has a hard limit. A script can suggest candidate techniques based on keyword matching against technique descriptions. It cannot decide whether a specific log field represents T1003.001 or T1003.008. That judgment call requires understanding the environment, which is exactly what the script doesn't have. I typically run a script to generate an initial draft mapping from a CSV export of detection rules, then spend two to three hours manually reviewing and correcting it. For an environment with roughly 200 detection rules, this usually cuts the process down from what would otherwise be a full day of manual work to about two hours of focused review. The time savings are real but only for the initial pass. There's also the Navigator tool to consider. It's free, it runs in a browser, and it supports layers. Multiple people can maintain different mapping layers for different scenarios — red team perspective, blue team perspective, threat intel feed coverage. The tool exports to JSON, which means you can version-control your mappings alongside your detection code. This is worth doing if you ever expect to update mappings systematically rather than as a one-time compliance exercise.
Common mistakes I see repeatedly
The biggest one is mapping techniques to detection names instead of to actual behavior. Your detection rule is called "Suspicious RDP Activity" and you map it to T1021.001. But if the underlying query actually checks for RDP connections originating from unusual source IPs during off-hours, you're not detecting the protocol usage at all. You're detecting anomalous network behavior. The technique might still be T1021.001, but the mapping justification needs to reflect what the detection actually catches, not what the rule name implies. Another mistake is treating every detection as a unique technique. T1078 has four sub-techniques covering default, local, domain, and cloud accounts. If you have three separate detection rules that all fundamentally detect valid credential use regardless of account type, mapping each one to a different sub-technique just because the detection sources vary slightly creates false granularity. Group them under T1078 and note the distinguishing factors in the justification. The framework isn't designed to capture every implementation detail of your environment. Data source coverage is where most mappings quietly fail. ATT&CK techniques are backed by data sources — things like Process, File, Network Connection, Registry. When you assign a technique to a detection, you should also verify that your detection actually captures the required data sources for that technique. A common gap shows up with T1003 — OS Credential Dumping. The technique has seven sub-techniques, but most enterprise environments only collect process creation events. That means you can detect T1003.001 (LSASS memory access via process creation) but you're blind to T1003.002 through T1003.007 because you don't collect the relevant registry or file events. Mapping the technique without acknowledging the data source limitation gives you a false sense of coverage.
What this approach doesn't solve
Mapping detections to ATT&CK techniques does not improve your detection coverage by itself. It doesn't find gaps. It doesn't reduce false positives. It creates a shared vocabulary between security engineering, threat intelligence, and incident response. The actual value shows up during tabletop exercises when someone can say "we're missing coverage for T1566.001 at the payload delivery layer" and everyone understands exactly what that means. Before mapping, that conversation usually devolves into explaining what phishing is to people who already know what phishing is. The framework also doesn't account for cloud-native behaviors as cleanly as it accounts for on-premises Windows behavior. Techniques in the Cloud section are newer and less mature. The data source coverage is spotty. If your environment is primarily AWS or Azure, you'll find yourself mapping to technique descriptions that assume you have cloud trail or audit log access you might not actually have. Be honest about what you can detect versus what the framework suggests you should detect. Finally, ATT&CK mapping is static by nature. The framework gets updated roughly quarterly with new techniques and sub-techniques. Your mappings become outdated the moment you finish them if the underlying techniques shift. I keep a running change log for each technique assignment and review it against the quarterly updates. It takes maybe thirty minutes per quarter for a medium-sized environment and prevents the awkward conversation where an auditor points out a technique that was deprecated six months ago.