Getting From Raw Numbers To Meaningful Averages
Most people encounter mode and mean in introductory statistics and immediately think they have the whole picture. They don't. The definitions are elementary but the practical application is where things fall apart if you haven't actually worked through messy real-world datasets. Let me walk through what each measure actually tells you and how to use them without shooting yourself in the foot.The Mode And Mean Definition Actually Matters In Practice
The mean is the arithmetic average: sum all values, divide by the count. The mode is the value that appears most frequently in a dataset. That's the textbook version. The version that saves you from making costly mistakes is understanding what each one is quietly refusing to tell you. I spent three years working in operational analytics before I learned this the hard way. We had a client whose customer support tickets were being analyzed for staffing decisions. The mean resolution time was 4.2 hours. Looks reasonable, right? Then I pulled the distribution and discovered the mode was 1.1 hours. The mean was being dragged into the stratosphere by a handful of enterprise accounts that took 60 plus hours to resolve because of compliance review cycles. If we had hired based on the mean alone, we would have understaffed our normal queue by roughly 40 percent. The mode showed us where the actual bulk of work lived. The mean told us the total pressure on the system. You need both, and you need to know which one your decision actually depends on.Here's the mechanical side first, since that's usually where people get tripped up.
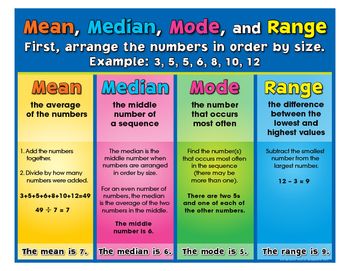
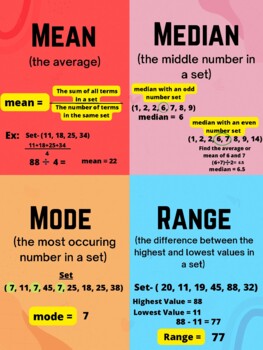
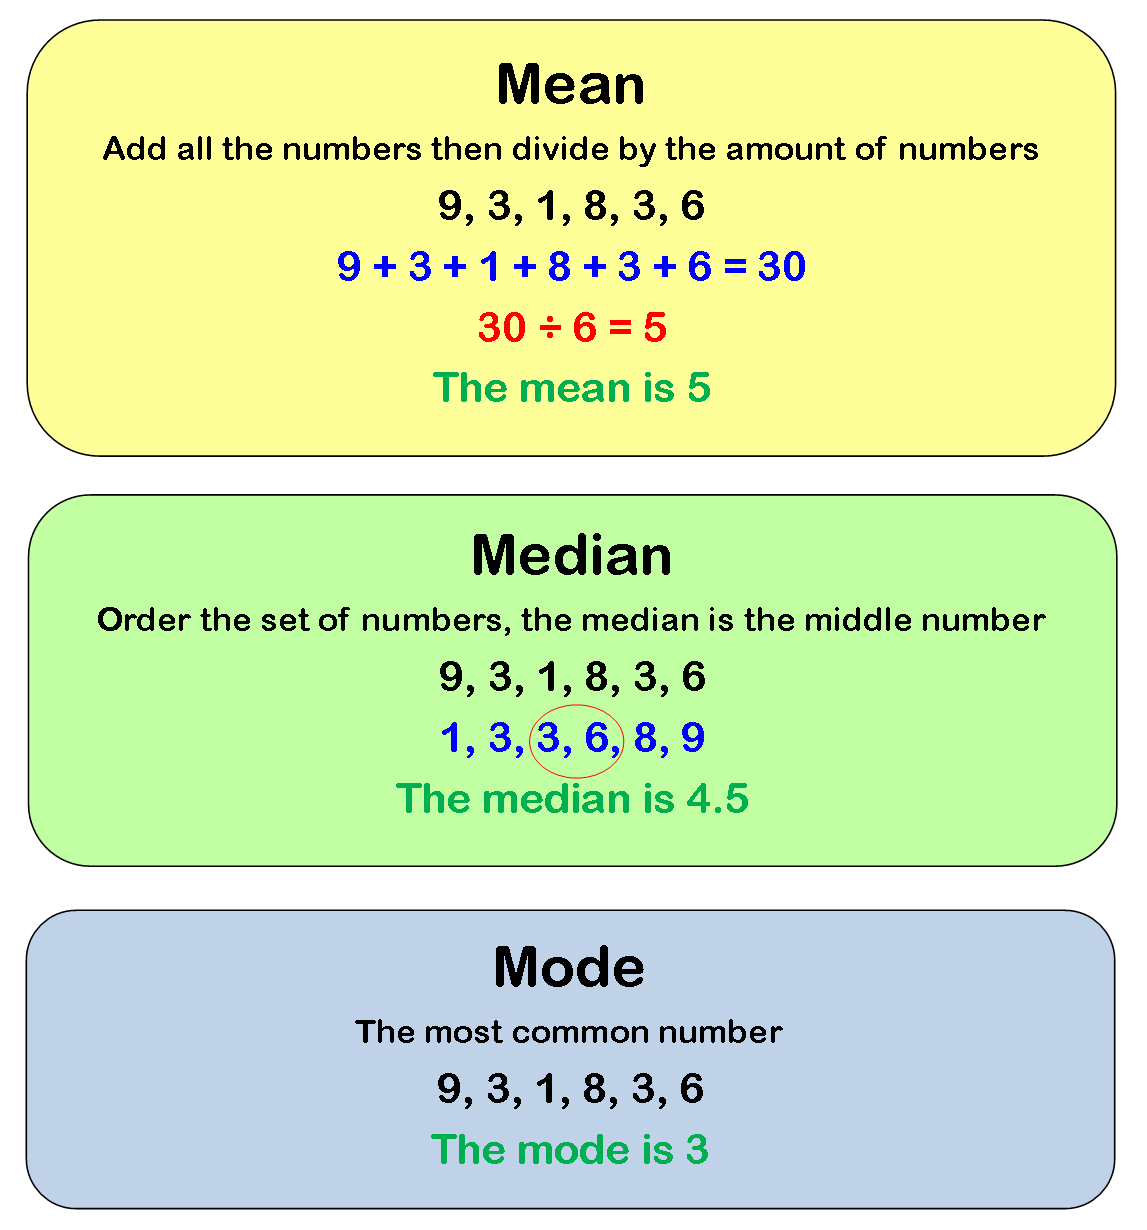
To calculate the mean, add every number together and divide by how many numbers you have. That's it. No tricks. For a dataset like 3, 7, 7, 9, 12, the sum is 38 and the count is 5, so the mean is 7.6. To find the mode, scan for frequency. In that same dataset, 7 appears twice while everything else appears once, so the mode is 7. Some datasets have no mode at all if every value is unique. Some have multiple modes if two or more values tie for highest frequency. Bimodal distributions are extremely common in real data and the mean will happily obscure that fact unless you're actually looking at the shape of the data.The part nobody tells you in basic courses is how these measures behave under different distribution shapes.
In a perfectly symmetric distribution, the mean and median and mode all occupy the same point. Real data is almost never perfectly symmetric. In a right-skewed distribution like income data, the mean sits to the right of the mode because the long tail of high values pulls the average upward. In a left-skewed distribution, the mean gets dragged to the left. This is why median income is almost always reported alongside mean income. They are telling you different stories about the same dataset. The mode is the most robust of the three to outliers because it simply doesn't care about extreme values. It only cares about frequency. That's a feature and a liability depending on what you're trying to do.I ran into a particularly annoying edge case last year involving product ratings.
Get the Full Details

There are also limitations worth being honest about.
The mean is highly sensitive to outliers and can be completely misleading in small samples with extreme values. A single data point can shift the mean dramatically. The mode has its own failure modes. With continuous data where every value might be slightly different, the mode becomes meaningless unless you bin the data first, and binning choices can artificially create or destroy apparent modes. In small datasets, the mode can be unstable, flipping between values as you add or remove single observations. Neither measure captures spread or variability on its own. A dataset of 10, 10, 10, 10, 10 has the same mean and mode as 1, 10, 10, 10, 19. They look identical under those two metrics but represent fundamentally different situations.For most practical work I recommend always reporting the mean alongside the standard deviation and the mode alongside the frequency distribution. That combination takes about the same amount of effort as reporting any single measure and prevents the kind of misinterpretation that shows up in boardroom presentations six months later.