Working with the Four Most Common Measures of Central Tendency
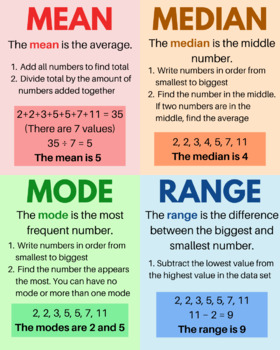
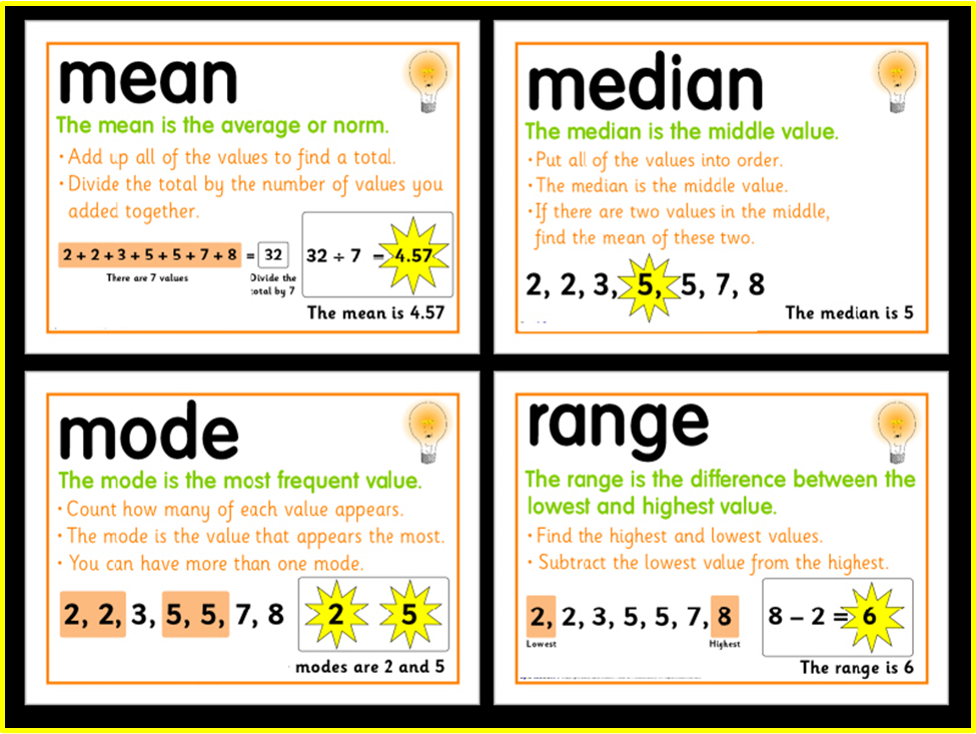
People usually learn these in statistics 101 and then never really think about them again until they hit a dataset that makes them question everything. The mode, median, mean, and range are the baseline tools. Getting them wrong is more common than you would expect, especially when your data isn't clean. The mean is the arithmetic average—add everything up, divide by the count. The median is the middle value when data is sorted. The mode is the most frequent value. The range is simply the highest value minus the lowest value. Easy enough on paper. In practice, it is not always easy. I remember working with a dataset of server response times from a production environment. The numbers ranged from about 12 milliseconds to 47,000 milliseconds. The mean came out to roughly 890 ms. The median was 45 ms. The mode was 41 ms. The range was 46,988 ms. The mean looked like it was inflating the picture so badly that anyone using it would have designed capacity planning entirely wrong.
The workaround was straightforward. I stripped the top 1 percent of outliers, recalculated, and then reported both the trimmed and untrimmed mean side by side. That way nobody could claim the average was 890 ms without seeing the context. I also stopped using the mean for anything that involved latency distributions because they are never normal. A log transform was the better move for that particular case. Here is a quick practical walk-through. Say you are looking at monthly revenue figures for a small retail chain: $32,000, $35,000, $31,000, $34,000, $88,000, $33,000, $36,000. Sort the data first: $31,000, $32,000, $33,000, $34,000, $35,000, $36,000, $88,000. The median is the fourth value: $34,000. The mean is the sum divided by seven, which comes out to about $42,857. The mode here does not really exist since every value appears once, which means you report no mode. The range is $88,000 minus $31,000, which is $57,000. You can see immediately that the mean is being dragged upward by that one outlier month.
When you are dealing with income data, housing prices, or any variable with a long right tail, the median is almost always the number you should lead with. The mean will look impressive to people who do not know better. Income inequality reports from census bureaus always highlight this. The mean household income can be wildly different from the median in the same city. The mode gets ignored too often. In a survey where respondents pick their preferred brand from a list, the mode tells you the most popular choice instantly. It works best with categorical or discrete numerical data. If you are measuring something continuous like height or weight, the mode becomes unstable because exact duplicates are rare. Bin the data into ranges instead. I used this trick when analyzing support ticket categories. The raw ticket IDs had no useful mode until I grouped them by department. Then the mode showed me which team was handling the majority of volume. The range is the simplest measure but also the most fragile. One bad data point ruins it completely. A single sensor glitch that records a negative temperature can make your range look absurd. I dealt with this when monitoring IoT temperature logs from a cold storage facility. A faulty probe sent back values like -999, which inflated the range to nearly 1,000 degrees. I fixed it by filtering for physically impossible readings before calculating range. You need a minimum sanity check layer before range ever touches your dashboard.
Get the Full Details
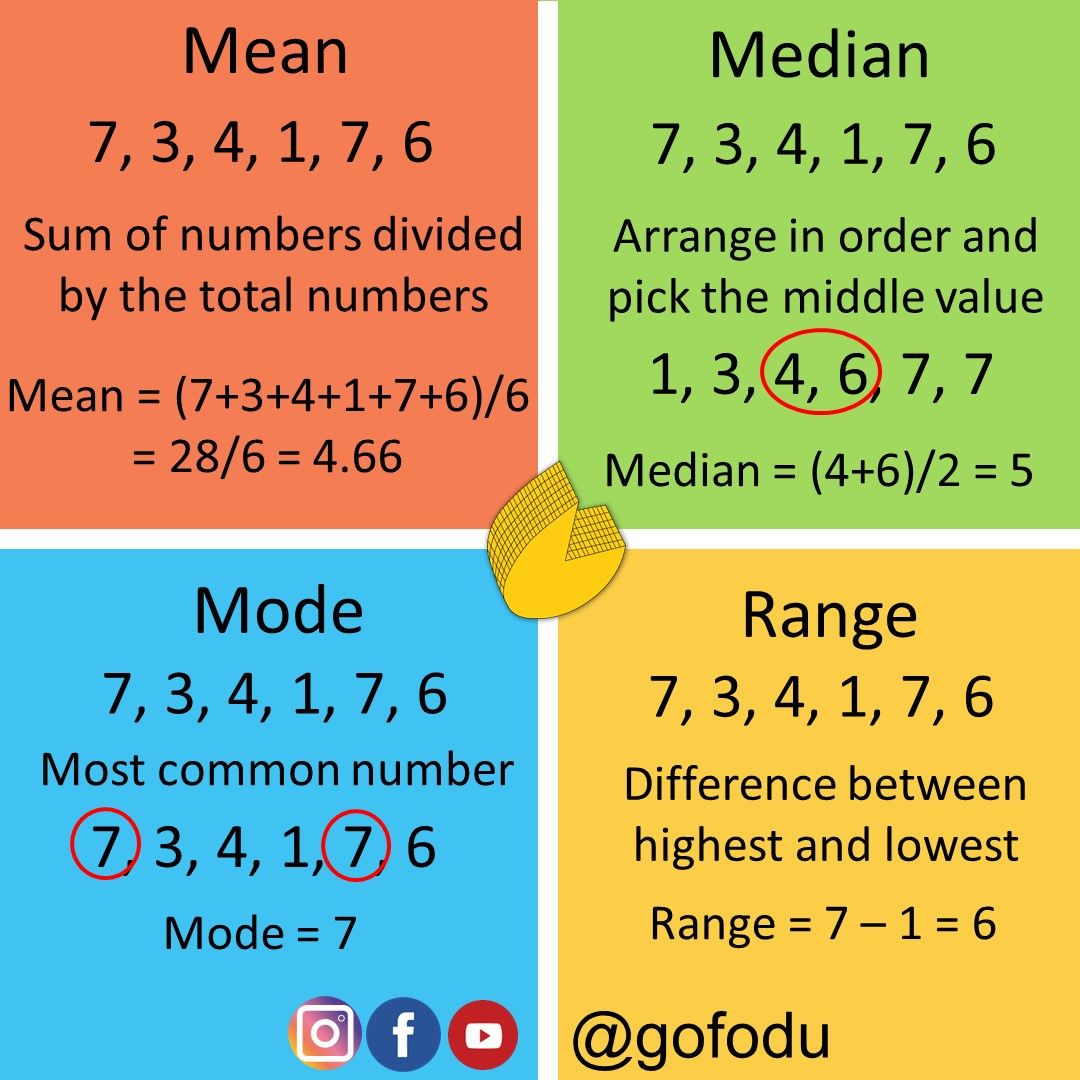
A counter-intuitive thing about the mean is that it is the only measure that minimizes the sum of squared deviations. That property makes it useful for regression and optimization, but it also means it pulls hard toward extreme values. The median minimizes the sum of absolute deviations. It is more resistant to outliers. If you are building a model and your residuals are not normally distributed, switching your loss function from squared error to absolute error is basically switching from optimizing for the mean to optimizing for the median. It changes the outcome in non-obvious ways. Another thing people miss is that a dataset can have multiple modes. Bimodal distributions are not rare. I found a bimodal pattern in user session durations on a video platform. One peak at about 45 seconds and another at roughly 14 minutes. The mean landed somewhere around 4 minutes, which described nothing accurately. The median was about 2 minutes. Neither told the full story. Splitting the users into two segments and analyzing each group separately gave me actionable insight. That kind of segmentation work is what separates someone who just computes numbers from someone who actually understands the data. Range has a bigger limitation that rarely gets discussed. It says nothing about the distribution between the extremes. Two datasets can have identical ranges but completely different shapes. Consider Dataset A: 1, 2, 3, 4, 5, 6, 7, 8, 9, 10. And Dataset B: 1, 1, 1, 1, 1, 10, 10, 10, 10, 10. Both have a range of 9. The spreads are utterly different. Variance and standard deviation exist for this reason. Reporting range alone is a sign that someone skipped half the analysis.
If you need a quick reference for calculation, here is a practical summary of when to use each measure.
- Mean: Use for symmetric distributions without heavy outliers. Good for additive processes and when squared deviations matter, like in experimental design.
- Median: Use for skewed distributions, income data, response times, and any variable with a long tail. It is the safer default when you are unsure.
- Mode: Use for categorical data or when identifying the most common value matters, like in inventory restocking decisions.
- Range: Use as a quick sanity check only. Always pair it with interquartile range or standard deviation for actual reporting.
I keep a small Python snippet saved for when I need to compute all four quickly. It handles the edge cases, flags missing modes, and strips obvious outliers before calculating range. Running it on a CSV file takes about three seconds for a dataset of fifty thousand rows. That is faster than doing it manually in Excel, especially when you have to repeat the process across dozens of files. The hardest part of working with these four measures is knowing which one your audience will misinterpret. Business stakeholders hear "average" and assume mean. If your mean is being dragged by outliers, you are setting them up for bad decisions. Lead with the median in those situations and call it out explicitly. People tend to trust the number that feels more representative of their own experience. One more practical note. When your data has a lot of tied values, the mode becomes more informative. I analyzed a dataset of customer complaint codes where five distinct codes made up over sixty percent of all entries. The mode immediately pointed to the top two codes. Those were the ones worth investigating. The mean and median of complaint codes are meaningless here because the codes are identifiers, not quantities. Range is useless too. The mode was the only measure that actually answered a useful question.
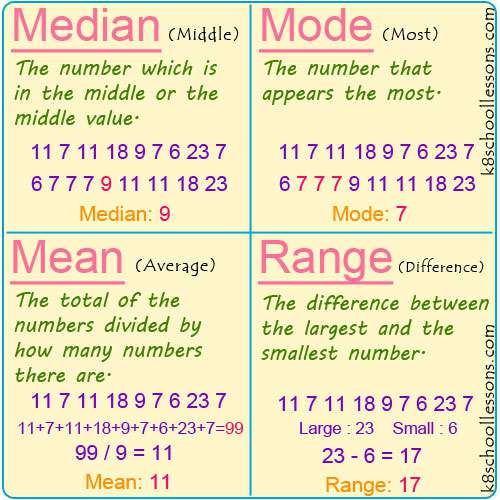
There is no single best measure. The right choice depends entirely on what you are measuring and what you are trying to communicate. The mean, median, mode, and range are all useful if you understand their failure modes. The people who get burned are the ones who apply the mean to skewed data and then act surprised when the results look wrong. Check the distribution first. Pick the measure that fits the shape. Report more than one when the story is complicated.