Getting Your Head Around Model In Math
Most people overcomplicate this. You don't need a fancy textbook. You need to understand that a model is just a simplified version of reality that lets you calculate something without running the actual thing. That's it. The rest is just figuring out which simplifications still give you answers you can trust. I've spent years building models for everything from structural loads to financial projections, and the thing that trips people up most isn't the math. It's picking the wrong abstraction level. You'll see beginners build models with thirty variables when five would do, then wonder why their results are impossible to interpret. More complexity doesn't equal more accuracy. It usually equals more noise.
What Actually Makes Model In Math Different From Just Plugging Numbers In
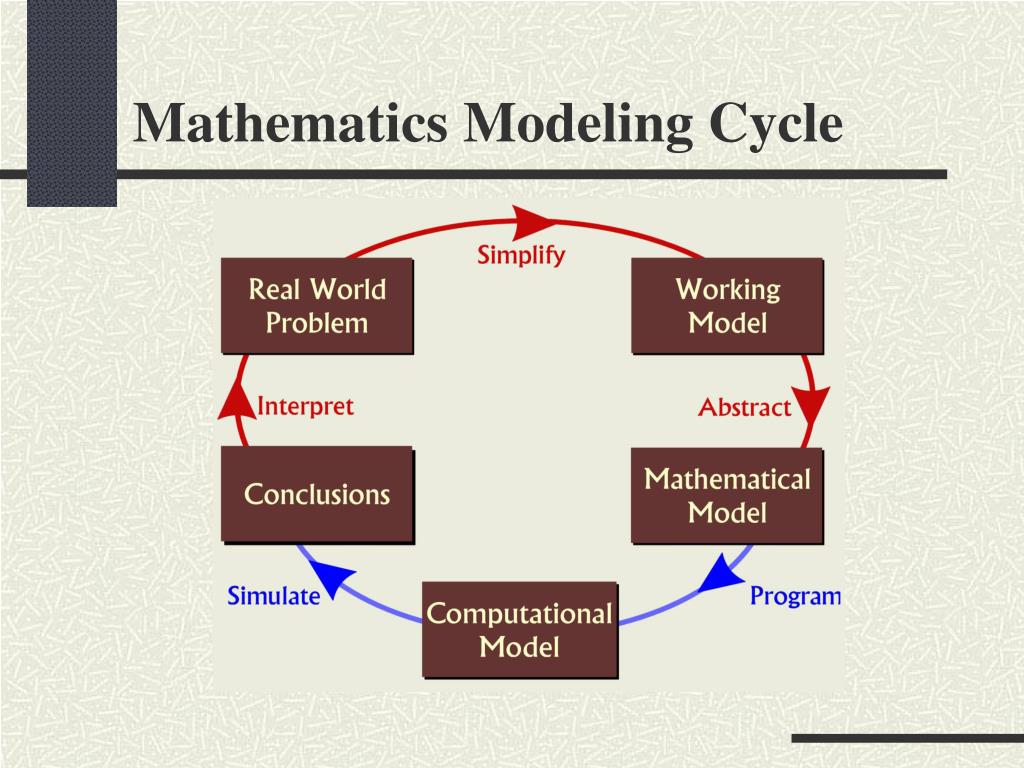
The distinction matters because a lot of people treat "math model" as a synonym for "equation." It isn't. A model is a system. It contains assumptions, parameters, constraints, and often multiple equations that talk to each other. When someone says they're doing Model In Math, they're usually referring to the entire workflow: defining the real-world situation, translating it into mathematical form, solving it, and then checking whether the solution actually maps back to reality in a useful way. Here's where I learned this the hard way. I once built a traffic flow model for a municipal planning project. The equations were correct. The simulation ran clean. But when we compared predictions against actual sensor data from the intersection, the model consistently underestimated peak-hour volume by about forty percent. Turns out the model assumed uniform vehicle spacing, which is fine for steady-state conditions but completely breaks down during rush hour when drivers bunch up and lane changes create ripple effects. The workaround wasn't adding more equations. It was introducing a stochastic component for headway distribution and running Monte Carlo simulations instead of a single deterministic output. That changed the whole character of the results. Suddenly we had ranges instead of points, and ranges are how traffic engineers actually think about capacity.
The Practical Workflow
Start with the question. Not the equation. The question. What are you trying to predict or optimize? Write it down in plain language before you touch any symbols. If you can't state the problem clearly without math jargon, you don't understand it well enough to model it. Next, identify your variables. Separate them into independent variables, dependent variables, and parameters. Independent variables are what you can control or observe. Dependent variables are what the model outputs. Parameters are constants within the model's scope — things like material properties, conversion factors, or calibration coefficients. Getting this classification right early prevents you from accidentally treating a parameter as a variable later, which is a remarkably common mistake that silently corrupts results. Then write the relationships. This is where most people reach for standard textbook models. Don't ignore textbooks. But also don't assume the first model you find fits your situation. A linear regression model might be the default choice for relationship modeling, but if your data has thresholds or feedback loops, linear is actively wrong. Look at the behavior you're trying to capture first. Then find or construct the mathematical structure that matches that behavior.
Get the Full Details

Model In Math at the Implementation Stage
Once your equations are set, you need to solve them. This means choosing between analytical solutions, numerical methods, or simulation. Analytical solutions are clean but rare. Most real-world models require numerical approaches. Finite element analysis, finite difference methods, iterative solvers — these are workhorses, not mysteries. Pick the one that matches your model's structure and your available computing resources. I remember a project where we modeled heat dissipation in an electronics enclosure. The analytical solution existed but required assuming perfectly uniform surface temperature, which is physically unrealistic for a component with localized hot spots. We switched to a finite volume method with a refined mesh around the heat sources. The computational cost tripled, but the temperature predictions dropped from being off by twelve degrees Celsius to within two degrees. That trade-off was worth it for a safety-critical design. Validation comes after implementation, not before. You solve the model, then you test it against known data. If you have historical measurements, compare your model's outputs against them. If you don't, run boundary case checks — what does the model produce when inputs go to zero, to maximum, or to impossible values? A model that gives sensible answers for edge cases is more likely to give sensible answers in the middle range too.
Where Models Fail and What to Do About It
No model survives first contact with reality intact. Here are the failure modes I've actually encountered: Parameter drift. Parameters that seem stable in the lab or the model environment change in the real world. Temperature affects resistance. Humidity affects material stiffness. If your model treats these as constants across conditions where they vary, your outputs will drift. The fix is to either add those dependencies explicitly or run the model across a range of parameter values to establish uncertainty bounds. Correlation masquerading as causation. This is the most dangerous pitfall. You find a statistical relationship between two variables in your data, encode it into the model, and suddenly the model appears to predict well. But when conditions change, it fails catastrophically because the relationship was coincidental, not structural. Before embedding any correlation into a model, ask whether there's a mechanistic reason for the relationship. If the answer is just "it showed up in the regression," treat it as a placeholder, not a conclusion.
Scale mismatch. A model calibrated at one scale often breaks at another. Laboratory experiments run on small samples. Field conditions involve larger systems with different dynamics. I worked on a hydraulic model that was calibrated using bench-scale flow data. When we scaled it up to full pipe diameter, the Reynolds number regime changed entirely, and the friction factor correlations we used became invalid. We had to switch to a different turbulence model and recalibrate against pilot-scale data before trusting the full-scale predictions. When a model fails, don't immediately add complexity. First check whether the failure is due to a violated assumption, a missing mechanism, or incorrect parameter values. Adding variables to a broken model just makes the broken model harder to debug.

A Note On Tools
You don't need expensive software. Python with NumPy and SciPy handles most modeling tasks. R is strong for statistical models. MATLAB and Julia are solid choices depending on your domain. The tool doesn't matter as much as understanding what the tool is doing under the hood. Every library call is an algorithm. Knowing which algorithm you're invoking and its limitations is more valuable than knowing which library is popular. For Model In Math specifically, the approach is the same regardless of platform: define the problem, translate to equations, implement, validate, iterate. The details change. The structure doesn't.