Picking the Right Model Organism
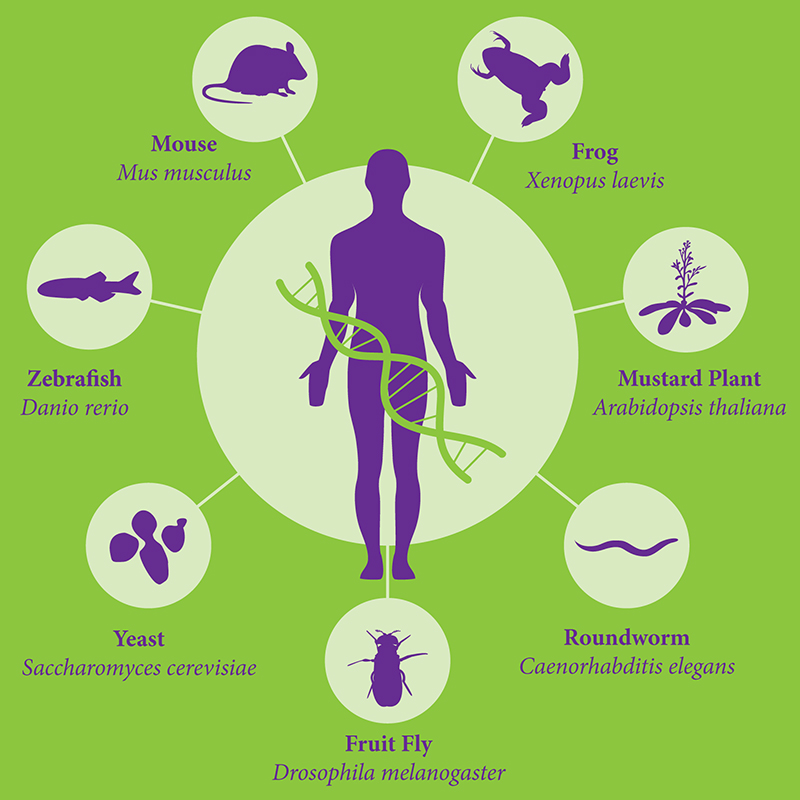
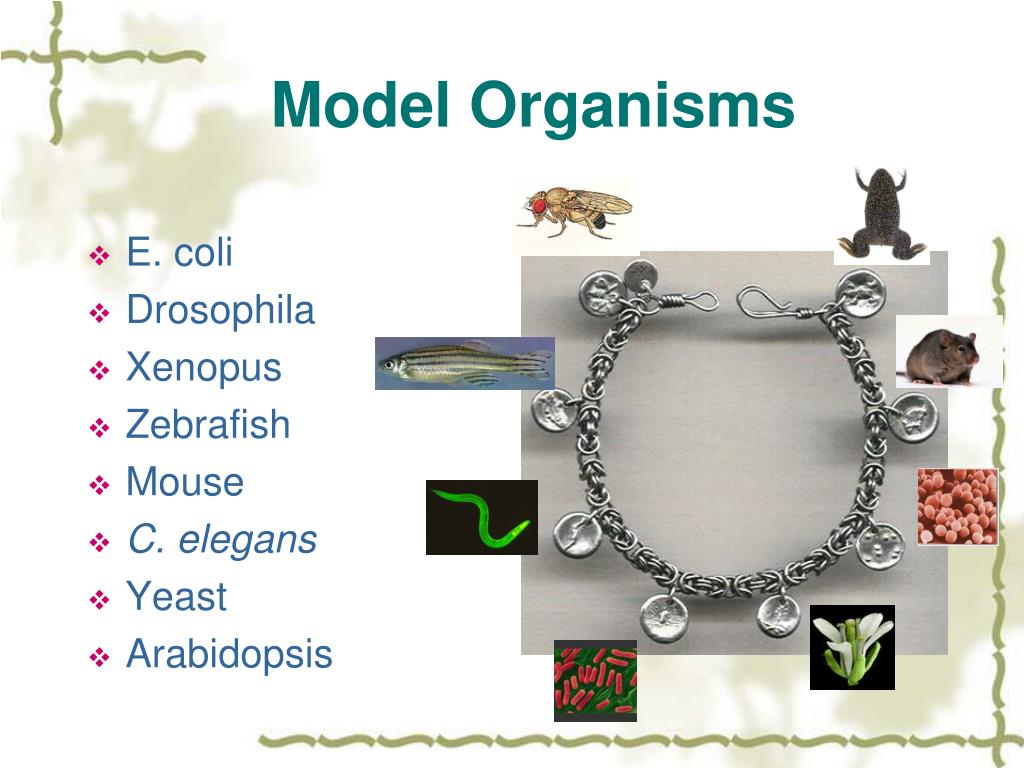
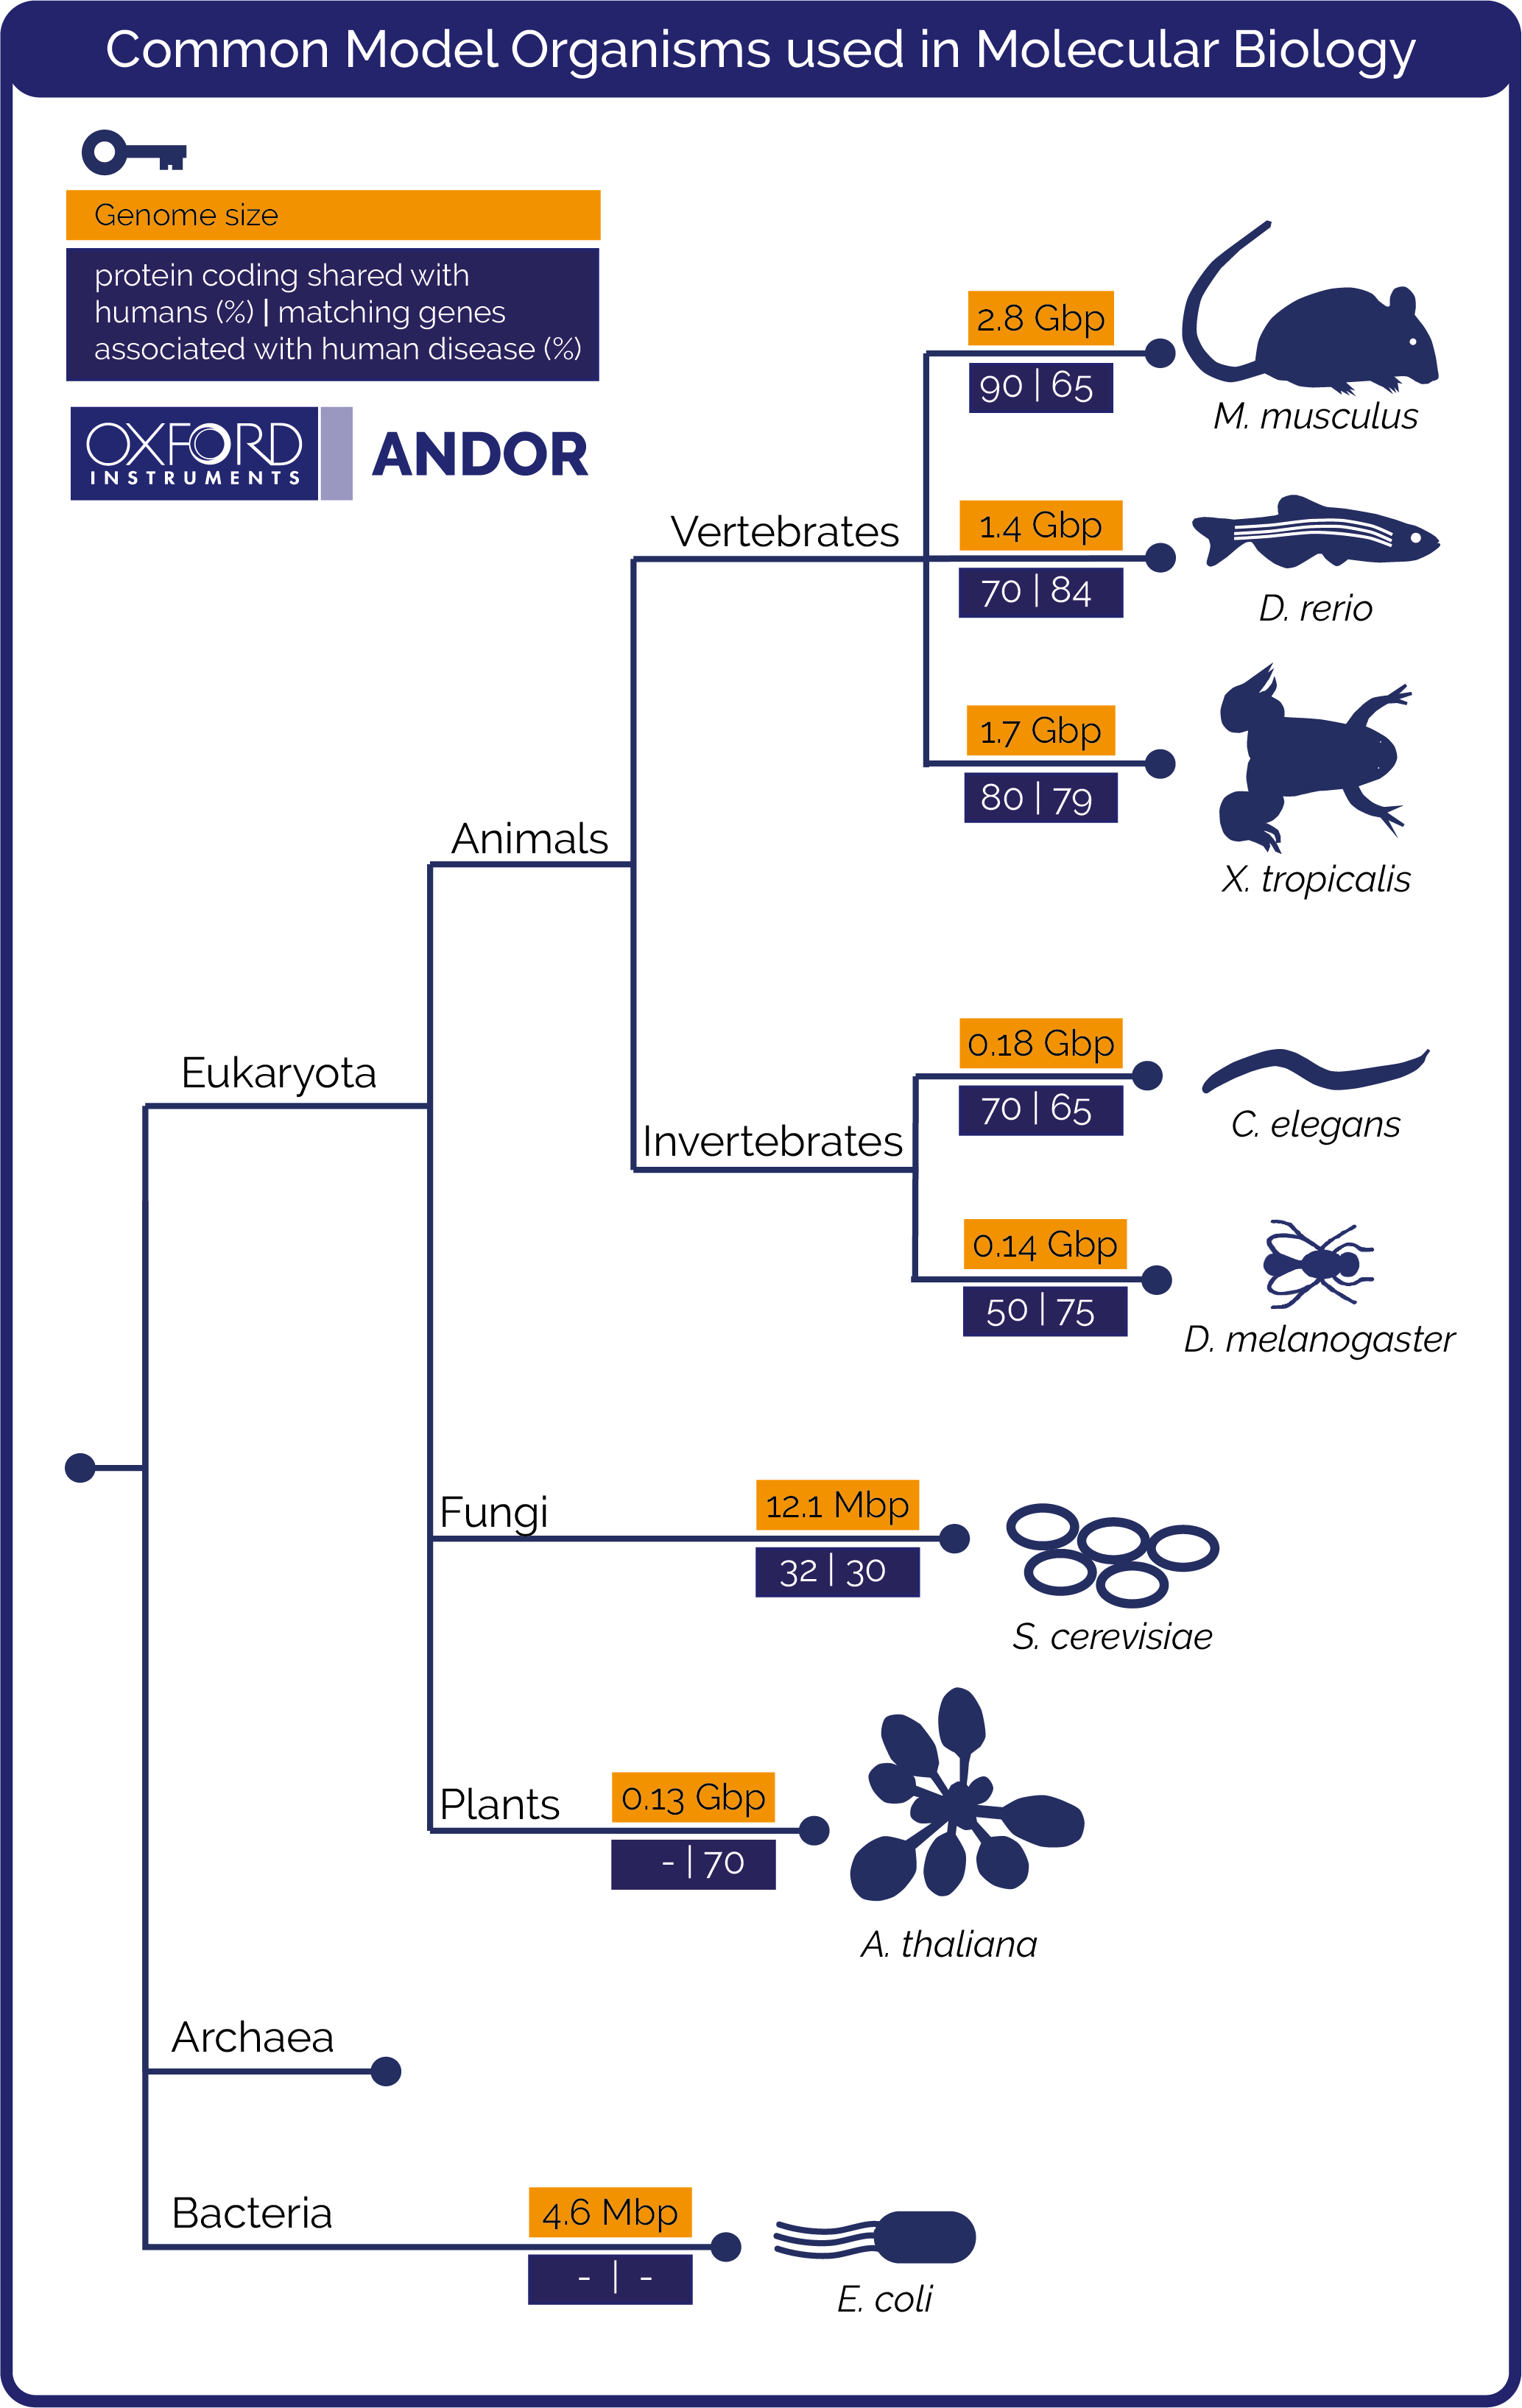
Choosing a model organism for molecular biology work isn't about what's trendy in papers. It's about what actually works for your experimental system, budget, and timeline. The list of common organisms—E. coli, S. cerevisiae, C. elegans, D. melanogaster, M. musculus, Arabidopsis thaliana, Zebrafish, and so on—comes with real tradeoffs that most guides gloss over. Here's how I approach it when someone hands me a project.
Deciding on Model Organisms In Molecular Biology for Your Project
Start by writing down the biological question in one sentence. Not the mechanism you hope to study. The question itself. "How does gene X respond to oxidative stress in epithelial tissue?" is better than "I want to study gene X." The question drives the organism choice, not the other way around. I've seen people pick C. elegans because it's cheap and easy, then spend six months fighting with RNAi knockdown efficiency before realizing the gene they cared about wasn't well-conserved in nematodes. That mistake costs reagents, time, and sanity. You can avoid it by checking orthology first. A quick BLAST or OrthoDB search against your organism of interest takes twenty minutes and might save you two weeks.
Practical Rules I Actually Follow
Bacteria (E. coli) — Use for cloning, protein expression, basic genetics. Fast, cheap, well-characterized. The limitation is that eukaryotic post-translational modifications don't happen here. If your protein needs glycosylation, phosphorylation patterns, or proper folding through chaperones that only exist in eukaryotes, E. coli will give you inclusion bodies and a lot of wasted purification time. I usually switch to insect cells (Sf9 with baculovirus) or mammalian cells for those cases. The setup takes longer—about two weeks for a stable line versus three days for a bacterial transform—but the yield and functionality are dramatically better for complex proteins. Yeast (S. cerevisiae) — Great for genetic screens, synthetic lethal interactions, and basic eukaryotic cell biology. The catch is that yeast lacks many metazoan-specific pathways. Signal transduction cascades like JAK-STAT don't exist in yeast. If you're studying those, you're working in the wrong system. Also, yeast has a cell wall that makes protein extraction different from mammalian cells. You need enzymatic digestion or bead beating, which adds a step most protocols don't emphasize until you've already disrupted three batches of culture. C. elegans — Transparent, short lifecycle, complete cell lineage is mapped. Excellent for in vivo imaging and developmental studies. The RNAi feeding system works for about 70% of genes, but the remaining 30% are stubborn. When I hit one of those, I don't keep trying higher IPTG concentrations or longer feeding times—that's a dead end. Instead I go straight to CRISPR knock-in with a fluorescent tag. It's more work upfront, maybe four to six weeks, but it's definitive. The feeding RNAi approach saves time on the high-percentage genes and lets you screen faster. Just don't treat it as universal.
Get the Full Details

Drosophila — Powerful genetics, well-annotated genome, Gal4/UAS system gives you spatial control that no other invertebrate offers. The downside is that some mammalian disease genes don't have clean fly orthologs. You'll find a homolog, but the protein might be missing key domains. Always verify domain conservation before committing. I once cloned a human kinase domain into a fly vector expecting it to complement a mutant allele. It didn't. The fly ortholog lacked a regulatory loop that the human version had. Sequencing the fly cDNA first would have caught that in a day instead of a month. Mus musculus — The gold standard for translational research. The cost and time are the reality check. A knockout line takes six to nine months from design to breeding. Conditional lines with Cre drivers add another three to six months. If your question can be answered in a simpler system, do that first and validate in mice afterward. This isn't conservatism. It's resource management. Mice cost roughly $3 to $5 per day per animal in housing, and your IACUC protocol alone can take two to four months to get approved depending on your institution. Arabidopsis thaliana — For plant molecular biology, this is your default. Transformation is straightforward with floral dip. The T-DNA insertion lines from the ABRC collection mean you rarely need to generate your own knockouts. The limitation is that Arabidopsis is a broadleaf plant. If you're studying grain crops or woody perennials, the physiology diverges enough that findings don't always translate. I've seen papers where a signaling pathway proven in Arabidopsis failed to reproduce in rice or wheat because the pathway had undergone lineage-specific duplication.
Zebrafish — External development, optical clarity in embryos, high fecundity. Good for developmental genetics and live imaging. The genome is fully sequenced and CRISPR works efficiently. The drawback is that adult zebrafish are larger than you'd expect for a lab tank setup, and they need heated water systems. A single rack of 12 tanks with recirculating water can draw significant electricity. Also, zebrafish have a whole-genome duplication event, meaning many genes have two paralogs. Knocking out one often shows no phenotype because the other compensates. You need double knockouts, which increases the breeding complexity substantially.
Common Mistakes That Wasted My Time
The biggest one I keep making is underestimating passage number effects. When I switch from low-passage HeLa cells to high-passage ones for a transient transfection, the efficiency drops without any obvious morphological change. The cells look fine. The transfection just doesn't work. I now freeze early-passage backbones and only use passages 15 through 25. Beyond that, I start a new vial. This habit replaced three months of inconsistent results I used to chalk up to "technique variability." Another issue: codon bias. When expressing a mammalian gene in E. coli, the rare codons cluster in specific regions. The ribosome stalls, the protein truncates, and you end up with a smear on your gel instead of a clean band. Using codon-optimized constructs from commercial services usually fixes this, but I've found that optimization alone isn't enough if the mRNA secondary structure around the start codon is too stable. A melting temperature above -8 kcal/mol at the ribosome binding site will slow initiation significantly. I check this with mfold or NUPACK before sending any construct for synthesis. Takes ten minutes and prevents weeks of troubleshooting. There's also the issue of organism-specific contamination. Mycoplasma testing catches most things, but it doesn't detect phage in bacterial cultures or fungal spores in fly vials. I learned this the hard way when an entire batch of C. elegans cultures crashed overnight. The NGM plates looked normal. The animals were lethargic but not dead. A Gram stain of the plate revealed bacterial overgrowth that mycoplasma tests wouldn't flag. Now I routinely streak plates on non-selective media and incubate at 30 degrees Celsius for 48 hours before using them. Simple, cheap, and it caught the contamination that almost cost me six weeks of work.

When Model Organisms Fail You
No single organism covers every question. If you're studying something like prion-like protein aggregation in neural tissue, C. elegans can model it, but the aggregation kinetics differ from mammalian systems because the chaperone networks are simpler. If you need drug metabolism data, mouse hepatocytes are closer to human than rat or rabbit for some CYP450 enzymes but further for others. There's no universal proxy. For membrane protein structural work, I usually start with insect cells (Sf9 or High Five) because they do proper lipidation and have the right chaperone environment. Bacterial expression fails for anything with more than four transmembrane domains. Mammalian cells work but grow slowly and give lower yields. Insect cells sit in a middle ground that's fast enough for screening and accurate enough for most crystallization attempts. The transition from insect to mammalian is worth it only when you specifically need human-specific glycoforms, which adds about three weeks to the pipeline and doubles the cost. The organism choice should match the deepest level of mechanistic detail you actually need. If a yeast two-hybrid screen tells you two proteins interact, that's useful. If your paper requires co-IP from mammalian cells, native tagging, and functional rescue, then yeast was never going to be sufficient. Don't build a three-organism pipeline because you started with the wrong one. Pick the simplest system that can answer your specific question, then upgrade only when the data demands it.