Hardy-Weinberg Modeling Labs and Why They Still Break
Most high school and college intro bio courses have students model gene pools using beads, M&Ms, or simple software simulators. The point is straightforward — demonstrate allele frequencies, genotype distributions, and the five conditions Hardy-Weinberg requires for equilibrium. The reality of grading these labs is considerably less clean. I spent years watching students fumble through this lab and grading hundreds of nearly identical write-ups. The answer key you find online usually covers the textbook calculations perfectly but says absolutely nothing about the common ways these labs fall apart in practice. Let me walk through what actually happens.
Modeling A Gene Pool Lab Answer Key
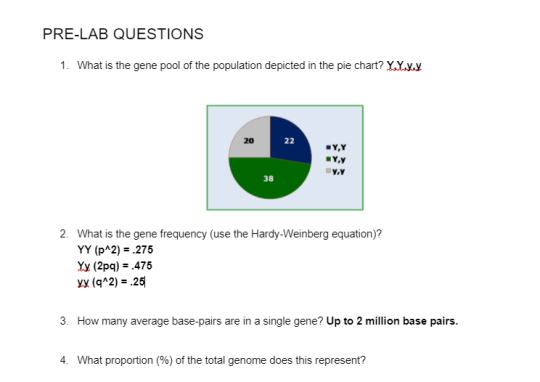
The core of this lab hinges on two equations. One tracks allele frequencies using p and q where p plus q equals one. The other predicts genotype frequencies with p squared plus two pq plus q squared equaling one. Any competent answer key will show students plugging observed phenotypes into the q squared term first, solving for q, then deriving p, then calculating the expected heterozygous and homozygous dominant counts. Here is where the simple math meets the messy classroom. I once had a class where every single group pulled different allele frequencies from the exact same bead mix. The bag we used had roughly 60 percent red beads representing the dominant allele and 40 percent white for recessive. But students sampling with spoons instead of their hands consistently undersampled the red beads because the spoons caught on the bottom of the container. The calculated q values ranged from 0.31 to 0.52 across groups who should have all landed near 0.40. Their answer keys showed wildly different results even though the procedure was identical. The fix was simple enough after the fact. Switch to sampling with a flat-bottomed tray so the beads distribute evenly, or better yet, use a randomized number generator built into free tools like PopGen or simple Excel sheets. That removes the physical sampling error entirely. Students still learn the math the same way but the numbers actually converge.
Another answer key detail most sources skip involves distinguishing between observed and expected values. The lab usually asks students to compare what they sampled against what Hardy-Weinberg predicts. You need to run a chi-square test for that comparison. The formula is the sum of observed minus expected squared divided by expected across all three genotype categories. If your chi-square value exceeds the critical value at your chosen significance level, typically 0.05 with two degrees of freedom giving you a threshold around 5.99, the population is not in equilibrium. Students routinely miss that the degrees of freedom here equal three minus one minus one. The minus one comes from the total sample size constraint and the other minus one comes from estimating q from the data itself. That gives you two degrees of freedom, not three. Getting that wrong flips your conclusion on whether evolution is happening in your model population. When evolutionary forces are introduced into the lab — selection, genetic drift, mutation, migration, or non-random mating — the answer key shifts. For selection against a recessive phenotype, you apply a fitness coefficient. Homozygous recessives might get a fitness of zero or something like 0.7 depending on the scenario. You recalculate allele frequencies each generation using the formula that weights each genotype by its fitness before normalizing. The allele does not disappear quickly even under strong selection because heterozygotes shield the recessive allele from removal. This is a point students consistently underestimate. Dropping the selection coefficient to something mild like s equals 0.1 still takes dozens of generations to shift p noticeably.
Get the Full Details
For genetic drift simulations, small population sizes matter. I recommend running the simulation with N equal to 10 and watching the allele frequency bounce around randomly for 20 generations. The result will vary wildly between groups. That is the entire point. A larger population like N equal to 100 will stay much closer to the starting frequency. Drift is stronger in smaller populations and the answer key should reflect that variance, not just a single expected trajectory. Common pitfalls to watch for. First, students often forget that p plus q must always equal one at every step. When drift or selection changes the frequencies, you recalculate both values from scratch rather than assuming the original p still holds. Second, rounding errors compound fast across generations. If you round q to two decimal places each generation in a drift simulation, the final result can drift significantly from what you would get keeping full precision. Keep at least four decimal places during intermediate steps and round only in the final report. Third, and this trips up advanced students, the assumption of no mutation in Hardy-Weinberg is the easiest condition to violate when you introduce a mutation parameter. Even a tiny forward mutation rate from the dominant to recessive allele like one in ten thousand per generation will slowly erode the dominant allele over hundreds of generations. Standard answer keys rarely include this scenario but it is useful for showing how mutation alone, while slow, is a permanent source of genetic variation.
If you need the actual answer key document, most instructors distribute it through their learning management system rather than public sites. Searching online for Modeling A Gene Pool Lab Answer Key will pull up various PDF repositories but quality varies. The best versions include the chi-square calculation steps, generation by generation tables for selection and drift scenarios, and a brief explanation of why deviations from equilibrium matter biologically. A bare calculation sheet without that context is not much use to anyone actually trying to learn the material. Some instructors also offer virtual alternatives to the bead lab. PhET has a population genetics simulator that handles the math automatically and lets you tweak selection pressure, population size, and migration rates in real time. It skips the tactile feel of physical sampling but gives you cleaner data for demonstrating the concepts. I use both depending on the class size. Physical labs work better for twenty students or fewer. Beyond that, the virtual tool saves enough time that you can actually discuss the results instead of just crunching numbers all period. The limitations of this lab are worth noting upfront. It models idealized conditions that barely exist in nature. Real populations face overlapping selective pressures, fluctuating sizes, and complex mating structures. The lab teaches the null hypothesis well — any deviation from Hardy-Weinberg expectations signals that some evolutionary force is at work. But students sometimes walk away thinking equilibrium is a realistic baseline rather than a theoretical reference point. That misconception is harder to correct than the math itself.
If your goal is purely calculation practice, the standard answer key format covers it. If you want students to understand why the model matters for real evolutionary biology, push them past the numbers. Ask what natural populations actually violate each of the five assumptions and have them find examples. The lab becomes significantly more useful when it connects to something beyond the classroom worksheet.