Building a Multiple Choice Math Test That Actually Works
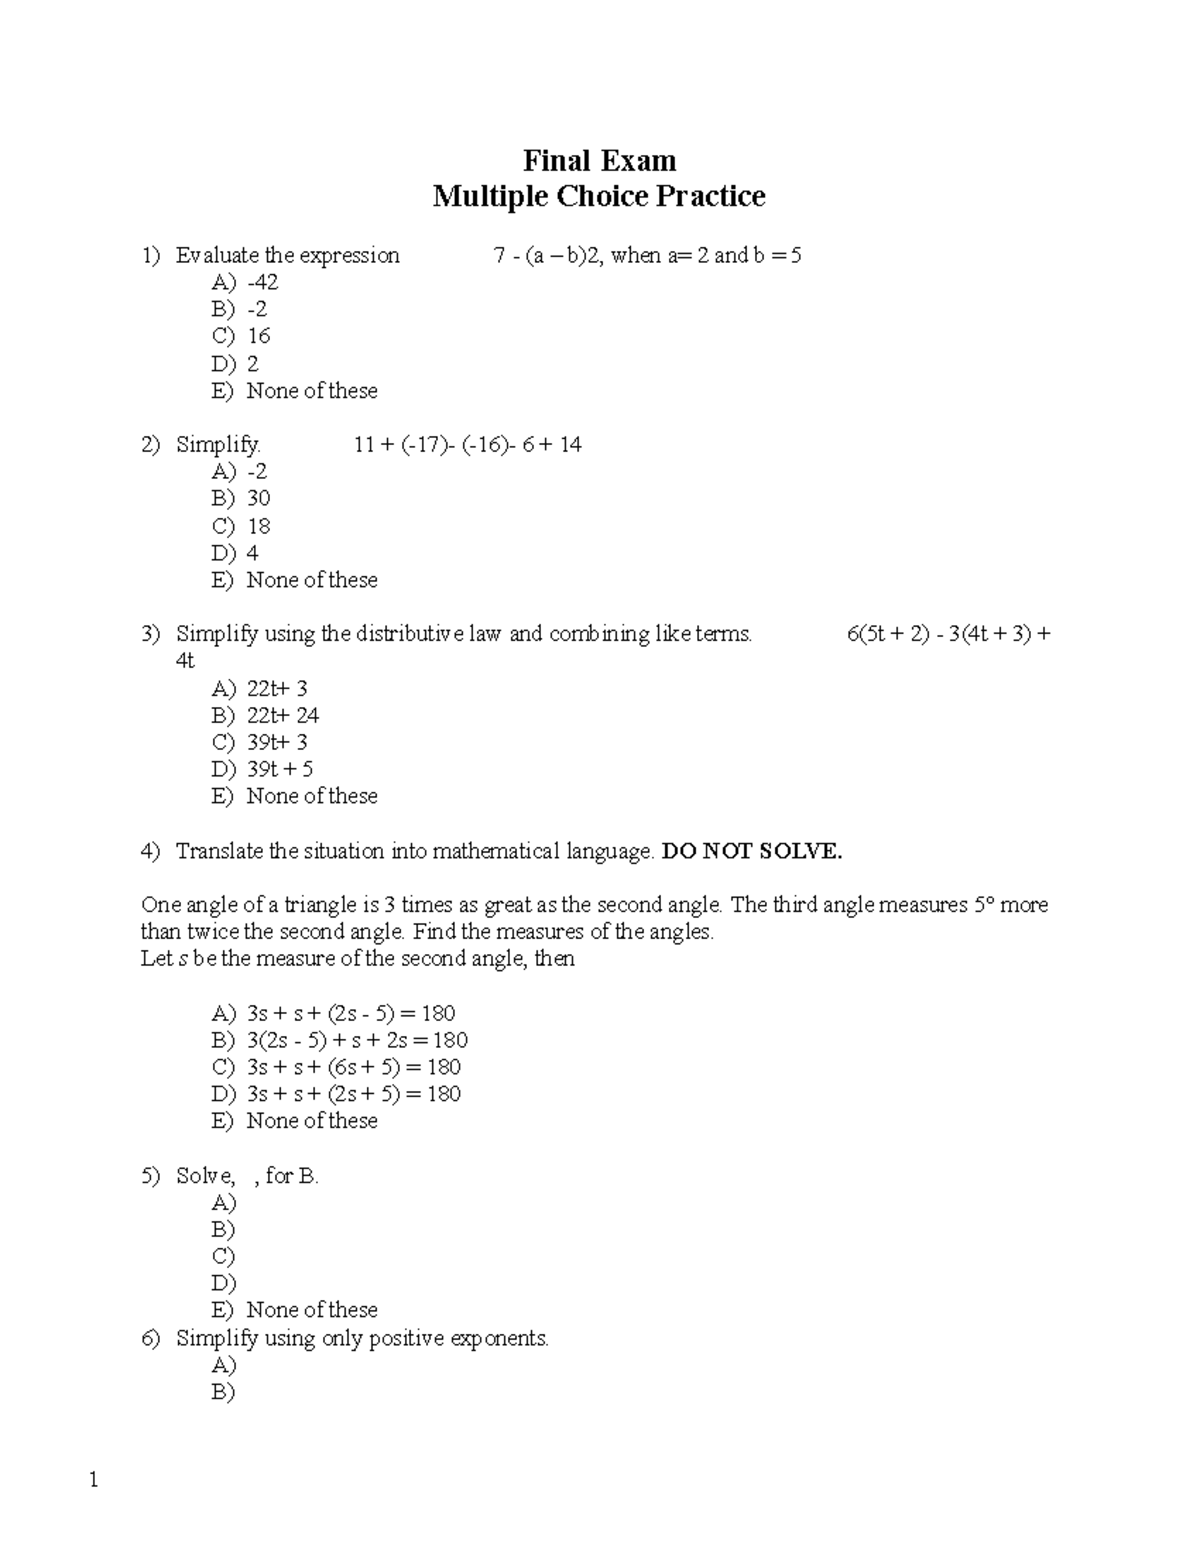
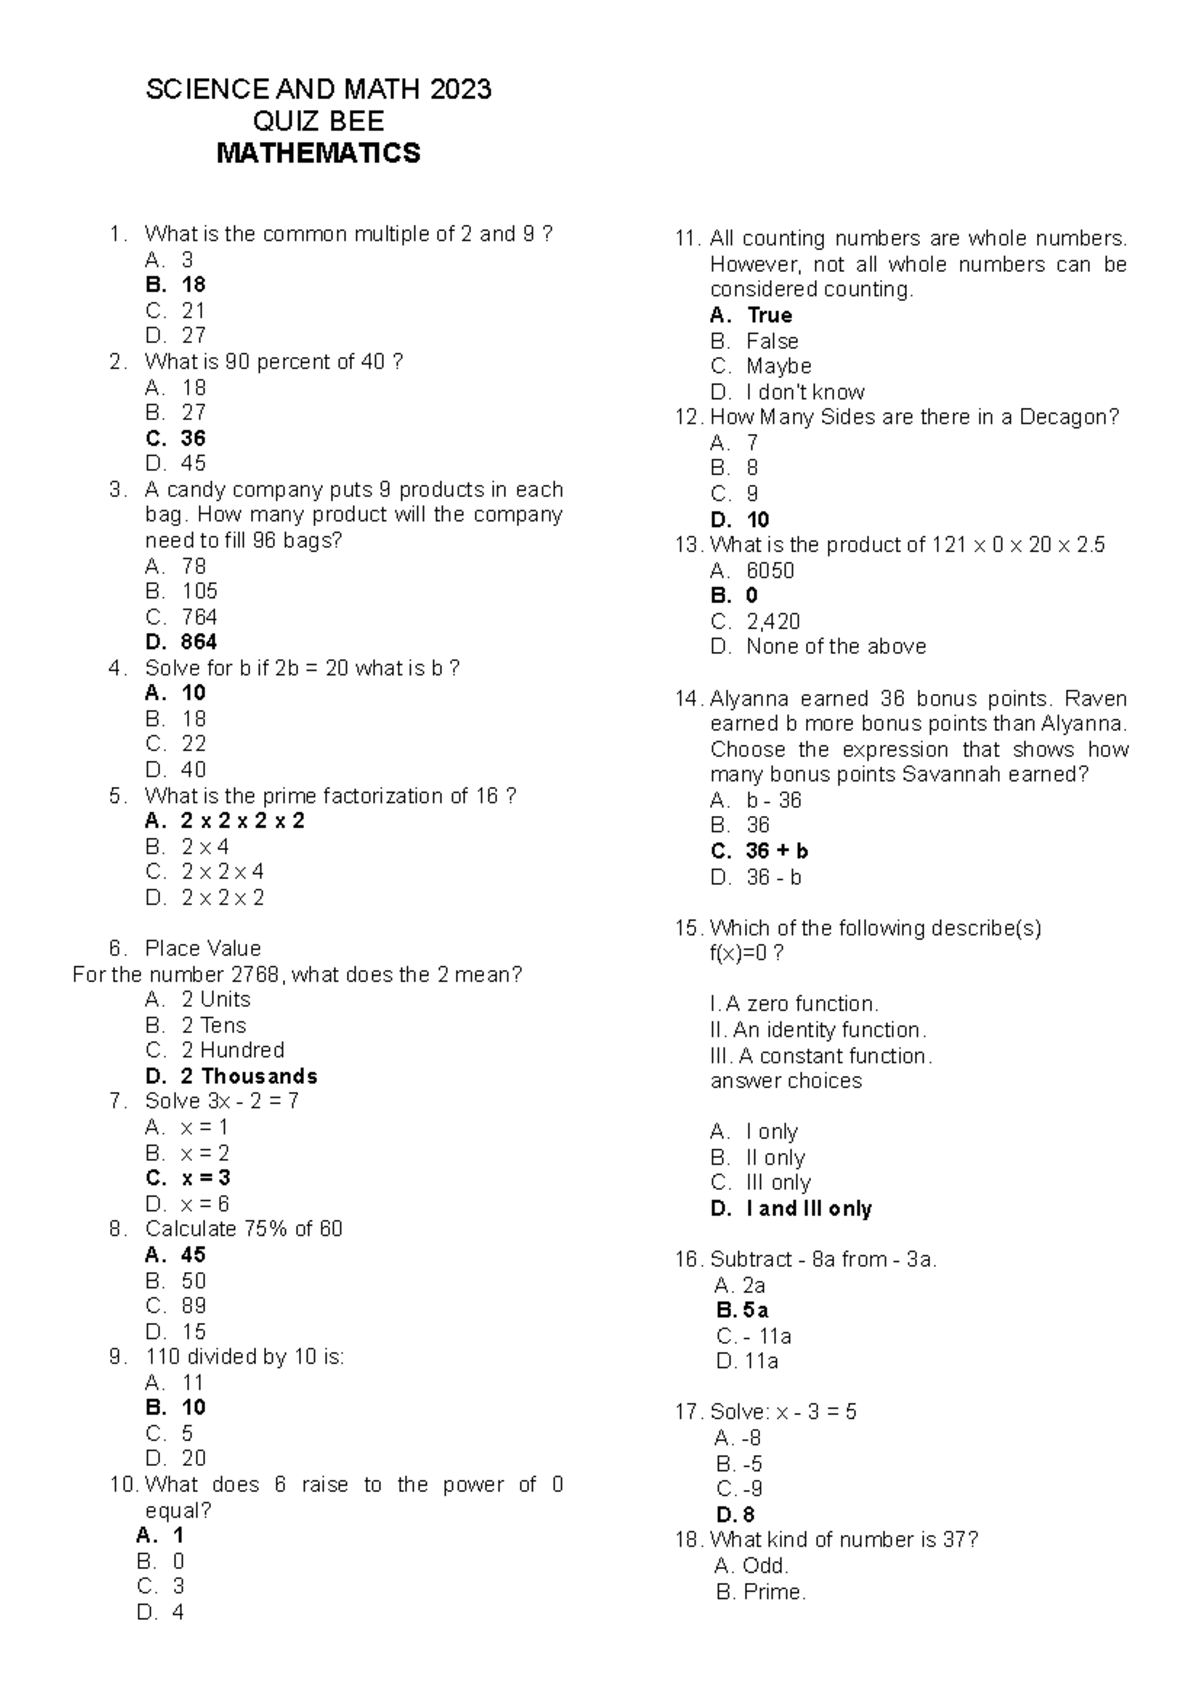
Most people treat multiple choice math questions as an afterthought. They paste a problem, slap in four numbers, and call it a day. The result is garbage data and students who learn nothing. I spent three years grading these tests across different curriculums, and the difference between a test that measures understanding and one that measures guessing ability comes down to how you construct each item. The core problem with poorly designed math tests is distractor quality. A distractor is the wrong answer you include alongside the correct one. If your distractors are random numbers, the test becomes trivial. Students eliminate options through estimation alone and never demonstrate actual reasoning. I once built a quadratic equations quiz where three of the four choices were plausible but computationally sound paths to wrong answers — the kind you get when students skip the middle step and jump straight to a conclusion. Only about 18 percent of students picked the actual correct answer because the distractors were so well-constructed that even strong students second-guessed themselves on two of the four problems. The workaround I eventually settled on was building every question backward from student errors. I compiled a spreadsheet of the top fifteen mistakes from each topic area, then turned each mistake into a distractor. This meant the wrong answers weren't arbitrary — they were specific, predictable wrong conclusions that revealed exactly what misconception a student held when they chose that option. When a student picked distractor C on a linear equations question, I knew whether they had added instead of multiplied, distributed incorrectly, or flipped a sign. The test stopped being a score and became a diagnostic map.
For generating the actual question stems, keep them short and unambiguous. A stem should state a single problem that can be resolved in one calculation path. Long word problems that require reading comprehension before you even get to the math are not a testing problem — they are a literacy problem wearing a math costume. I learned this the hard way when my remedial algebra class scored six points lower on functions questions embedded in multi-paragraph word problems than on the same questions stripped down to bare equations. The content was identical. The reading load had dropped their effective math score by nearly a full letter grade.
Item Construction Methods
There are three reliable ways to build these questions, and each has a time cost that scales differently. Method one: hand-crafted questions. This is the slowest approach. You write the stem, compute the correct answer, then generate three plausible wrong answers based on known error patterns. For a single well-constructed question, budget twenty to forty minutes. For a thirty-question test, expect six to twelve hours if you are doing it right. The payoff is that every item tells you something specific about student thinking. Method two: algorithmic generation. You write a script that randomizes parameters within a template and computes both the correct answer and common wrong answers. A Python script using sympy can generate twenty unique quadratic equations in roughly eight minutes, complete with factoring errors and sign flips baked into the distractors. The catch is that algorithmic generation produces quantity over quality unless you also program distractor logic, which adds significant development time upfront. I have a working script that takes about forty-five minutes to set up and then generates unlimited question sets afterward.
Get the Full Details
Method three: remixing from existing banks. Many publishers and open-source collections offer question banks. The risk here is that the distractors may not align with your students' specific misconceptions. If you adapt questions from a bank, rework at least half the wrong answers to match your class's error patterns. This usually takes five to ten minutes per question and dramatically improves diagnostic value.
Technical Implementation Details
If you are building these tests digitally, the answer key format matters more than people realize. Use a structured key that includes not just the correct option but the topic code and the intended distractor mapping. A minimal format looks like this: question ID, correct answer letter, topic tag, and notes on what misconception each distractor represents. This allows you to run item analysis later and identify which questions are performing poorly or which misconceptions are persisting across a cohort. When I switched from simple answer sheets to keyed analysis formats, I was able to spot a consistent failure pattern in my trigonometry section within two weeks. Students were systematically choosing a distractor that corresponded to using degrees instead of radians in a derivative problem. That single insight let me adjust the next week's lesson instead of grinding through thirty more identical problems.
Limitations and Where This Approach Fails
Multiple choice math tests have hard ceiling effects. They cannot assess proof-writing, derivation, or multi-step problem solving where the process matters more than the final number. If your curriculum requires students to show work or justify steps, a multiple choice format will give you a false sense of comprehension. I have seen programs replace all essay and proof questions with multiple choice and report a fifteen percent average score increase, while independent assessments showed no improvement in actual mathematical reasoning. The test measured something, just not the right thing. Guessing is another structural weakness. Even with four options, a student who eliminates one wrong answer raises their expected score from 25 percent to 33 percent without knowing the material. Adding "all of the above" or "none of the above" as options makes this worse, not better, because it introduces a fifth implicit choice that biases toward selection. The standard fix is to score with a correction formula: subtract one-fourth of a point for each wrong answer and add one point for each correct answer. This dampens the guessing advantage but does not eliminate it, and some educators argue it penalizes risk-averse students who leave questions blank. For topics like calculus proofs, geometric constructions, or modeling problems where the answer is not a single value, multiple choice is the wrong tool entirely. In those cases, switch to short response or performance-based assessment. Do not force a square peg into a round hole just because the grading is easier.
Practical Workflow for a Standard Test
Here is the sequence I use when building a test from scratch. It takes roughly two to three hours for a thirty-question assessment. Start by listing the learning objectives. Not the chapter titles — the actual skills. "Solve for x in a linear equation" is a skill. "Chapter three" is a location. Write down four to six objectives for a standard test. For each objective, write two question templates: one procedural and one conceptual. Procedural means calculating a value. Conceptual means identifying a property, comparing values, or interpreting a result. A balanced test has roughly equal weight between the two types.
Draft each stem on its own line with the correct answer computed first. Then add distractors by referencing your error compilation or running common mistake algorithms. Verify every distractor by working the problem backward — confirm that each wrong answer is reachable through a specific, identifiable error path. Assemble the test in order of increasing difficulty if possible. Students who struggle should encounter simpler items first, which reduces anxiety and gives you a clearer signal about where the breakdown happens. Shuffle the final order only if you are distributing to multiple sections to reduce cheating. Run a pilot with five to ten students who are not in your target population, or walk through every question yourself under timed conditions. I time myself at one and a half minutes per question for standard high school level material. If I consistently overshoot that on any item, the question needs to be simplified or moved to a harder form.
Scoring and Analysis
Once the test is administered, the raw score is the least useful number you will see. The item difficulty index — the percentage of students who answered each question correctly — tells you far more. Questions with a difficulty below 0.3 are likely too hard or poorly written. Questions above 0.9 are too easy and provide no discrimination. Aim for a spread between 0.4 and 0.8 across most items. The discrimination index measures whether high-performing students got the question right while low-performing students got it wrong. A negative discrimination value means the question is broken — either the answer key is wrong or the question is ambiguous. I discard or revise any question with negative discrimination before reporting scores. For a full test with thirty questions, running this analysis takes about twenty minutes in a spreadsheet if you have clean data. Some learning management systems do it automatically, but the output quality varies widely depending on the platform.

The format itself is not a silver bullet. It works well for screening, for quick formative checks, and for covering broad content areas efficiently. It fails when you need depth, when you need to assess process, or when your students are skilled at test-taking but weak in the underlying concepts. Know which situation you are in before you build the test.