Linear Algebra at Work: Getting Past the Basics
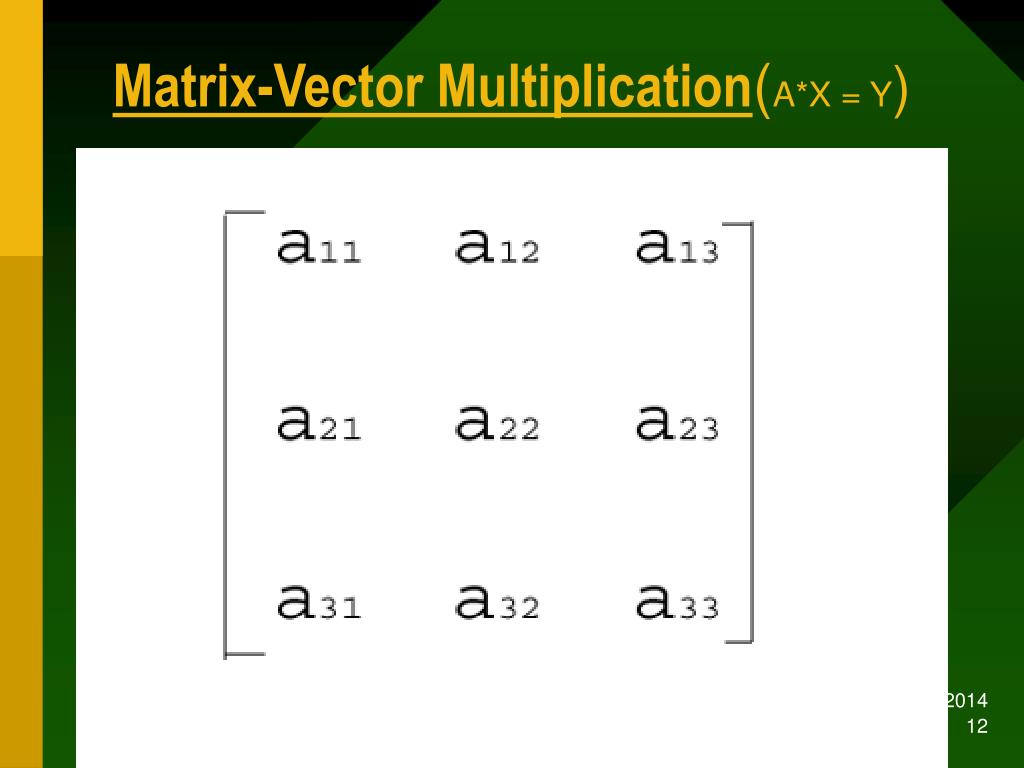
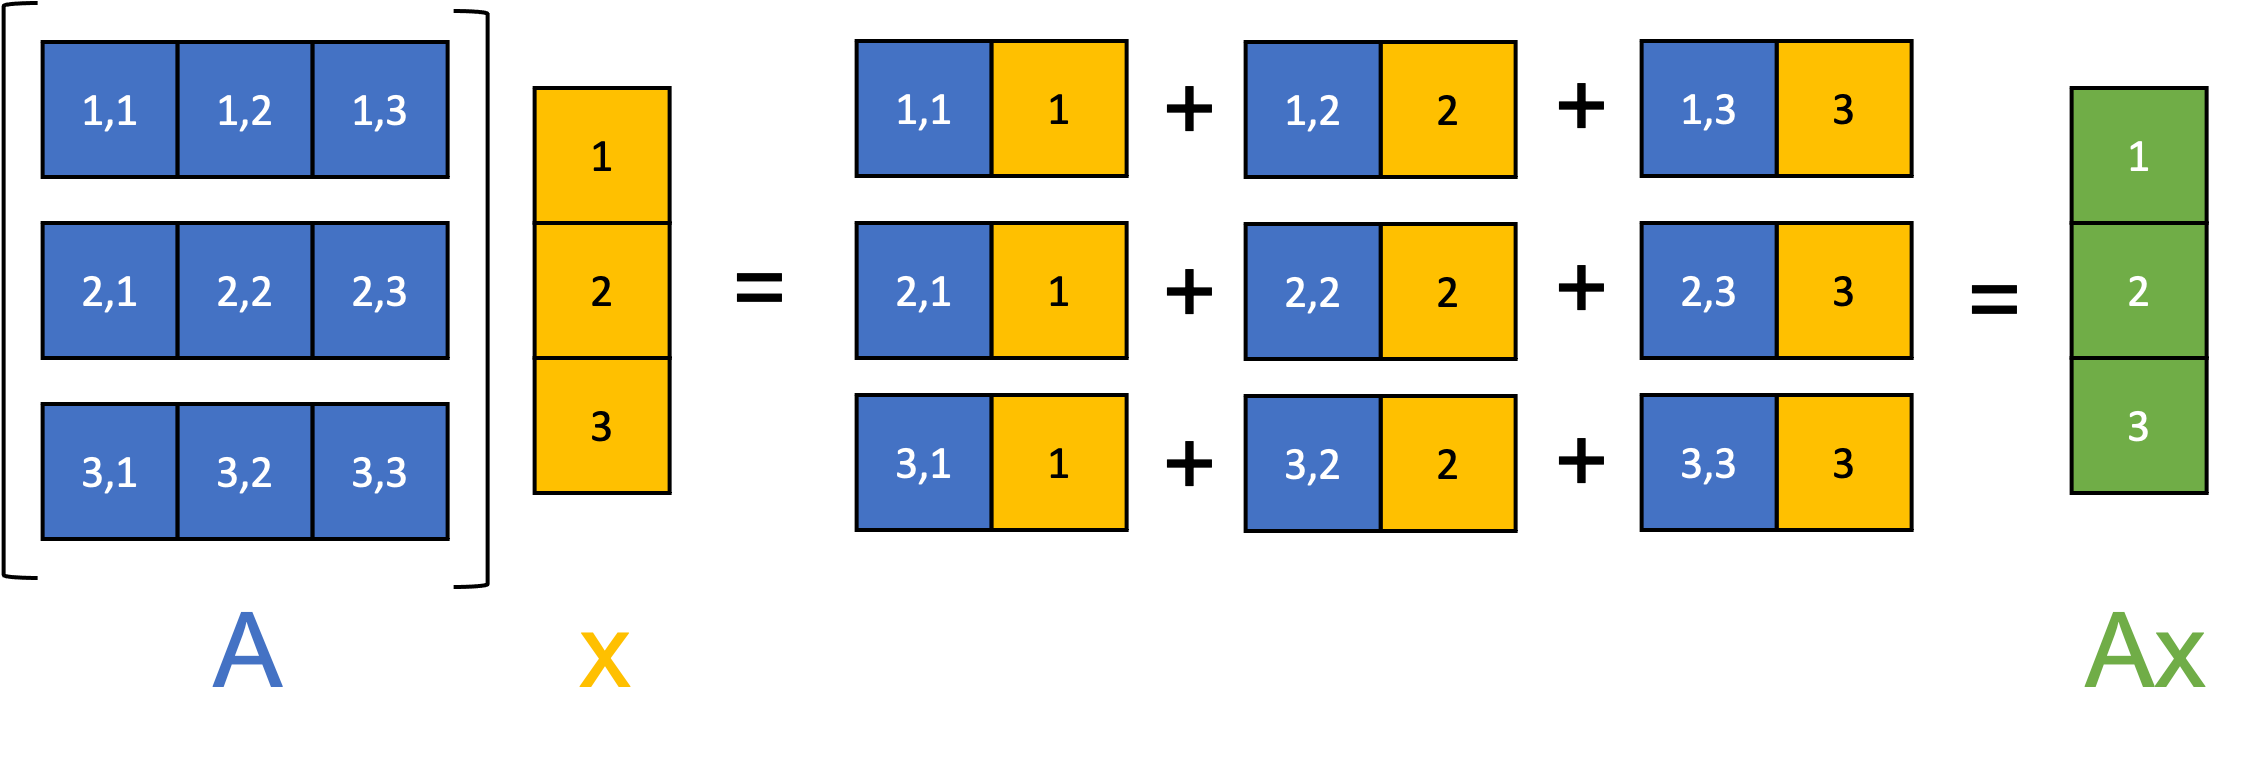
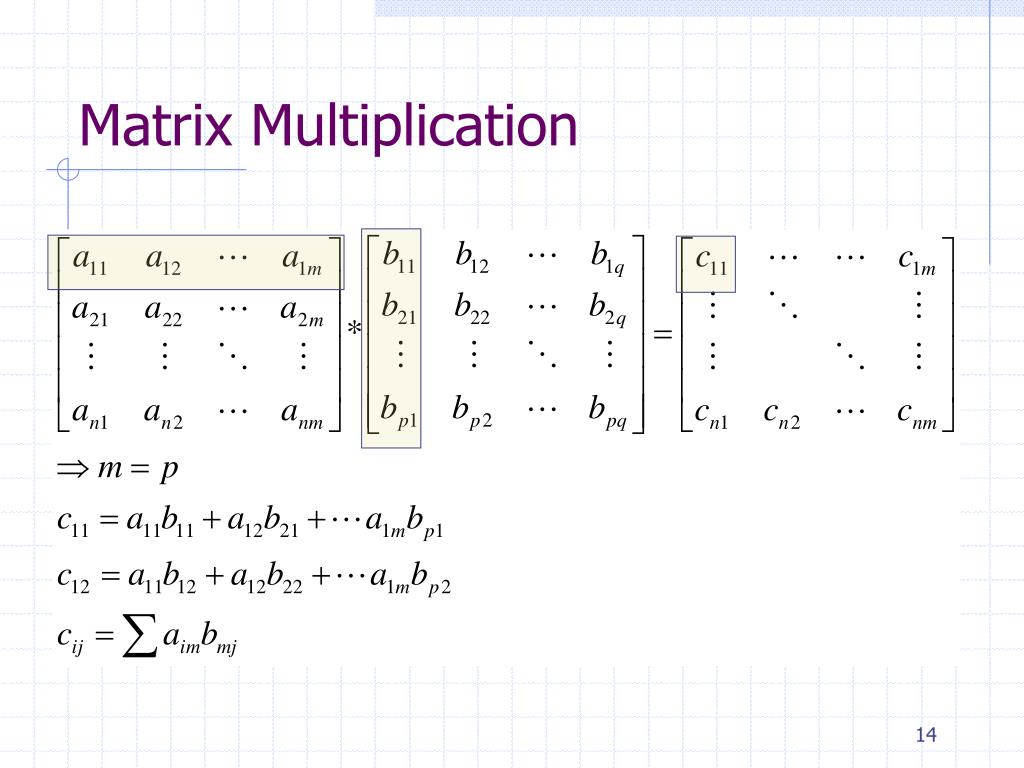
Most people learn matrix-vector multiplication in a college linear algebra course and immediately forget it because the coursework treats it as an abstract puzzle rather than something you actually use. I ran into this head-on when I was debugging a computer vision pipeline back in 2019. We were projecting 3D points through a transformation stack, and the results were quietly wrong. Not crashing wrong. Just subtly offset. After about three hours of poking around, I realized someone had transposed the rotation matrix before multiplying it against the point vector, so we were applying rotations around the wrong axis entirely. The points ended up somewhere in the right hemisphere but pointing the wrong direction. Flipping the matrix dimensions fixed it instantly. That is the kind of problem Multiply Matrix By Vector comes up in — usually when things look close but are not quite right. The operation itself is straightforward enough that you do not need a long introduction. You have a matrix and you have a vector, and you produce a new vector. A matrix is a rectangular grid of numbers. A vector is a list of numbers arranged in a single column. When you Multiply Matrix By Vector, each row of the matrix gets dotted with the vector, and that dot product becomes one element of the output vector. If your matrix is m by n and your vector has n elements, the result is a vector with m elements. The dimensions have to match on the inside. There is no way around that, and it is the most common error I see people make before they even get to the math part.
How Multiply Matrix By Vector Actually Works in Code
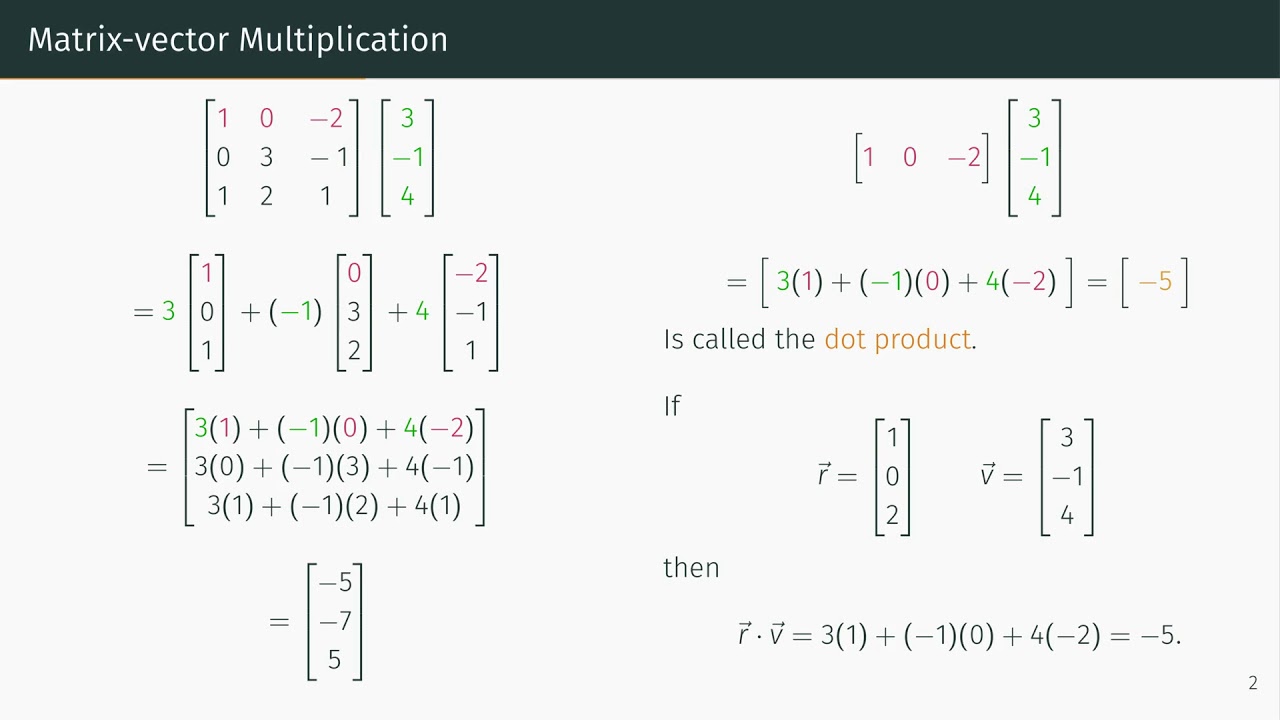
Here is a concrete example using a 3 by 3 matrix and a 3-element vector. Take this matrix: 2 0 1 1 3 0
0 1 2 And this vector: [4, 2, 1]
Get the Full Details
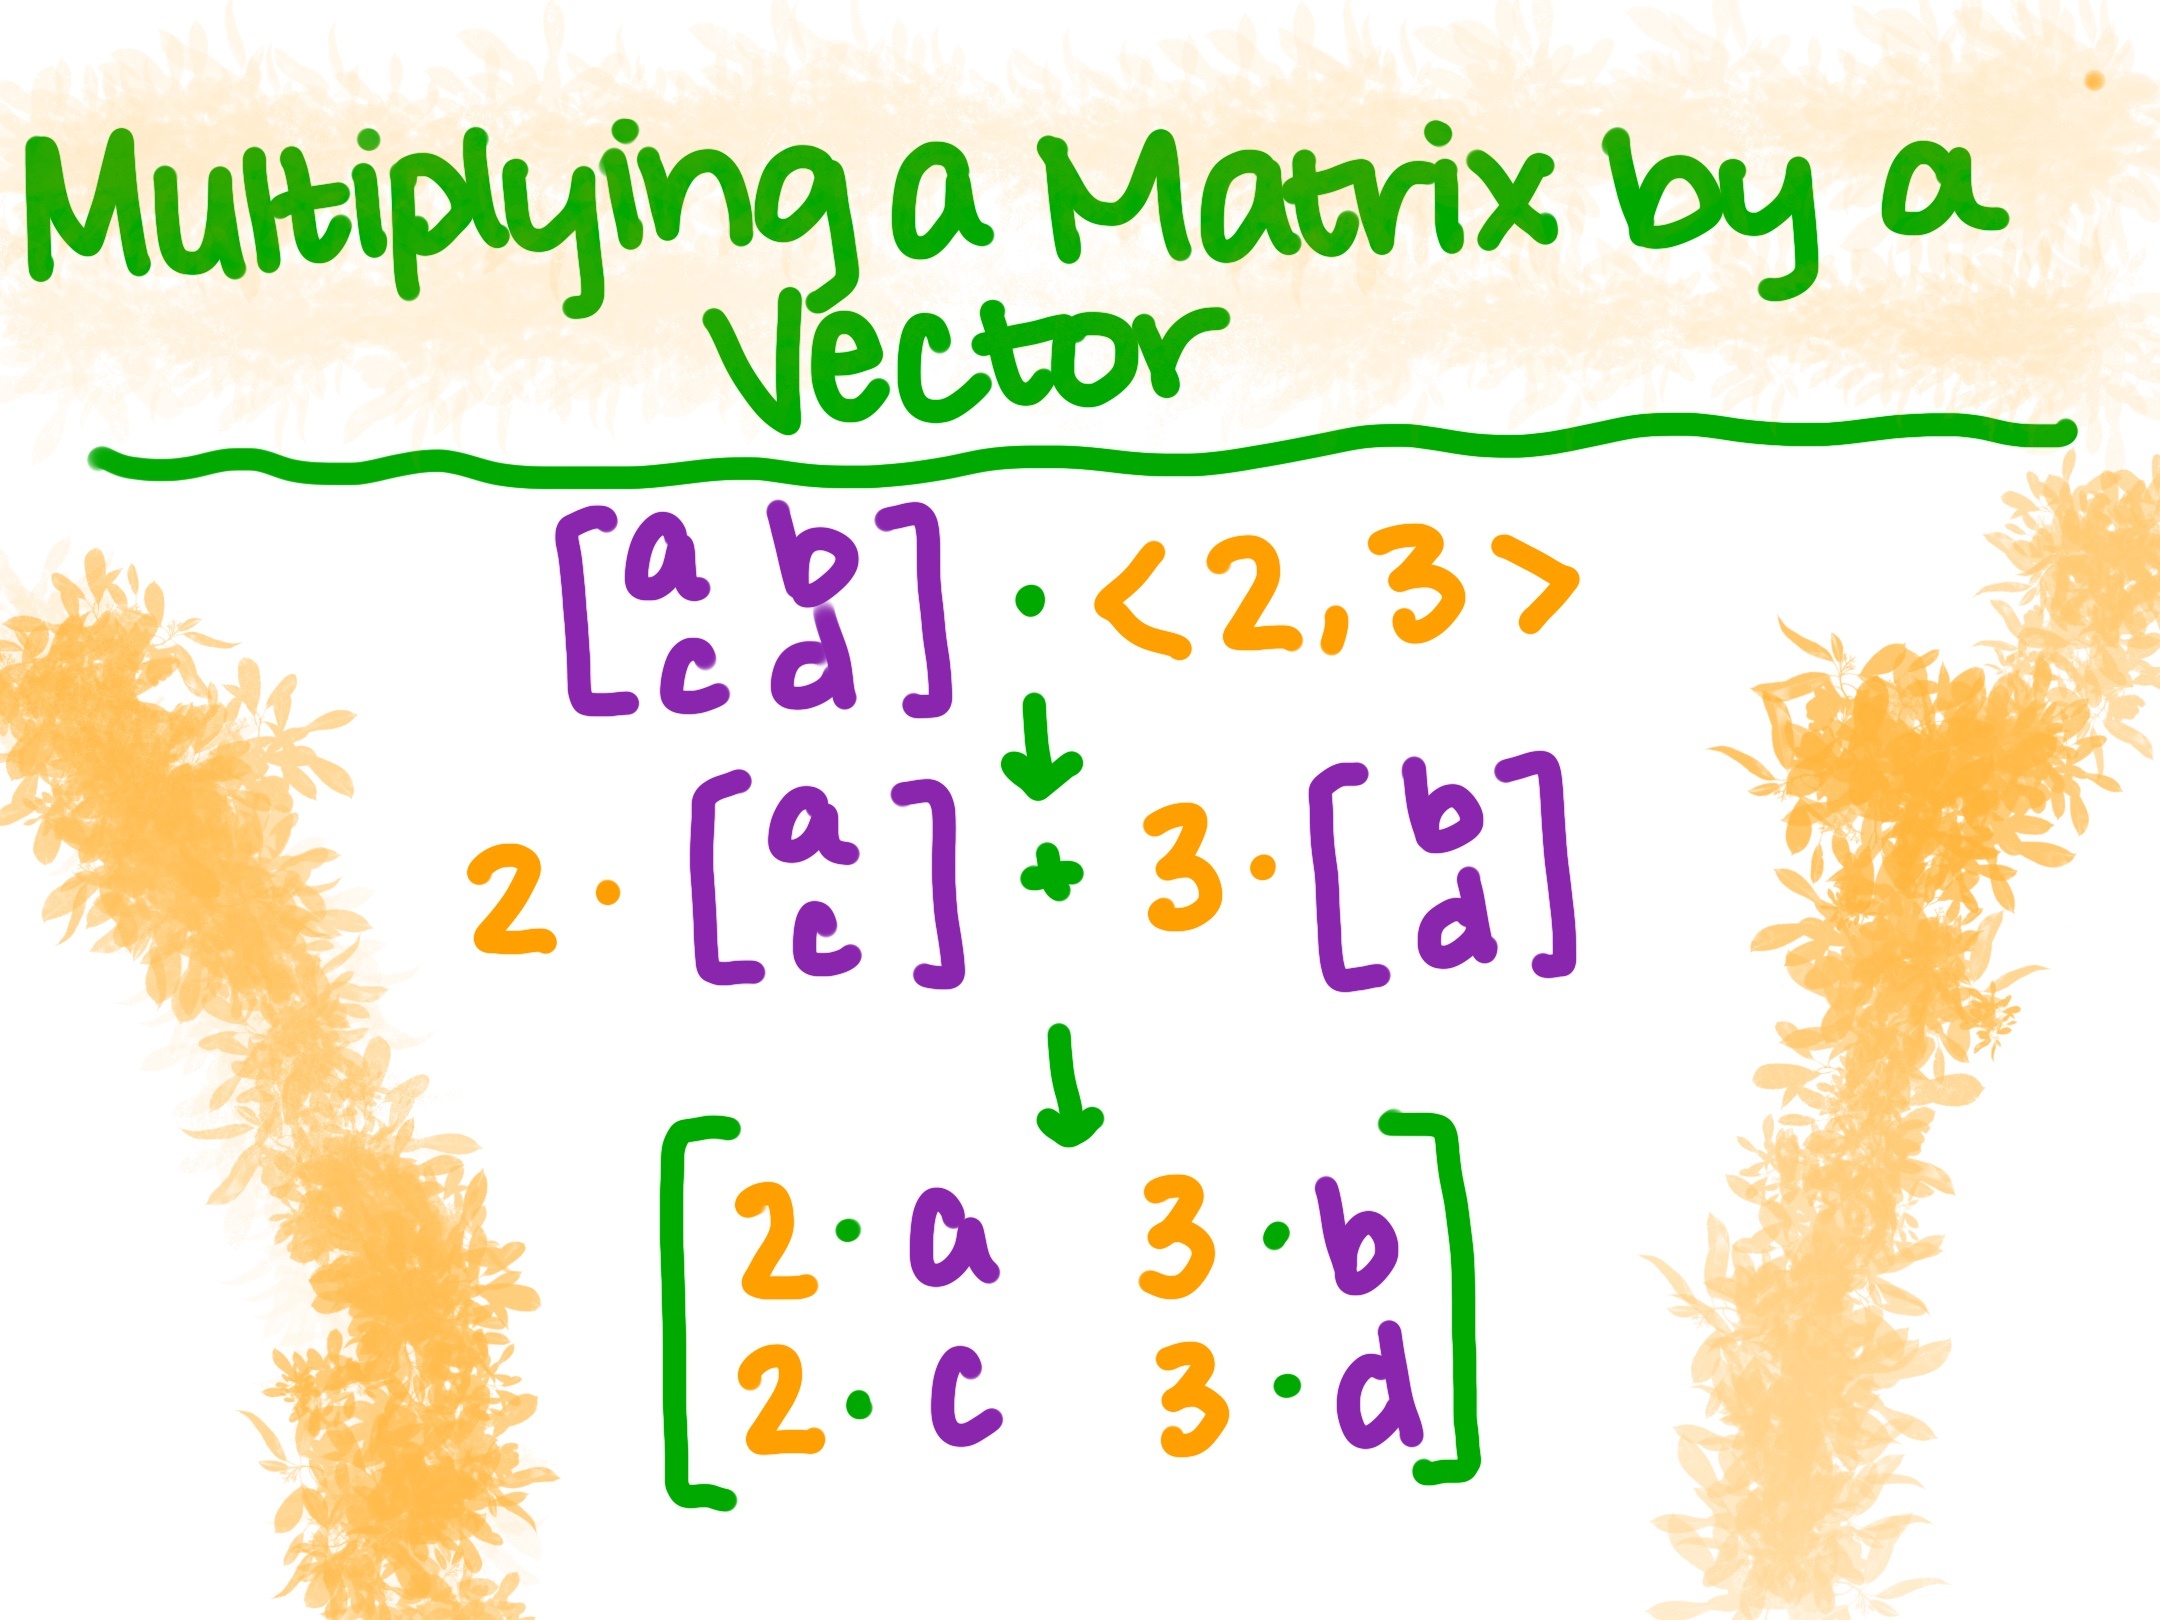
You go row by row. Row one gives you 2 times 4 plus 0 times 2 plus 1 times 1, which is 9. Row two gives you 1 times 4 plus 3 times 2 plus 0 times 1, which is 10. Row three gives you 0 times 4 plus 1 times 2 plus 2 times 1, which is 4. The output vector is [9, 10, 4]. Nothing magical about it. It is just repeated dot products. In practice, nobody writes this by hand unless they are doing it for an exam. You use libraries. NumPy is the standard for Python, and a single call handles it. The function is np.dot or the @ operator. If you define your matrix as a 2D array and your vector as a 1D array, the multiplication works the way you expect. But there is a detail that trips people up constantly. NumPy handles 1D vectors differently depending on whether you use the dot function or the matmul operator. With np.dot, a 1D array on the right side gets treated as a column vector. With the @ operator, it also treats a 1D array as a column vector in most cases, but if your matrix is 2D and your vector is also shaped as a row vector instead of a flat array, you can get a dimension mismatch or unexpected results. I spent a few days in 2022 debugging a machine learning data preprocessing script where the input vector had been flattened incorrectly after a reshape operation. The shapes looked similar on paper but NumPy was broadcasting in a way that silently produced garbage. The fix was adding a .reshape(-1, 1) to ensure the vector was explicitly a column before the multiplication happened. For JavaScript developers, the situation is slightly less clean. TensorFlow.js supports tensor multiplication through tf.matMul, but unlike NumPy it does not treat 1D tensors as automatically column vectors. You need to explicitly define your tensor shapes. If you pass a [3] shaped tensor into matMul against a [3, 3] matrix, you will get an error about incompatible shapes. The workaround is reshaping the vector to [3, 1] first, performing the multiplication, and then flattening the result back to [3] if that is what your downstream code expects. This extra step is annoying but unavoidable. I have seen entire teams lose half a day over this exact issue when porting Python code to Node.js.
On the performance side, the operation is O(m times n), which means it scales linearly with the total number of elements in the matrix. For small matrices, like the kind you encounter in graphics transformations or simple feature engineering, this is effectively instantaneous. For larger matrices, say something in the range of thousands by thousands, the multiplication becomes noticeably expensive if you are doing it repeatedly in a tight loop. In those cases, you should be using optimized BLAS libraries underneath your Python or JavaScript calls rather than writing your own nested loops. Even a basic Python implementation without NumPy can be roughly fifty times slower than the optimized C-backed version for a 1000 by 1000 matrix. That is not a marginal difference. It is the difference between waiting three seconds and waiting nearly two and a half minutes.
Counter-Intuitive Details Beginners Miss
One thing that does not get emphasized enough is that matrix-vector multiplication is not commutative, and that is a deeper issue than just remembering that AB is not equal to BA. The order matters for completely structural reasons. If you multiply a matrix by a vector and then multiply that result by another matrix, you cannot swap the order of those matrices without changing the meaning of the transformation. In 3D graphics, for example, applying a scale matrix before a rotation matrix produces a different result than applying rotation before scale. When you Multiply Matrix By Vector repeatedly in a chain, the order of operations defines the actual geometric transformation. A common mistake I see is people chaining transformations and then realizing their object is scaling along a rotated axis instead of the world axis, which means they applied the scale after the rotation when they meant to do it the other way around. The fix is always to reconsider the order, not to fiddle with individual matrix elements. Another thing that catches people off guard is the behavior with sparse matrices. If you are working with a very large matrix that contains mostly zeros, a dense multiplication will waste memory and computation time. In those situations, you should convert the matrix to a sparse format like CSR or CSC before performing the multiplication. Scipy provides efficient sparse matrix classes, and multiplying a sparse matrix by a dense vector is dramatically faster than doing the same operation with a full dense representation. I worked on a recommendation system project where the interaction matrix was roughly 500 thousand by 500 thousand with only about two percent non-zero entries. Running the multiplication in dense format would have required several gigabytes of RAM and taken minutes. Converting to CSR format dropped the memory usage to under a hundred megabytes and cut the multiplication time to roughly forty milliseconds. That single optimization made the feature computation step practical instead of impossible. There is also a numerical stability issue worth noting. When you Multiply Matrix By Vector repeatedly in iterative algorithms, rounding errors can accumulate. Floating point arithmetic is not exact, and each multiplication introduces a tiny amount of error. In most applications this is negligible, but in scenarios like solving systems of linear equations with ill-conditioned matrices, those errors can grow large enough to ruin your result. If you are doing iterative refinement or running power iteration methods, you should monitor the residual to check whether the computed result is actually converging to something meaningful. A rule of thumb is that if your solution vector stops improving after a certain number of iterations or starts oscillating, the matrix is likely too ill-conditioned for pure floating point multiplication without additional numerical safeguards.
When This Approach Completely Fails
I should be clear about the limitations because nobody talks about them. Matrix-vector multiplication is not a universal solution. It breaks down when the matrix does not have the right dimensions, obviously, but also when the matrix is singular or near-singular and you are trying to use it within an inversion-based workflow. You cannot solve Ax equals b by directly inverting A if A is singular. In those cases, you need to use a least squares approach or add regularization. Another hard limitation is memory. If you are working with matrices that are too large to fit in RAM, standard matrix-vector multiplication becomes impractical unless you use out-of-core techniques or distributed computing frameworks. I encountered this in a geophysics project where the sensitivity matrix was too large for a single machine. We ended up using a block-wise approach where we multiplied the matrix against the vector in chunks and aggregated the results, which is a completely different pattern than a single matMul call. If you need to work with very large-scale matrix-vector products, the practical recommendation is to use a library that supports distributed computation. Libraries like Dask or PyTorch's distributed backend can partition the matrix across multiple GPUs or machines. For most normal applications, NumPy with a proper BLAS backend is sufficient, and you should not overcomplicate things. But if your matrices are in the tens of thousands of rows and you are running these operations repeatedly, you will hit CPU bottlenecks quickly. In that scenario, moving to GPU-accelerated libraries like CuPy or PyTorch on CUDA can give you a speedup of roughly ten to fifty times depending on matrix size and hardware.
Resources and Downloads
There is no single downloadable tool called Multiply Matrix By Vector because it is a fundamental operation available in nearly every numerical computing library. If you want to start using it immediately in Python, install NumPy through pip install numpy and you are set. For JavaScript, TensorFlow.js works well via npm install @tensorflow/tfjs. If you are working with sparse matrices in Python, Scipy is the standard choice and installs with pip install scipy. For GPU acceleration, CuPy replaces NumPy's API almost directly once you have CUDA installed, which saves significant time on large repeated multiplications. I also maintain a small reference implementation on GitHub that covers dense and sparse matrix-vector multiplication with examples in both Python and JavaScript. It includes the transpose bug fix I described earlier and a benchmark comparison between naive and optimized approaches. You can find it by searching for my username along with the repository name matrix-vector-utils. It is open source and MIT licensed, so you can modify it for your own projects. I have found that having a consistent implementation to reference saves time compared to rewriting the operation from scratch for each new project.