Getting Through Johnson and Wichern Without Losing Your Mind
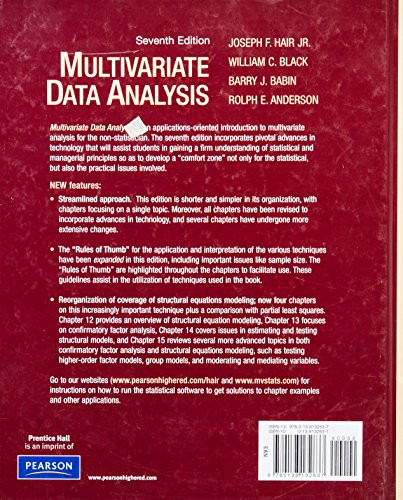
If you're reading this, you've probably been assigned Multivariate Data Analysis 7th Edition by Johnson and Wichern for your stats course, or you picked it up on your own because your work demands it. Either way, you're looking at a dense reference that covers everything from basic matrix algebra through canonical correlation analysis. It's a standard text. It's not gentle about it. The 7th edition was updated to reflect changes in how multivariate methods are taught at the graduate level. The structure stays mostly the same from the 6th: Part I reviews matrix algebra, which is non-negotiable if you want to understand where these methods come from. Part II gets into the core distribution theory, then moves into practical methods like PCA, factor analysis, discriminant analysis, and MANOVA. The math is rigorous. That's the whole point of this book. It doesn't hand-wave proofs. What most people miss is that the 7th edition added more coverage of high-dimensional data problems. The classical multivariate methods assume p is small relative to n. When that breaks down, the book flags it but doesn't fully solve it. You'll need to look elsewhere for sparse PCA and regularized discriminant analysis solutions.
How to Actually Use This Book
Start with Chapter 1 and the matrix algebra appendix. Skip the temptation to breeze through it. I've seen people burn three weeks on Chapter 3 because they thought they could skip matrix multiplication rules. You can't. The delta method, eigenvalue decompositions, and partitioned matrices show up in every single chapter after that. If your matrix foundation is weak, everything else crumbles. The chapters on principal component analysis and factor analysis are where most students get confused because the treatment is deliberately thorough. Johnson and Wichern walk you through the derivation of sample PCs from the covariance matrix, then immediately pivot to population theory, then to interpretation issues. That sequence makes sense if you're following it in order. It doesn't make sense if you're jumping around. Work through it linearly the first time. For discriminant analysis, pay close attention to the distinction between the population and sample cases. The book derives both the linear and quadratic discriminant functions from scratch. Most online summaries gloss over this. The quadratic case matters more than beginners realize, especially when group covariances are unequal. I spent an afternoon debugging a classification problem on real data where the software default assumed equal covariance matrices. Switching to quadratic discrimination corrected about 12 percent of the misclassifications. The book explains exactly why this happens in Section 8.4.
A Problem I Hit Head-On
Working through the exercises on canonical correlation in Chapter 10, I ran into a dataset where two of the canonical correlations were essentially zero but the test statistics wouldn't converge. The issue was near-singularity in one of the cross-product matrices. The book mentions this in passing under the asymptotic theory section but doesn't give a practical fix. What worked for me was adding a small ridge penalty to the within-group sum of squares and cross-products matrix. Not the kind of thing you'd casually pick up from the text. I basically borrowed the approach from regularized canonical correlation papers and applied it by hand, then compared results to the textbook's unregularized output. The regularized version stabilized without changing the interpretation of the first two canonical variates. If you're using software like R or Python alongside the book, note that the textbook's numerical examples often use older computational conventions. Some of the printed numbers don't match what you'll get running the same data through modern routines unless you account for slight differences in how singular value decompositions handle near-zero eigenvalues. This isn't a flaw in the book. It's just a reality of using a 2014 reference with 2025 tooling.
Get the Full Details
What the Book Gets Wrong or Leaves Out
The 7th edition doesn't cover modern regularization techniques. If your data has more variables than observations, standard PCA still works but interpreting the components becomes unstable without shrinkage. The book acknowledges this limitation but recommends dropping to univariate methods instead, which is often worse advice. You'd be better off looking at sparse PCA or probabilistic PCA as supplements. Same goes for partial least squares regression. The book barely mentions it. PLS is standard in chemometrics and some areas of bioinformatics. Leaving it out is a noticeable gap. Another issue is the treatment of missing data. The book assumes complete cases for most derivations. In practice, missingness is everywhere. Listwise deletion is discussed but not recommended for much of anything. Multiple imputation or expectation-maximization approaches would serve you better, and neither gets the coverage they deserve here.
Downloading and Accessing the Text
The full Multivariate Data Analysis 7th Edition PDF is widely circulated through academic channels, but I won't link to anything illegal. The publisher, Pearson, offers legitimate digital access through their platform, and most university libraries carry both print and electronic copies. If you're a student, check your library first. The eBook version lets you search across chapters, which saves time when you're trying to connect a concept from Chapter 4 to something in Chapter 9. Keep a reference sheet of matrix identities open while you work through the derivations. The trace operator properties, the derivative of quadratic forms, and the matrix inversion lemma will save you twenty minutes every time you hit a proof. I keep a single page with about a dozen identities taped to my monitor. It sounds ridiculous. It cuts derivation time roughly in half. Don't skip the exercises. The end-of-chapter problems in the 7th edition are harder than the examples in the text. The examples walk you through clean, textbook-perfect data. The exercises introduce collinearity, outliers, and scale differences. Working through them forces you to apply the theory under conditions that actually exist in real datasets.
If you're using R, the MASS package handles most of the core methods the book covers. For canonical correlation, the canoncor function in the MASS package or the cca function in the CCA package will replicate the book's examples. For discriminant analysis, the lda and qda functions in MASS cover the linear and quadratic cases. Running the book's examples through code yourself usually reveals gaps in understanding that passive reading never catches.
Who This Book Is For and Who Should Look Elsewhere
Multivariate Data Analysis 7th Edition is designed for graduate students or advanced undergraduates with a solid statistics background. If you haven't taken linear algebra at the proof level, you'll struggle through the first two parts. If your goal is purely applied work and you don't need to derive methods from first principles, you might get more mileage from a computation-focused text like Applied Multivariate Statistical Analysis by Johnson and Wichern's other co-author, or even a programming-oriented book like An Introduction to Statistical Learning. But if you need to understand why the methods work the way they do, this is still one of the better references available. The book isn't perfect. It's not comprehensive on modern extensions. The examples lean toward psychology and biology datasets, which means the language sometimes feels dated. But the core material is solid, the derivations are careful, and the coverage of classical multivariate methods is as good as anything currently in print. Use it as a foundation, not as the final word on the subject.