What Happens When You Actually Run Multivariate Analysis on Messy Real-World Data
Multivariate analysis is the act of looking at more than two variables at once and trying to figure out what relationship exists between them. Most tutorials start with perfectly normalized datasets and show you the math in a vacuum. That's not how it works outside of academia. When you pull data from a production database, you are usually dealing with missing values scattered across columns, variables on completely different scales, and correlations that make no intuitive sense until you spend a day on them.
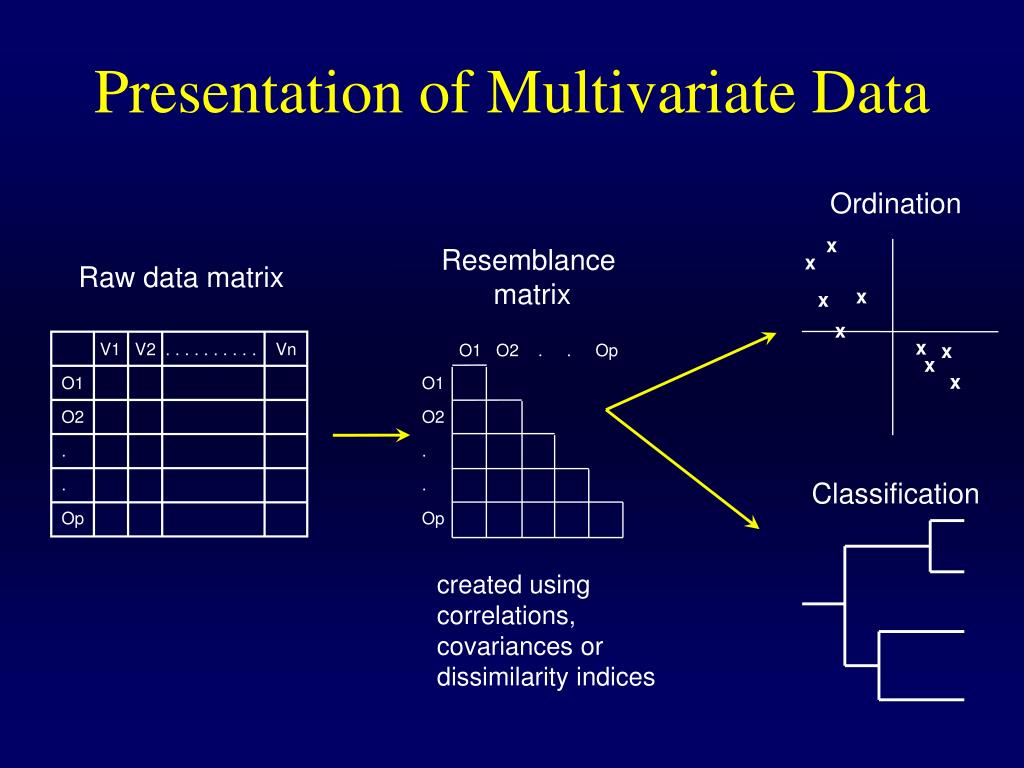
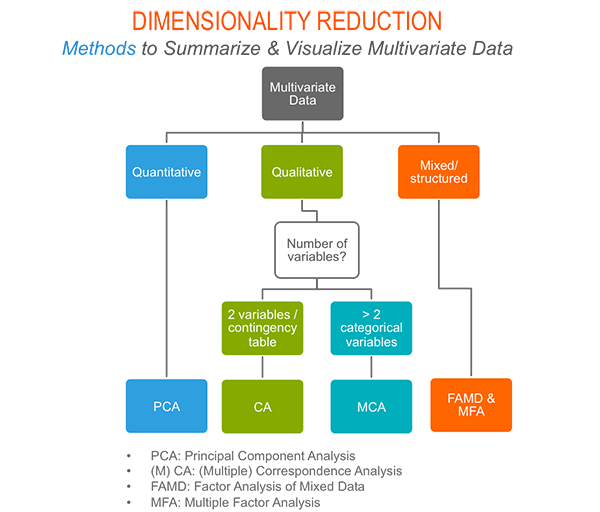
The core methods people use fall into a few buckets. Factor analysis collapses dozens of correlated variables into a smaller set of latent constructs. Principal component analysis does something similar but focuses on variance decomposition rather than underlying constructs. Cluster analysis groups observations based on similarity across all those variables. Canonical correlation looks at the relationship between two sets of variables. Discriminant analysis classifies observations into predefined groups. Each of these has assumptions that, when violated, produce garbage results, and most beginners never check whether those assumptions actually hold for their data. Let me walk through how this actually plays out when you are doing Multivariate Data Analysis In Practice, because the gap between the textbook and the desk is where most people lose time.
Why Your Data Will Break Standard Assumptions Before You Even Start
The first thing I tell anyone who picks this up is that you need to check your assumptions before you run any model, and I mean really check them, not just glance at a summary output. Multivariate normality is a standard assumption for many techniques like discriminant analysis and canonical correlation. You can test it with Mardia's test or by examining multivariate kurtosis. If your data comes from a business source, it almost certainly violates this assumption. Revenue data, click counts, response times, satisfaction scores — none of these follow a nice bell curve when combined across dimensions. When I ran a canonical correlation analysis last year on customer behavior data combining purchase frequency, session duration, page depth, support ticket volume, and churn probability, the Mardia test came back with a p-value of basically zero. The model still ran. The results were qualitatively reasonable, but the significance tests on the canonical correlations were unreliable. I switched to bootstrapping the standard errors, which meant resampling the dataset 1000 times and recalculating the canonical correlations each iteration. That gave me confidence intervals that actually reflected the uncertainty in my data. The initial run took about ten minutes. The bootstrap approach took roughly twenty-five minutes on a standard laptop, which is acceptable when your results would otherwise be questionable.
Scaling Is Not Optional, It Changes Everything
Variables on different scales will dominate distance-based methods unless you standardize them. This sounds obvious, but people routinely run cluster analysis on raw data where one variable ranges from 0 to 100 and another from 0 to 500,000. The clustering algorithm will ignore the first variable almost entirely because the second one swamps the distance calculations. Standardize with z-scores before any distance-based method. That means subtracting the mean and dividing by the standard deviation for each variable independently. Here is a nuance that beginner guides rarely mention: standardization should happen after you handle missing data, not before. If you impute missing values using the mean, and then standardize, you are fine. If you standardize first and then impute, your imputed values will be off because the mean and standard deviation you use for imputation were calculated from standardized values, which creates a circular dependency in certain imputation frameworks. It is a small detail, but it matters when you are working with more than fifteen percent missingness, which is common in observational data.
Get the Full Details

The Problem With Too Many Variables and Not Enough Observations
This is the most common structural issue in applied multivariate work. You have fifty variables and only two hundred observations. Most multivariate techniques require the number of observations to exceed the number of variables by a comfortable margin. When you flip that relationship, your model becomes unstable. Eigenvalues in PCA become noisy. Factor analysis solutions refuse to converge reliably. Discriminant analysis breaks down because the within-group covariance matrix becomes singular. The practical workaround is dimensionality reduction before you run your primary analysis. I typically run a PCA and look at the scree plot combined with parallel analysis, which generates random datasets with the same dimensions as yours and compares eigenvalues against those random benchmarks. Variables that do not explain more variance than random noise are discarded. In one engagement involving employee performance metrics, I started with forty-two variables and thirty-two observations across six departments. After parallel analysis, I retained eight components. Running discriminant analysis on those eight components produced a stable classification model with about seventy-eight percent accuracy on a holdout set. Running it on the original forty-two variables failed entirely due to the singular matrix problem.
Handling Missing Data Without Lying to Yourself
Listwise deletion, which removes any row with a single missing value, is the default in many statistical packages and it is usually the wrong choice unless your missingness is completely random. If you have ten variables and five percent missingness per variable, listwise deletion can easily discard forty percent or more of your data. That is a substantial loss of statistical power and potentially introduces bias if the missingness is related to the outcome. Multivariate imputation by chained equations, or MICE, is the standard approach for this. It iteratively models each incomplete variable as a function of all the others and fills in plausible values. I use the mice package in R for this. It handles different variable types within the same dataset, which matters when you have a mix of continuous, binary, and ordinal variables. The process takes longer than simple mean imputation, but mean imputation underestimates variance and attenuates correlations, which biases subsequent multivariate results in predictable but often unnoticed ways. I worked on a project involving health survey data where approximately thirty percent of responses had at least one missing value. Mean imputation produced a factor structure that looked clean but had artificially inflated loadings on the imputed variables. MICE with twenty imputed datasets, run with the predictive mean matching method for continuous variables and logistic regression for binary ones, produced a much more realistic covariance structure. The difference in the factor solutions was subtle but important. It took about forty minutes to run the full MICE procedure on that dataset compared to nearly instantaneous mean imputation, but the downstream analysis was not worth trusting if the input data was biased.

Choosing the Right Method for Your Actual Goal
People often pick a multivariate technique because it is the first one they learned, not because it matches their research question. This is a significant source of incorrect conclusions. Factor analysis and PCA are frequently confused. They serve different purposes. PCA is a data reduction technique that creates linear combinations of your observed variables to capture maximum variance. The components are mathematical constructs that may not correspond to anything meaningful in the real world. Factor analysis assumes that your observed variables are influenced by underlying latent constructs, and it tries to recover those constructs. If you care about interpretation and theory, factor analysis is the better choice. If you just want fewer variables for a downstream model, PCA is simpler and often sufficient. Cluster analysis is another area where people jump in without thinking about what kind of clusters they actually need. K-means clustering partitions observations into a fixed number of groups by minimizing within-cluster variance. It is fast and works well when clusters are roughly spherical and similarly sized. Hierarchical clustering builds a dendrogram that lets you see relationships at multiple resolution levels, but it does not scale well past ten thousand observations and the results can change dramatically depending on the linkage method you choose. Ward's method generally produces compact, balanced clusters, while single linkage tends to produce long chaining artifacts that are rarely useful in practice. When I was analyzing market segmentation data for a retail client, I initially ran k-means with three clusters because the business question was straightforward. The clusters looked reasonable visually, but the silhouette scores averaged only 0.28, which indicates weak cluster structure. I switched to model-based clustering using the mclust package, which fits Gaussian mixture models and selects the optimal number of clusters and covariance structures using BIC. The best model suggested six clusters with a silhouette score of 0.51. The business team initially pushed back because three was easier to act on, but the six-cluster solution revealed two distinct subsegments within what looked like a single group, and those subsegments had meaningfully different purchasing patterns. The model-based approach took about eight minutes compared to under a minute for k-means, and the additional insight justified the extra computation time.
Structural Equation Modeling When You Need Causal Structure
Structural equation modeling combines factor analysis with path analysis to test hypothesized relationships between latent and observed variables. It is the most demanding technique in the multivariate toolkit and the one most commonly misapplied. You need a theoretically grounded model before you run SEM. Fitting a model with no theoretical basis and then interpreting the path coefficients as meaningful relationships is just data mining with extra steps. Identification is the key concept here. Every SEM model must be identified, which means there must be enough information in the data to estimate every parameter uniquely. A general rule of thumb is that you need at least as many unique variances and covariances in your data as you have parameters to estimate. With five observed variables, you have fifteen unique elements in the variance-covariance matrix. If your model has more than fifteen free parameters, it is underidentified and will not converge. Model modification indices can suggest where to free or constrain parameters, but you should only follow those suggestions when they make theoretical sense. I have seen analysts add covariance paths between error terms based solely on modification indices, which inflates model fit artificially and produces results that cannot be replicated. The lavaan package in R is the standard tool for SEM work. Model specification is done through a text-based syntax that is fairly intuitive once you get past the initial learning curve. Model fit is assessed through multiple indices because no single index is sufficient. The chi-square test is sensitive to sample size and will reject well-specified models in large samples. The RMSEA below 0.08 and the CFI above 0.90 are widely accepted thresholds, but they are guidelines, not rules. I once reviewed a model with a CFI of 0.89 and an RMSEA of 0.082 that was substantively correct and practically useful. Declaring it a failure based on arbitrary cutoffs would have been worse than accepting a marginally inferior model that happened to fit the cutoffs.
Validation and Reproducibility in Applied Settings
Running a multivariate analysis on your full dataset and reporting those results as fact is a common mistake. The results are conditional on your specific sample. Cross-validation or holdout validation tells you whether those results generalize. For classification techniques like discriminant analysis, I typically split the data into a training set containing seventy percent of observations and a holdout set containing the remaining thirty percent. The model is built on the training set and then applied to the holdout set. Classification accuracy on the holdout set is usually five to fifteen percentage points lower than on the training set, and that gap is informative about overfitting. For techniques like cluster analysis where there is no explicit dependent variable, stability analysis is more appropriate. You run the clustering procedure multiple times on bootstrap samples and examine how consistently observations end up in the same clusters. If cluster membership changes substantially across bootstrap samples, your clusters are not stable and should not be used for decision-making. This took me about twelve minutes per bootstrap iteration on a typical dataset of five hundred observations with fifteen variables, and I usually run fifty bootstrap samples, so the total additional time is manageable but not negligible. Reproducibility is another practical concern that gets ignored until someone asks you to redo the analysis six months later. Document every step: the original data source, the cleaning procedures, the imputation method, the standardization approach, the parameter choices for each algorithm, and the random seed used for any resampling. I keep a single R Markdown document that reproduces the entire analysis from raw data to final output. This takes additional time upfront, maybe an extra hour for a typical project, but it saves days of reconstruction work later and makes peer review or handoff to another analyst straightforward.

The biggest limitation of multivariate analysis in practice is that it requires assumptions that real data rarely satisfies cleanly. No amount of technical sophistication will fix fundamentally poor data quality or a research question that is too vague to map onto any statistical method. When the assumptions cannot be met through standard transformations or robust methods, the honest answer is often to simplify the analysis or collect better data rather than to push forward with a technique that will produce elegant-looking but misleading results.