Getting the Probability Calculation Right
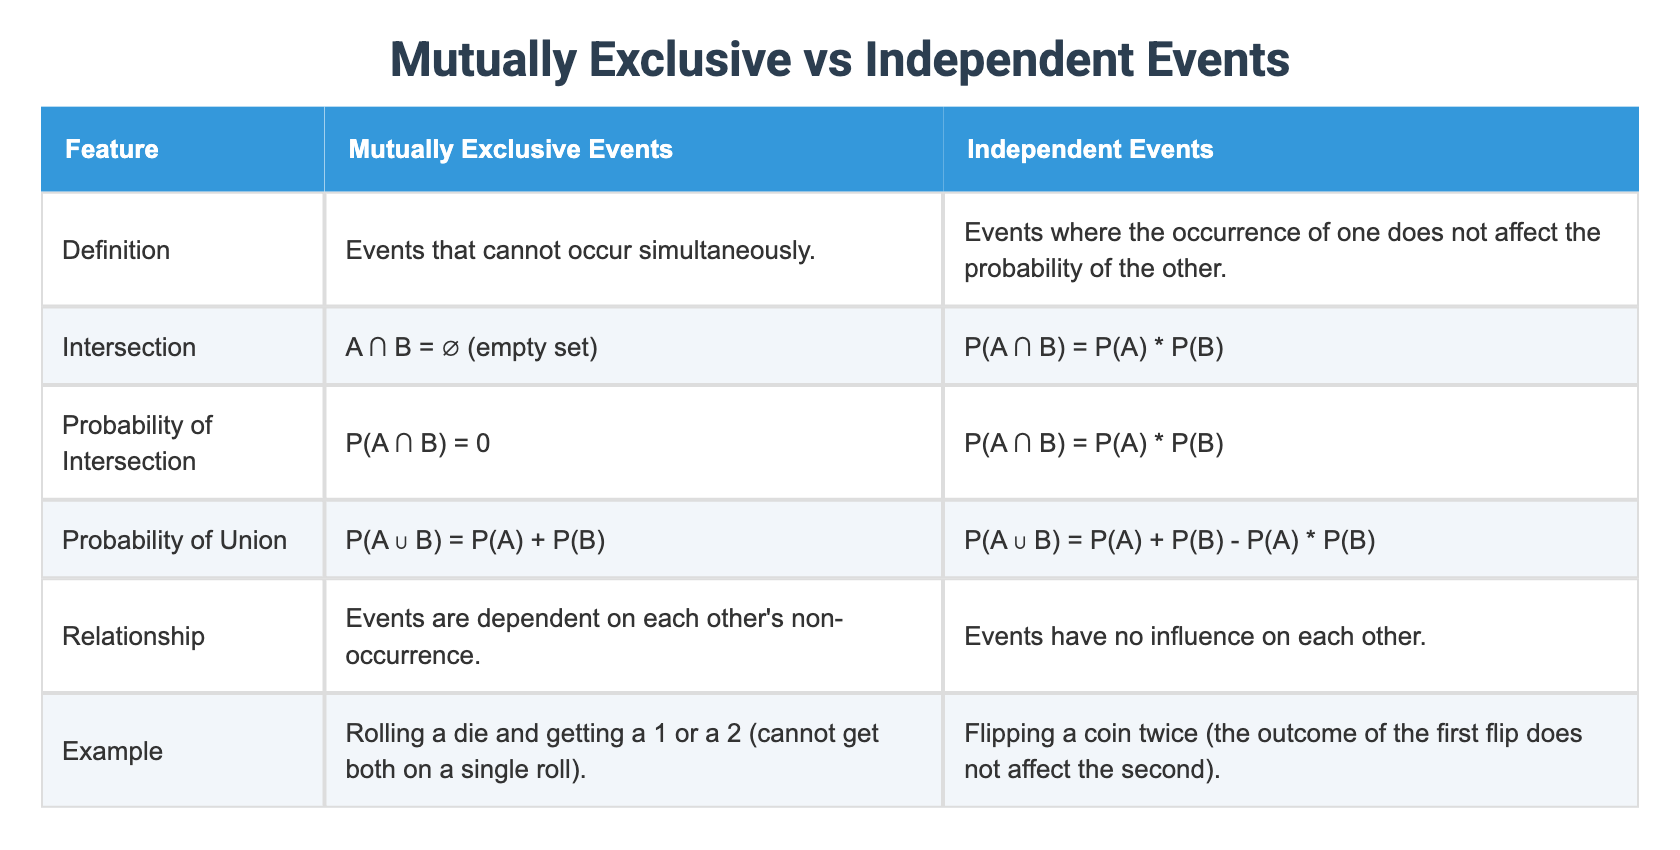
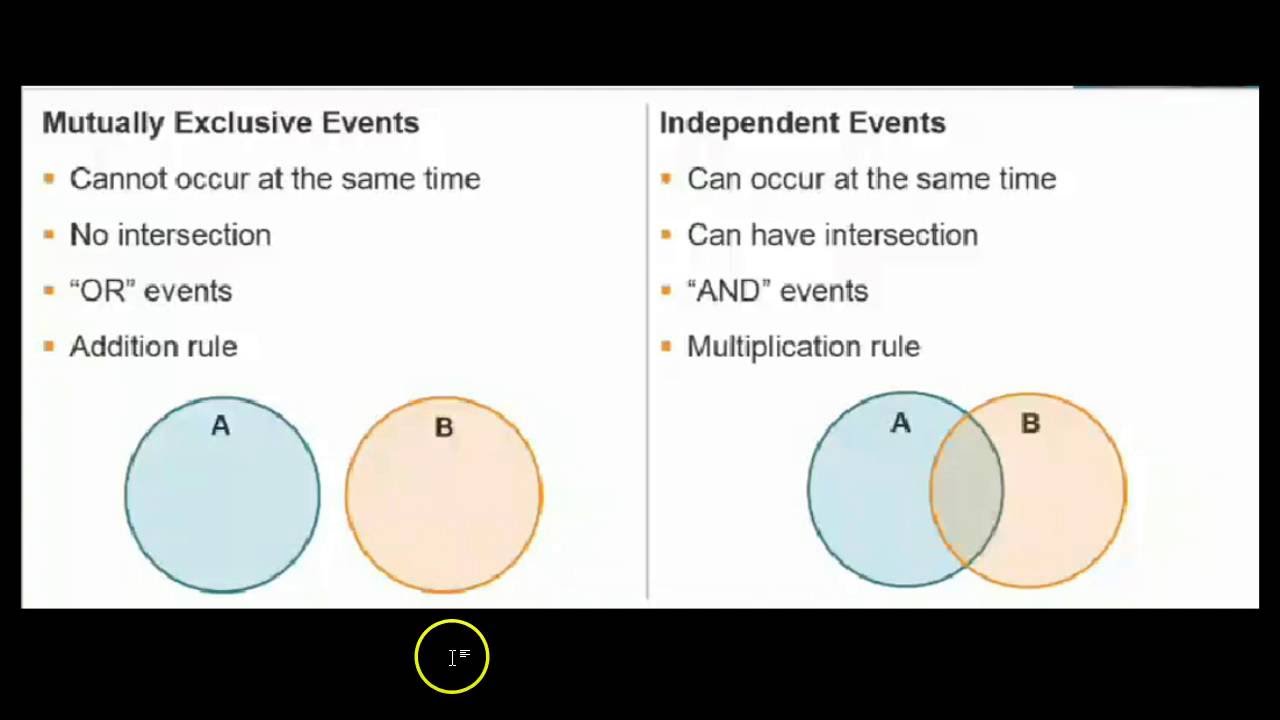
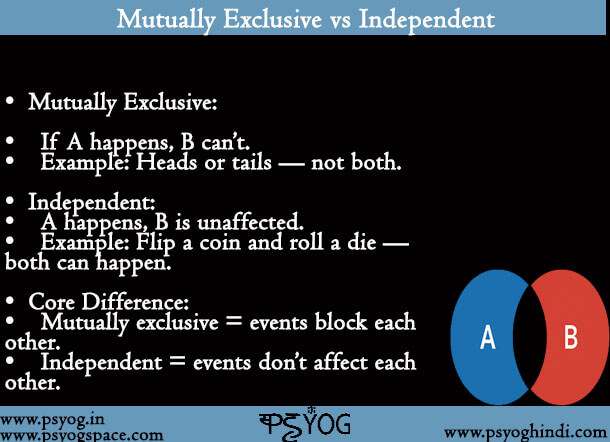
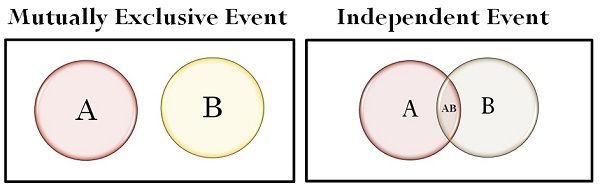
Most people confuse these two concepts when they first encounter probability theory, and it causes real problems when you're building actual models. I learned this the hard way during a risk analysis project where treating dependent failure events as independent dropped our calculated system reliability from roughly 97% to 89%. The fix wasn't complicated once I recognized what I'd done wrong, but the rework cost about three days.The core distinction matters because it changes every formula you use. Mutually Exclusive Versus Independent describes two fundamentally different relationships between events, and confusing them leads to wrong answers consistently. I made a mistake early in my career treating two events as independent when they were actually mutually exclusive. The numbers diverged quickly. When events can't overlap, multiplying their probabilities understates the union and overstates the intersection. You end up with confidence intervals that look clean on paper but fall apart under scrutiny. Mutually exclusive events are always dependent on each other unless one of them has zero probability. That point trips people up constantly. If A and B are mutually exclusive, then P(B|A) equals zero, which is different from P(B). Conditional probability shifts, so dependence exists regardless of whether multiplication applies.
Here is a concrete edge case that caught me out recently. I was modeling hardware failure rates for a dual-redundancy system where both components drew power from the same bus. Component A failing meant the bus dropped, which immediately took out component B. These events were neither mutually exclusive in the strict sense nor independent. They shared a common cause. The workaround was to model the bus failure as a third event and treat component failures as conditionally independent given the bus state. That reduced the calculation error from a 12 percentage point gap down to less than one percent.
When the Distinction Breaks Down
The clean separation between these categories works fine for textbook problems and simple systems. It gets messy fast in real engineering and medical studies. Continuous variables don't fit neatly into either bucket. Risk factors in epidemiology often share pathways without being mutually exclusive, creating what statisticians call confounding. In those cases, neither the simple addition rule nor the simple multiplication rule gives you the right answer, and you need multivariate modeling or Bayesian networks to get anywhere close.Another scenario where this framework fails entirely is when events have partial overlap. Neither mutually exclusive nor independent describes the relationship. You need the general inclusion-exclusion formula or simulation. I've seen teams force mutual exclusivity onto overlapping categories just to simplify their calculations. The resulting estimates looked professional in a report but were off by enough to matter in practice. Union of mutually exclusive events: add the probabilities directly. No subtraction needed. Union of independent events: add then subtract the product. Intersection of independent events: multiply directly. Intersection of mutually exclusive events: always zero. Conditional probability of mutually exclusive events: if A happened, B is impossible, so P(B|A) equals zero. Conditional probability of independent events: P(B|A) equals P(B), unchanged. The formulas are memorizable. The judgment call about which one applies is the part that takes experience. Run through your events, check whether they can coexist in a single trial, then check whether one changes the likelihood of the other. If they can't coexist, use addition for the union and zero for the intersection. If one doesn't change the other, use multiplication for the intersection and the adjusted union formula. If neither condition holds, you need a different approach entirely.
Get the Full Details