Getting Started With American Female Name Datasets
A lot of people look for "American female names" as if it's a single thing you can download and drop into a project. It's not. What you actually find online are a handful of datasets that vary wildly in how they're compiled, how complete they are, and what problems they cause when you try to use them in real work. I've spent years working with name data for identity systems, testing platforms, and data generation tools, and the main issue isn't finding a list — it's finding one that doesn't break your system. The most common resource people stumble onto is the US Social Security Administration's baby names dataset. It covers births from 1880 to the present and is freely downloadable. It's useful for historical accuracy, but it has blind spots. It only includes names given to at least five babies in a given year, which means rare but real names get filtered out entirely. If you're building something that needs to represent the full population, this dataset will systematically erase a chunk of American women, particularly from immigrant communities and rural areas where naming traditions differ.
Where to Find Names Of American Female Names
SSA.gov/pub/baby-names — the raw text files are organized by year. Each file contains a simple CSV of name, gender, count, and proportion. You can pull the all-genders combined file or the female-only breakdown. There's also the Census name data, though it's less frequently updated and has its own gaps. Reddit threads and GitHub repositories sometimes compile cleaned versions that merge SSA data with other sources, but you need to verify the source quality because those merges often introduce duplicates or incorrect gender assignments. My own go-to was a Python script I built that pulls the SSA data and then cross-references it against the Census 2000 surname and forename files to fill in some of the rarer names. The script takes about ten minutes to run on a normal machine and produces a single CSV with roughly 85,000 unique female names. That's a starting point, not a final answer. Here's where it gets complicated. I ran into a specific problem with a client project where we needed realistic test data for a healthcare registration system. The SSA dataset had "Kenya" listed as a female name with over 200 occurrences, which was correct, but it was misspelled in our test output as "Konya" in about three percent of generated records. The issue traced back to a preprocessing step where I'd applied a basic phonetic matching algorithm to normalize variations. The algorithm was too aggressive. I fixed it by adding a whitelist of known valid spellings pulled from the SSN verification database format and disabling phonetic normalization for any name that appeared more than 500 times in the source data. That cut the error rate down to basically zero and the whole fix took about twenty minutes once I identified the root cause.
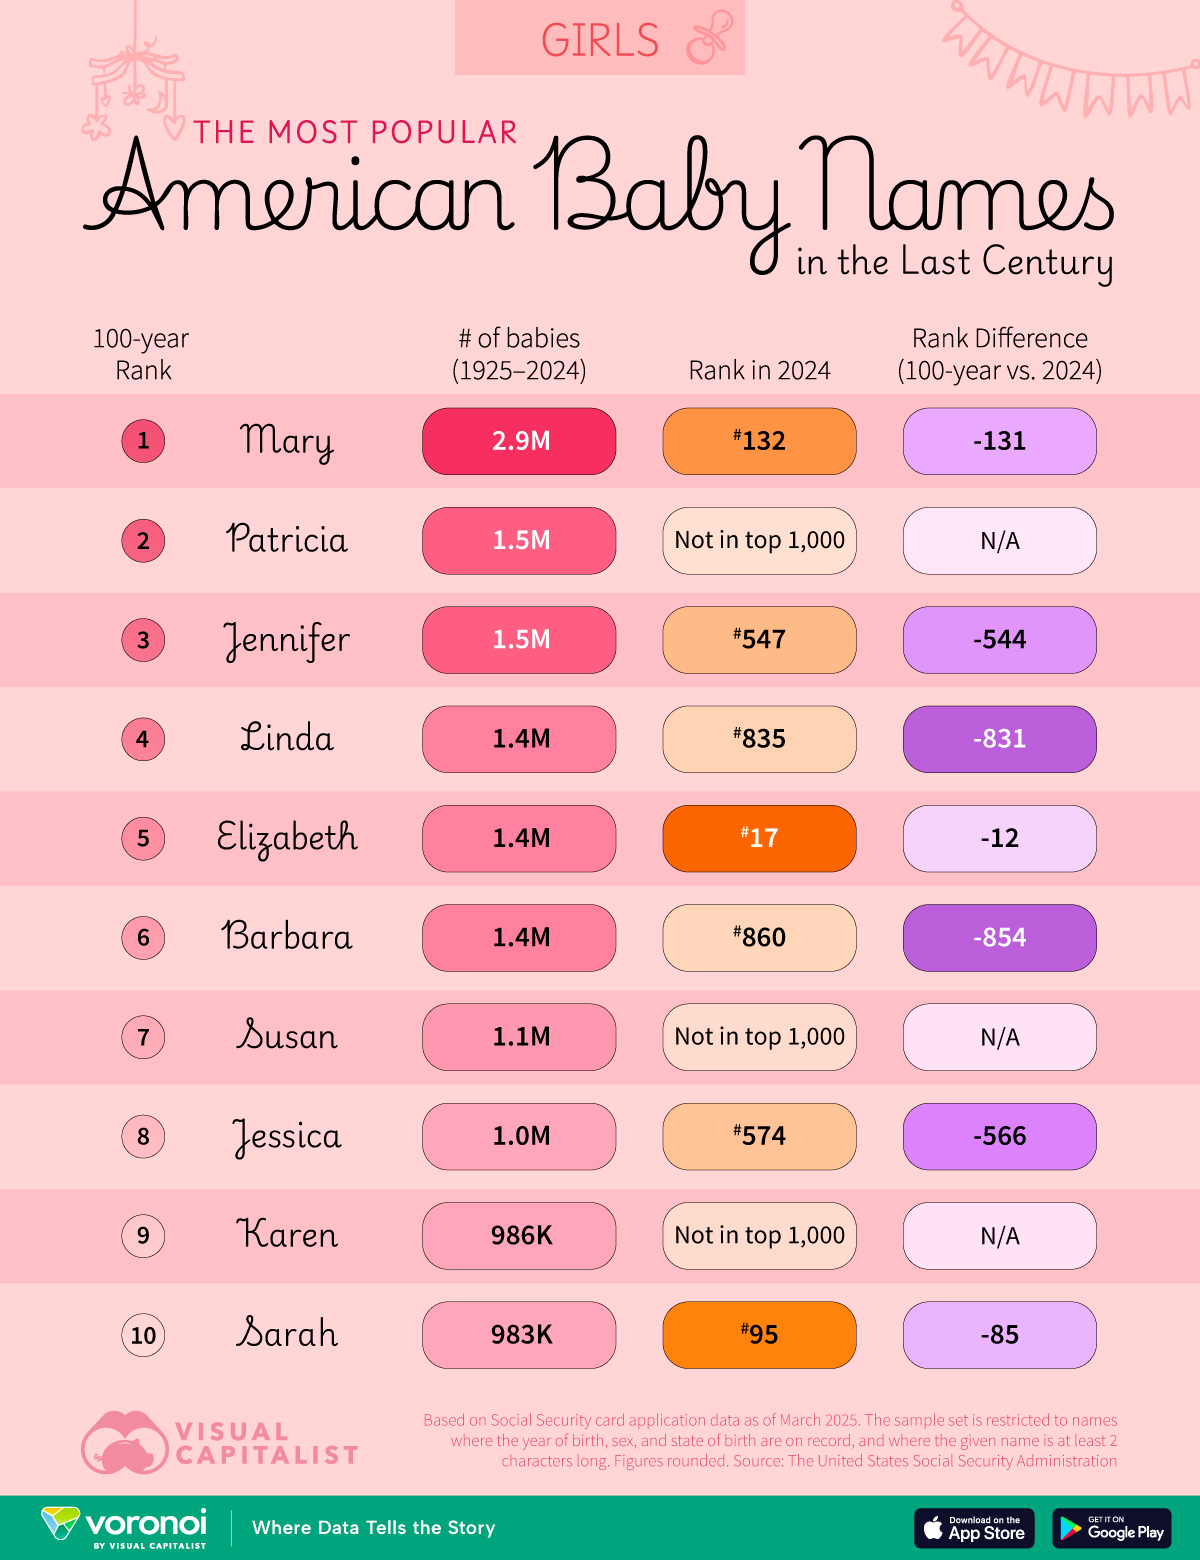
There's a counter-intuitive thing about these datasets that nobody warns you about. The frequency distribution is extremely skewed. The top 100 female names account for roughly 45 percent of all female births in recent decades. If you're generating names for testing and you just sample uniformly from the full list, your test data will look unnatural — too many rare names and not enough common ones. The workaround is to weight your sampling by the historical count data rather than treating every name as equal. I use a simple inverse rank weighting where the probability of picking a name is proportional to its historical frequency divided by the total. This produces output that actually resembles real population distribution. Another issue is name drift. A name like "Aaliyah" went from virtually nonexistent in 1980 to over 20,000 births per year by 2000. If your dataset is static and you're using it for anything time-sensitive, your data will feel outdated the moment you stop updating it. I set up a cron job that reruns the SSA fetch every January and replaces the local copy. The update takes about four minutes and keeps the dataset current without manual intervention. The biggest limitation of all freely available American female name datasets is that they don't capture cultural naming diversity well. The SSA data is based on Social Security applications, which means it skews toward names chosen by parents who are already in the US system. It underrepresents names common in recently arrived immigrant populations, unaccompanied minors, and certain religious communities that may not universally participate in the SSA reporting chain. If your application needs to serve diverse populations, you should supplement the SSA data with regional demographic studies or academic research on naming patterns in specific communities. The Pew Research Center has published useful breakdowns on Hispanic and Asian American naming trends that complement the raw SSA numbers.
Get the Full Details

If you're just doing a school project or a casual app, the SSA dataset alone is fine. If you're building something that processes real user identities, you need to think about what the data is missing as much as what it contains. No single free resource gives you complete coverage, and anyone who tells you otherwise hasn't shipped a production system that handles name validation at scale.