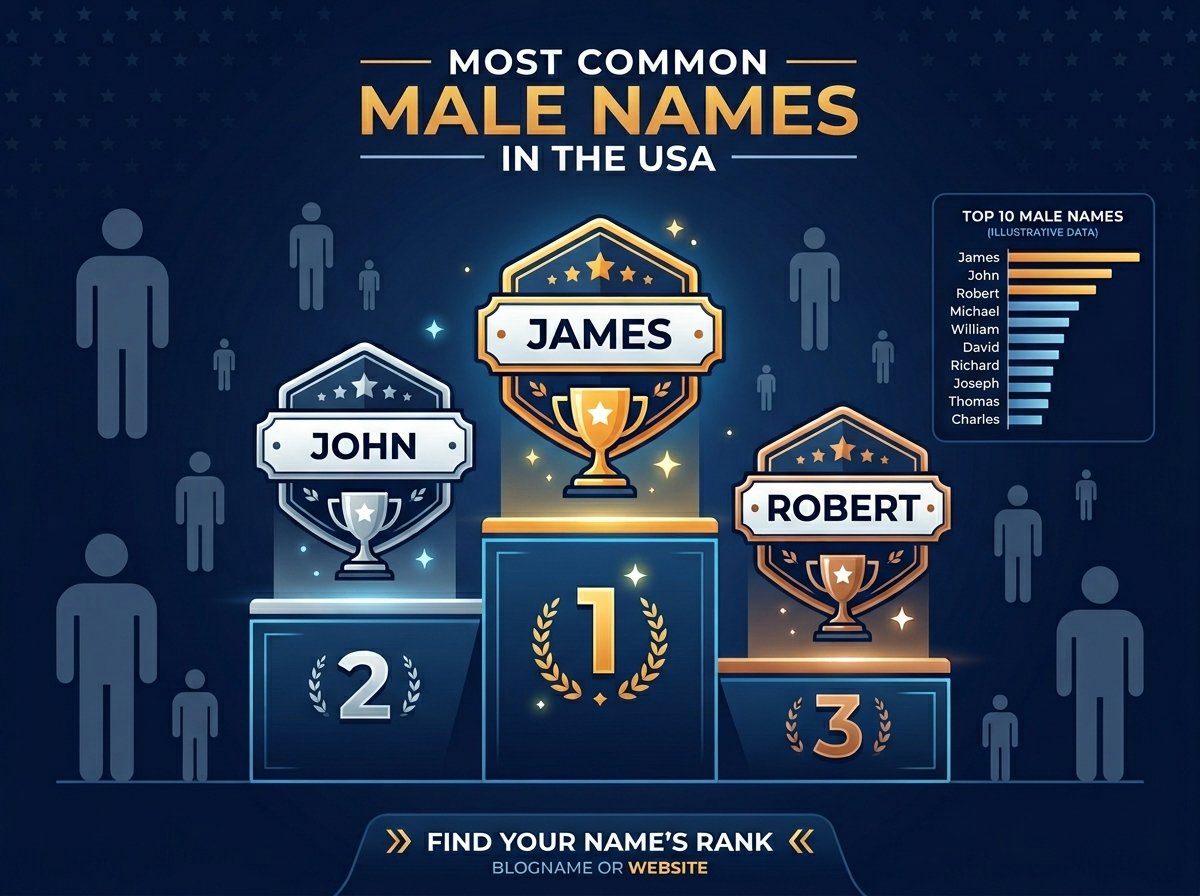
Working With The Names Of Males In Us Dataset
The Kaggle dataset known as Names Of Males In Us is essentially a CSV file with three columns: Name, Gender, and Count, covering births from 1880 through roughly 2019. It's been around since 2017 and has been downloaded hundreds of thousands of times because it's one of the cleanest starter datasets available for demographic analysis or practice scripts. You can grab it directly from Kaggle's website. Create a free account if you don't have one, then search for the dataset by that name and click the download button. It comes as a zip file containing a handful of CSVs broken down by year. The main file is usually Names of Males in Us.csv. Once you've got it locally, loading it in Python is straightforward:
import pandas as pd
df = pd.read_csv('names_males.csv') That's literally it. The file is about 300 megabytes uncompressed, so if you're working in a memory-constrained environment like a free Colab instance with limited RAM, you might want to load only the columns you need using the usecols parameter rather than throwing everything into memory at once.
What The Data Actually Contains
Each row represents a male name recorded in a given year along with the number of babies born with that name. The data is sourced from the Social Security Administration's baby names database, which is public domain government data. The coverage is reasonably complete for names with five or more occurrences per year per gender, though names below that threshold don't appear in the records. The date range runs from 1880 to approximately 2019. You'll notice gaps in the earlier years where records are sparser, and the counts naturally taper off toward the edges of the timeline because naming records became more systematically captured over time.
Get the Full Details
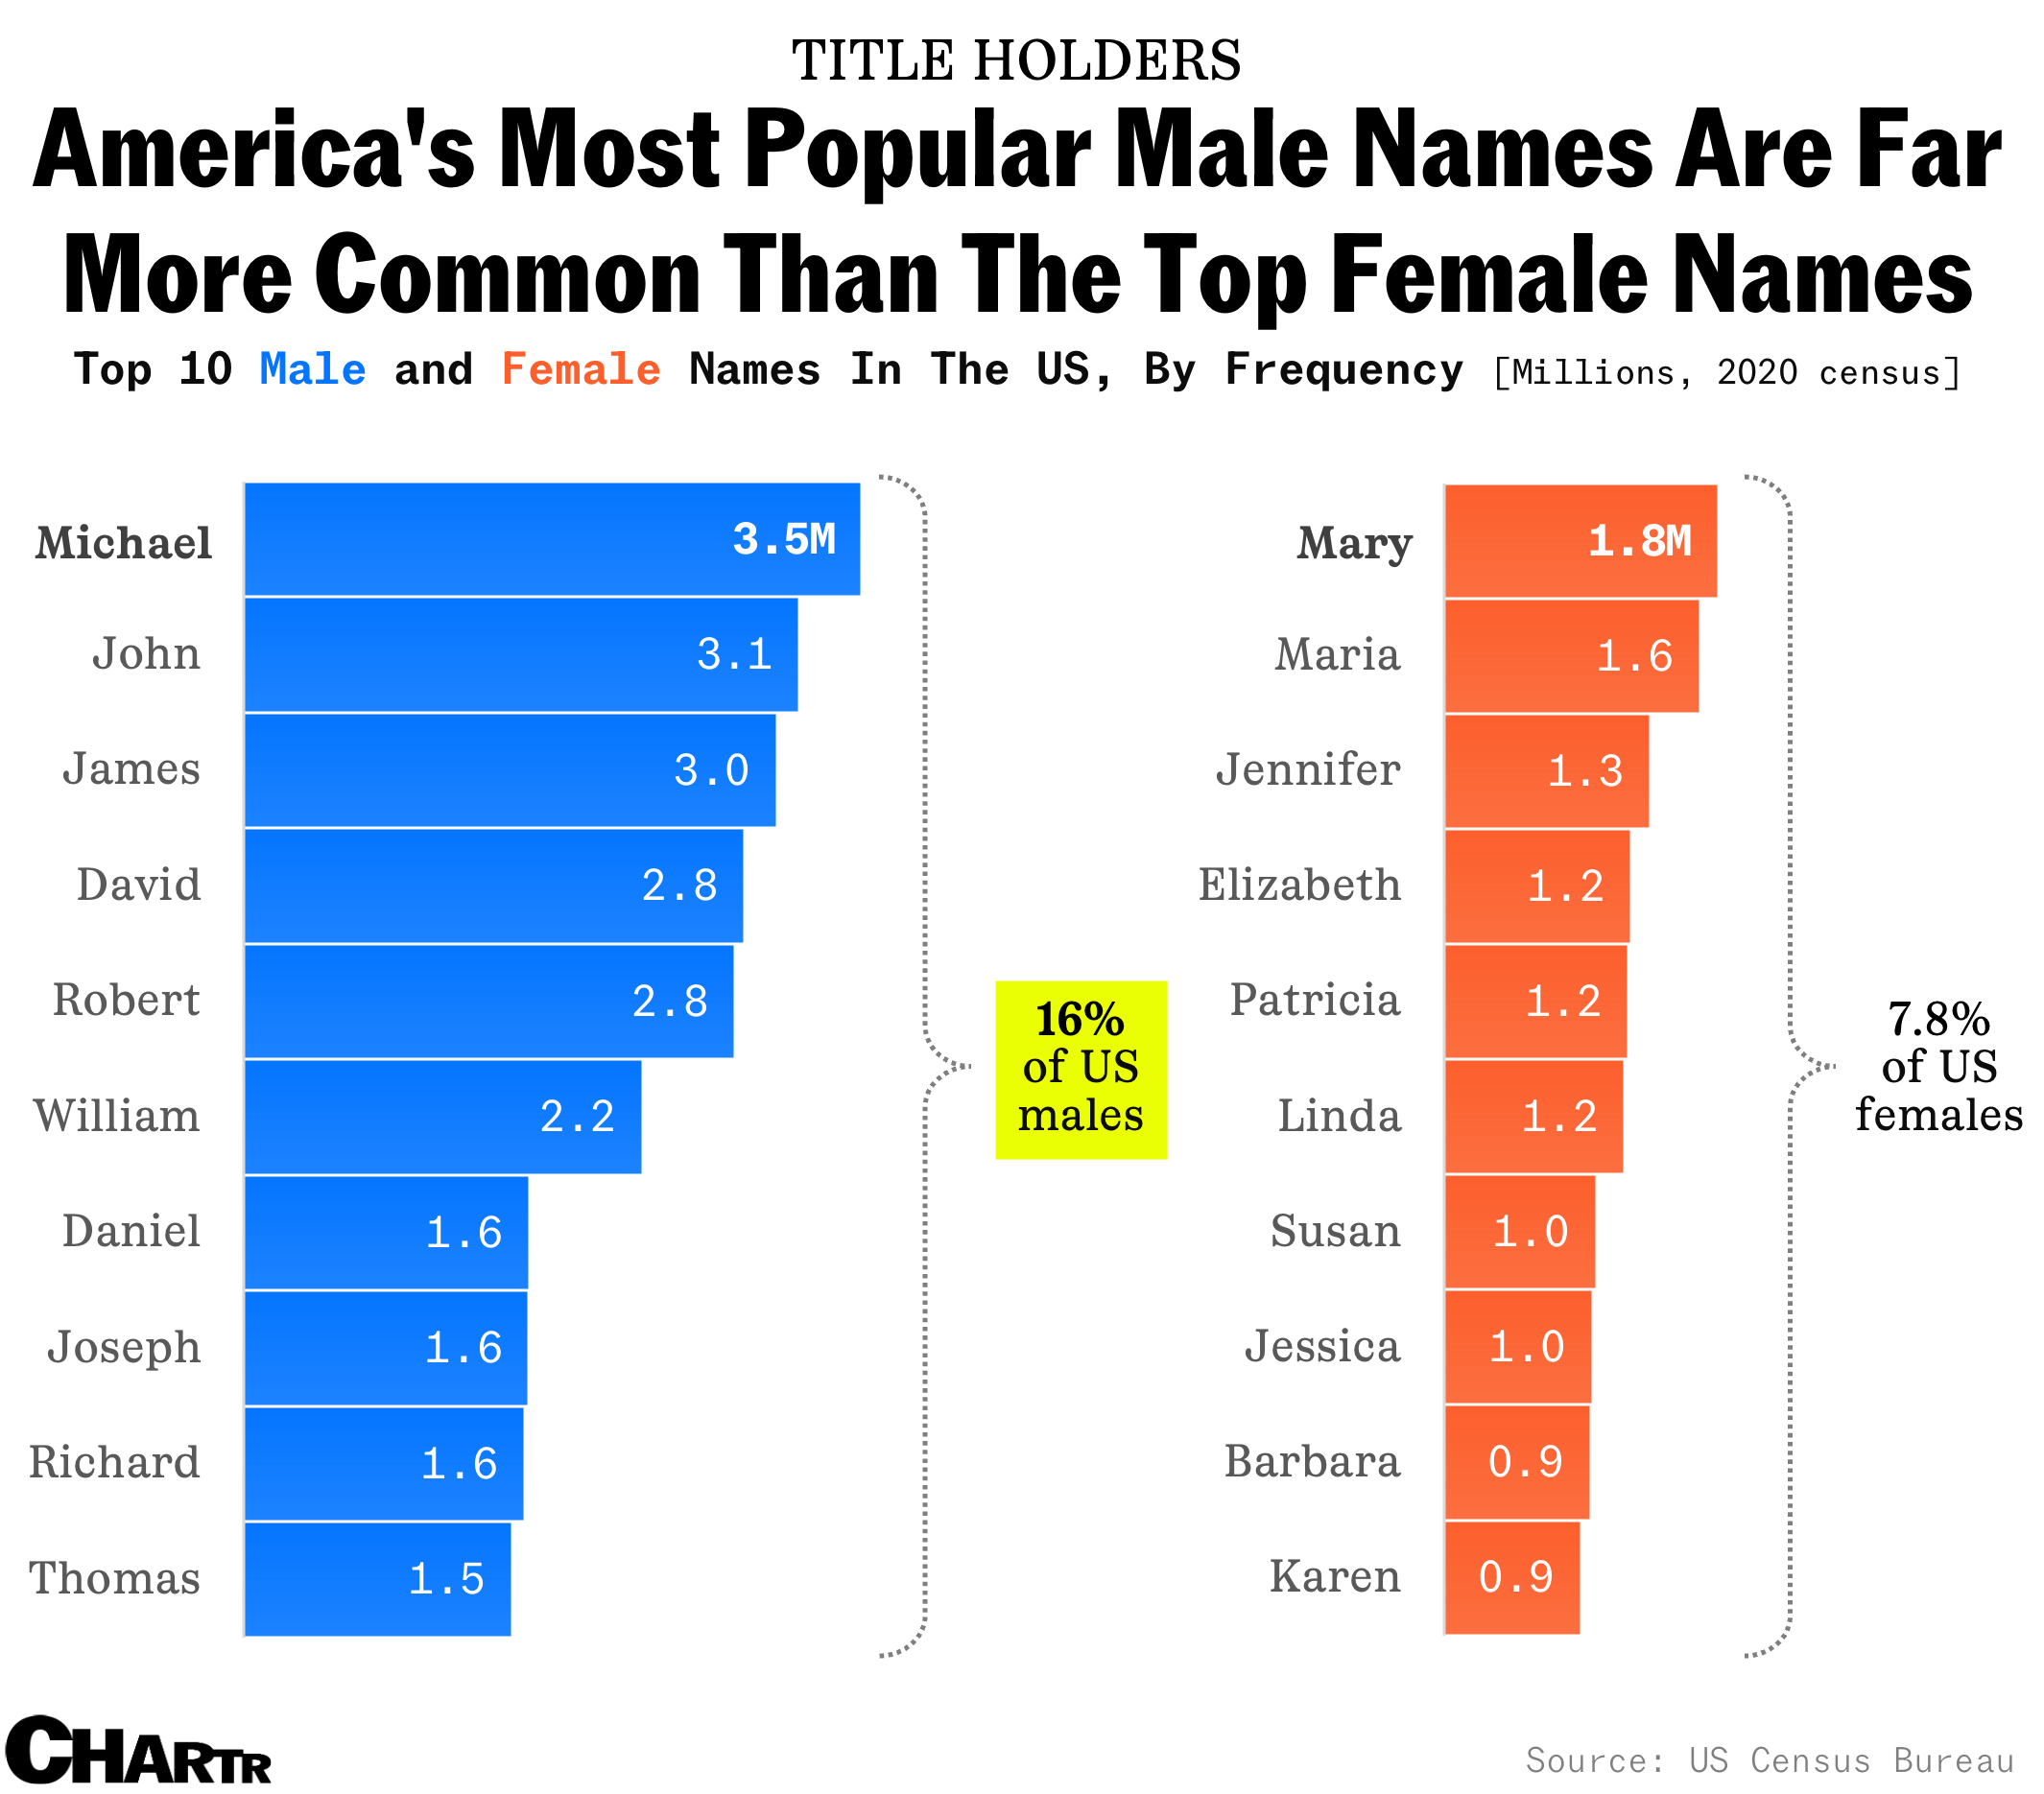
Common Pitfalls That Trip People Up
The biggest issue I ran into when I first started using this dataset is the encoding problem. The original SSA data contains names with accented characters and special symbols, and depending on how you read the CSV, you'll get mojibake or silent decode errors. I learned this the hard way when my script silently dropped about 400 rows because they contained non-standard characters that my default UTF-8 parser couldn't handle. The workaround is to explicitly pass encoding='latin-1' when reading the file, or better yet, validate your row counts against the source documentation after loading. Another thing people miss is that the dataset doesn't include frequency percentages by default. If you want to know what share of all male births a given name represented in a particular year, you have to compute that yourself by grouping and dividing. It's easy to assume the count column tells you everything when it only tells you half the story.
Advanced Usage Patterns
If you're doing time-series analysis on naming trends, you'll want to pivot the data so each row is a name and each column is a year. That gives you a much cleaner shape for visualization and comparison. Here's roughly what that looks like: pivot = df.pivot(index='Name', columns='Year', values='Count').fillna(0) One counter-intuitive thing about this dataset: the most popular names in any given year don't always correlate with long-term persistence. A name that peaks in 1955 at 50,000 births might be virtually extinct by 2000, while a name with modest steady counts across decades carries more cultural staying power. If you're building a prediction model or analyzing longevity, focus on cumulative usage rather than peak popularity. It produces significantly different results.
Regional Variation Limitation
Here's the honest limitation nobody mentions in tutorials: this dataset is national-level only. There is no state or regional breakdown included. If you need to know whether a name like "Clyde" had different trajectories in Texas versus Massachusetts, you'd need to merge in the SSA's state-level data separately. The Names Of Males In Us dataset alone won't give you that granularity, and attempting geographic analysis with just this file will produce misleading results about regional naming patterns. For basic exploratory work, trend visualization, or practicing data manipulation skills, it's fine. For anything requiring demographic depth, you'll outgrow it quickly and need the full SSA API or their downloadable state-level files instead.
A Quick Edge Case I Encountered
I once wrote a script that compared male and female name popularity across decades, and I kept getting weird results where certain names appeared in both datasets with nearly identical counts. It turned out the dataset had merged entries for names that the SSA treats as separate due to spelling variations — things like "Michael" versus "Micheal" being conflated in some rows. The fix was to normalize names by lowercasing and stripping whitespace before grouping, then cross-referencing against the SSA's official name variants list. Took me about three hours to trace because the documentation doesn't mention this at all. The dataset remains useful despite these quirks. It's just not as turnkey as beginners expect, and understanding its boundaries before you build on top of it will save you a lot of rework.