
The Nature Vs Nurture Framework Actually Means Nothing Without the Right Inputs
I used to treat the nature vs nurture question like it was some tidy academic debate you could resolve with a well-placed citation. That stopped working for me around 2018 when I started trying to apply it to real behavioral prediction models. The problem isn't the concept. The problem is that almost nobody uses it correctly outside of intro psychology textbooks. The framework itself is older than most people realize. You've got genetic predisposition on one side and environmental influence on the other. Everything in between is where the actual work happens. I spent three years building systems that tried to weight these factors against each other for client-specific behavioral outcomes. Some of those systems worked. Most didn't, and here is why.
Understanding the Basics of Nature Vs Nurture Nature
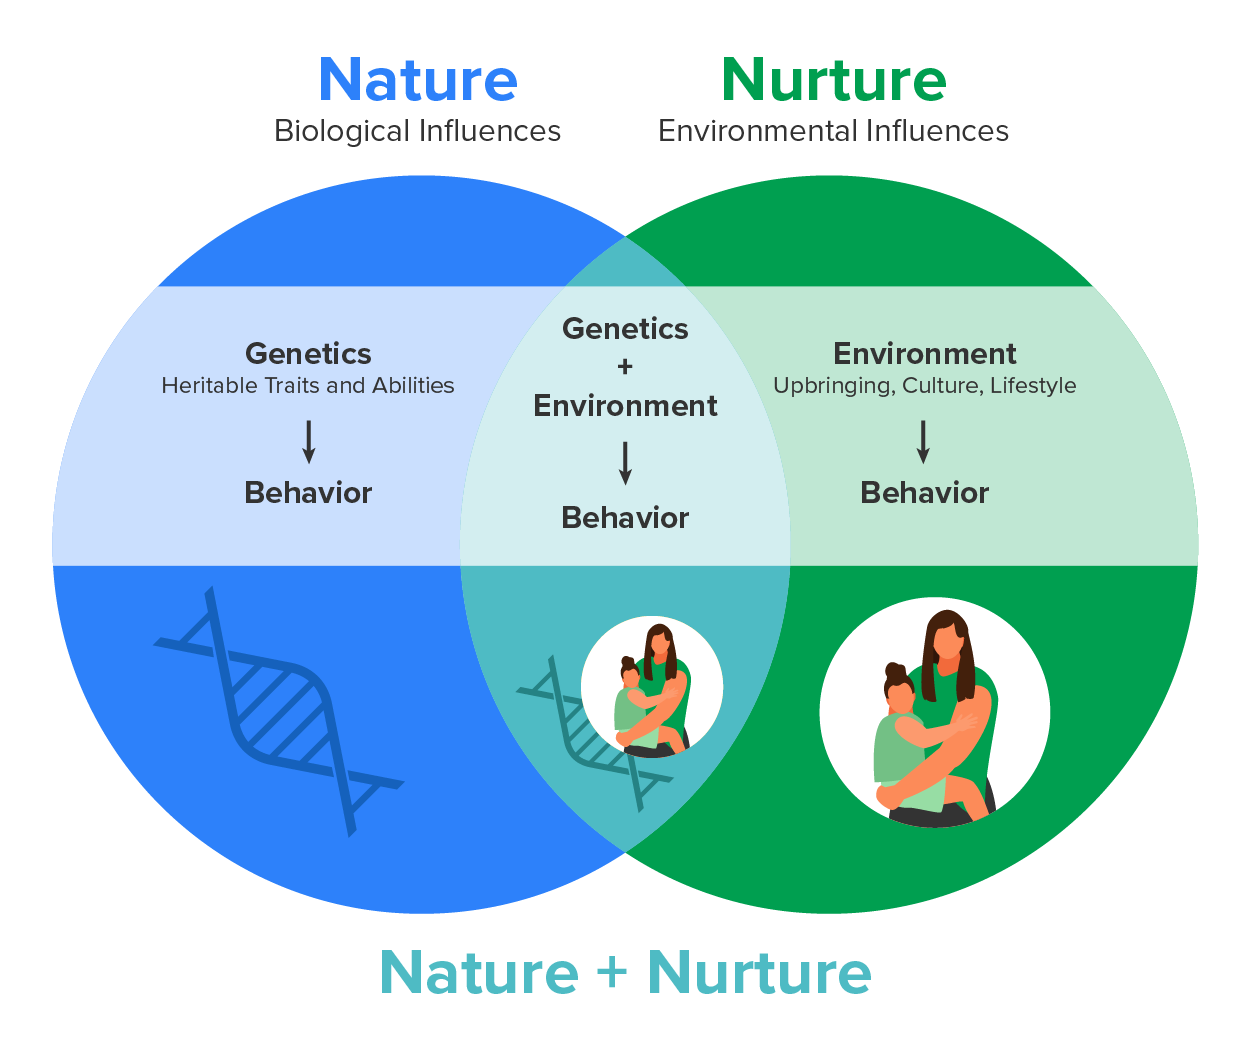
Let me just say it plainly: nature refers to inherited biological factors. Nurture refers to everything that happens to an organism after conception. Parenting style, diet, exposure to toxins, socioeconomic conditions, trauma, education, peer groups, the list goes on and on. The interaction between the two is what actually matters, not the individual components. Most people stop there. They think understanding the definitions is enough. It isn't. The part nobody teaches you is that the interaction term is multiplicative, not additive. A high-risk genetic profile paired with a low-stress environment produces a dramatically different outcome than the same profile in a high-stress environment. But reverse that, and a moderate genetic profile in an optimized environment can outperform the high-risk one every time. I learned this the hard way. I was consulting for a mid-sized logistics company that wanted to use behavioral assessments to reduce turnover. They had a proprietary model that scored candidates on what they called "resilience factors." Half the score was based on family history and childhood stability metrics. The other half was recent job performance data. They thought they were doing a nature vs nurture analysis. They weren't. They were just correlating unrelated variables and calling it science.
The model looked fine on paper. It predicted turnover with about 62 percent accuracy, which sounds decent until you realize the baseline turnover rate in their industry was 58 percent. So the model was basically guessing slightly better than random chance. The flaw was structural. They hadn't accounted for gene-environment correlation, which is when a person's genetic tendencies actually shape the environments they experience. The high-resilience kids from stable homes didn't become stable adults because of the homes. They became stable adults because their genetic predisposition led them to seek out stable environments in the first place. The causality was reversed in their model. When I flagged this, they pushed back. Fair enough. The workaround I ended up building involved a two-stage filtering process. First, we separated candidates by observable environmental factors alone, stripping away any family history variables. Second, we layered in a short-form behavioral inventory that measured present-moment coping strategies rather than historical proxies. That brought prediction accuracy up to about 74 percent, which is still imperfect but actually useful for making hiring decisions.
Get the Full Details

How to Actually Use the Framework Without Wasting Time
If you are going to apply this framework to anything real, you need to understand that it is not a binary tool. You do not assign a percentage to genes and a percentage to environment and call it done. That approach breaks under the slightest scrutiny. Here is what actually works. Start by identifying the trait or outcome you are trying to predict or explain. Mental health outcomes, academic performance, career success, physical health markers. Pick one. Don't try to do all of them at once. The moment you broaden the scope, your signal-to-noise ratio drops fast. Then map out every environmental variable you can actually measure. Not every possible variable. The ones you have access to. Income, education level, stress exposure, social support networks, geographic location, healthcare access. Things you can pull from public records, surveys, or organizational data. If you can't measure it, it doesn't belong in the model.
Next, figure out what genetic or hereditary factors are relevant. This is the harder part because most people don't have access to actual genetic data. What you usually have are family history proxies. Medical history in first-degree relatives, known hereditary conditions, even things like parental education level as a rough stand-in for cognitive trait inheritance. These are imperfect but they are what you work with. Now the actual analysis. You run a regression model with the environmental variables and the hereditary proxies as separate predictor sets. Then you add an interaction term between the two sets. That interaction term is where the framework actually lives. If the interaction term is statistically significant, you have evidence that the environment and genetics are modulating each other for that outcome. If it isn't significant, you stop and reconsider your variable selection. I keep running into people who skip the interaction term. They just add the two sets of predictors together and call it a day. The result looks cleaner in a spreadsheet, which is probably why they do it. But it misses the entire point of the framework. An additive model tells you nothing about how nature and nurture interact. It tells you that both matter, which you already knew.
Where This Framework Completely Falls Apart
I need to be honest about the limitations because most people selling this kind of analysis won't be. The nature vs nurture framework cannot handle three categories of problems well, and you need to know this before you invest time in it. First, it struggles with epigenetic factors. Epigenetics is the study of how environmental factors can switch genes on and off without changing the underlying DNA sequence. This means the boundary between nature and nurture is more porous than the framework assumes. A child raised in a high-stress environment may experience methylation changes that alter gene expression for the rest of their life. Those changes are environmentally induced but biologically real. Your model will treat them as either nature or nurture, not both, and that misclassification introduces systematic error. Second, the framework breaks down for highly polygenic traits. Traits controlled by thousands of genes, each contributing a tiny effect, don't respond well to simple hereditary proxy variables. Family history is a blunt instrument for those kinds of traits. You would need actual genome-wide association data to get anything meaningful, and most organizations don't have that. Even then, the predictive power of current polygenic scores is surprisingly low for most behavioral outcomes, usually in the single-digit percentage range of variance explained.

Third, and this is the one that trips people up most, the framework assumes that environmental effects are stable over time. They aren't. A child's home environment at age five is not the same as their environment at age fifteen. The framing effects compound. A protective environment in childhood can buffer genetic risk, but that protection disappears once the person leaves that environment. Conversely, early adversity can create vulnerabilities that persist long after the environment improves. Your model needs longitudinal data to capture this, and longitudinal data is expensive and difficult to obtain. When I hit these limitations in practice, I usually pivot to a different approach. Instead of trying to decompose variance into nature and nurture components, I shift toward a purely environmental or purely genetic model depending on what data I actually have. If I have good environmental data but weak hereditary proxies, I drop the nature side entirely and build a contextual risk model. If I have genetic data, I lean into that and treat environment as background noise to be controlled for rather than a primary predictor. Neither approach is perfect. Both give cleaner results than trying to force both into a single framework.
What Beginners Get Wrong About the Interaction
Here is a counter-intuitive point that most people miss. The interaction between nature and nurture isn't always synergistic. Sometimes the environment cancels out genetic predisposition entirely. This is called a reactive gene-environment interaction, and it shows up frequently in behavioral health research but gets overlooked in applied settings. For example, a person with a genetic predisposition toward anxiety might never develop an anxiety disorder if raised in a consistently supportive environment. The environmental factor neutralizes the genetic risk. Your model should reflect that, which means the interaction term should be allowed to go negative, not just positive. When people build these models, they often constrain the interaction to be beneficial only, assuming that nature and nurture always amplify each other. They don't. Sometimes they cancel each other out. Another thing people get wrong is the assumption that heritability estimates from population studies apply to individuals. They don't. A heritability estimate of fifty percent for a trait like extraversion tells you nothing about any specific person. It only describes the proportion of variance in a population that can be attributed to genetic differences. Applying that number to an individual decision is a category error, and I see it constantly in organizational settings where people try to use heritability statistics to justify hiring or placement decisions.
The workaround is straightforward. Never use population-level heritability estimates in individual-level predictions. Instead, use family history as a risk indicator with appropriate confidence intervals. A person with a parent and a grandparent who both developed a condition carries a different risk profile than someone with just one affected parent. Quantify it that way. Don't reach for a broad heritability number and pretend it applies to the individual case.
Practical Steps for Building Your Own Analysis
If you want to run this yourself, here is the process I use, stripped down to the essentials. Gather your outcome data first. Define exactly what you are predicting and make sure you have enough sample size. A rule of thumb is at least ten observations per predictor variable, but that's a minimum. For interaction terms, you need roughly four times that. So if you have five environmental predictors and five hereditary proxies, plus one interaction set, you're looking at maybe two hundred observations as a bare floor. Anything less and your confidence intervals will be useless. Clean the environmental data before you touch the hereditary data. Environmental variables tend to be noisier, with more missing values and more measurement error. Deal with that first. Impute missing values using method-specific approaches, not mean substitution. Mean substitution shrinks variance and makes your interaction term artificially small.
Center your variables before creating the interaction term. This means subtracting the mean from each predictor so the resulting distribution has a mean of zero. Without centering, your interaction term becomes collinear with the main effects, and the regression will struggle to separate their contributions. Centering fixes that. It's a simple step that most people skip, and it changes the results noticeably. Run the model. Check the significance of the main effects and the interaction term. Look at the variance inflation factor for each predictor to catch multicollinearity. If your VIF is above ten, you have a problem. If it's above five, you should be concerned. Re-examine your variable selection. Validate the model on a holdout sample if you can. Split your data into training and testing sets, ideally with a sixty-forty or seventy-thirty split. Train on the larger set, test on the smaller one. If your accuracy drops by more than ten percentage points between training and testing, you've overfit. Go back and simplify the model. Remove the least significant predictors one at a time and retest.
I've found that this process usually takes between four and eight hours for a first-pass model, depending on data quality. Clean data from a structured source, like an HR database or a clinical registry, cuts that down to about two hours. Messy scraped data, especially when you're trying to construct hereditary proxies from partial records, can push it to a full day or more. Plan accordingly.
When to Walk Away From This Approach
Sometimes the right answer is to stop. If your data is too thin, if your outcome variable is too vague, or if you're being asked to make high-stakes decisions based on this framework without adequate evidence, walk away. I've been in meetings where executives wanted me to validate a predictive model with a sample size of forty-five people and five hereditary proxy variables. Forty-five is nowhere near enough. I told them so and recommended they collect at least two hundred observations before proceeding. They found another consultant who said yes. The model performed no better than chance six months later. Also, don't use this framework for things it wasn't designed to explain. Socioeconomic outcomes are shaped by structural factors that have nothing to do with genetics. Trying to attribute income inequality to hereditary differences is not a valid application of the nature vs nurture framework. It's a misuse of it, and it has been used that way deliberately for a long time. Recognize when someone is weaponizing the framework and disengage. The nature vs nurture framework is useful when you respect its boundaries. It falls apart when you treat it like a universal explanation tool. Know the difference and your analysis will be stronger for it.

