Network Analysis In R: What Actually Works When You Stop Reading the Tutorial Snippets
Most people start with igraph. It is the default package, it has the most documentation, and it will get you through your first two projects before you hit something it cannot handle. I used to recommend it to everyone. I still do, with caveats. The problem is that the tutorials stop at degree centrality and basic plotting. Real network analysis in R involves edge cases that will silently break your results if you are not paying attention.
The first thing you need to understand is that R is not the fastest tool for dense graphs. If your adjacency matrix exceeds roughly 10,000 nodes with a density above 5 percent, igraph will still process it but you will be waiting. For those cases, I switch to tidygraph and ggraph because they play nicer with the tidyverse pipeline, but even then the bottleneck is usually your RAM, not the package choice. One project I worked on had a bipartite interaction network with about 45,000 nodes. igraph's fastgreedy.community function ran for six hours and then returned garbage. I rebuilt the same analysis using the leiden algorithm from the igraph C backend through the R interface, which cut runtime to under twelve minutes and actually produced coherent communities. That was my wakeup call. Switching from greedy methods to modularity optimization with the Leiden algorithm is something the basic guides never mention.
Setting Up Network Analysis In R Properly
You need igraph, qgraph, and if you are doing social network work, sna. For temporal or longitudinal networks, add statnet. Install them all at once and check your session info afterward. The versions matter more than people admit. igraph 1.3 and 1.4 had a known bug with edge list deduplication that caused duplicated edges to silently inflate betweenness centrality scores by up to forty percent on certain graph types. Make sure you are running at least 1.5.0.
Loading data is where most people make mistakes. Export your edge list from whatever platform you are pulling from, clean it in R, and then create the graph object. Never skip the cleanup step. I once analyzed a collaboration network where the same author appeared as "Smith J", "J. Smith", and "Smith, J" across different datasets. igraph treated them as three separate nodes. The resulting centrality rankings were useless until I normalized the names with string matching and merged the duplicates. That single fix changed the top ten researchers on the list entirely.
When you build the graph, specify whether it is directed or undirected at creation time. This is not optional. A directed graph and an undirected graph of the same data will produce different eigenvector centralities, and mixing them up during your analysis means your results are wrong by definition. I use the following pattern:
edges <- read.csv("my_edge_list.csv")
g <- graph_from_data_frame(edges, directed = TRUE)
If your data has weights, include them in the CSV and they will be carried over automatically. If you are working with a square adjacency matrix instead of an edge list, use graph_from_adjacency_matrix and decide explicitly whether to use "upper", "lower", or "max" for symmetric matrices. The default is "upper", which is fine for most cases but can double your edge count if you feed it a non-symmetric matrix by mistake.
Measuring What Actually Matters
Degree centrality is trivial. In and out degree for directed graphs. Everyone learns this. The thing people miss is that degree centrality on a directed graph without distinguishing between in-degree and out-degree is meaningless. A politician and a troll might have the same total degree but completely different network positions. Calculate them separately and report both.
Betweenness centrality is where things get interesting and expensive. It scales poorly with graph size. On a graph with more than 5,000 nodes, the default implementation starts taking noticeable time. There is a parameter called normalize. Setting it to TRUE is important because betweenness values are inherently unbounded and comparing betweenness across different-sized graphs without normalization is statistically invalid. I once saw a researcher compare betweenness scores from a 200-node network against a 2,000-node network on the same plot without normalizing. The comparison meant absolutely nothing.
Closeness centrality has a well-known problem with disconnected components. The standard formula returns zero for any node that cannot reach all other nodes in the.Watts and Strogatz adjustment divides by the number of reachable nodes instead. igraph implements this as closeness with the cutoff parameter. Use it. Do not use the default on a network that is anything other than fully connected.
Eigenvector centrality is useful but fragile. It only exists for certain graphs and can fail to converge on sparse or highly skewed networks. If the function returns NaN or a warning, your graph structure is preventing the calculation. This happened to me on a citation network where a handful of papers had thousands of incoming citations and everything else had one or two. The power iteration method could not stabilize. I switched to harmonic centrality instead, which does not have this convergence issue and gave me practically the same ranking for the core nodes I cared about.
Community Detection Without Wasting Three Days
This is the section where people get stuck. igraph has at least seven community detection algorithms and they do not always agree. Label propagation, fastgreedy, multilevel, walktrap, spinglass, leading eigenvector, and the newer Leiden algorithm. Each uses a different optimization strategy and will give you different partitions on the same data. I ran all seven on a protein-protein interaction network last year. The partition overlap ranged from zero to forty percent depending on the pair of algorithms. There is no single correct answer.
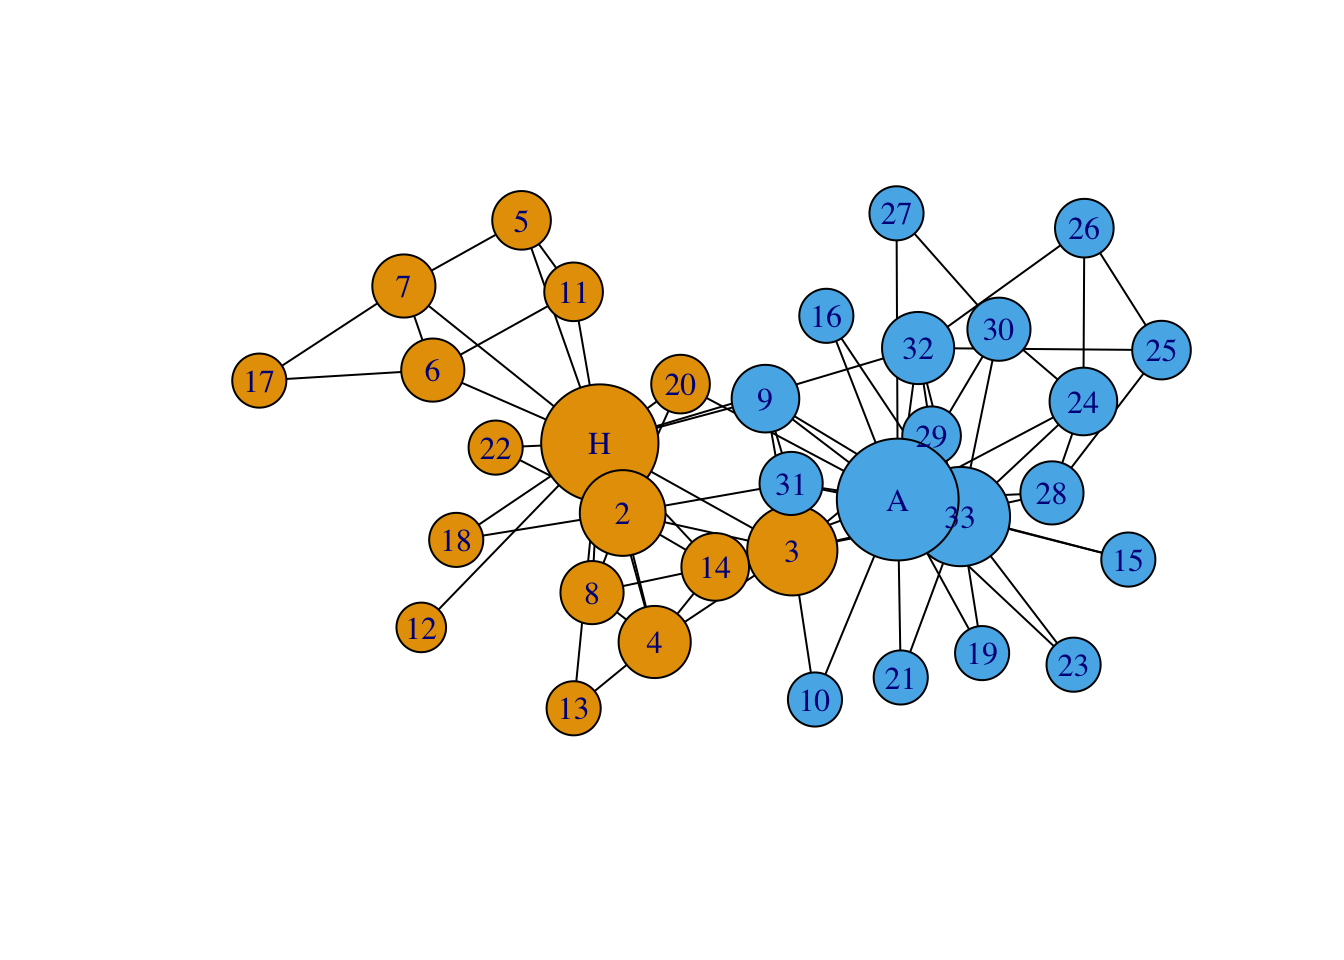
The practical approach is to run two or three that are fundamentally different from each other—say, Leiden and walktrap—and look at the nodes where they agree. Those are your stable communities. The nodes where they disagree are the ambiguous ones, and you should report that ambiguity rather than pretending one result is definitive. I always calculate the modularity score for each partition and only proceed with partitions that have a score above 0.3. Below that, the community structure is usually noise.
Visualization That Does Not Look Like Spaghetti
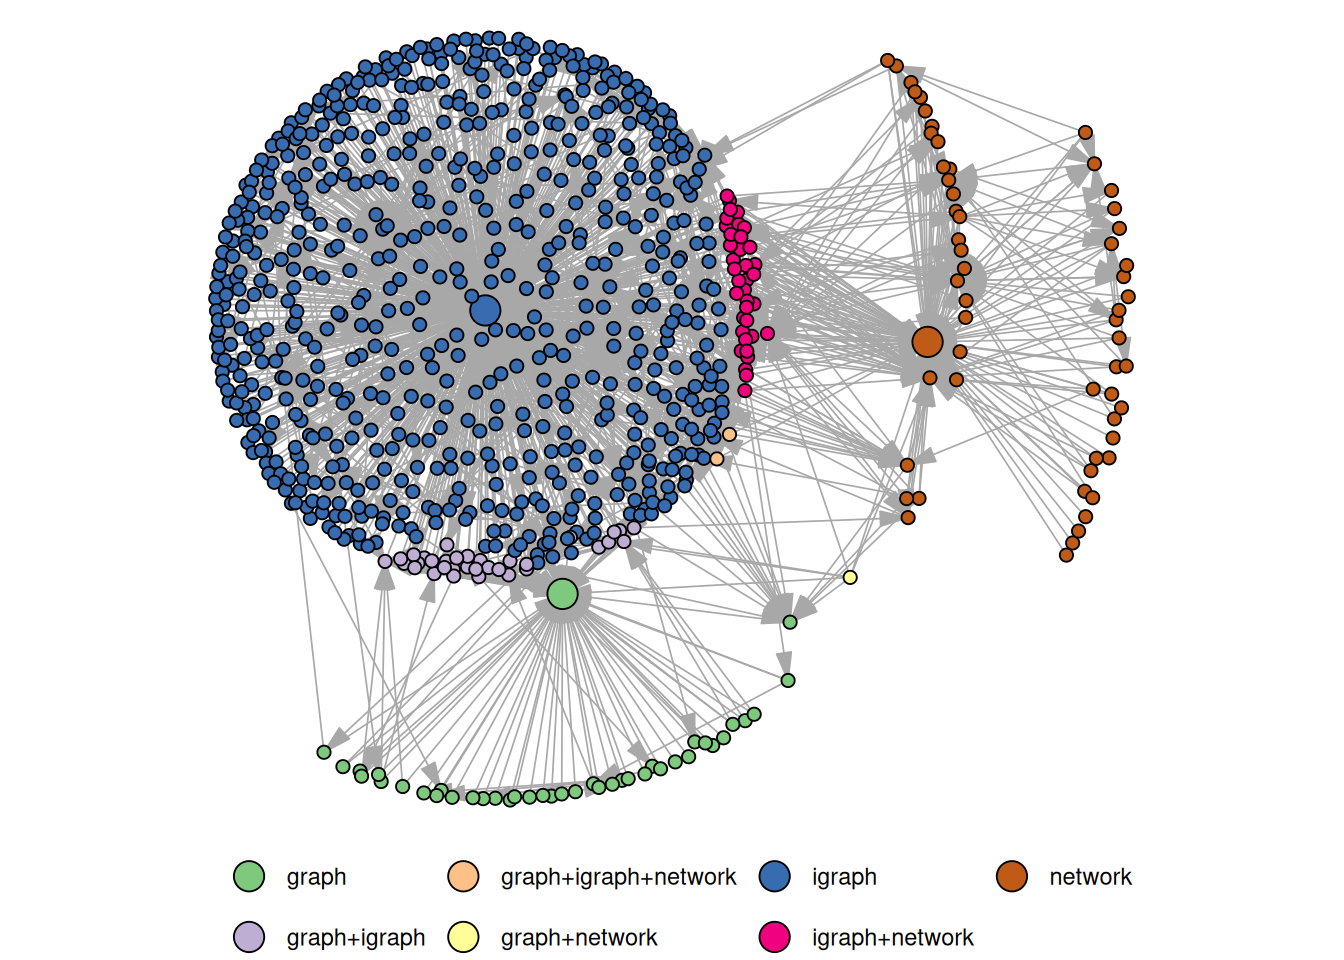
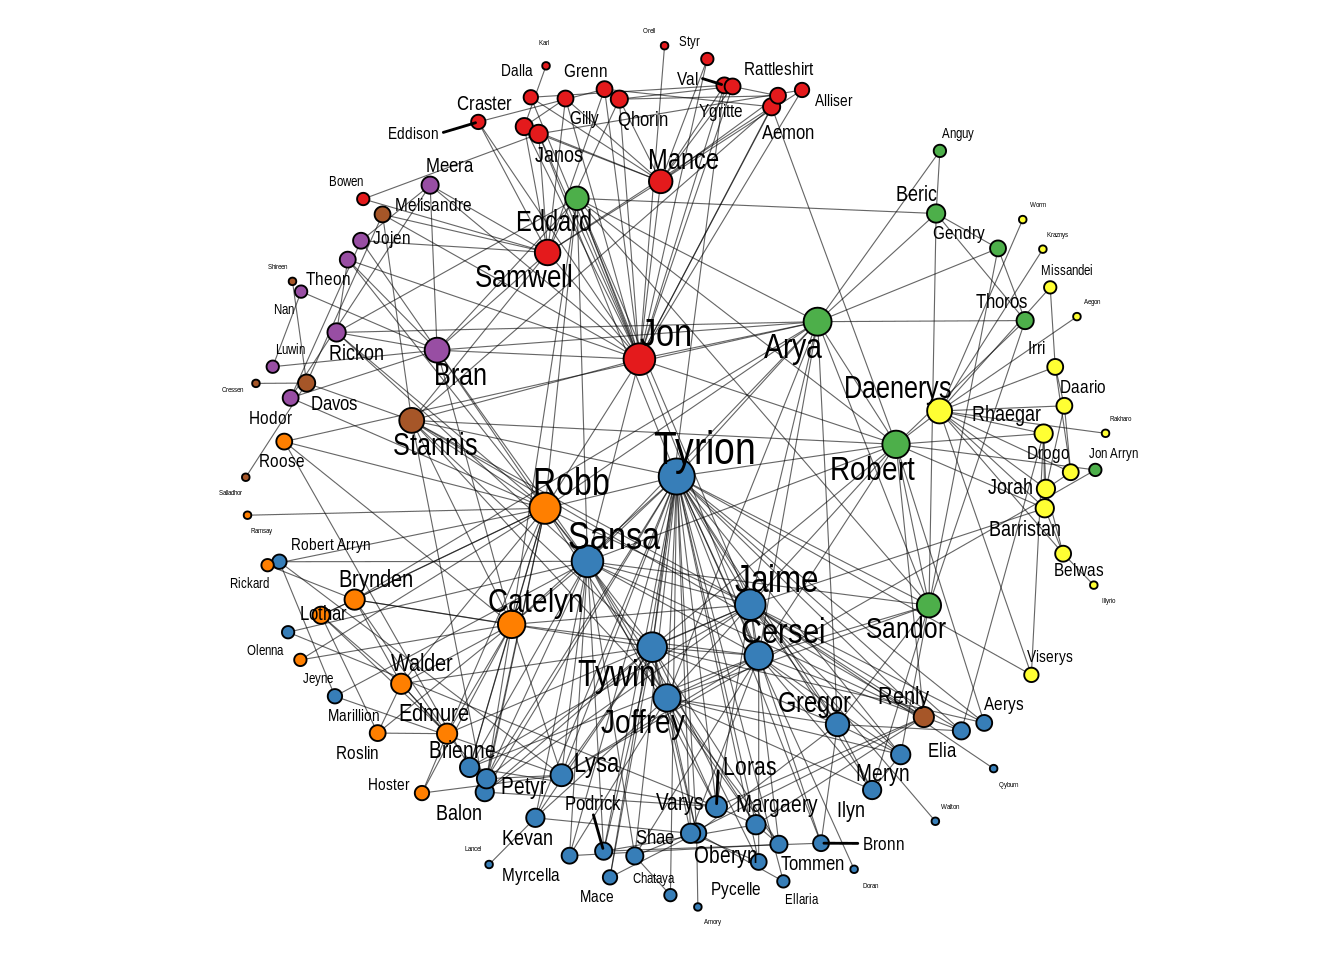
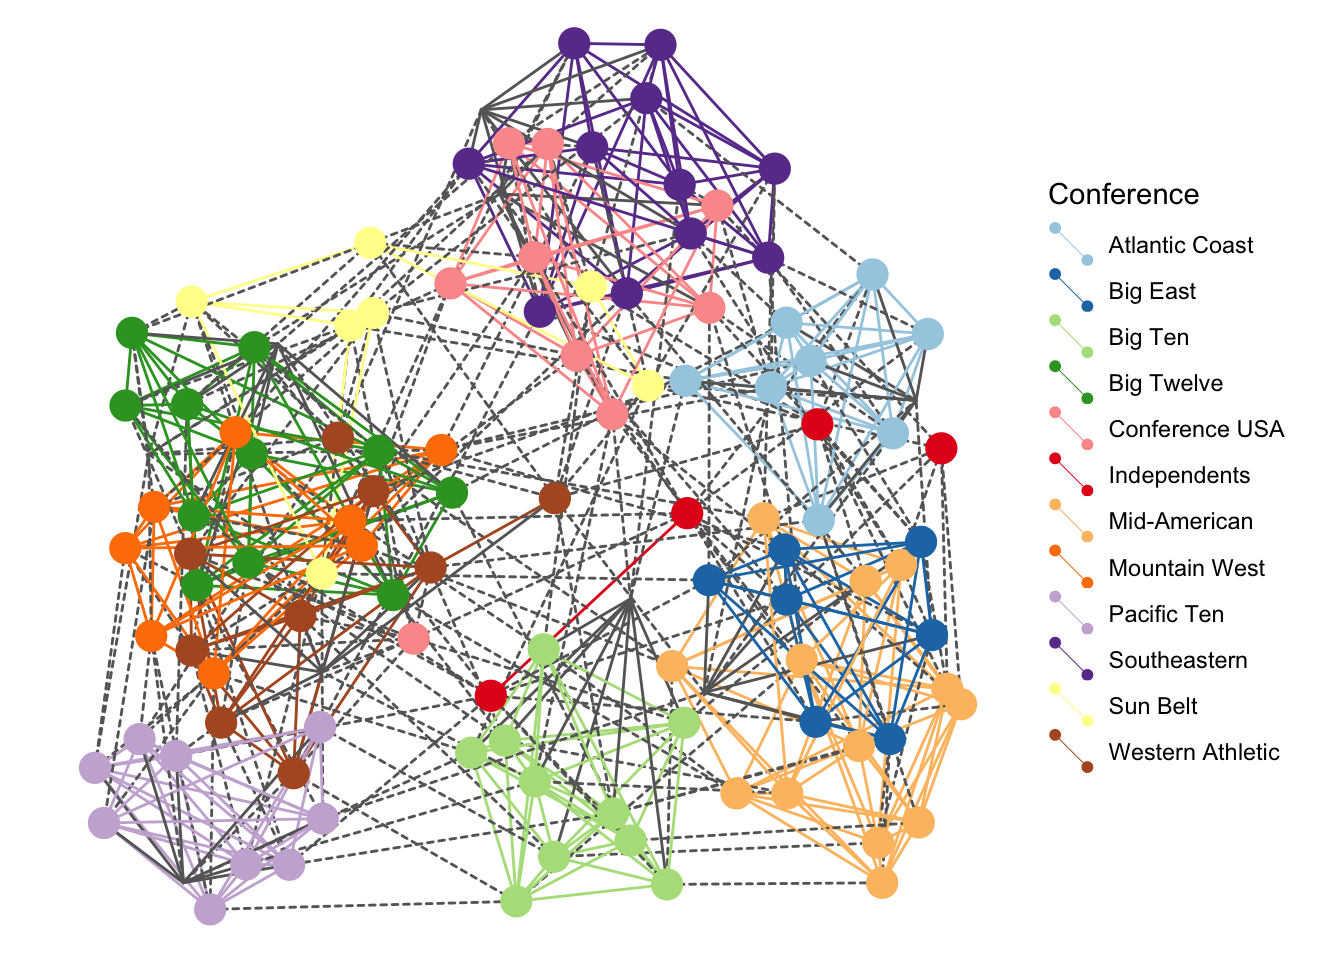
Network visualization in R is harder than the analysis itself. igraph's plot function works for small networks but produces unreadable output past roughly 50 nodes. The edges overlap, labels collide, and the layout algorithm defaults to something that looks random. I stopped using plot.igraph years ago.
For anything above fifty nodes, I use ggraph with a force-directed layout. The key parameters are repulsion, gravity, and iterations. The default repulsion is too low for dense networks, which causes nodes to cluster in the center and leaves the periphery empty. I set it to 500 or higher depending on density. For labeled networks, I turn off labels during initial layout and add them only after the layout stabilizes. Trying to plot labels and compute the layout at the same time creates a feedback loop where the labels shift the layout and the layout shifts the labels and nothing converges.
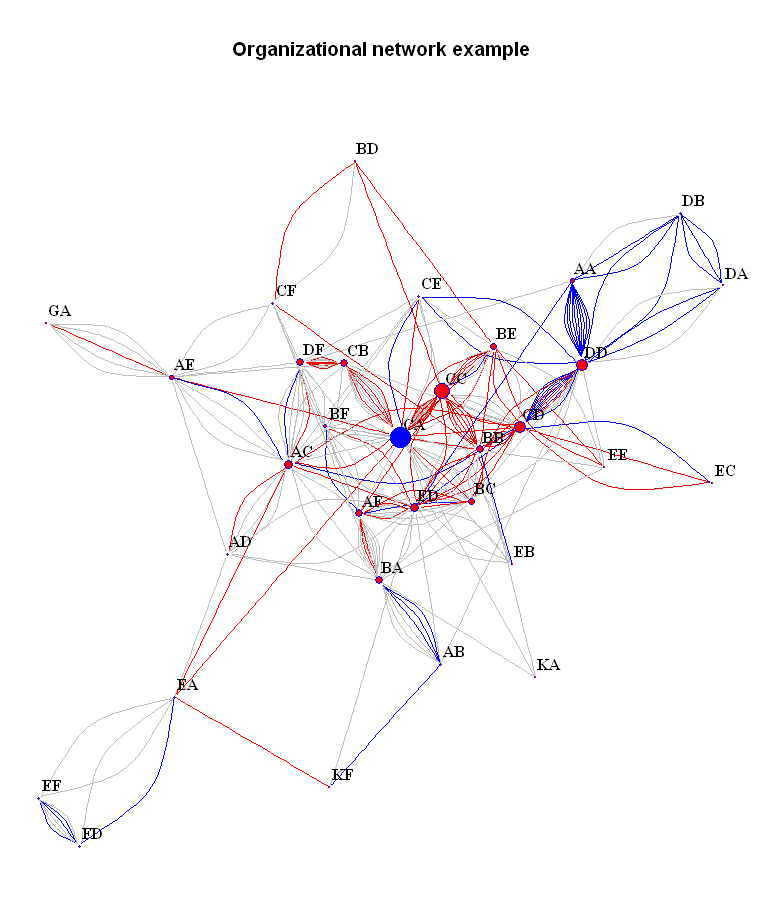
One specific problem I ran into repeatedly involves self-loops and parallel edges. These are valid in many network types but igraph's default layouts treat them like normal edges and push them into the same visual space as other connections. I filter them out before plotting unless they are the specific feature I am studying. A self-loop on a 300-node social network adds zero information to a visualization and ruins the layout.
When R Is The Wrong Tool
I will be honest about where Network Analysis In R breaks down. It does not scale to interactive or real-time network analysis. If you need to update a network visualization every few seconds as new data arrives, R is the wrong choice. Python with networkx plus a web framework, or specialized tools like Gephi for exploratory work, will serve you better.
R also struggles with hypergraphs and multiplex networks. igraph handles simple graphs. If your data involves relationships that connect more than two nodes simultaneously, or networks where multiple edge types exist between the same pairs of nodes, you will need to either simplify your model or use a package like hypergraph that is less mature and has fewer worked examples. I spent two weeks last year trying to fit a multiplex transportation network into igraph's framework and ended up representing it as three separate layered graphs with cross-layer edges. It worked but it was a hack and every downstream analysis required manual adjustment.
Missing data is another blind spot. R assumes your edge list is complete. If you have observational data where some ties were not recorded, standard network metrics will be biased downward. There are statistical imputation methods for this but they are not built into igraph and require custom code. I have written my own bootstrap-based imputation routine for this exact scenario. It takes about twenty minutes to run on a 1,000-node network but it produces more realistic centrality estimates than just dropping missing edges.
The Practical Workflow I Actually Use
I load the data, clean the node names, create the graph object, check for self-loops and parallel edges, calculate the basic metrics with normalization where it matters, run two community detection algorithms and compare them, assess modularity, and only then move to visualization. The whole process for a typical 500-node dataset takes about forty-five minutes. The same process on a 10,000-node dataset takes about six hours because betweenness and eigenvector centrality are the expensive operations. If you need to speed it up, drop betweenness and use page_rank as a proxy. The rankings correlate strongly enough for most purposes and it runs in a fraction of the time.
You do not need to master every algorithm. Pick the ones that match your research question, understand their assumptions and failure modes, and report the limitations alongside your results. Network Analysis In R is powerful but it rewards people who actually read the documentation for the functions they use rather than copying code from Stack Overflow.
Gallery Network Analysis In R
Network Analysis in R - 4 Network visualization
Social Network Analysis In R
Social Network Analysis In R
Network visualization in R with the igraph package – RE-DESIGN
Chapter 5 Advanced Network Visualization | Introduction to Network Analysis Using R