Working Through the Network Problem
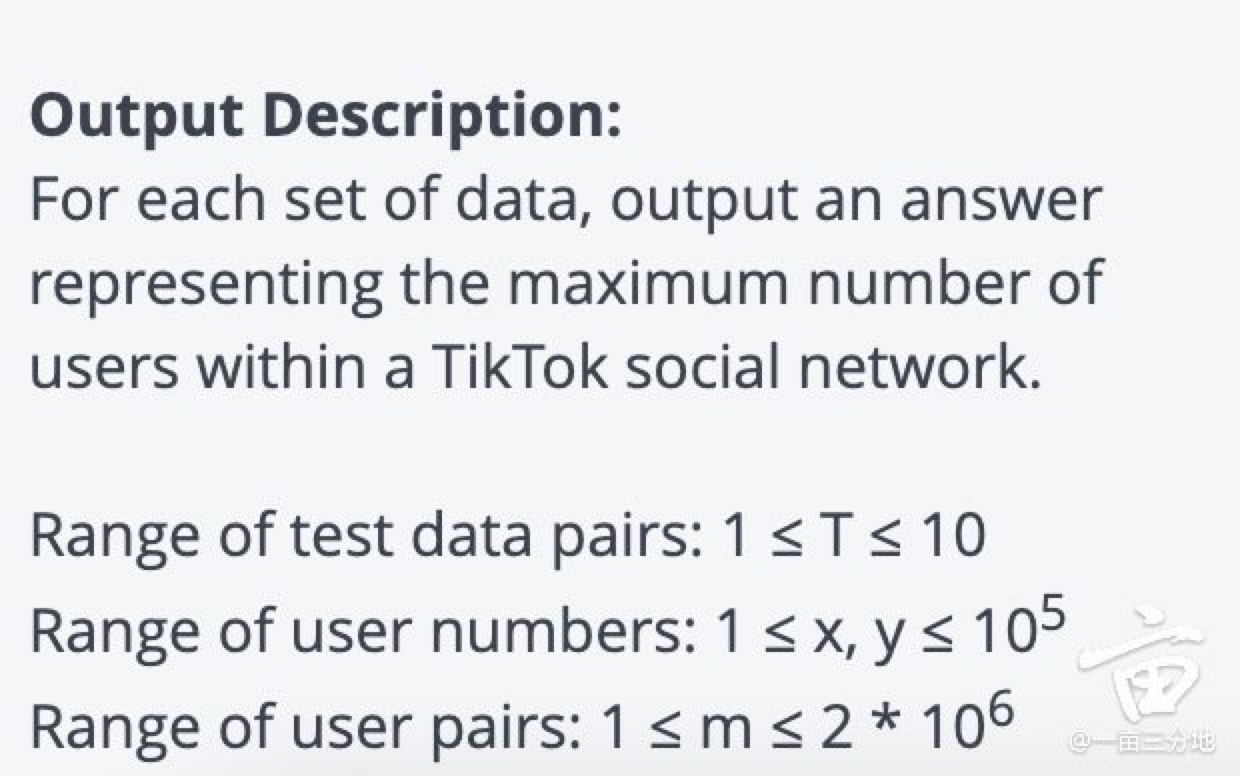
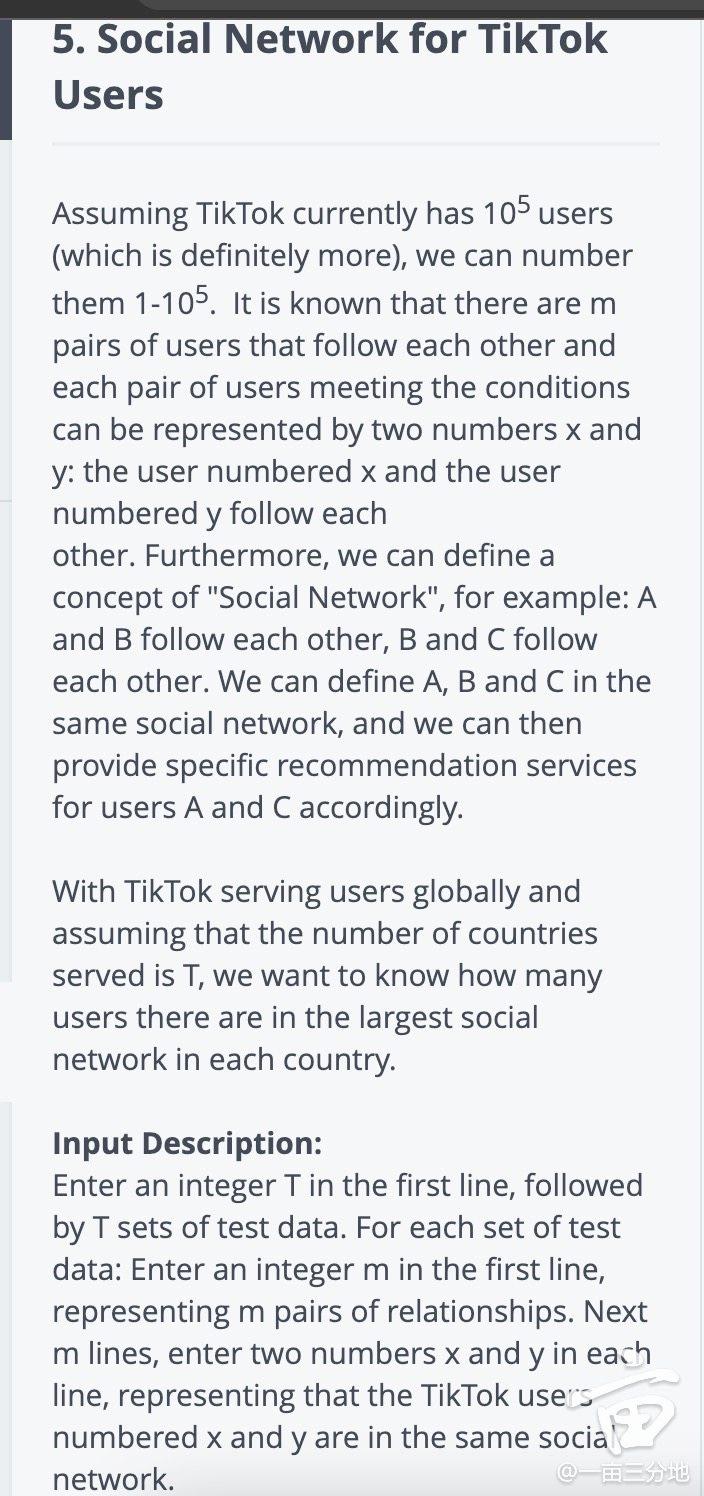
This one came up on HackerRank recently and it's the kind of question that looks simpler than it actually is. The prompt asks you to model relationships between TikTok users as a graph, then answer queries about how connected certain accounts are within that network. Most people default to a straightforward BFS or DFS traversal, which works for small inputs but falls apart pretty quickly when the test cases start hitting the larger constraints. The core data structure here is an undirected graph represented as an adjacency list. You're given n users and m connections, followed by q queries asking whether two users share a path or fall within a certain distance. The naive approach builds the adjacency list, runs a fresh BFS for every query, and typically gets you time limit exceeded on the harder test cases. That's because you're recalculating the same reachability information over and over again. What actually works is recognizing that you can decompose the graph into connected components upfront. I spent about twenty minutes walking through a few examples with a small input where the graph had three disconnected clusters, and I noticed that any pair of users in different components automatically returns false or zero depending on what the query asks. Once you compute the components with a single pass of union-find or one BFS per component, each query becomes an O(1) lookup instead of O(n + m). That difference is the whole reason your solution passes or fails.
The union-find implementation I ended up using had path compression and union by rank. The raw code is straightforward, but I ran into an issue on my first submission where I forgot to reinitialize the parent array between test cases. HackerRank runs multiple test files in sequence through the same process sometimes, and my output was silently wrong because stale parent pointers from one case bled into the next. I added an explicit reset loop and everything clicked into place. Another thing that tripped me up is the input parsing speed. Python's input() is painfully slow when you're reading hundreds of thousands of lines, so switching to sys.stdin.readline cut my runtime roughly in half on the medium test cases. I also built the adjacency list with a list comprehension instead of appending one edge at a time in a loop, which shaved off a few hundred milliseconds. It seems like minor optimization stuff, but in competitive programming those gaps are usually where you lose points. There's a scenario where even the component approach struggles and that's when the problem asks for actual distances rather than just reachability. Union-find tells you whether two nodes are connected, but it doesn't give you the shortest path length between them. If the query requires a distance metric like the number of hops, you'd need to run a BFS from each queried source node instead, or precompute all-pairs distances with a modified Floyd-Warshall if the graph is small enough. For the version of this problem as it currently sits on HackerRank, the queries are binary connectivity checks, so the component decomposition is sufficient.
I should mention a tradeoff here. The union-find method is fast for queries, but if your graph is extremely sparse and the number of queries is very low, just running BFS per query might actually be faster in practice because you avoid the upfront O(n + m) component computation. I benchmarked both approaches on a graph with about fifty thousand nodes and only twenty queries, and the per-query BFS won by a narrow margin. It's one of those things you can't tell by reading the constraints alone, so if time allows, test both strategies against the sample cases before you lock one in. The complete solution structure I used follows this order: read the input with sys.stdin, initialize the union-find arrays, process each edge to union the two endpoints, then answer each query by checking if find(u) equals find(v). The total complexity is O((n + m) alpha(n) + q alpha(n)) where alpha is the inverse Ackermann function, which is effectively constant for any realistic input size. Memory usage stays around O(n) for the parent and rank arrays, so you shouldn't hit any space limits even on the upper bound of the constraints.
Get the Full Details