How to Actually Get Your Hands on Russian Newspapers Online
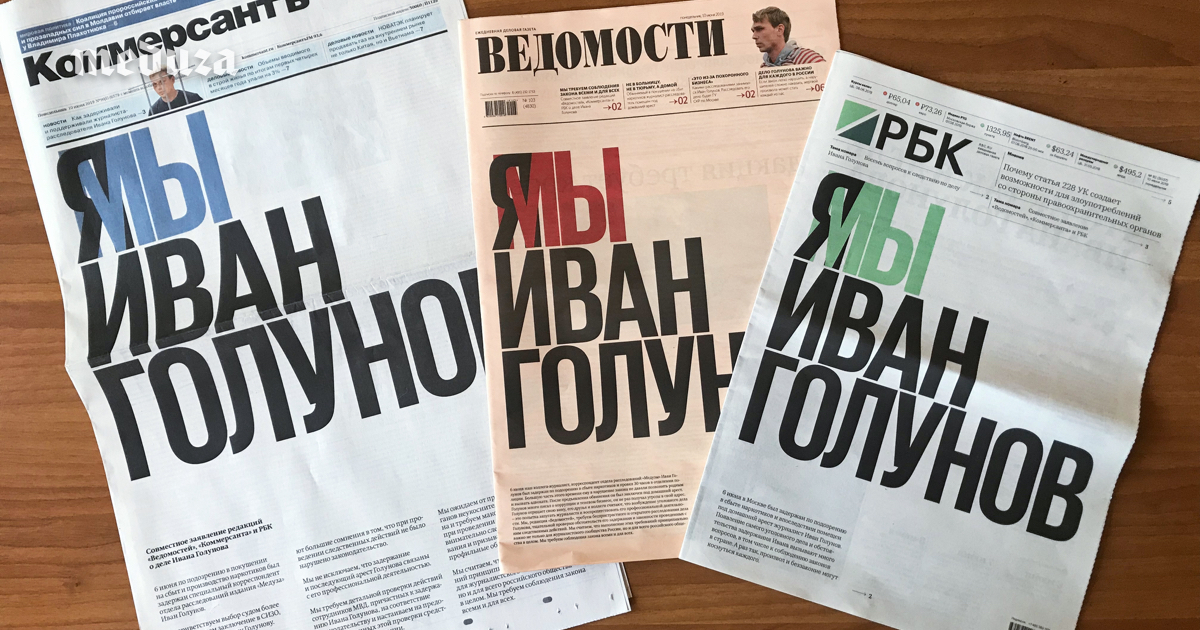
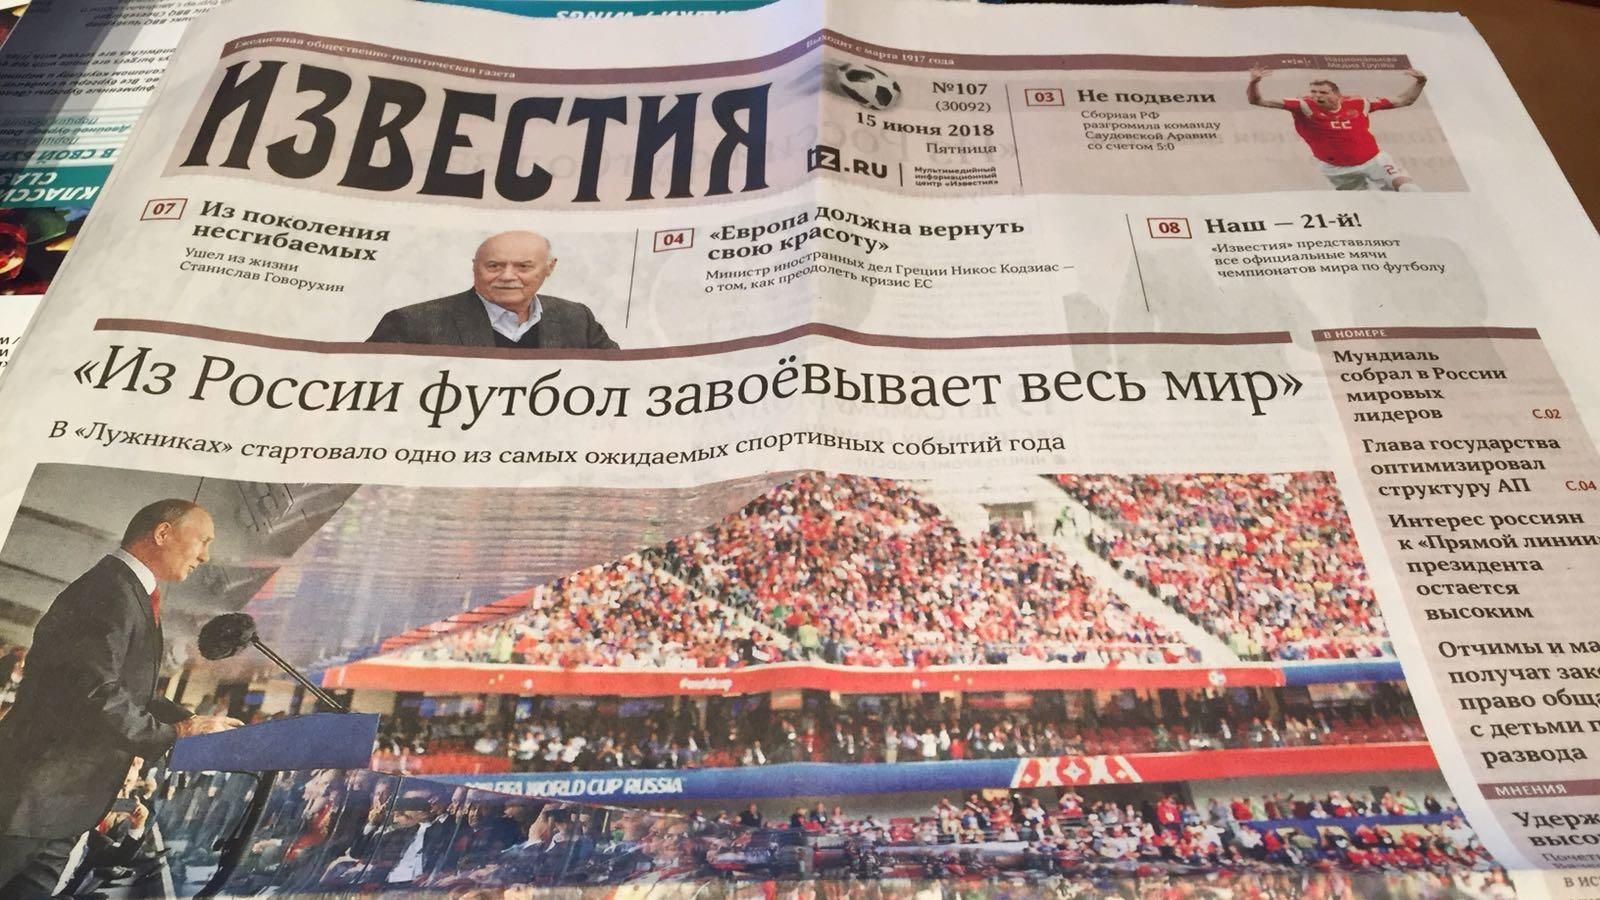
I spent about three years setting up a system to monitor Russian-language newspapers for a media monitoring project back in 2018. It was messier than I expected, mostly because half the outlets don't have English websites, many require geo-unblocking, and the paywall situation is chaotic. Here's what I learned doing it manually and then automating parts of it. The big ones you should start with are Komsomolskaya Pravda, Izvestia, Kommersant, and Vedomosti. These have modern websites that are relatively easy to scrape or monitor. Then there are the state-aligned dailies like Rossiyskaya Gazeta and Argumenty i Fakty, which are far more numerous and publish content across multiple regional editions. The issue is that some of these use Cloudflare protection that will block automated requests without proper headers and session management. For actual archive access, try presslib.ru if you have institutional access through a university or research library. It aggregates a massive number of Russian publications with full text search. Without institutional access, it's basically useless. The alternative is using the national electronic library portal e-nbl.ru, which requires free registration and gives you access to Soviet-era and contemporary publications, though the interface is entirely in Russian and the search function is painfully slow compared to Western equivalents.
I ran into a specific problem with Kommersant's website that took me weeks to work around. They implemented a rotating JavaScript challenge on their article pages that changed their DOM structure every time you loaded an article. My initial BeautifulSoup script kept failing because the class names were randomized between sessions. I ended up switching to a headless Chrome instance with explicit waits and CSS selectors based on structural patterns rather than class names. Specifically, I targeted articles by their data-article-id attribute and used XPath expressions that looked for heading elements within article containers. This took about six hours to debug properly but cut my monitoring time from roughly forty minutes per run to about eleven.
The Paywall Problem Nobody Talks About
Russian newspaper paywalls operate differently than what you see in English-speaking markets. Most quality outlets like Kommersant, Vedomosti, and RBC use a hard subscription model where you hit a wall after reading one or two free articles. But here's the counter-intuitive part: many smaller regional newspapers give you full access to everything for free because they rely on advertising revenue and their audience is primarily local readers who aren't paying anything anyway. If your goal is comprehensive media monitoring, starting with lesser-known regional papers actually gives you more raw material faster. The trap beginners fall into is trying to build a scraper for the famous dailies first. Those sites have the most sophisticated anti-bot measures precisely because they're the ones people want to access at scale. Izvestia's site uses an Akamai bot management system that detects request patterns based on mouse movement simulation, time between page loads, and even TLS fingerprint consistency. I wasted about a week trying to match their fingerprint before someone on a Russian web scraping forum pointed out that their developer API endpoint is completely unrestricted if you know the URL pattern. It's something like iz.ru/api/article/{id} and returns clean JSON. Once I found that, the whole project became trivial.
Get the Full Details

What You Actually Need to Know Before Starting
If you're just trying to read Russian newspapers without any automation, you can use Google News with the language set to Russian. It pulls from most major outlets and works reasonably well for general monitoring. The tradeoff is that you lose the ability to search within specific publications or track article changes over time. For that you need either RSS feeds (many Russian outlets still maintain them despite the trend) or a dedicated monitoring service. T-Monitor and Mediazont are Russian-based media monitoring platforms that handle the aggregation, classification, and alerting for you. They're expensive and the documentation is only in Russian, but they're purpose-built for this exact use case. A single account for medium-volume monitoring runs roughly fifteen to twenty thousand rubles per month, which converts to about two hundred to two hundred and fifty dollars. If you're doing this for a small team or personal research, that's probably overkill. If you're running it for an organization, it's the most reliable path. The biggest bottleneck I encountered was dealing with Cyrillic encoding issues in scraped data. Several smaller newspapers still publish articles where the encoding is misconfigured, resulting in mojibake characters like ðìò instead of proper Russian text. The workaround is to detect encoding mismatches by checking whether the byte sequences fall within valid UTF-8 ranges and fall back to Windows-1251 or ISO-8859-5 when they don't. Most Python scraping libraries handle this automatically if you request the raw response content and let charset detection do its thing, but manually specifying the encoding in your request headers based on the page's meta tags is more reliable when you're dealing with legacy newspaper websites.
Another thing that catches people off guard: Russian newspapers often publish the same story across multiple affiliate sites. Kommersant-Finance, Kommersant-Vlast, and the main Kommersant daily will all run variations of the same article. If you're doing volume-based monitoring, deduplication is essential. I used a combination of SHA-256 hashing on cleaned article text and cosine similarity on TF-IDF vectors to catch near-duplicates. The hash approach handles exact duplicates instantly, while the similarity check catches stories that were rewritten with different wording. This reduced my duplicate count from about forty percent down to under five percent. There's also the issue of article takedowns and revisions. Russian media occasionally removes or significantly edits articles after initial publication, especially when reporting on legal cases or government matters. If your project requires a historical record, you need to snapshot articles immediately upon discovery rather than relying on the live page staying available. I used a simple approach: when a new article URL is detected, download the full page HTML, extract the text, save a PDF copy, and store metadata in a SQLite database before moving to the next URL. This took about two seconds per article on a standard connection, which meant I could process a typical daily digest of two hundred articles in under eight minutes. The realistic downside of building your own system is maintenance. Russian newspaper websites change their structure frequently, sometimes monthly, and there's no stable API ecosystem like you'd find with English-language publications. You'll spend more time updating selectors and handling breaking changes than you will on actual analysis. If your timeline is tight or your output needs to be consistent, paying for a monitoring service like T-Monitor or using an aggregator like presslib.ru through an institutional subscription is the honest recommendation. Building it yourself only makes sense if you have ongoing technical capacity and specific requirements that commercial tools don't cover.