The stuff nobody tells you about running your own NGS pipeline
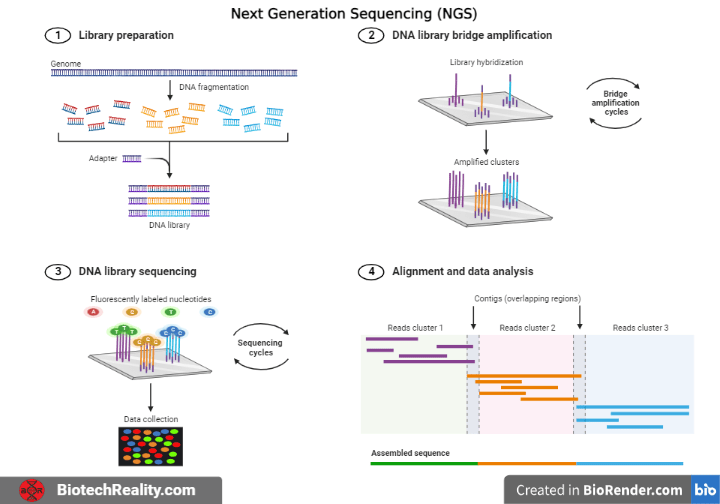
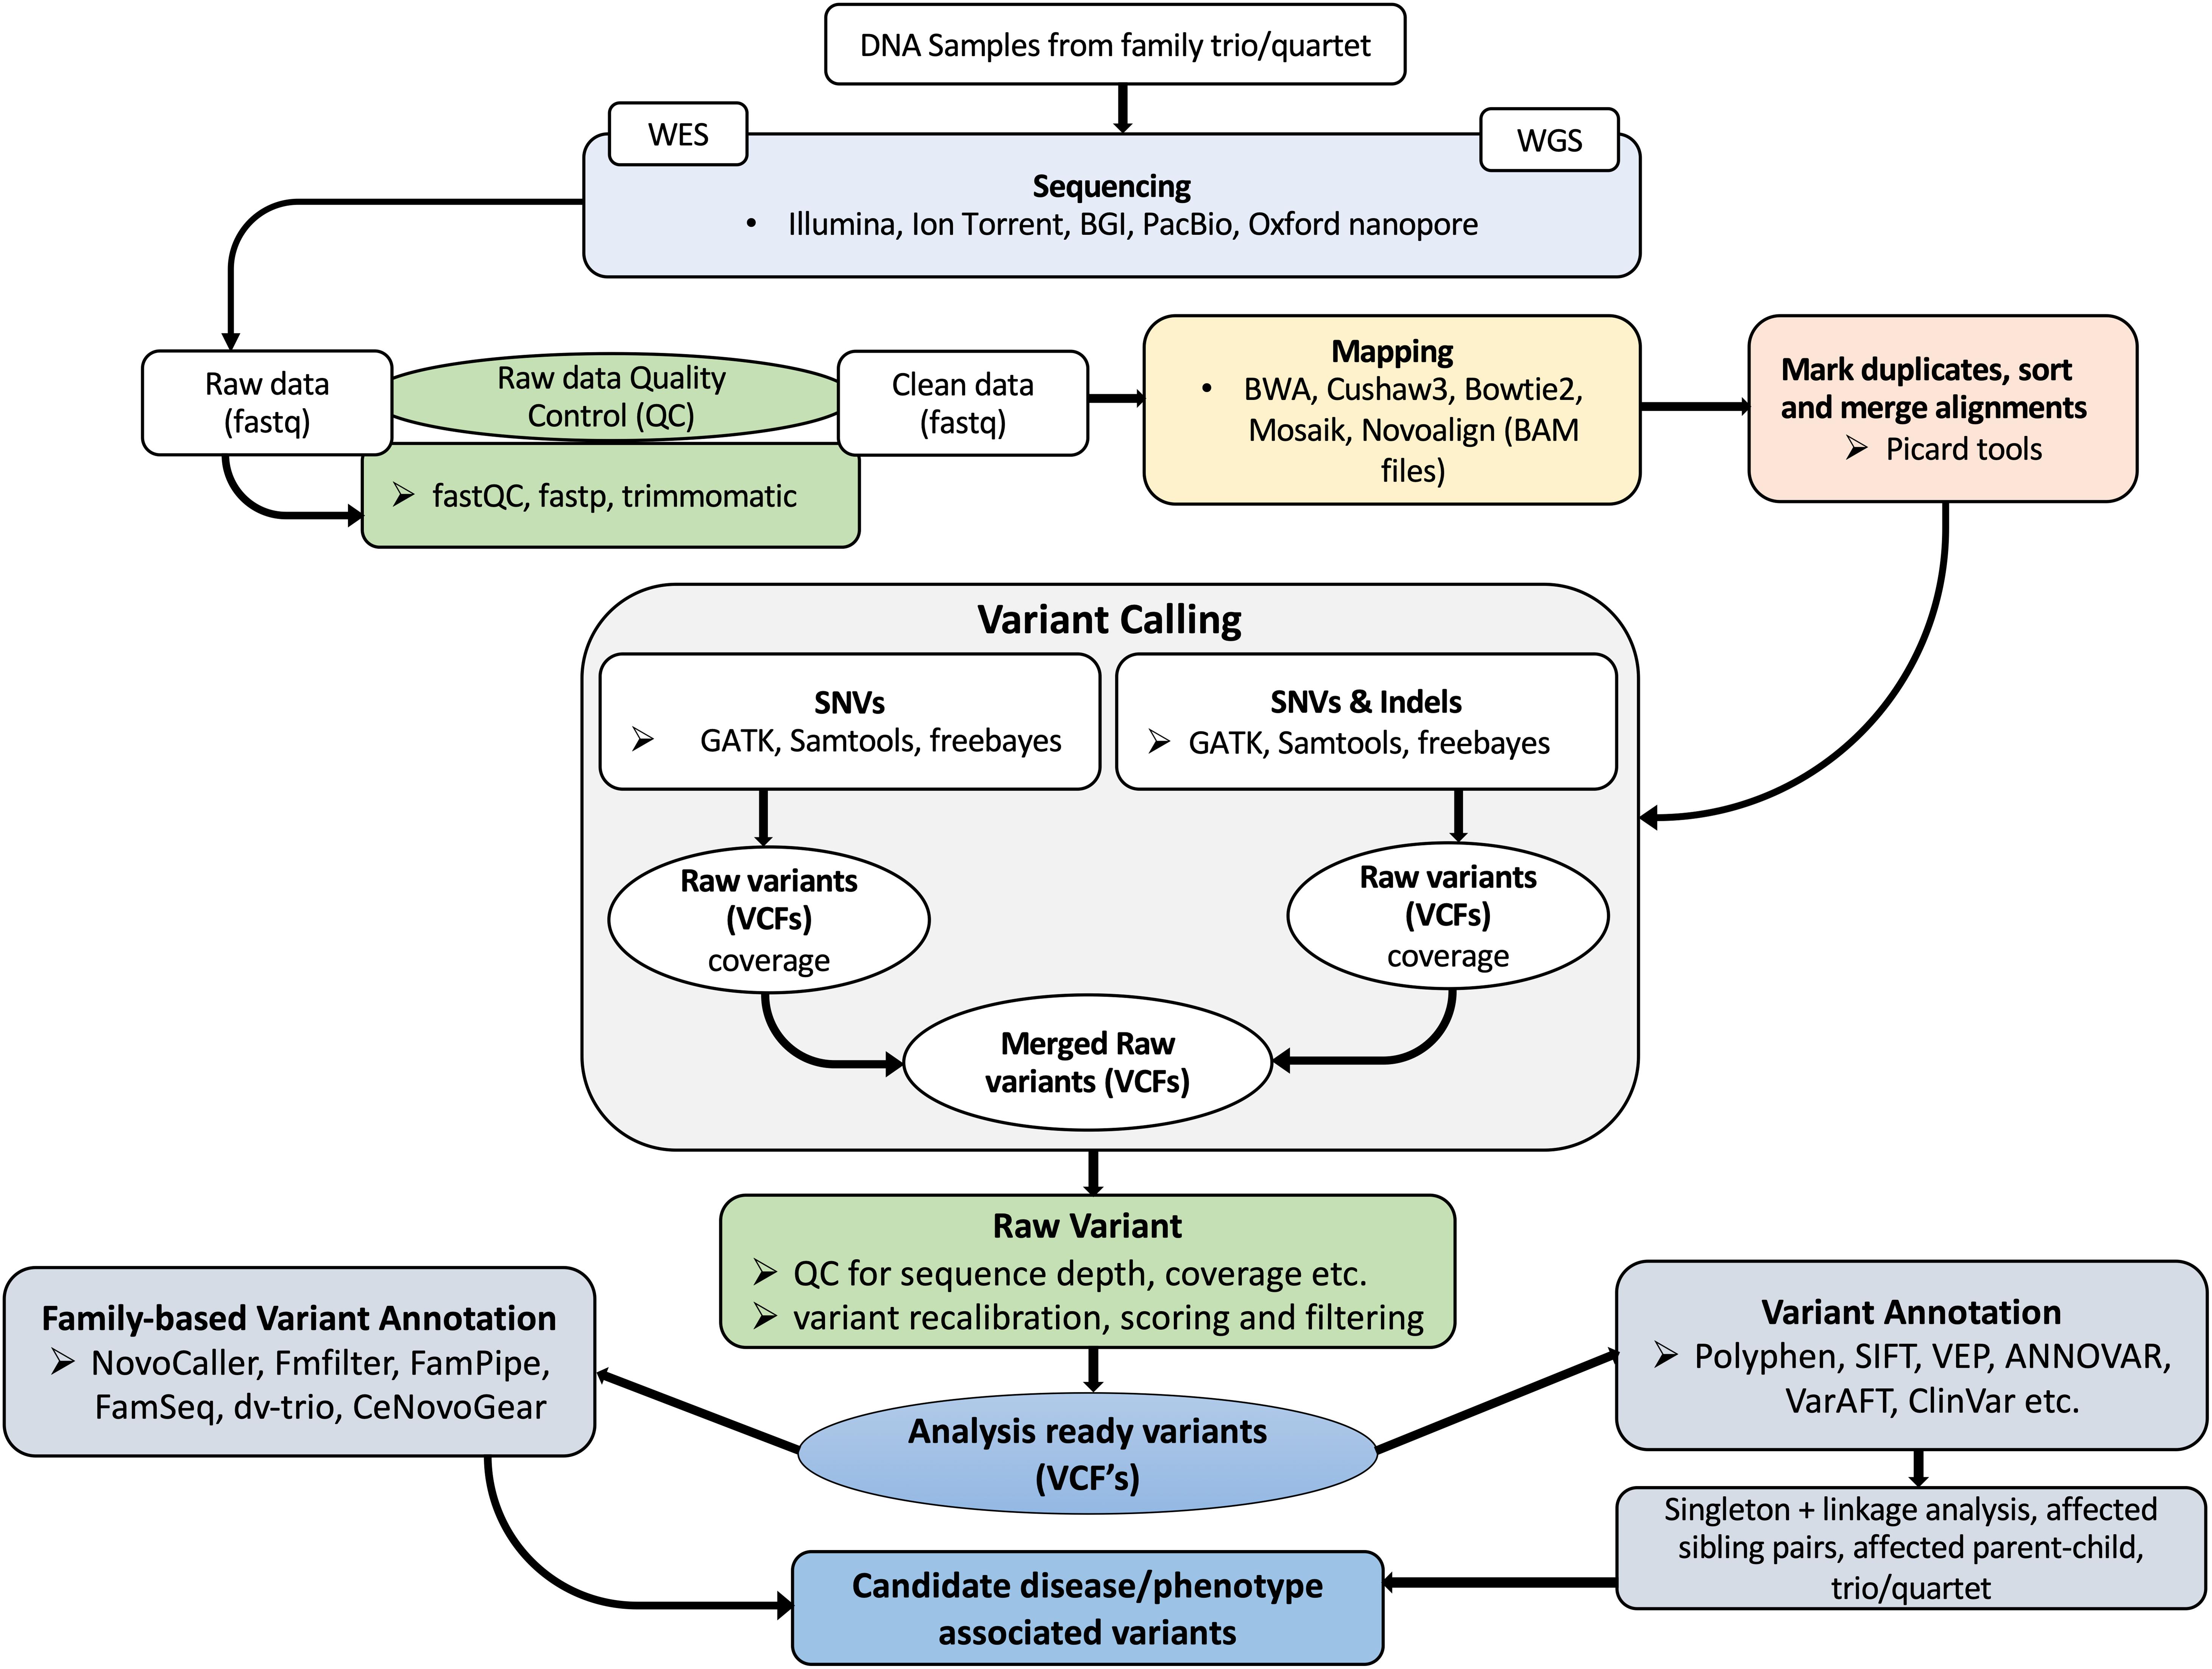
I spent three weeks last year trying to get a 30x whole genome sequencing run to produce clean variant calls because the initial alignment kept dropping reads in GC-rich regions, which is not something you typically learn from the documentation. It turned out the default BWA-MEM settings weren't handling the extreme clamping in those areas, so I ended up switching to a paired-end tuning parameter that relaxed the soft-clipping threshold and re-ran the alignment. Coverage recovered to 94 percent across the target regions, which was acceptable for what we needed. The first thing most people get wrong is how they treat the raw FASTQ files. You download them, you throw them at a aligner, and you call it a day. That works until your adapter contamination rate is sitting at eight percent or your per-base quality scores decay sharply after position 110 on a 150-bp read. Trimming and quality filtering are not optional steps in Next Generation Sequencing Data Analysis. I use fastp for this because it handles adapter trimming, quality filtering, and generates a clean report in a single pass, which saves me from juggling three separate tools. Run it before alignment. Always.
A workflow that actually produces usable results
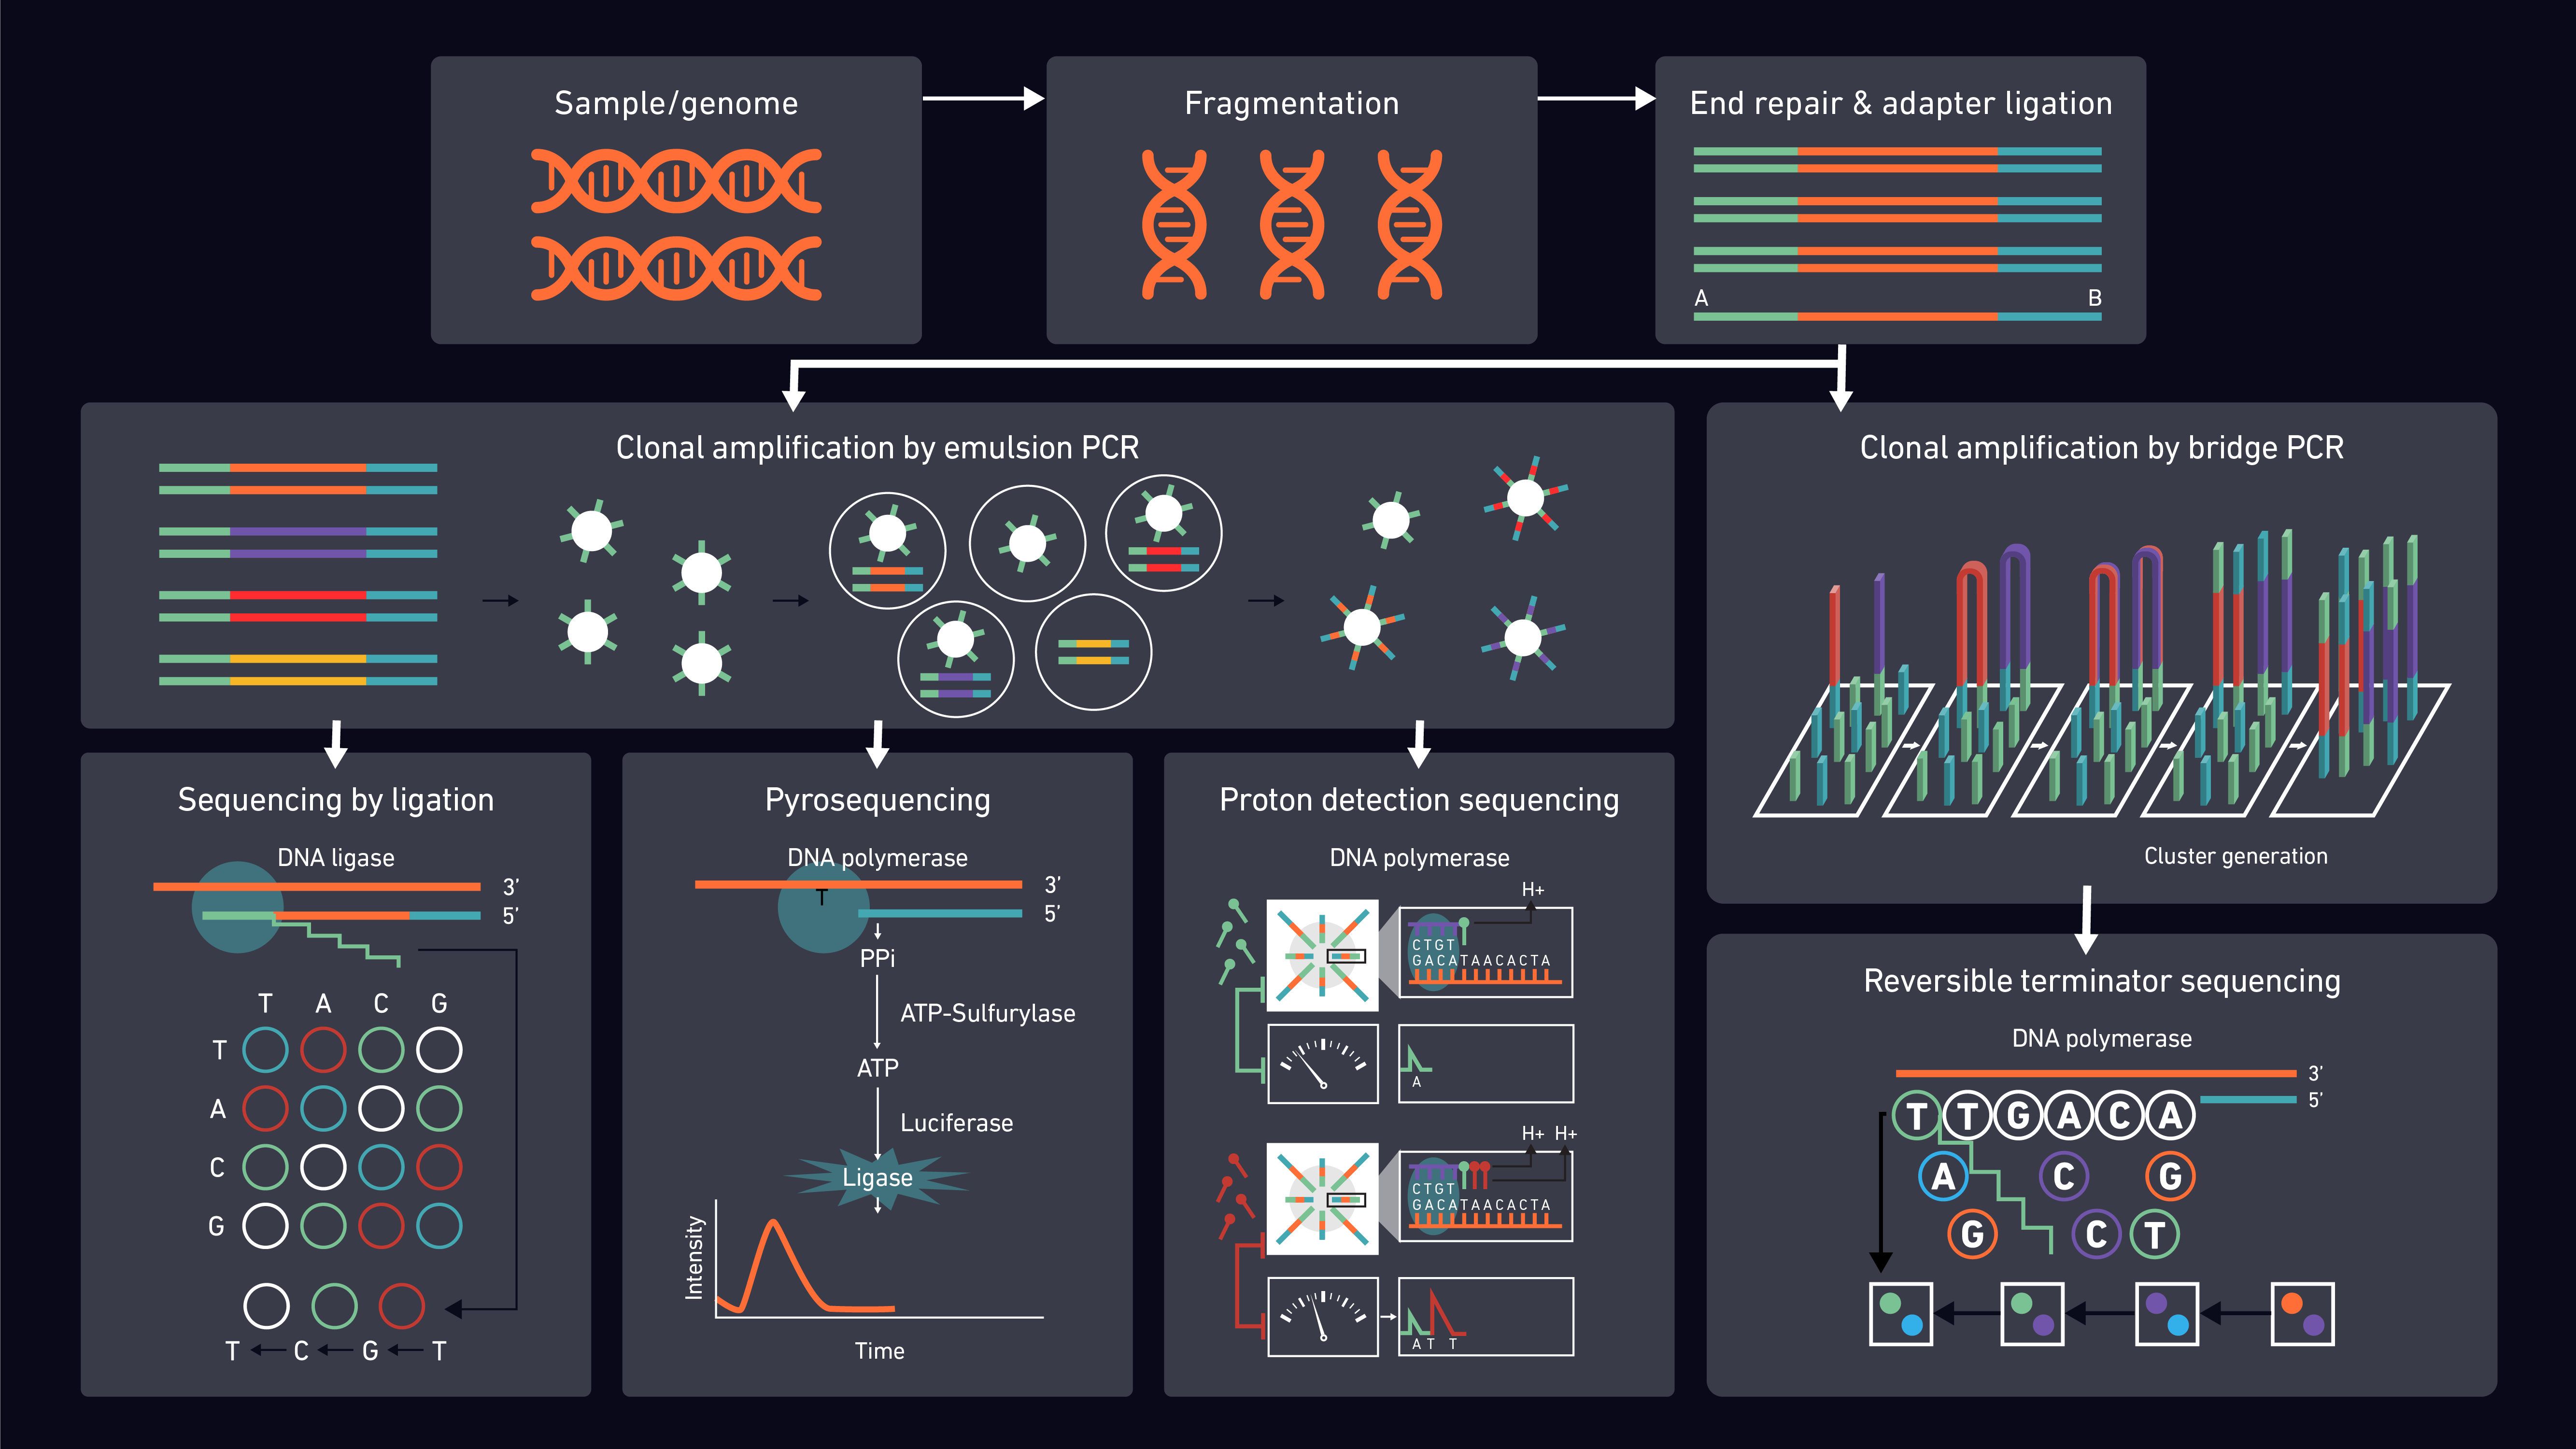
Here is what I run when I need reliable variant calls from Illumina data, starting from demultiplexed FASTQ files. The pipeline takes about four hours on a machine with 32 cores and 128 gigabytes of RAM for a single 30x WGS sample. That timing varies depending on your hardware and the size of your reference genome, but it gives you a baseline. The process begins with trimming using fastp with default parameters unless your library preparation kit has non-standard adapters, in which case you point it at the correct adapter sequences. Then you align trimmed reads with BWA-MEM2 rather than the original BWA-MEM. BWA-MEM2 is noticeably faster on multi-core systems and produces nearly identical alignment scores for standard paired-end data. If you are working with long reads from PacBio or Oxford Nanopore, this does not apply and you should use minimap2 instead. After alignment, you sort the BAM file and mark duplicates. Duplicate marking is essential because PCR artifacts during library amplification create artificial coverage spikes that variant callers interpret as real homozygous variants. Without duplicate marking, your false positive rate climbs significantly, especially in targeted sequencing panels where the same fragment gets amplified and sequenced many times over. I use samtools markdup, which is straightforward and fast enough for most use cases.
The next step is base quality score recalibration. This is one of those steps that beginners skip constantly. The recalibration step corrects systematic errors in base quality scores caused by the sequencing instrument itself, such as cycle-specific quality drops or context-dependent errors around homopolymers. GATK BaseRecalibrator handles this, though it requires a known variants resource like dbSNP to function properly. If you are working with a non-human organism without a good known variants database, you can skip this step but accept that your variant calls may carry slightly higher error rates in specific sequence contexts. Variant calling comes after recalibration. For germline variants in human data, GATK HaplotypeCaller in GVCF mode is the standard approach. It processes each sample individually into a gVCF file, which you then joint-call across a cohort. This joint-calling strategy is important because it allows the caller to compare samples against each other, improving accuracy for rare variants. Single-sample calling works fine for quick checks but produces noticeably worse sensitivity for low-frequency variants when you scale up. For somatic variants from tumor samples, you switch to Mutect2, which requires a normal sample from the same patient for filtering. Running Mutect2 without a matched normal dramatically increases your false positive rate, so do not skip the normal sample collection if you are doing cancer sequencing.
Get the Full Details
Common failure points I have seen repeatedly
One specific issue I ran into recently involved a panel sequencing run where the coverage dropped to near zero in five exons across three different genes. The alignment looked fine everywhere else. The problem turned out to be a primer design flaw in the capture probe set that left a specific exon uncovered. No amount of parameter tuning would fix this because the reads simply never existed in the data. The workaround was to flag those exons as unreportable and rely on an orthogonal method like Sanger sequencing for clinical interpretation of any variants found there. This is a reminder that you should always check your coverage metrics against your capture design before assuming something went wrong with the bioinformatics. Another frequent problem is reference genome mismatch. I have seen multiple people align reads to GRCh37 when their variant annotation pipeline expects GRCh38 coordinates, which produces confusing results that look like biological findings until you realize the entire coordinate system is off by a few million bases in certain regions. Always confirm your reference genome version before starting and keep it consistent across every tool in the pipeline. The UCSC liftOver tool can convert coordinates between versions if you catch the mistake late, but prevention is much less painful. Memory usage is another practical concern that the documentation often understates. GATK's HaplotypeCaller can consume up to 8 gigabytes of RAM per sample during local reassembly, and joint-calling a cohort of fifty samples easily pushes past 64 gigabytes. If your server has limited memory, you will hit swap space and the runtime will balloon from hours to days. Splitting your genome into chunks and processing them in parallel is the standard mitigation, though it adds complexity to your workflow management.
Contamination is a subtle issue that rarely shows up in basic QC metrics. If your sample has even two percent microbial or cross-sample contamination, your heterozygous variant calls become unreliable because the contaminant reads create artificial allele balance distortion. The tool VerifyBamID can estimate contamination levels from your BAM file by comparing your genotype calls against a contamination reference panel. Run it early enough that you can identify contaminated samples before wasting compute time on downstream analysis.
Practical recommendations based on what actually works
If you are getting started and want something that runs without constant debugging, the nf-core/sarek pipeline is a solid starting point. It bundles most of the steps I described above into a single Nextflow workflow, handles dependency management automatically, and has active community support. The tradeoff is that it is less transparent about individual tool parameters, which makes troubleshooting harder when something goes wrong. For routine analysis it is excellent. For method development or unusual data types, you will want more control. For organisms without well-established pipelines, the general framework remains the same even if the tool choices change. Trim, align, sort, mark duplicates, recalibrate if possible, call variants, filter. The specific tools swap out but the logic does not. BWA-MEM becomes Bowtie2 or minimap2 depending on your data. GATK becomes FreeBayes or DeepVariant depending on your needs. DeepVariant, by the way, is worth mentioning because it uses a convolutional neural network to call variants and often produces cleaner results than traditional statistical callers, particularly in regions with moderate repeat content where GATK struggles. Storage is the hidden cost nobody budgets for. A single 30x human WGS BAM file after alignment and sorting is roughly 90 gigabytes. Your intermediate files, recalibrated BAMs, gVCFs, and final VCFs multiply that quickly. A cohort of one hundred samples will eat through a terabyte fairly fast if you are not careful. I compress my BAM files with SAMtools and delete intermediate outputs I do not need after each major step, which keeps the total storage footprint manageable without losing the ability to go back and re-run specific steps if needed.
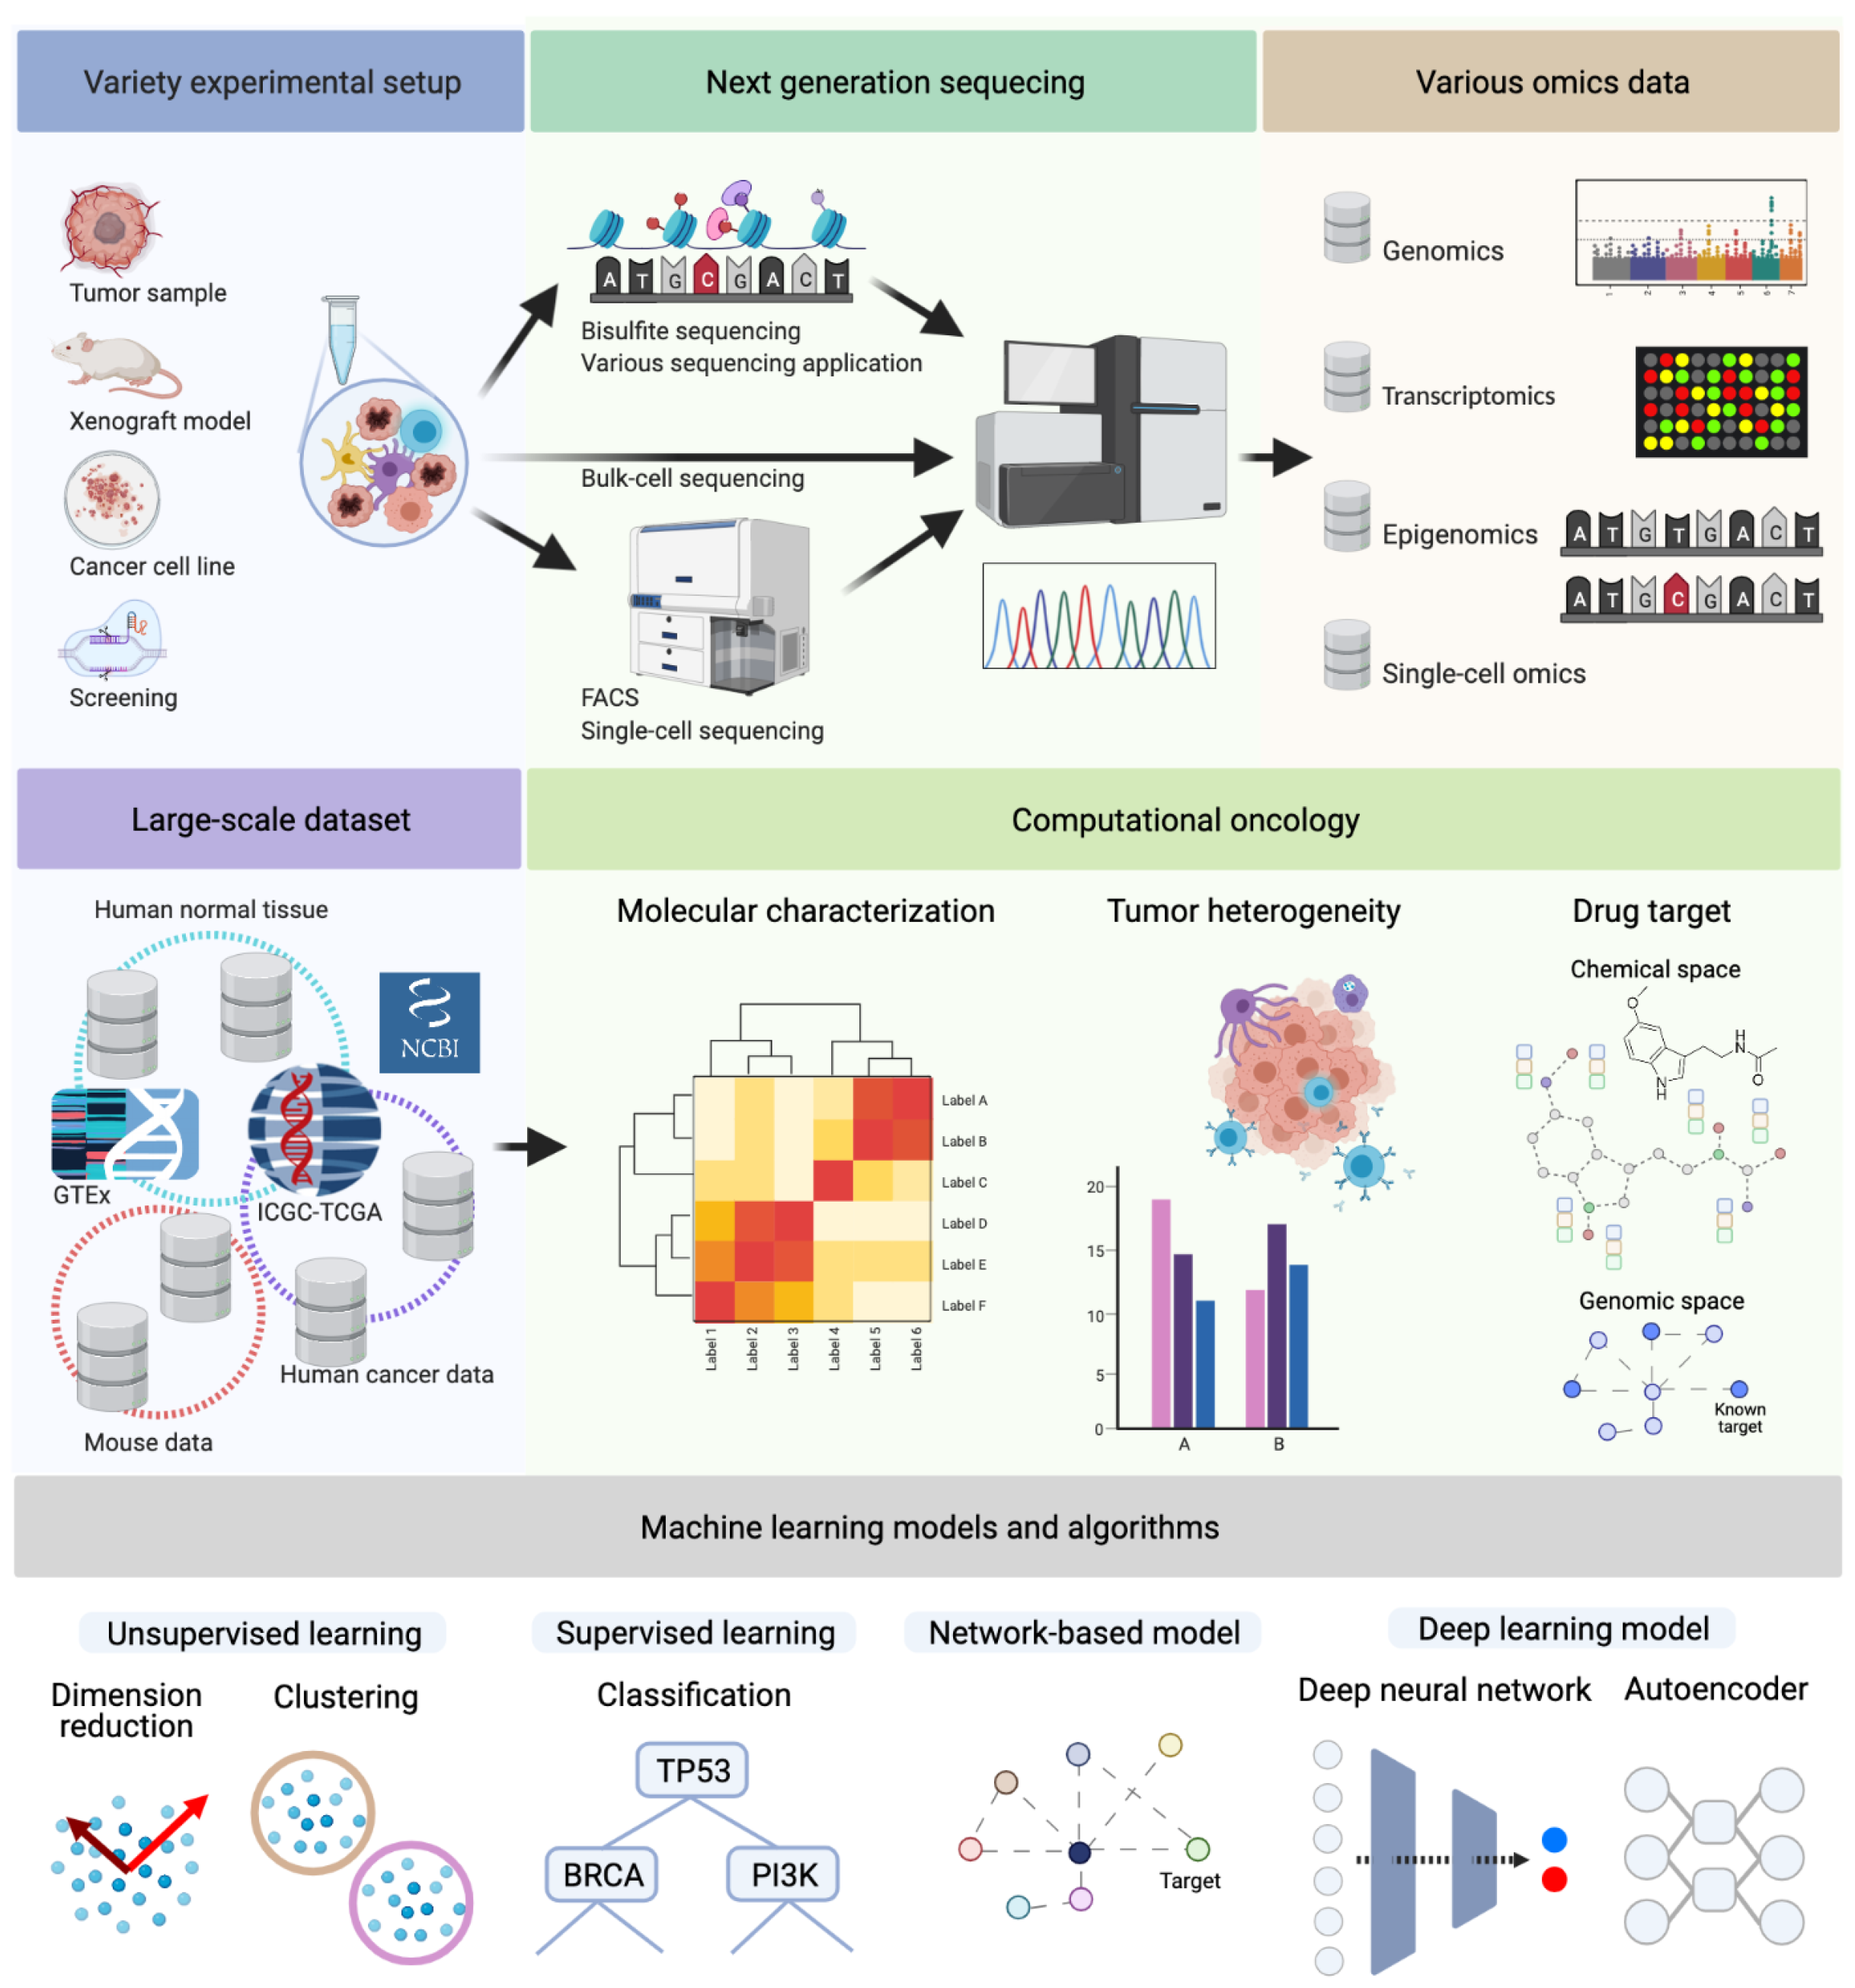
Validation matters. No matter how clean your metrics look, you should validate a subset of your variant calls against an established benchmark set if one exists for your organism and sequencing protocol. GIAB reference materials from NIST are available for several human reference genomes and serve as a reliable ground truth. Running your pipeline against GIAB data tells you your actual precision and recall rather than leaving you to guess based on coverage percentages alone. A pipeline that looks perfect on QC metrics but achieves only 85 percent recall on known variants is producing data you cannot trust for clinical or publication purposes.