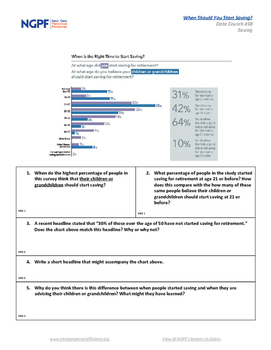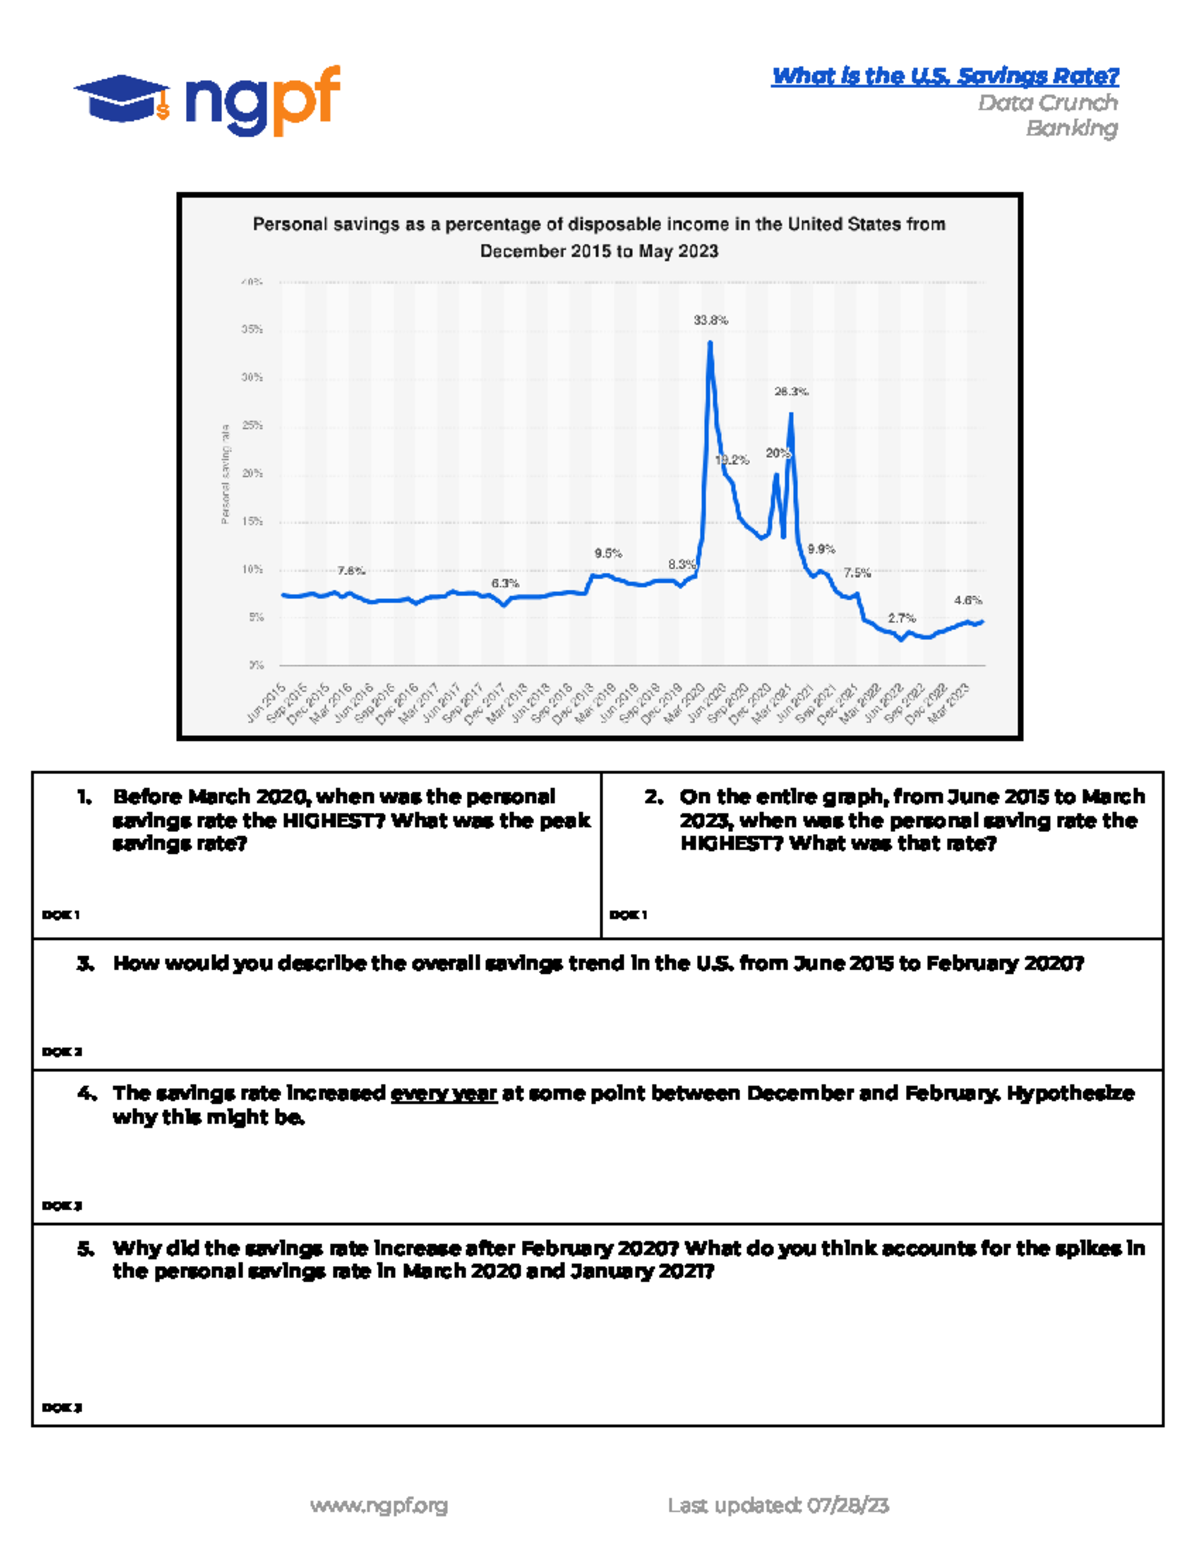
Working With Ngpf Data Crunch
Most people come to this because they uploaded a file and the numbers don't line up. That is the actual problem, not some theoretical issue. The Ngpf Data Crunch Answer Key is really just a reconciliation output that tells you which records matched, which didn't, and why. It is not a magic fix. It is a diagnostic report. The process starts with two datasets: the source file from the sponsor or bank, and the reference data stored in the NPS database. When you run the data crunch, the system does a field-by-field comparison.UAN, name, date of birth, bank account number, IFSC, nominee details, contribution amount. Each field gets a match or mismatch flag. The answer key is the summary of those flags across all records. I remember running this for a mid-sized corporatesponsor about three years ago. We had roughly forty thousand employee records. The crunch came back with nearly eighteen percent mismatches on bank account fields. At first I thought the reference data was wrong. Then I checked the source file format. The sponsor had sent the account numbers with leading zeros stripped out. NPS stores them as twelve-character padded strings. Once we reformatted the source file with proper zero padding, the mismatch rate dropped to under two percent. That two percent was genuine data issues, not formatting problems.
The answer key breaks down mismatches by category. Field-level mismatches, structural mismatches, duplicate entries, missing mandatory fields. You need to look at each category separately. Trying to fix everything at once just creates confusion. I usually sort by mismatch count descending and tackle the biggest category first.
How to Run the Crunch Properly
Download the latest template from the NSDL NPS portal. Do not use an old version. The field mapping changes occasionally and using a stale template silently drops columns you think are being processed. I have seen people waste half a day on this before realizing the template version was outdated. Validate your source file before uploading. Check for blank mandatory fields. Verify date formats match what the system expects. Make sure there are no duplicateUAN entries in your upload file. The system will reject the entire file if duplicates exist. There is no partial acceptance. I run a quick Excel dedup check using conditional formatting on the UAN column. Takes about three minutes for ten thousand rows and saves you from resubmitting the whole batch. After the crunch completes, you get the answer key file along with a success or failure notification. The answer key is usually a CSV or Excel file you can open directly. Download it immediately and keep a copy. The portal sometimes holds files for only a limited window.
Get the Full Details
Reading the Answer Key
Column one is always the record identifier. Column two is the mismatch type. Column three tells you which field failed. Column four has the source value and column five has the reference value when available. Columns six through eight contain system-generated error codes. Some mismatch codes are straightforward. Code E001 means the name spelling differs from the reference. Code B003 means the bank account number does not exist in the DBT enabled list. Other codes are less obvious. E047 for instance relates to nominee declaration format issues that most people do not expect until they see it in the wild. Here is something beginners miss. The answer key does not tell you everything. It only flags what the system compared. If a field is missing from your upload and also missing from the reference, you might not see a mismatch at all. Null matches null. So always cross-check your column count against the template. If you are missing columns, the system cannot flag those fields. You need to verify completeness manually before uploading.
Another thing nobody mentions. The crunch run is not always real time. Depending on the volume and the current load on the NSDL infrastructure, results can take anywhere from ten minutes to several hours. I used to refresh the page every two minutes and lose my mind. Now I submit and check back after sixty minutes unless the portal gives a different timeline on the upload confirmation screen.
Common Problems and What Actually Works
Name mismatches are the biggest headache. Indian names have endless variations. Spelling differences, initials versus full names, special characters getting mangled. The system uses a fuzzy matching algorithm for names, but the threshold is tighter than most people expect. I have seen cases where adding or removing a single space caused a rejection. There is no setting to adjust the fuzzy match tolerance. You work with what the system gives you. The workaround for persistent name mismatches is to go to the CPR search on the NPS portal and pull the exact registered name spelling. Then paste that into your source file. Do not try to standardize names yourself based on what seems correct. The registered spelling is the ground truth. Bank account mismatches follow a similar pattern but are easier to fix because the system gives you the reference account number in the answer key when it exists. Copy the reference value, update your source file, and resubmit. However, if the answer key shows no reference value, it means the account is not yet seeded in the database. In that case you need to complete the bank seeding process through the sponsor portal first. Running another crunch before seeding is done just wastes your time and queue position.
I should mention that the data crunch approach has limitations. It works well when your sponsor data is reasonably clean and complete. When you are dealing with legacy records from before UAN was widely adopted, the matching becomes unreliable. Old records may have multiple entries per person, inconsistent naming conventions, or missing Aadhaar linking. The crunch will flag all of these, but there is no automated way to resolve them. You end up doing manual reconciliation row by row, which defeats some of the purpose of using the tool in the first place. For those cases, I recommend reaching out to your regional NPS helpdesk with a consolidated list of problematic records rather than trying to fix them through repeated crunch submissions. The system also struggles with joint nominee declarations. The format is nested and many sponsors send it as a flat structure. The answer key will show mismatch after mismatch for nominee fields even though the data is technically present. The fix is to restructure the nominee section according to the current template format, which requires understanding the XML schema behind the Excel upload. I keep a reference copy of the schema document saved locally because the portal link breaks occasionally during high traffic periods.
Final Notes
The Ngpf Data Crunch Answer Key is a practical tool if you approach it as a diagnostic rather than a solution. It tells you what is wrong. You still have to figure out why and fix the source. Budget roughly twenty to thirty minutes per ten thousand records for the full cycle including validation, upload, waiting, analysis, and resubmission. The first run always takes longer because you are learning your specific data issues. Subsequent runs are faster once you understand your sponsor's common failure patterns.