Why your vulnerability management program is probably failing
You implemented the controls. You mapped them to NIST SP 800-40, 800-115, and 137. You even wrote the policy document. Yet when the audit came around, you still had critical vulnerabilities sitting in your environment for months with no clear owner. This happens more often than you'd think. The problem isn't that NIST doesn't tell you what to do. It's that their documentation assumes a level of resource maturity most organizations don't actually have. I spent years trying to make everything fit neatly into the compliance boxes, and honestly, it never worked that cleanly. What works is understanding the intent behind the framework and adapting it to your actual situation instead of forcing a square peg into a round hole.
Understanding the Nist Vulnerability Management Policy
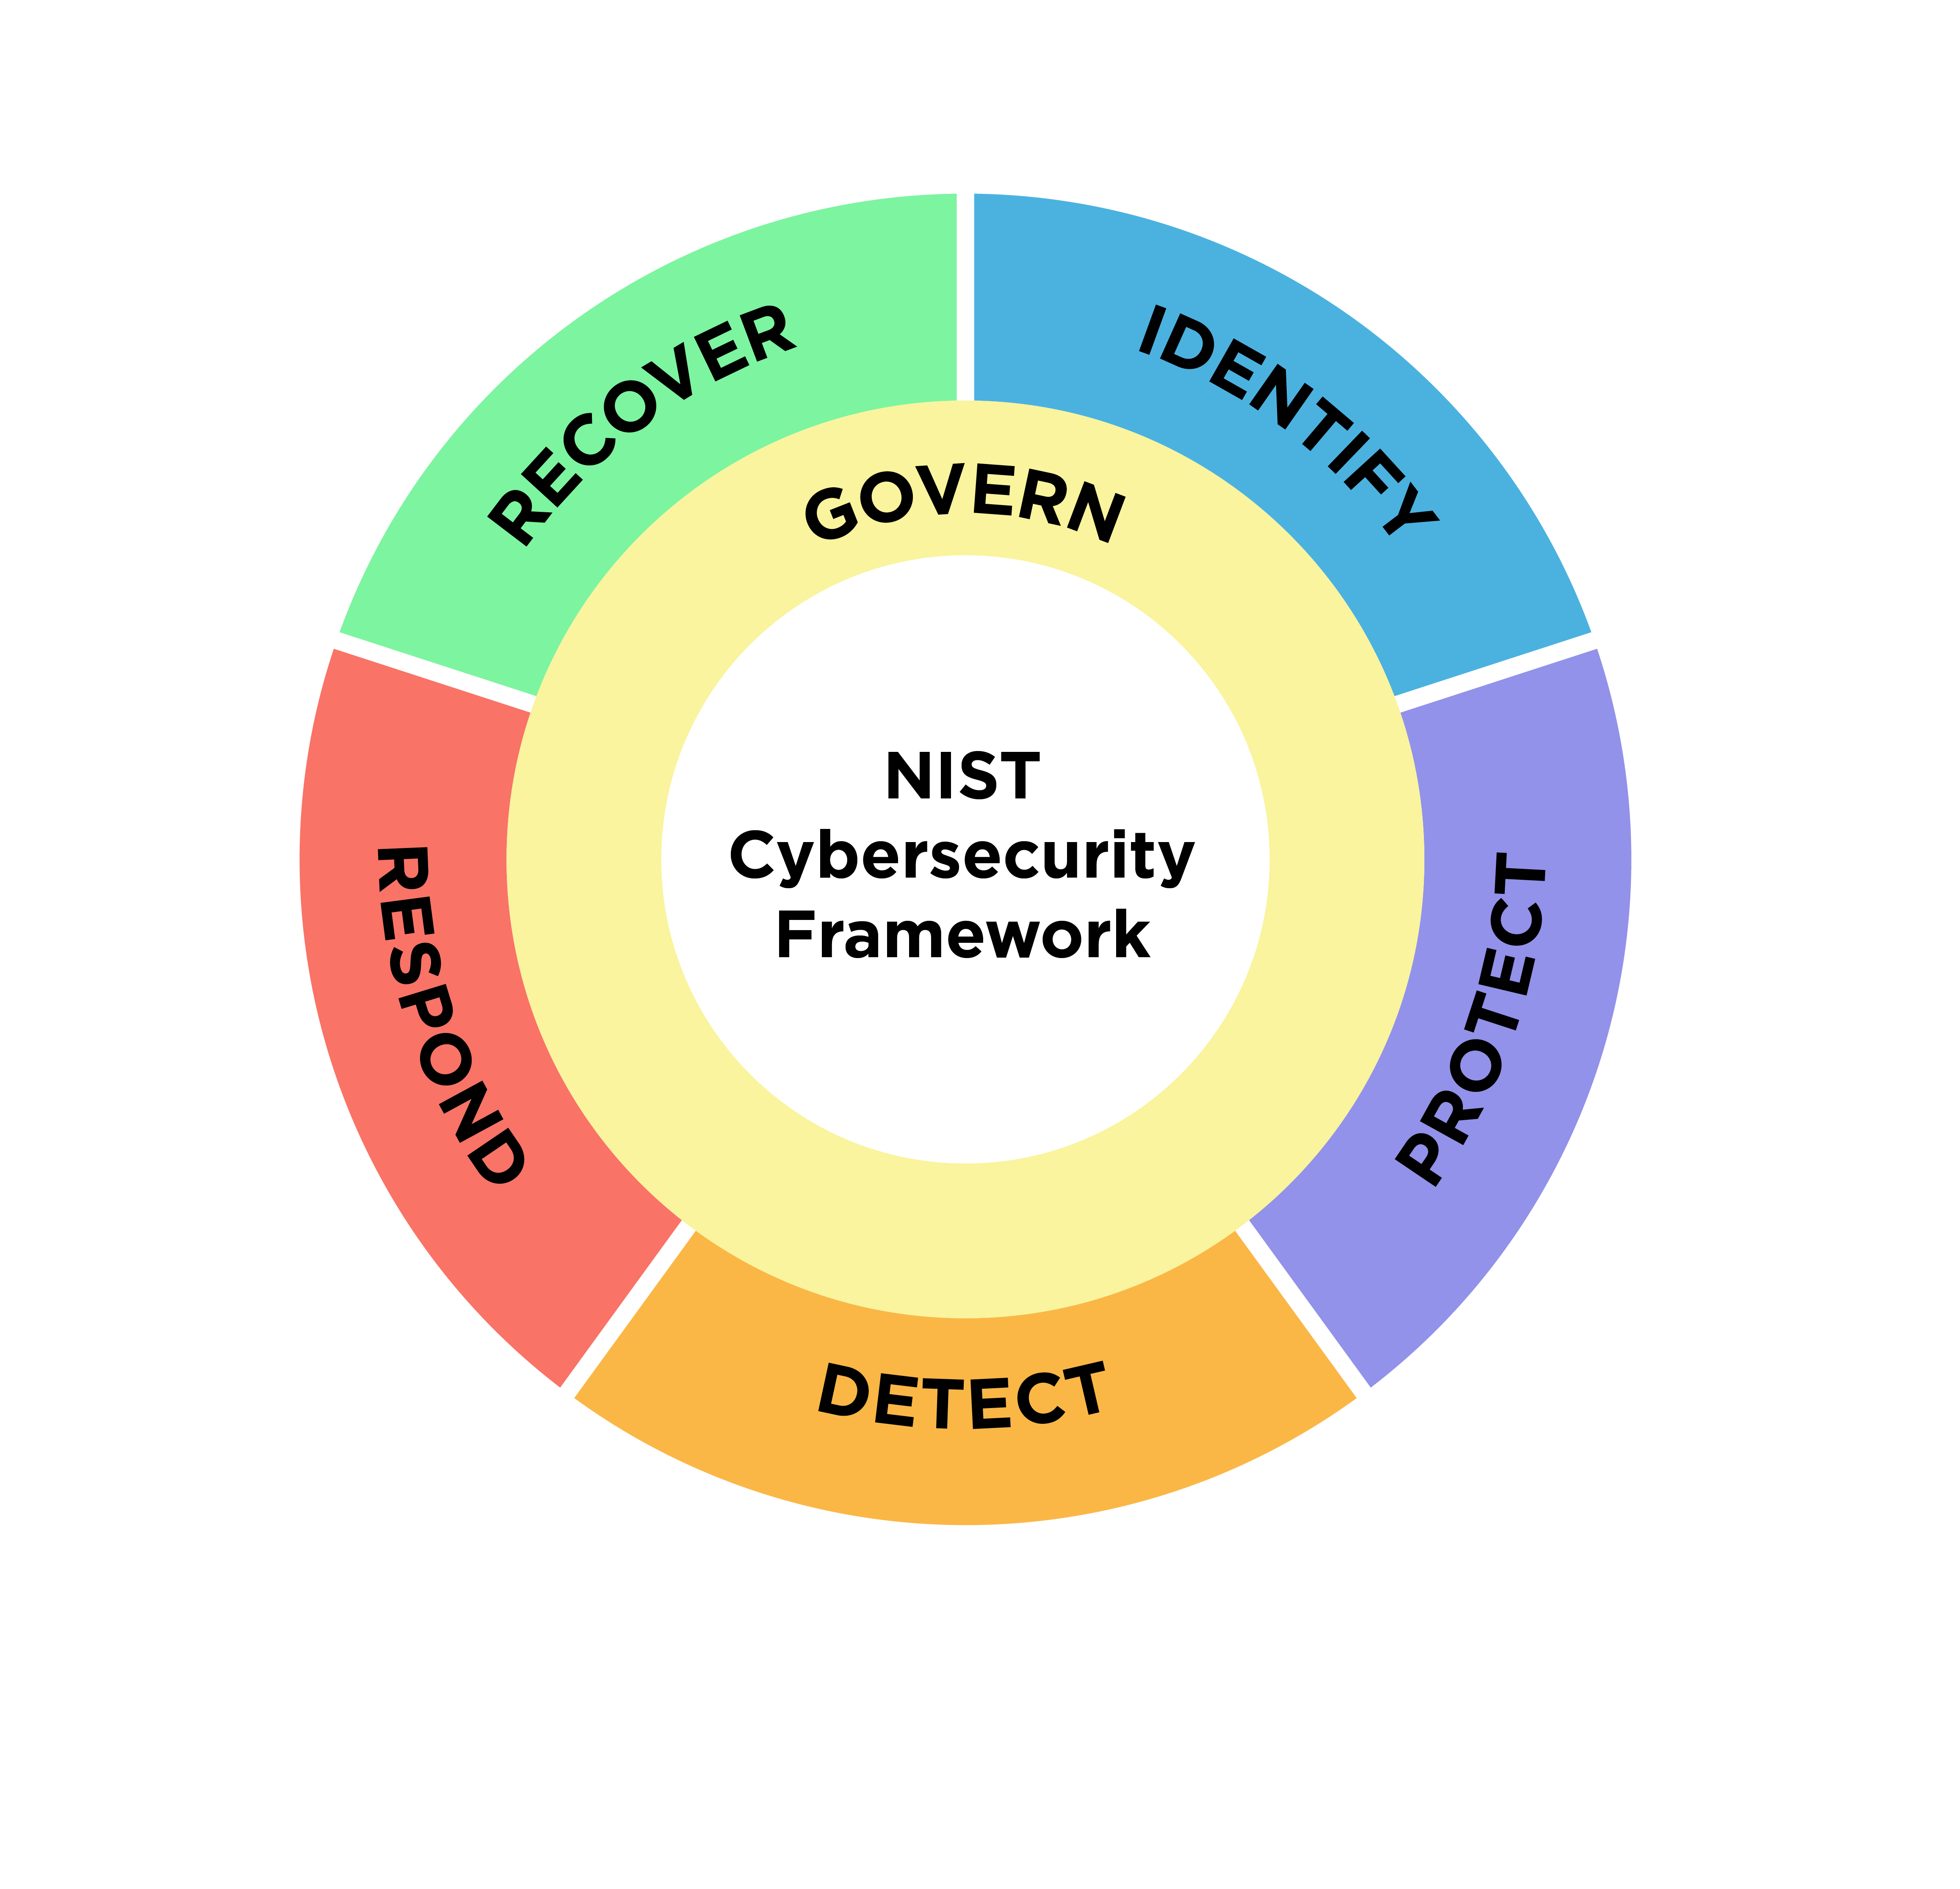
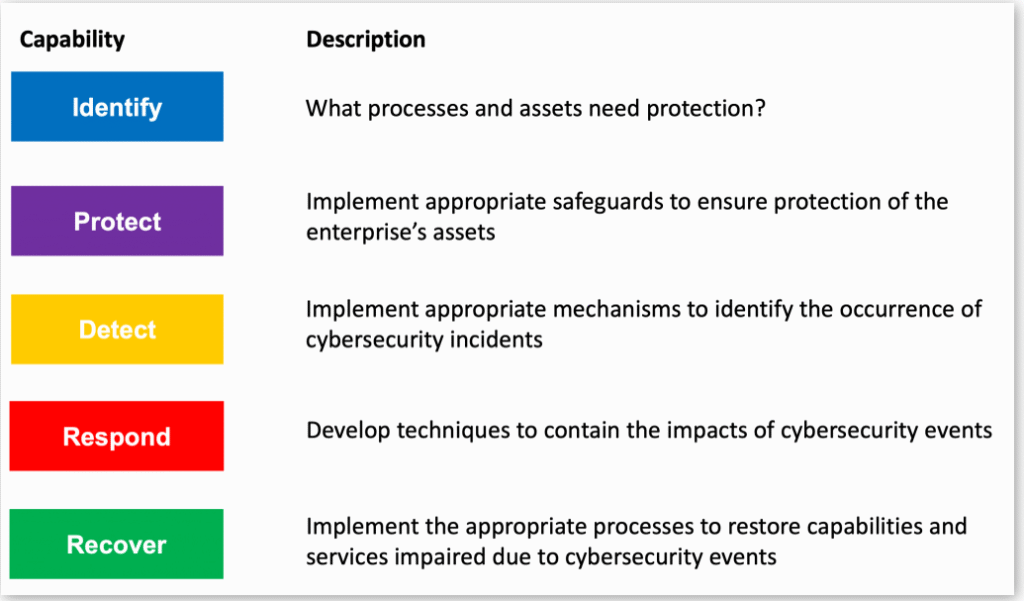
At its core, the Nist Vulnerability Management Policy framework from NIST SP 800-137 covers three main phases: vulnerability identification, risk estimation, and vulnerability response. The model was designed to be iterative, not linear, which means your process should loop back on itself continuously rather than following a one-and-done checklist approach. Most organizations treat it as a checklist, which is exactly why it fails. Here's what the framework actually requires from you. Vulnerability identification involves continuous scanning using both authenticated and unauthenticated methods, complemented by threat intelligence feeds and manual disclosure channels. This isn't just about running Nessus or Qualys and calling it a day. You need to understand what tools are actually detecting what, and more importantly, what they're missing. Patch management falls under the response phase, but configuration review, code scanning, and penetration testing results all feed back into identification.
Risk estimation is where most programs stall. NIST expects you to weigh exploitability, impact, and compensating controls, not just grab a CVSS score and move on. A CVSS of 9.8 on an internal service that's air-gapped and patched through a different mechanism might genuinely be lower priority than a 6.5 on an exposed internet-facing system with known exploit tooling in the wild. I've seen teams burn through remediation budgets chasing perfect scores while real exposure went unaddressed because the numbers looked smaller on paper. Vulnerability response covers remediation, mitigation, acceptance, and avoidance. Each path needs documented justification, and your risk acceptance decisions should have an expiration date. Indefinite risk acceptance is just deferred negligence with a fancy name.
Get the Full Details
How to actually implement this in a real environment
Start by establishing what you're responsible for. Asset inventory comes first, and I mean a real asset inventory, not the half-dead CMDB entries that haven't been updated since 2022. If you can't find it, you can't scan it, and if you can't scan it, you're flying blind. Run automated discovery alongside manual verification for at least one full cycle. The gap between what your scanners find and what actually exists in production is usually where the expensive surprises hide. Set your scanning cadence based on risk tier, not a one-size-fits-all schedule. Critical internet-facing systems should be scanned weekly at minimum, with daily scans during active threat events. Internal systems might go biweekly or monthly depending on change frequency. Static environments that haven't changed in six months don't need the same attention as a CI/CD pipeline that deploys multiple times a day. Here's where things got interesting for me. I was working with an organization that had roughly 14,000 assets and was scanning everything on the same weekly cadence. The scanner team was drowning in findings, the remediation team couldn't prioritize, and senior management kept asking why we still had critical vulnerabilities open past policy deadlines. The problem wasn't the scanning, it was the triage process.
We switched to a contextual prioritization model instead of raw CVSS ranking. We pulled exploit status from CISA's known exploited vulnerabilities catalog, cross-referenced asset criticality from business unit owners, checked whether compensating controls like WAF rules or network segmentation were already in place, and factored in patch availability from vendor advisories. This cut our actionable findings from around 8,000 per week down to roughly 400, and the remediation team's close rate improved from about 23% to 89% within two quarters. The vulnerability count didn't decrease because of better scanning, it decreased because we stopped wasting time on issues that didn't actually matter. The response phase needs clear SLAs tied to risk tier. Critical vulnerabilities with available patches and active exploitation in the wild should get 72-hour response windows. High severity without known exploitation might get 14 days. Medium and low follow standard patch cycles. But here's the thing nobody tells you: SLAs only work if someone owns the remediation. Assign each finding to a specific person or team with a clear deadline, and require acknowledgment within 24 hours. An unacknowledged finding is just noise. Documentation matters more than you'd expect. Every risk acceptance needs a written justification, the name of the person approving it, and a review date. Audit teams will ask for these, and when you can't produce them, the vulnerability becomes an audit finding regardless of how low the actual risk was. I've had clients lose points on assessments not because of the vulnerability itself but because the risk acceptance form was missing a signature or had a blank justification field.
Where the framework breaks down
NIST's model assumes you have dedicated security staff, reliable scanning tools, and organizational authority to enforce remediation timelines. That's not every environment. Small teams wearing multiple hats will struggle to maintain continuous identification without burning out. The framework doesn't account well for constrained operations where IT and security are the same three people. Another limitation is the heavy reliance on accurate asset data. If your network architecture changes frequently and your asset tracking can't keep up, your vulnerability management program will consistently miss newly provisioned systems. I once found a development server running an unpatched version of OpenSSL that had been provisioned three months prior and never scanned because it lived outside the normal IP allocation ranges. The scanning tool had a blanket exclusion for that subnet that nobody remembered adding. The framework also treats patch management as straightforward, but zero-day situations don't wait for patch availability. When Log4j hit, the NIST model's response phase hit a wall because the standard remediation path simply didn't exist yet. Organizations that had implemented workarounds, compensating controls, and network segmentation strategies fared significantly better than those waiting for vendor patches. This is a scenario the framework acknowledges in theory but doesn't prepare you for practically.

If your organization is small or resource-constrained, consider supplementing the NIST framework with a simpler approach like the Cybersecurity and Infrastructure Security Agency's CIS Critical Security Controls, particularly Control 4 and Control 11. These are less prescriptive and more action-oriented, which can be easier to operationalize with limited staff. Some teams also pair NIST guidance with vendor-managed detection and response services to fill the continuous monitoring gap that manual processes struggle to maintain.
Practical steps to get started
Audit your current asset inventory and reconcile it with what your scanning tools actually see. This alone will surface gaps that most organizations overlook for months. Then tier your assets by business criticality rather than treating everything equally. You don't need perfection here, just enough structure to make prioritization decisions defensible. Integrate threat intelligence into your triage process early, not as an afterthought. CISA's known exploited vulnerabilities catalog updates regularly and provides a straightforward way to separate theoretical risk from active threat. A vulnerability with a known PoC exploit and active deployment in the wild deserves immediate attention regardless of its base CVSS score. Establish a formal risk acceptance process with expiration dates. I'd suggest 90 days as a default review period for any accepted risk. This forces regular reassessment and prevents findings from accumulating indefinitely in a dashboard somewhere. Set up automated reminders so nothing falls through the cracks.
Train your asset owners, not just your security team. Vulnerability management fails when security is the only group that cares about the results. If the person responsible for a server doesn't understand why a particular finding matters or what their response timeline is, the finding will sit open until someone notices during an audit. Make ownership clear and communicate expectations in plain language. The NIST Vulnerability Management Policy framework gives you a solid structure to build on, but it's not a turnkey solution. It requires adaptation to your environment, honest assessment of your resources, and a willingness to prioritize based on actual risk rather than compliance checkbox mentality. The organizations that get the most value out of it are the ones that treat the framework as a guide rather than a gospel and adjust it to match their reality.