Setting Up an NLU Pipeline That Actually Works
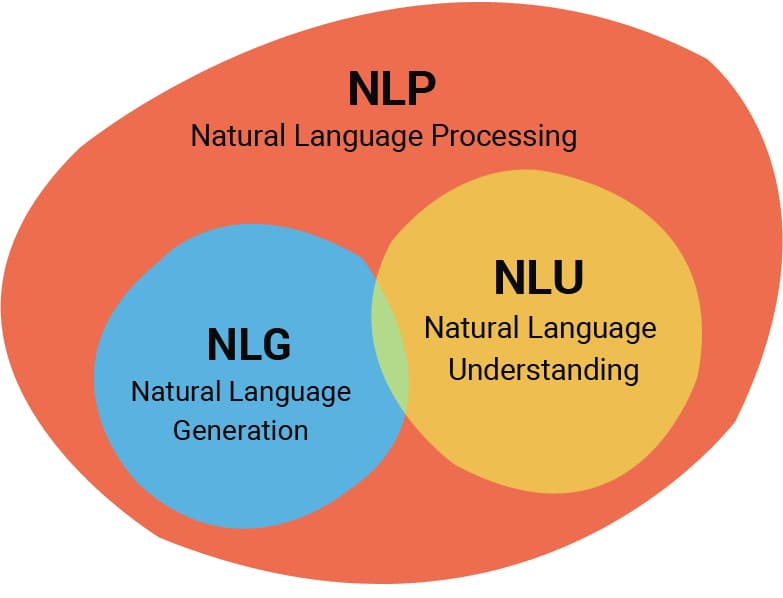
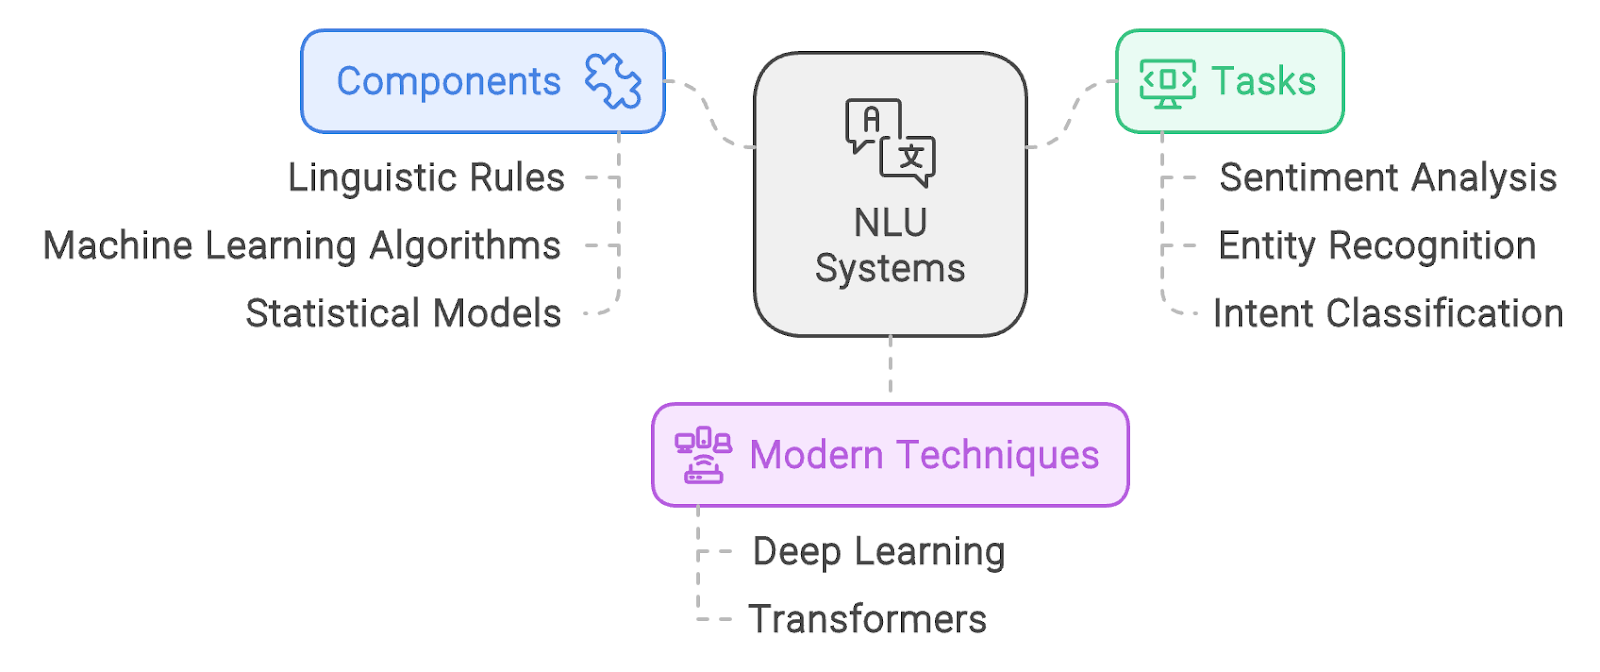
Nlu Natural Language Understanding is one of those terms that got stretched so thin across the industry that nobody seems to agree on where it ends and machine learning begins. You hear it in vendor decks, job postings, and product roadmaps, usually attached to something that just does regex and a decision tree. Here's what the actual pipeline looks like when you're building it from scratch instead of buying it pre-bundled. Start with intent classification. This is the layer that decides what the user is trying to do. If you're building a support bot, intents might be things like "check order status," "request refund," or "talk to a human." You collect labeled utterances for each intent and train a classifier. The boring part: you need at least 50-100 examples per intent minimum if you're using a traditional model like fastText or a small fine-tuned transformer. A few dozen won't cut it and you'll end up with garbage confusion matrices that look fine on paper but fail in production. Then comes entity extraction, also called named entity recognition. This is where you pull structured data out of the raw text. Dates, order numbers, product names, email addresses. Standard approaches use BIO tagging with a CRF layer on top of word embeddings, or you can go straight to a spaCy NER pipeline or a fine-tuned BERT model depending on your latency requirements. I've seen teams waste weeks trying to get a custom NER model to beat spaCy's out-of-the-box model. It rarely happens unless you have domain-specific entities that aren't in any pretrained corpus.
The slot filling layer sits between intent and entity. It maps extracted entities to the variables your action handlers expect. This is the part most people underestimate. It sounds trivial until you get a user saying "I want the order from last Tuesday" and your system has no way to resolve relative dates without pulling in a date normalization library like dateparser or a small lookup table. Finally, dialogue state tracking keeps score across turns. The user doesn't say everything in one utterance. They'll mention an intent, come back later with an entity, then modify something three messages in. A simple finite state machine handles basic flows. Anything more complex needs something like a database-backed state store or a lightweight reinforcement learning agent if you're doing open-domain conversations.
What Nobody Tells You About Training Data
The biggest bottleneck isn't the model architecture. It's the data. Specifically, it's the fact that your training distribution will never match your production distribution. I spent three months debugging an intent classifier that scored 94% accuracy on test data and then crashed in production because real users said things like "uh yeah no wait I mean not that one the other thing that was blue" and your model had never seen a single example of hedging language. The workaround I ended up using was active learning with a human-in-the-loop review queue. You run your model on incoming traffic, flag low-confidence predictions, and route those to a human annotator. Over time your dataset grows with actual production examples instead of synthetic test data. I used Label Studio for annotation and a simple Flask backend to serve predictions, then looped the reclassified examples back into training every two weeks. This cut my false positive rate by about 60% over six weeks. The whole setup took maybe two days to configure and runs for free on a t3.micro if you're doing modest traffic.
Get the Full Details
Counter-intuitive things that actually matter
More training data past a certain point hurts your intent classifier. I know that sounds wrong. But when you start adding noise or borderline cases that don't clearly belong to any intent, your model starts hedging and becomes less decisive. I saw a team go from 93% to 89% accuracy after they blindly augmented their dataset with 10x more examples because they didn't curate the new data. The fix was manual review and trimming ambiguous samples, not collecting more. Another thing: regularization matters more than model complexity for NLU. A simpler model with proper dropout and label smoothing will often beat a massive transformer that's overfitting to your training set. I had a project where switching from a fine-tuned DistilBERT to a properly regularized fastText classifier actually improved out-of-distribution generalization because the simpler model was forced to learn more robust features instead of memorizing surface-level patterns.
The Part Where Everything Falls Apart
Multi-language NLU is a minefield. Word embeddings trained on English data don't transfer cleanly to languages with different morphological structures. Agglutinative languages like Turkish or Finnish basically break most off-the-shelf tokenizers because words that look like one token in English are five tokens in those languages. If you need multilingual support, use XLM-RoBERTa or mBERT and validate tokenization per language. Don't assume your English pipeline works for Spanish without testing it first. Sarcasm and indirect speech remain genuinely unsolved problems. Your NLU system will confidently classify "Oh great another broken widget" as positive sentiment with high confidence. There's no clean fix. You can add sentiment analysis as a secondary signal, but even that won't catch context-dependent irony. The practical workaround is to route ambiguous or emotionally charged utterances to a human agent rather than trying to model pragmatics in your classification layer. Context window limitations are another hard ceiling. Most NLU systems process each utterance independently unless you explicitly build state tracking into the pipeline. That means if a user says "cancel it" as a follow-up to a previous message about an order, your model sees only "cancel it" and may or may not infer the right referent. Adding a simple context buffer that concatenates the last two to three turns before classification helped my team, but it doesn't scale to long multi-turn conversations without proper dialogue management.
Tools I actually use
For prototyping, Rasa is the most straightforward open-source framework. It handles intent classification, entity extraction, and dialogue management in one package. The learning curve is moderate but the documentation is thorough. Training a basic pipeline takes about an hour if you have your data ready. Production deployment adds complexity though, especially around scaling and monitoring. For entity extraction specifically, I recommend spaCy with its prebuilt transformer pipelines. The speed is good enough for most real-time applications and the accuracy is competitive. Fine-tuning a spaCy NER model on your domain data typically takes a few hours on a single GPU and can improve entity F1 scores by 10-15% over the default model depending on how specialized your entities are. If you need to do this at scale, Hugging Face transformers with a dedicated serving layer like TorchServe or vLLM is the way to go. vLLa specifically gives you high throughput inference at reasonable latency, which matters when you're processing thousands of requests per second. The tradeoff is operational complexity and GPU costs that can add up fast.
When NLU Is the Wrong Tool
Keyword matching and rule-based systems still solve a lot of problems that NLU attempts to solve unnecessarily. If you're building a system with a closed domain and well-defined intents, a carefully constructed decision tree with regex fallbacks can be more interpretable, faster, and cheaper to maintain than a neural classifier. I've replaced NLU pipelines with rule-based systems in production and reduced latency from 200ms to under 20ms while actually improving precision because the rules were explicit about edge cases the model kept misclassifying. Search-heavy use cases are another area where NLU adds complexity without much benefit. BM25-based search with some query rewriting is often sufficient and infinitely easier to debug than a black-box intent classifier that gives you no visibility into why it made a particular prediction. The bottom line is that NLU is a tool, not a solution. It fits certain problems well and fails catastrophically in others. Know your constraints before you build. Start simple, measure everything, and be willing to fall back to rules when the model starts working against you instead of for you.