How Normal Bell Curve Percentages Actually Work in Practice
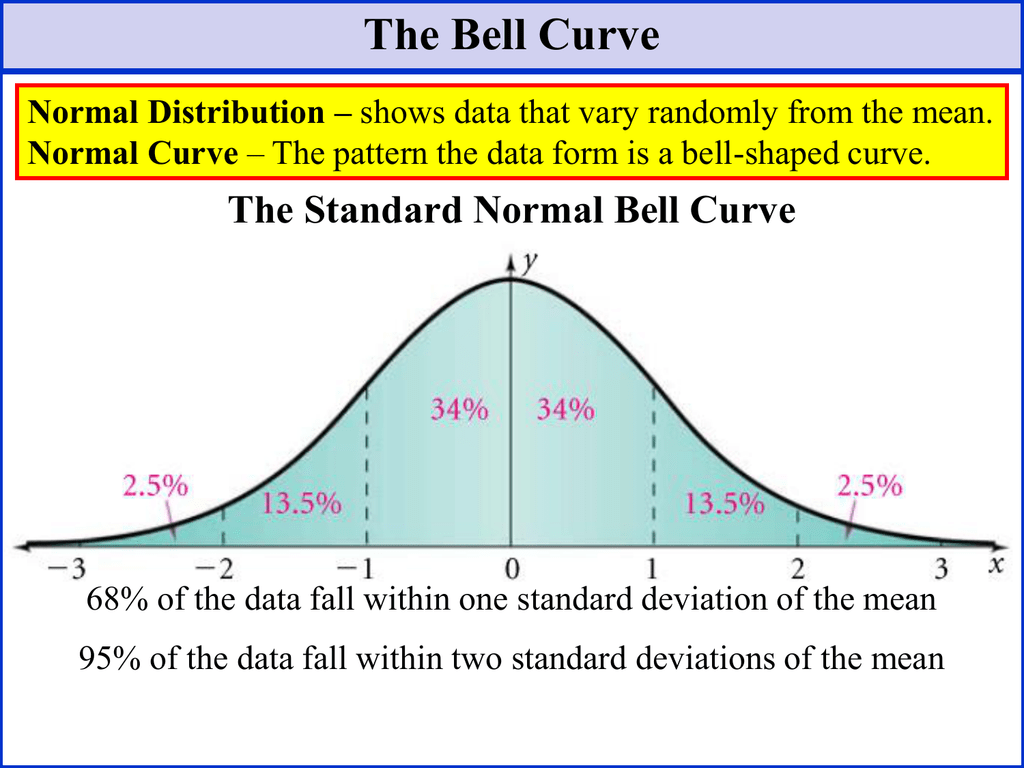
I still remember running a regression on a dataset from a mid-size manufacturing client where the response variable had a slight right skew. The quality engineer insisted on using normal distribution tables because it was what they'd been taught. The predictions were off by enough to matter — we were talking about rejecting good parts and keeping bad ones. The workaround was straightforward: a Box-Cox transformation before applying the standard deviation-based thresholds, which brought the skew down and made the Z-score method viable again. But the real lesson was that the bell curve is a tool, not a rule. The Normal Bell Curve Percentages you are probably looking for come from the empirical rule, also called the 68-95-99.7 rule. About 68 percent of the data falls within one standard deviation of the mean. Roughly 95 percent falls within two standard deviations. The remaining 99.7 percent sits within three standard deviations. That leaves about 0.3 percent outside that range, split nearly evenly between the two tails. People often assume this means anything beyond three standard deviations is impossible, which is wrong. It just means it is very unlikely under a normal distribution. A single outlier in a dataset of a thousand observations is not unusual at all if the underlying process has heavy tails or occasional step changes.
Normal Bell Curve Percentages and Their Real-World Application
To use these percentages, you need a mean and a standard deviation. You calculate the mean by adding all observations and dividing by the count. The standard deviation is the square root of the average squared deviation from that mean. Once you have both, you convert any raw value into a Z-score by subtracting the mean and dividing by the standard deviation. A Z-score of 1.0 means the value is one standard deviation above the mean. From there, you look up the cumulative probability in a standard normal table or use any statistical software. Most people skip the table entirely now and use Excel's NORM.S.DIST function or Python's scipy.stats.norm.cdf. The output tells you the probability of observing a value less than or equal to your Z-score. Here is a practical scenario. You manage a warehouse and your order processing times average 4.2 hours with a standard deviation of 0.8 hours. You want to know what percentage of orders take longer than 5.8 hours. The Z-score for 5.8 is 2.0. The cumulative probability up to Z equals 2.0 is about 0.9772. Subtract that from 1 and you get roughly 2.28 percent. So about 2 percent of your orders will take longer than 5.8 hours. This is useful for staffing and SLA planning, but only if your processing times are actually normally distributed. They rarely are. Order processing times usually have a lower bound at zero and a long right tail because some orders hit edge cases like missing paperwork or supplier delays. In those situations, the bell curve overestimates the likelihood of extreme fast completions and underestimates the tail risk of extreme delays. There are a few things most tutorials do not tell you. First, the normal distribution is fully defined by its mean and standard deviation. If those two numbers are correct and the data truly follows a normal pattern, you know everything about the distribution. That sounds powerful, but it means you are entirely dependent on those two statistics being accurate representations. A single data entry error can shift the mean and inflate the standard deviation, which then distorts every percentage you compute downstream. Second, the empirical rule percentages are approximations. The exact values for a standard normal distribution are approximately 68.27 percent within one standard deviation, 95.45 percent within two, and 99.73 percent within three. The rounded numbers are fine for quick mental math, but if you are writing a technical report or a specification document, use the precise values. It does not matter much for rough estimates. It matters when someone else is auditing your work.
A more nuanced issue is that many people confuse the population standard deviation with the sample standard deviation. The population formula divides by N. The sample formula divides by N minus one. When you are working with sample data, which is almost always the case, you should use the sample standard deviation because it corrects for bias. The difference is negligible with large samples but noticeable with small ones. If you have twenty observations and use the population formula instead of the sample formula, your standard deviation will be slightly too small, which means your Z-scores will be slightly too large, which means your tail probabilities will be slightly too small. It is a compounding error that is easy to miss. I also ran into a case where someone tried to apply Normal Bell Curve Percentages to a binary outcome. They were analyzing pass-fail rates on a certification exam and wanted to model the scores as a continuous normal distribution. The scores were clustered near the extremes because the exam was either too easy or too hard for different cohorts. The resulting curve was clearly bimodal, not normal. Forcing a normal approximation onto bimodal data produced nonsense confidence intervals and misleading percentile cutoffs. The better approach was to use a beta distribution, which handles data bounded between zero and one, or simply to work with the raw proportions and a binomial model. The normal approximation to the binomial works when the sample size is large and the probability is not too close to zero or one, but that condition was violated here. Another limitation worth stating bluntly is that the bell curve is symmetric. Real data is often skewed or has heavier tails than a normal distribution predicts. Financial returns, for example, are famous for fat tails. A model based on normal percentages would vastly underestimate the probability of extreme market moves. This is not a theoretical concern. The 2008 financial crisis was partly fueled by risk models that assumed normality while ignoring the possibility of correlated tail events. If you are working with data that has skewness or kurtosis outside the range of plus or minus one, the normal approximation is likely inadequate. You should check a Q-Q plot or run a Shapiro-Wilk test before committing to a normal-based analysis. These are cheap diagnostics that save you from costly mistakes later.
Get the Full Details

When the normal distribution is the right choice, the workflow is simple. Collect your data. Verify it looks roughly normal with a histogram and a Q-Q plot. Compute the mean and sample standard deviation. Convert your values of interest into Z-scores. Look up the corresponding probabilities. If you need the probability between two values, calculate each Z-score, find their cumulative probabilities, and subtract. The result is the area under the curve between those points, which is the probability of observing a value in that range. This applies to everything from grading curves in education to tolerance intervals in engineering. The math is the same regardless of the domain. For software implementation, here is the quickest path. In Excel, use NORM.DIST to get the cumulative probability for a given value, mean, and standard deviation. Use NORM.INV to reverse the operation and find the value corresponding to a given percentile. In R, pnorm gives you the cumulative distribution and qnorm gives you the quantile function. In Python, scipy.stats.norm provides cdf and ppf, which are the same functions under different names. If you are building something at scale, these vectorized operations are extremely fast and can handle millions of calculations without breaking a sweat. The bottleneck is usually the data cleaning step, not the computation itself. One edge case that catches people regularly is the interpretation of percentiles versus Z-scores. A Z-score of zero corresponds to the 50th percentile, which is the median and the mean in a perfectly normal distribution. A Z-score of positive or negative 1.0 corresponds to the 84.13th and 15.87th percentiles respectively. These numbers are worth memorizing because you will encounter them constantly. A Z-score of 1.645 corresponds to the 95th percentile in a one-tailed test. A Z-score of 1.96 corresponds to the 97.5th percentile, which is the threshold for a two-tailed test at the 5 percent significance level. Confusing one-tailed and two-tailed thresholds is a common error that leads to incorrect conclusions in hypothesis testing and confidence interval construction.
There is also a practical distinction between using the normal distribution for inference and using it for prediction. The percentages tell you about the distribution of the data itself, but they do not account for uncertainty in your estimates of the mean and standard deviation. When your sample size is small, the t-distribution is a better choice because it has fatter tails that reflect the additional uncertainty. As the sample size grows, the t-distribution converges to the normal distribution, so the difference becomes irrelevant. A common rule of thumb is to switch to the normal distribution when your sample exceeds 30, though this is arbitrary and depends on how normal your data already is. If your data is clearly non-normal and your sample is small, no amount of sample size inflation will make the normal approximation valid. In that case, you should use a non-parametric method or a distribution that fits your data better. I have seen teams waste weeks trying to force a normal model onto data that clearly did not fit. The turning point usually comes when someone runs the diagnostic tests and the p-values scream that the null hypothesis of normality should be rejected. At that point, the rational move is to accept that the data is not normal and choose an appropriate alternative. Weibull distributions are common in reliability engineering. Lognormal distributions work well for variables that cannot be negative and have multiplicative growth. Gamma distributions are flexible enough to handle a range of shapes. The normal distribution is not the default answer to every statistical problem, even though introductory courses often present it that way. Understanding when it works and when it fails is the difference between producing useful analysis and producing polished nonsense. The Normal Bell Curve Percentages framework is reliable when the assumptions hold and wasteful when they do not. Calculate your statistics carefully, check your assumptions explicitly, and be ready to move to a different model when the data demands it. The percentages themselves are not complicated. What takes experience is knowing when to trust them and when to walk away.