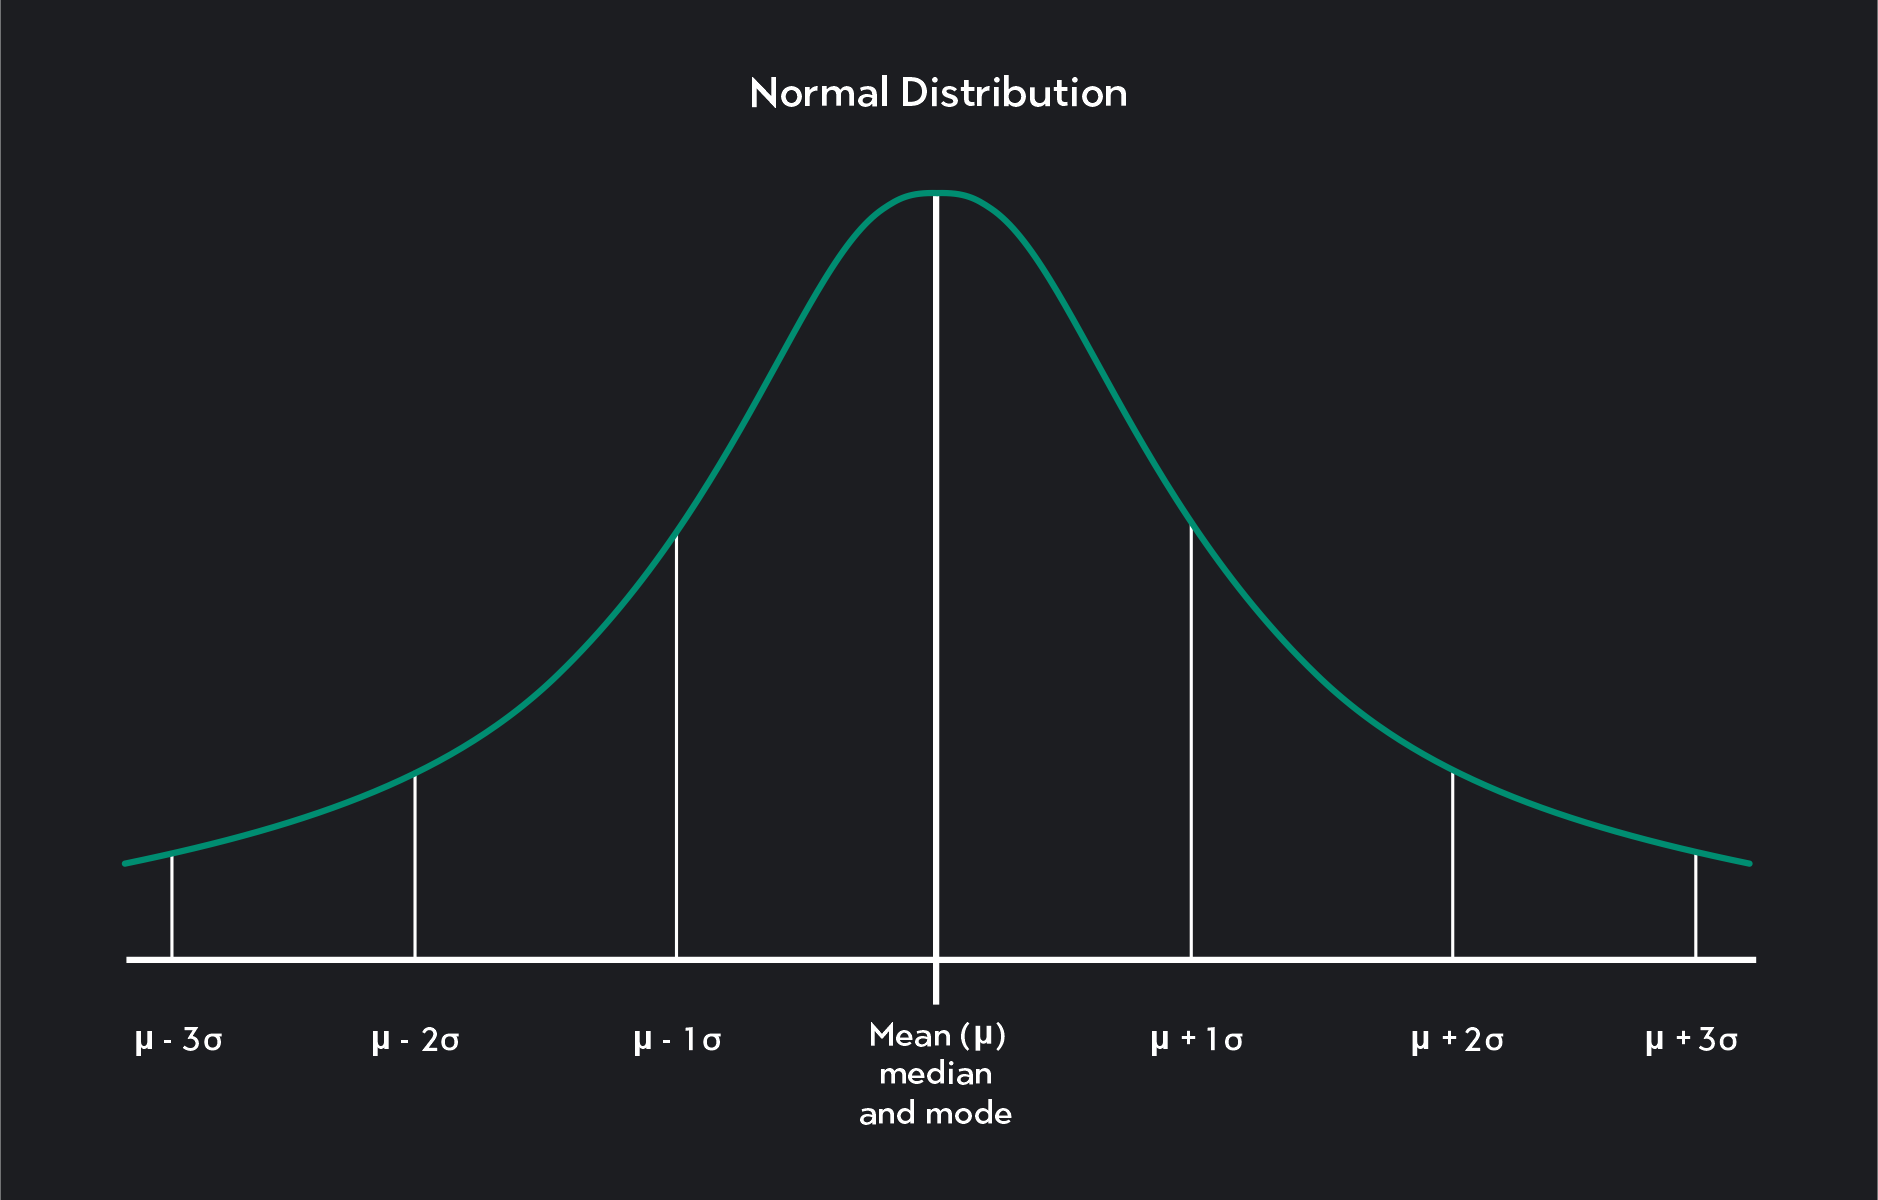
Working with Standard Deviation on a Normal Curve
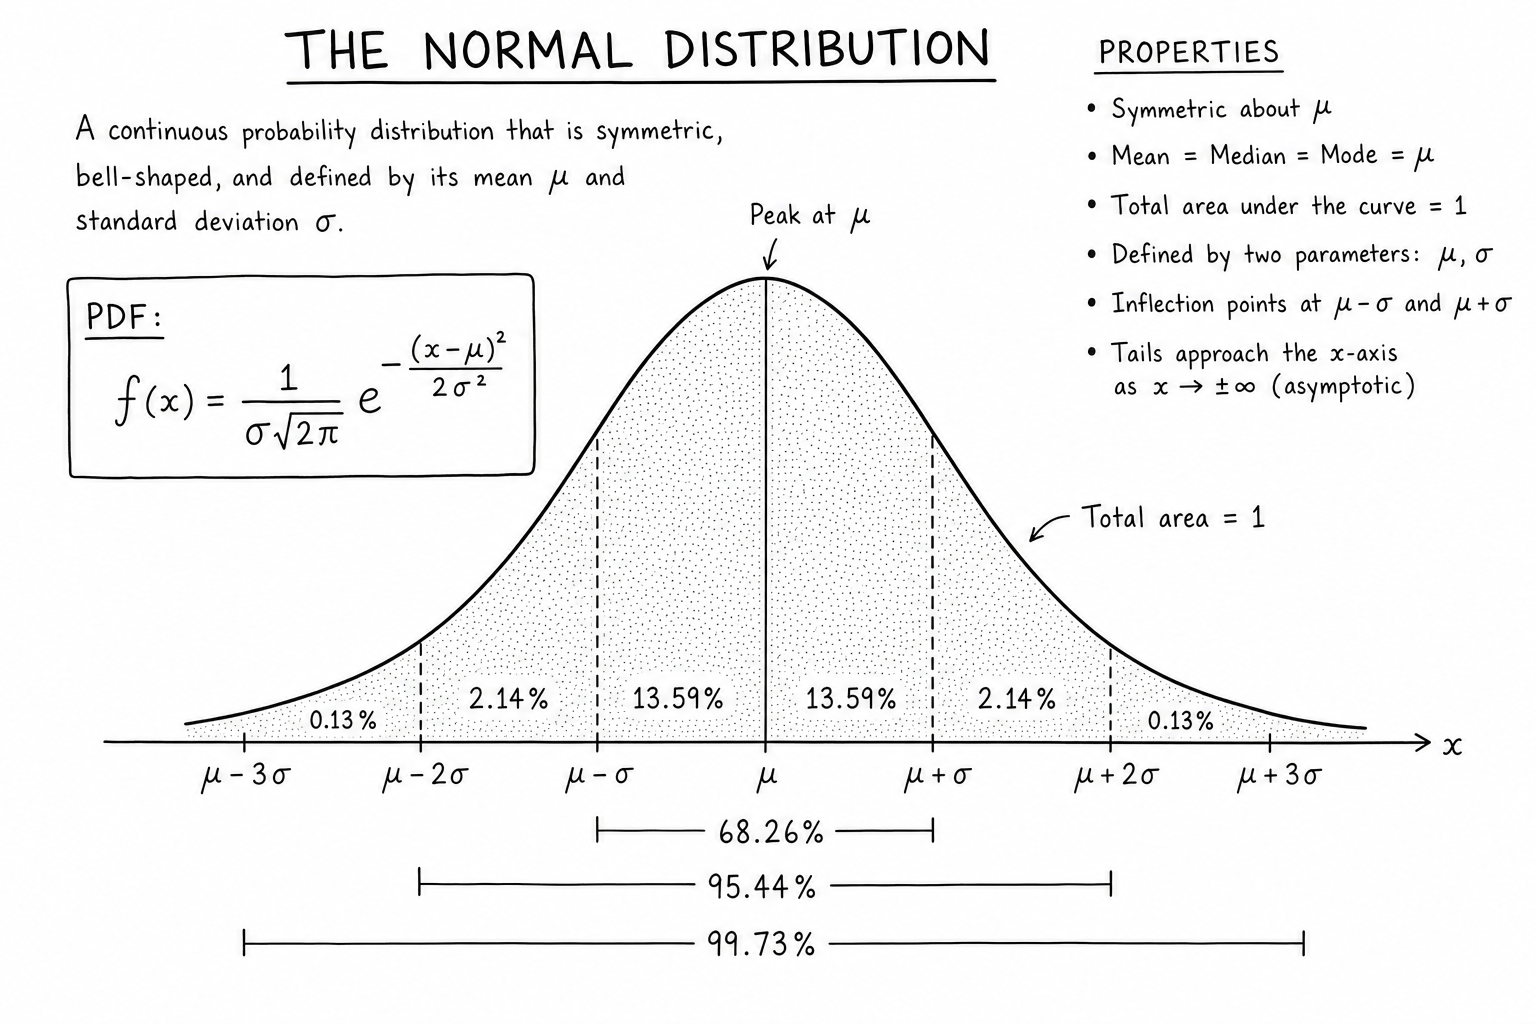
Most people learning statistics hit a wall when they try to apply standard deviation to a normal curve because the textbook examples are too clean. Real data rarely behaves. I'm going to walk through how to actually calculate and interpret this in practice, not just define it. The Normal Curve Standard Deviation measures how spread out your data is around the mean when that data follows a roughly bell-shaped distribution. The formula itself is straightforward: subtract the mean from each data point, square the result, sum all those squares, divide by the number of data points for a population (or by n-1 for a sample), then take the square root. That gives you sigma, or s for a sample. What people miss at first is that the standard deviation only describes spread under the assumption of normality. If your data is skewed, bimodal, or has heavy tails, the standard deviation still calculates fine but becomes almost useless for prediction. You could have a perfectly valid standard deviation and still be making terrible guesses about where your next data point lands.
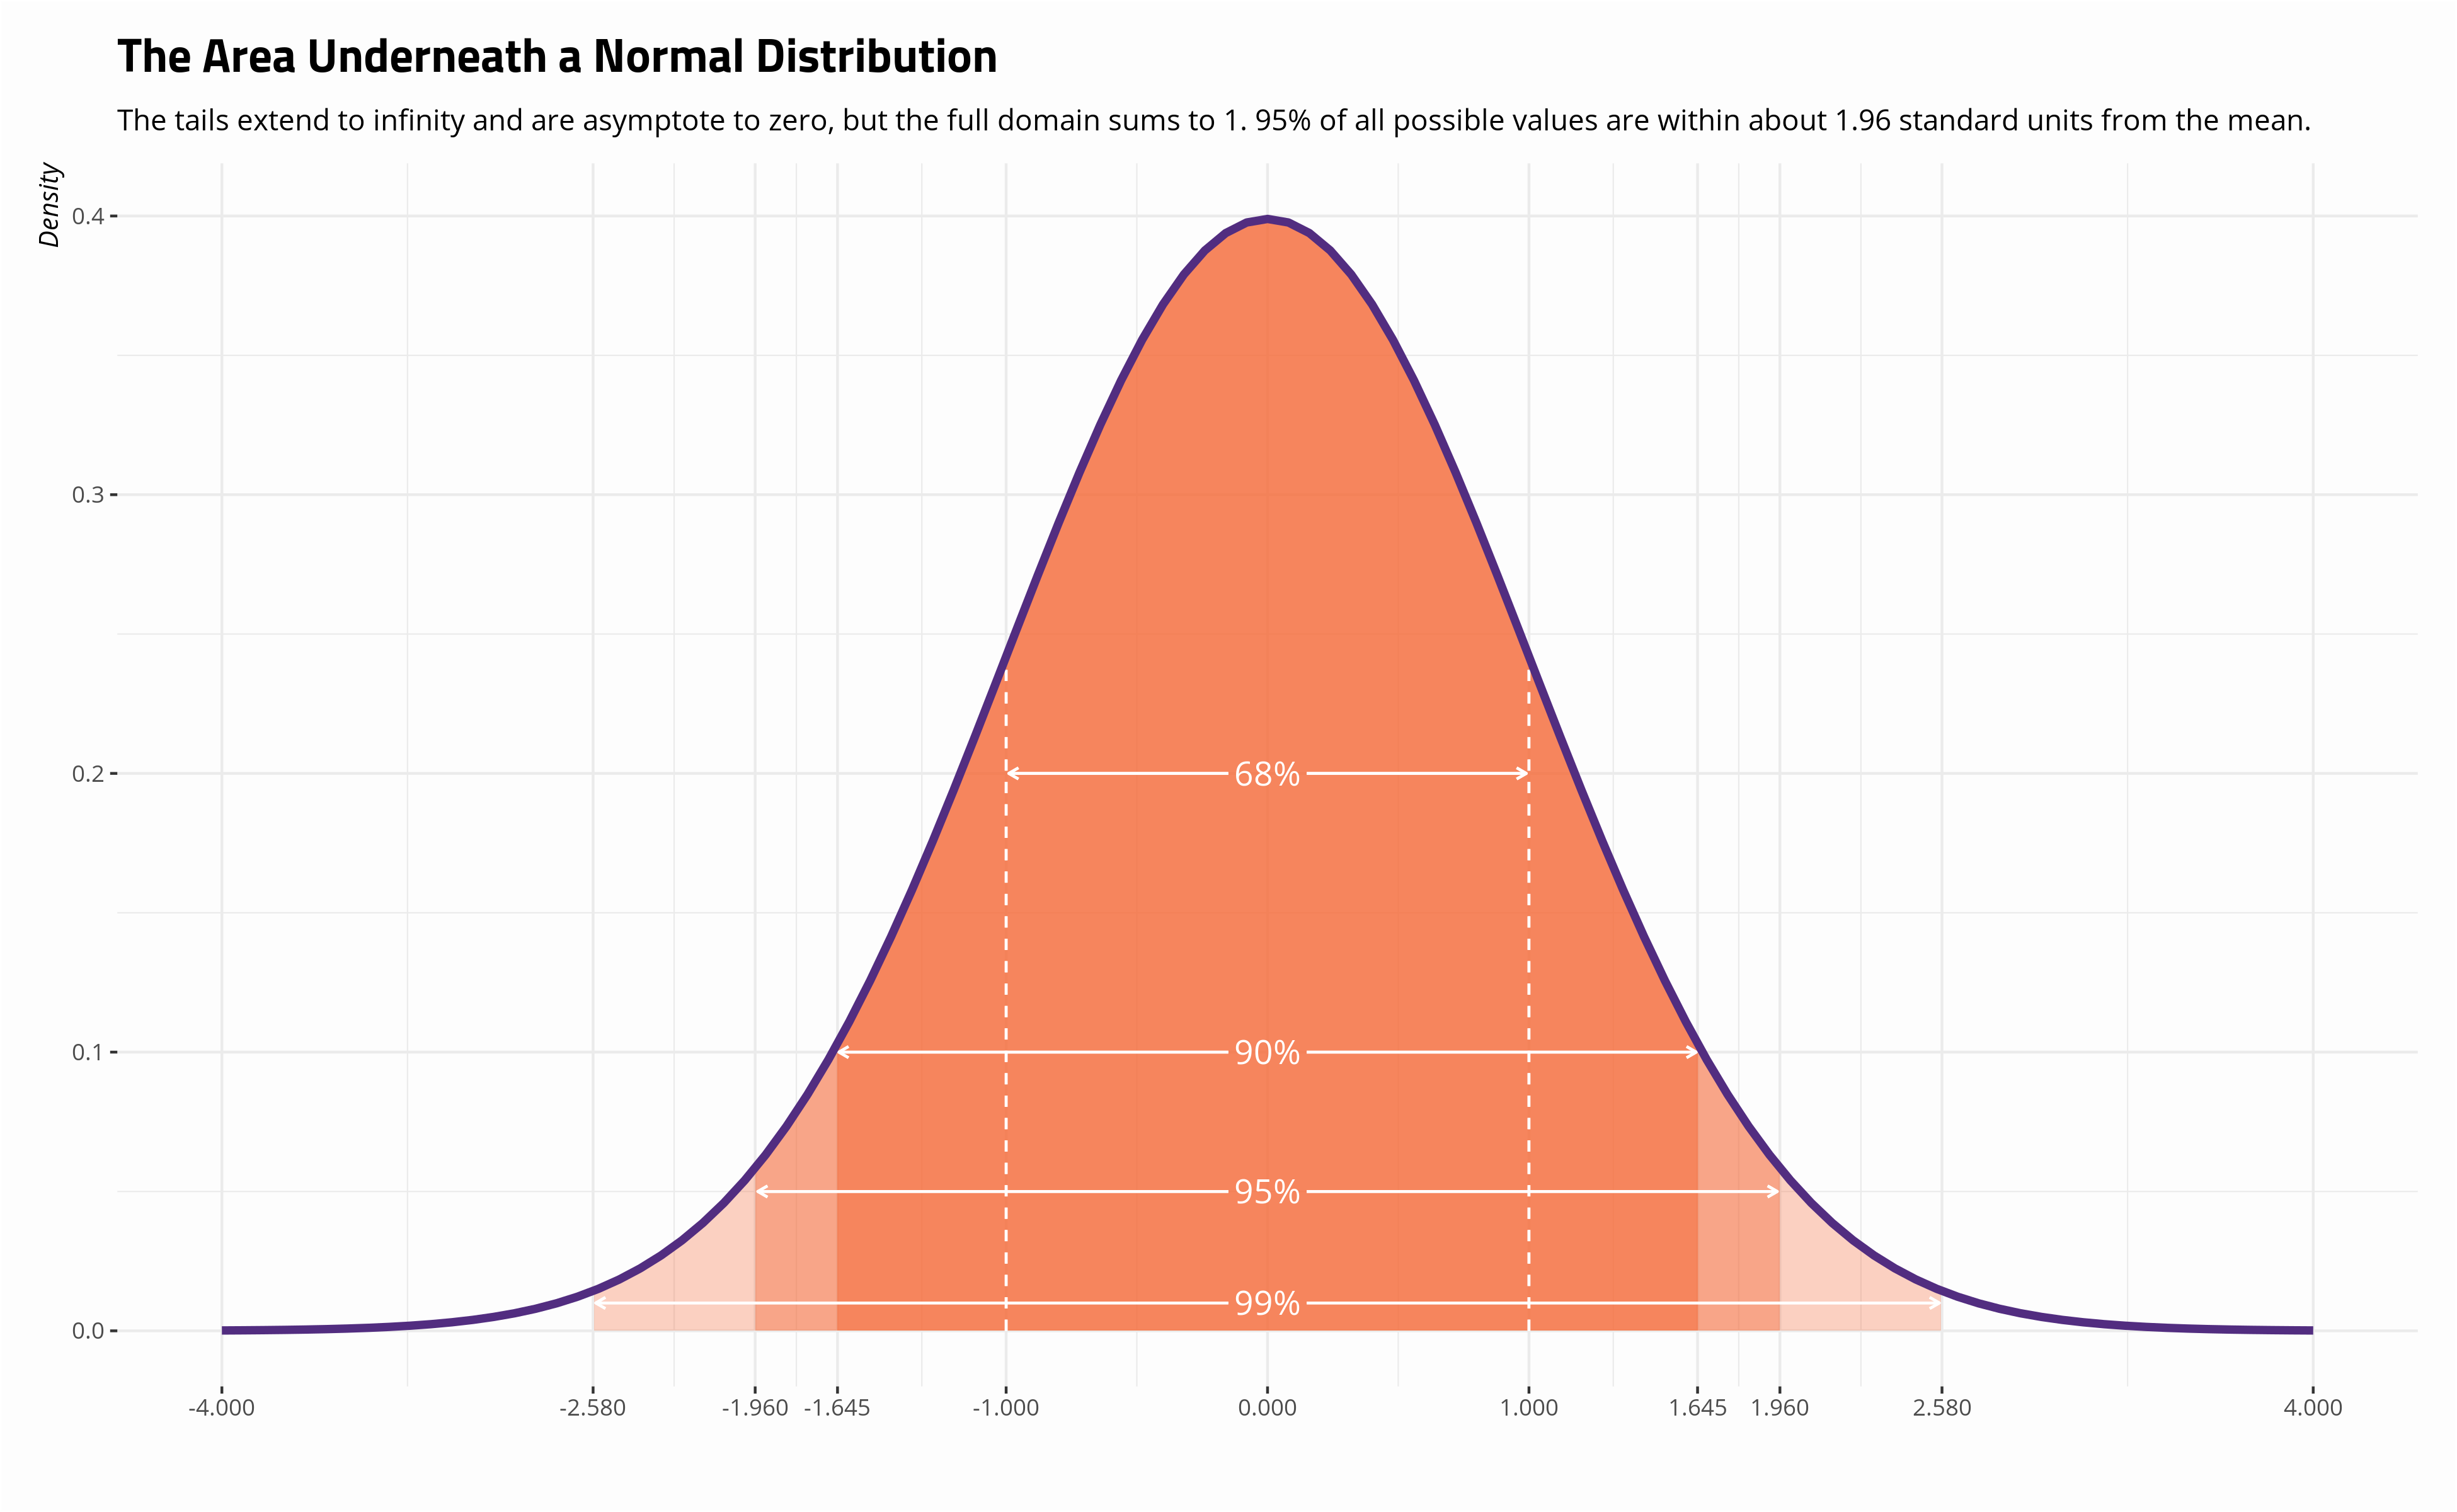
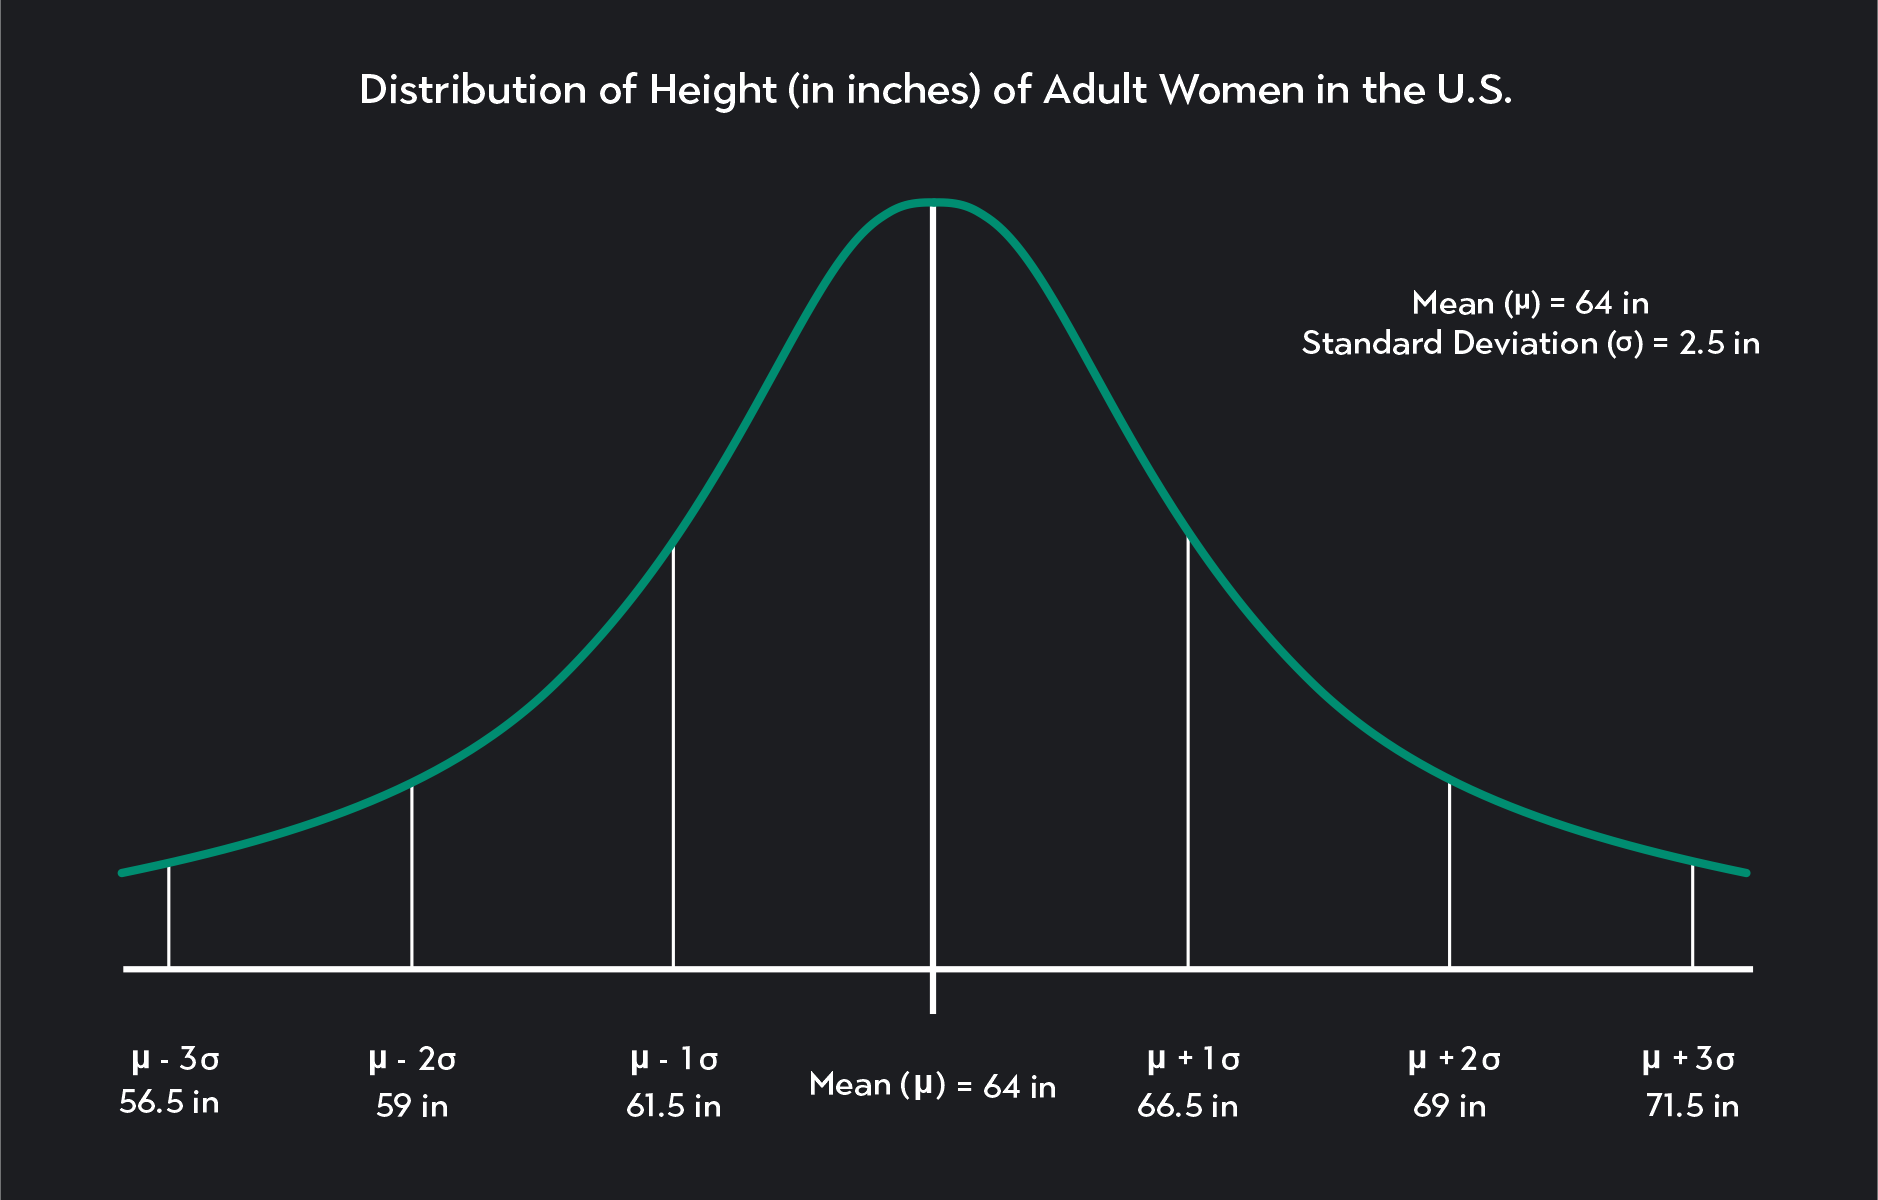
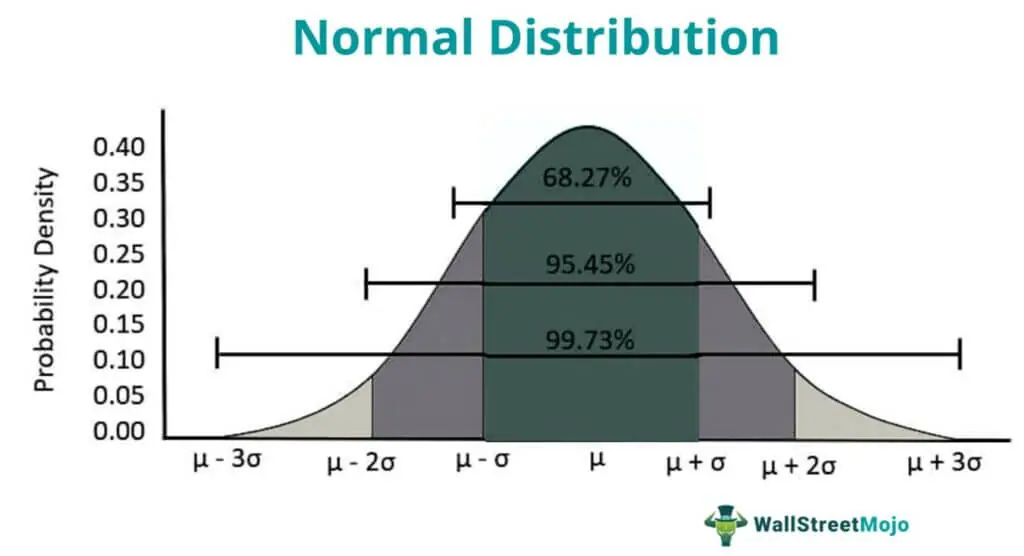
Here's the practical rule that matters more than the formula: in a true normal distribution, about 68% of observations fall within one standard deviation of the mean, 95% within two, and 99.7% within three. This is the empirical rule, also called the 68-95-99.7 rule. It only works cleanly when the distribution is actually normal. I once spent three days debugging a quality control model because someone fed it a heavily right-skewed dataset with a few extreme outliers, and the standard deviation was inflated to the point where the process appeared to be in control when it was clearly not. The fix was switching to a log transformation of the data before calculating sigma, which normalized the distribution and brought the control limits back to something meaningful. When you're working with sample data instead of a full population, always use n-1 in the denominator. This is Bessel's correction, and it produces an unbiased estimator of the population standard deviation. Using n instead of n-1 systematically underestimates the true spread, especially with small samples. With n less than 30, the difference between dividing by n and dividing by n-1 can shift your standard deviation by 5% or more, which is enough to flip a hypothesis test from significant to not significant. Another thing that trips people up is the relationship between standard deviation and the shape of the curve itself. A smaller standard deviation means a taller, narrower bell curve. A larger one means a shorter, wider curve. The total area under the curve is always 1, or 100%, regardless of how wide or narrow it is. This is important because it means you can compare distributions with different standard deviations directly without the area changing the interpretation.
If you need to find the probability that a value falls within a certain range, you convert your raw scores to z-scores using the formula z equals x minus mu divided by sigma. The z-score tells you how many standard deviations a particular value is from the mean. Once you have the z-score, you look it up in a standard normal table or use a calculator. Most people use online calculators now, which is fine, but it's worth knowing that the cumulative distribution function for the standard normal doesn't have a closed-form solution. The tables exist because the integral has to be approximated numerically. One edge case that catches experienced analysts off guard is when you're combining two normal distributions with different standard deviations. Say you have data from two different manufacturing processes, each normally distributed but with different variances. Simply averaging their standard deviations gives you a number that doesn't accurately represent either group. You need to pool the variances first, then take the square root. The pooled variance formula weights each group's variance by its degrees of freedom, which is n-1 for each group. Here's where standard deviation completely fails as a description of spread: when your data contains outliers or follows a distribution with significant skew. In those cases, the interquartile range or median absolute deviation gives you a much more robust picture of variability. I've seen people report standard deviations for income data, which is notoriously right-skewed, and those numbers are nearly meaningless without also reporting the median and the IQR. A standard deviation on income data will be inflated by the high earners and give a false impression of how typical the spread actually is for the majority of the population.
Get the Full Details

Another limitation worth noting: the standard deviation treats all deviations from the mean equally, whether they're above or below. For many practical applications, that's exactly what you want. But if you're working in a field where overestimating and underestimating have very different consequences, like in inventory management or financial risk, you might want to look into semivariance, which only considers deviations in the direction that matters. Semivariance is the standard deviation of either the values above or below the mean, depending on your concern. For anyone doing this work regularly, learning to spot when your data violates the normality assumption saves you from a lot of downstream errors. A quick histogram and a Shapiro-Wilk test will tell you whether your data is close enough to normal for standard deviation-based methods to be reliable. If the test comes back significant, your data is not normally distributed, and you should consider non-parametric alternatives or a transformation before proceeding. The calculation itself takes seconds in any spreadsheet. Excel's STDEV.S function handles the sample standard deviation with Bessel's correction built in. STDEV.P handles the population version. The trick isn't the calculation. It's knowing when the result you're looking at actually tells you something useful and when it's just a number that looks precise but means very little.