Getting the Standard Deviation Right When Your Data Isn't Perfect
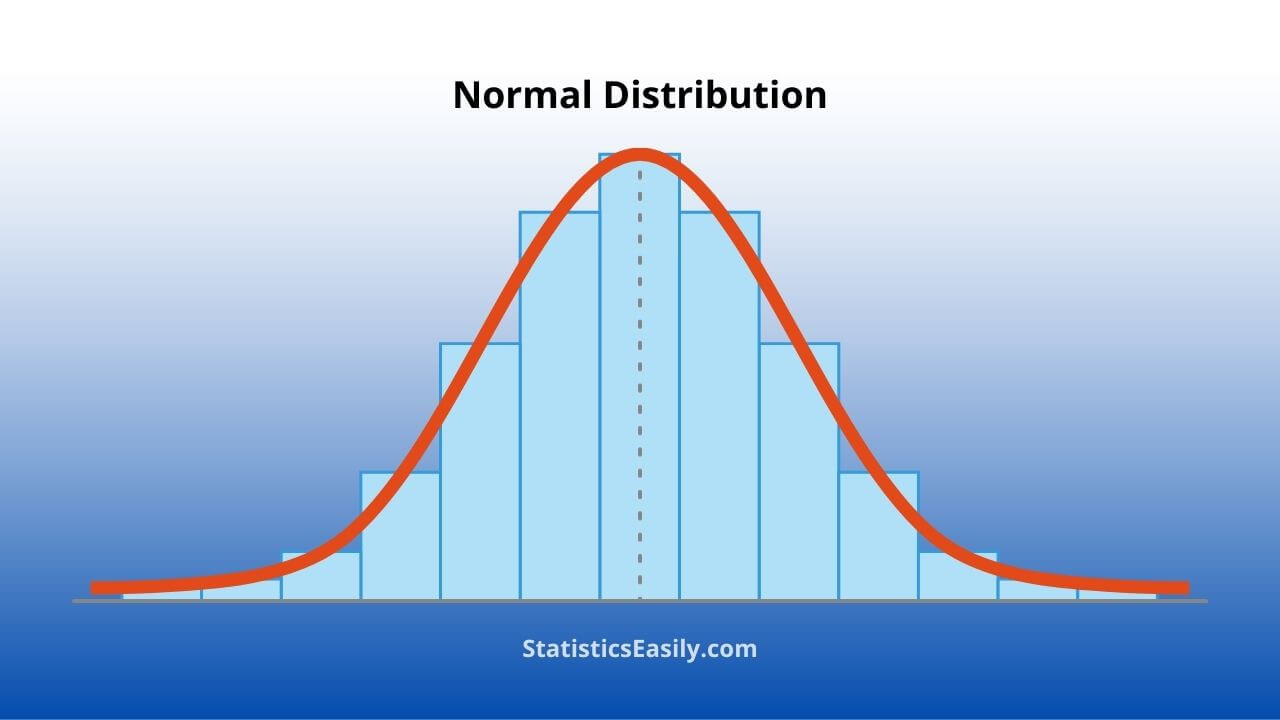
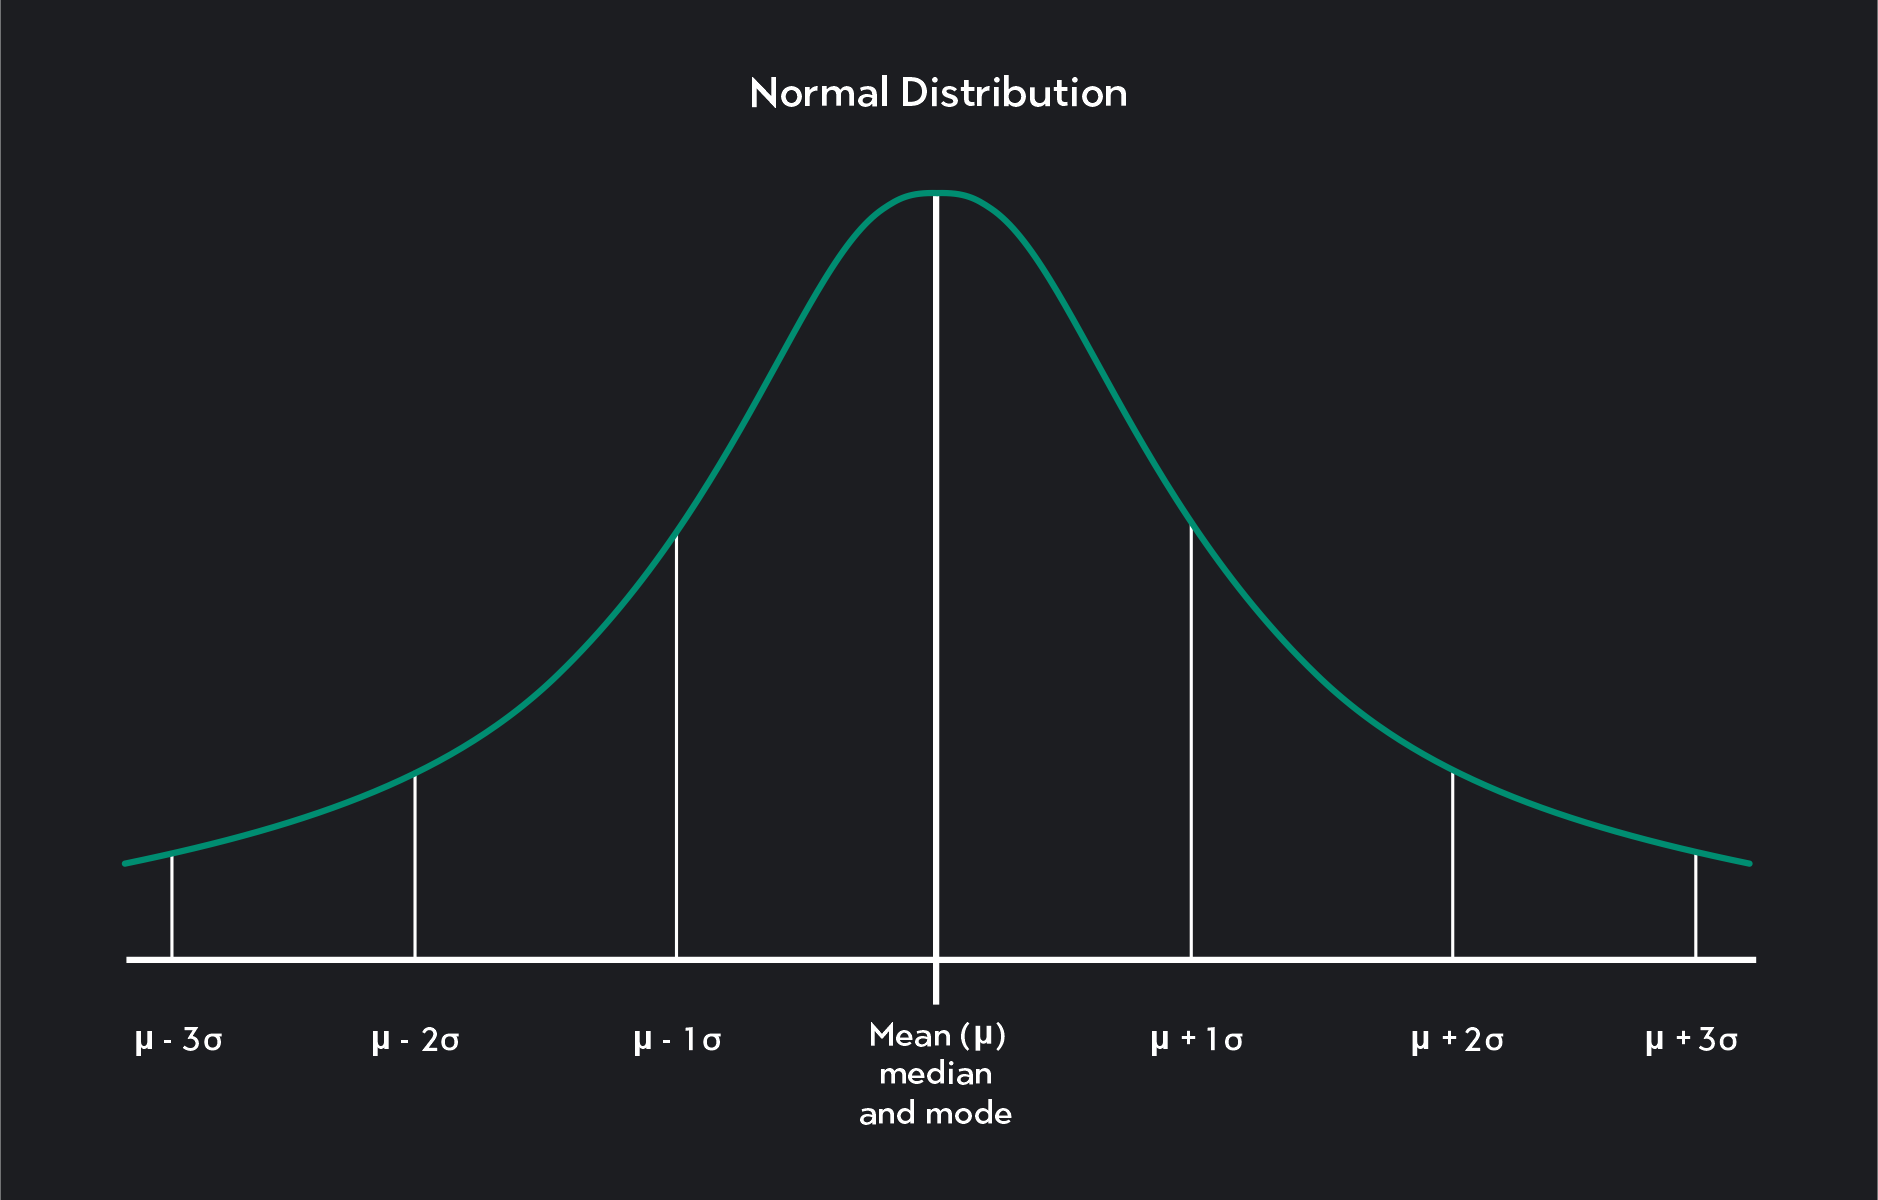
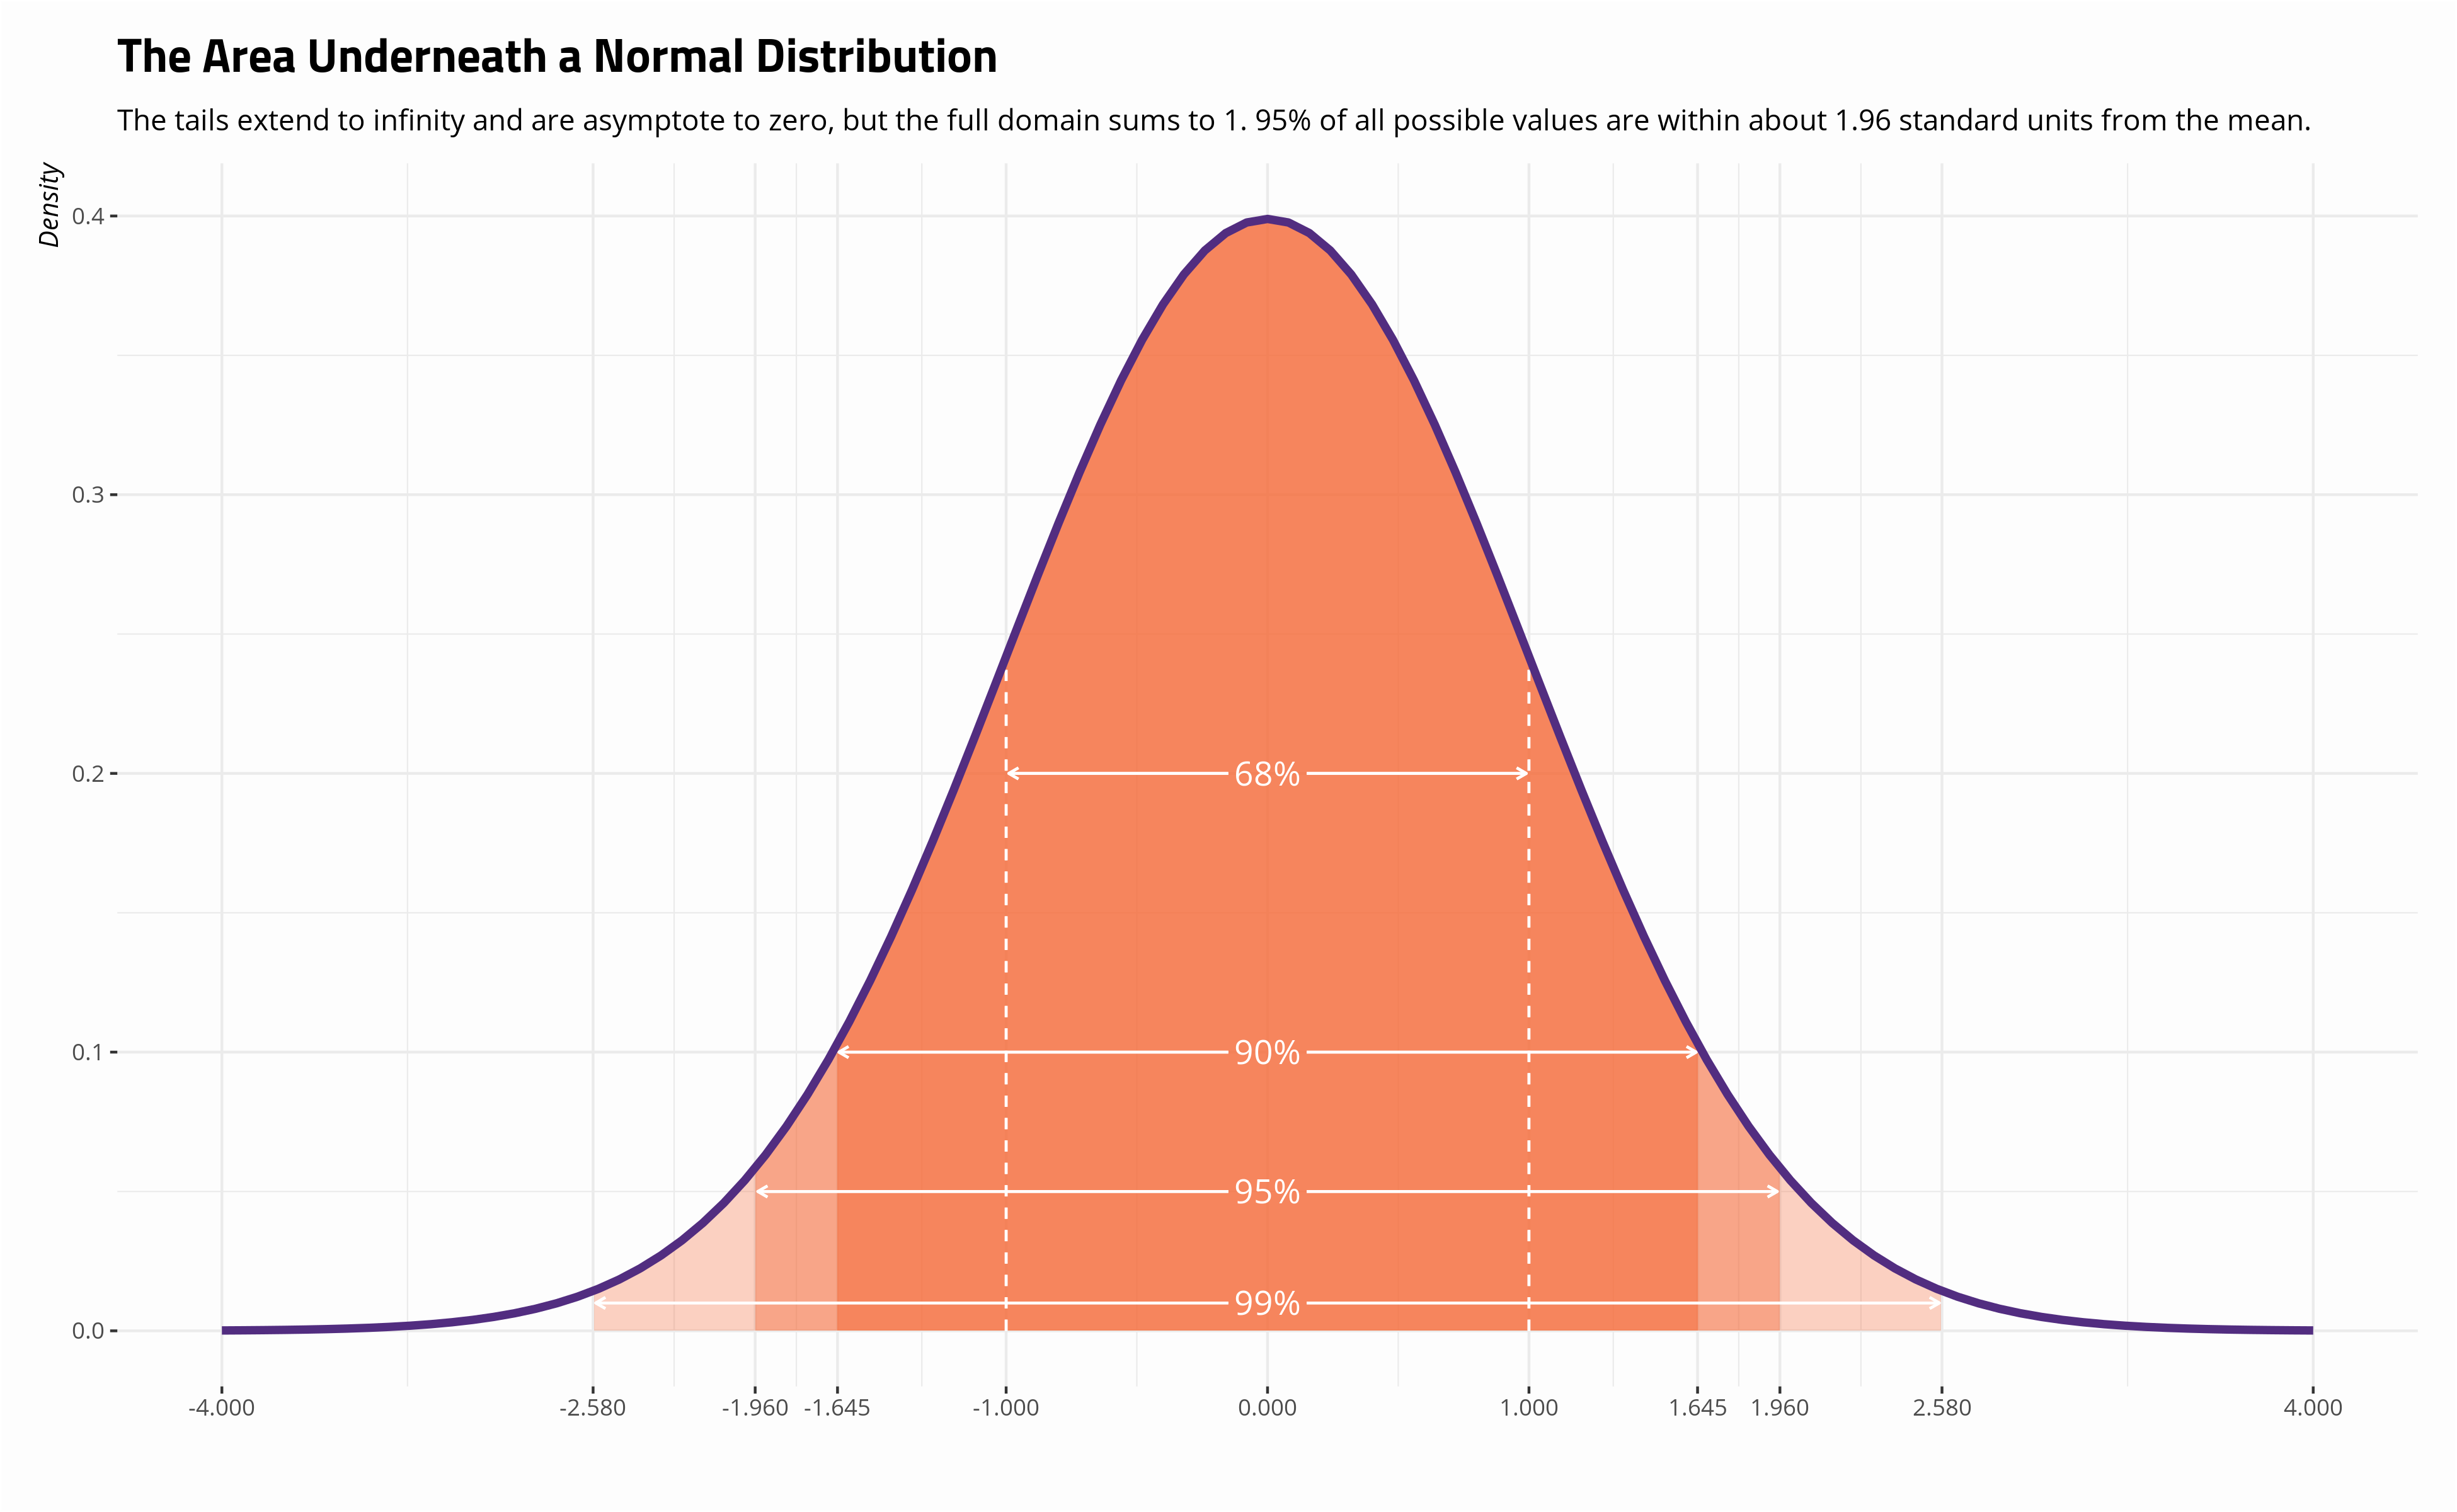
I spent three weeks debugging a quality control pipeline last year because the standard deviation was drifting and nobody noticed until we shipped bad product. The issue wasn't the calculation itself. It was that the underlying data wasn't actually normal, and we'd been blindly applying the standard formula anyway. This happens more often than you'd think. The standard deviation measures how spread out your data points are from the mean. For a normal distribution, about 68% of data falls within one standard deviation, 95% within two, and 99.7% within three. That's the empirical rule. But the empirical rule only works if your data is actually normal, which is a big if. Here's how I calculate it for a sample. Take each data point, subtract the mean, square the result, sum all those squared differences, divide by n minus one, and take the square root. The n minus one is Bessel's correction, and it exists because when you're working with a sample rather than a full population, dividing by n underestimates the true spread. If you skip that correction your confidence intervals will be too narrow and you'll be overconfident in your results.
I usually write this as a quick Python function instead of doing it by hand. Numpy's std function does it in one line, but you have to remember to set the ddof parameter to 1 for sample standard deviation. Default is 0, which gives you population standard deviation. I made that mistake early on in a project and the model predictions were off by enough to matter. Took me two days to trace it back.
Why Your Standard Deviation Lies to You
The biggest problem I see people run into is assuming their data is normally distributed when it isn't. Real-world data is rarely perfect. A normal distribution is symmetric with zero skew and a kurtosis of three. Most things you measure in production don't look like that. Revenue data is right-skewed. Sensor readings can be bimodal. Defect counts follow a Poisson distribution, not a normal one. When you apply the standard deviation to non-normal data the percentages break down. The 68-95-99.7 rule stops being accurate. You might think 95% of your values fall within two standard deviations when really only 80% do, or vice versa. That difference between assumed and actual coverage can cost you a lot in risk assessment. I learned this the hard way with a dataset of customer support ticket resolution times. The mean looked clean. The standard deviation calculated fine. But the distribution was heavily right-skewed because a small number of tickets took weeks to resolve while most were done in hours. When I used the standard deviation to set SLA thresholds based on the normal assumption, I missed about 12% of the outlier tickets that were actually problematic. Switching to a log transformation before calculating the standard deviation fixed the issue entirely. The transformed data was much closer to normal and the thresholds became actually useful.
Get the Full Details
A Workflow That Actually Works
Before you calculate anything, check whether your data is normal. Use a Q-Q plot or a Shapiro-Wilk test. The Shapiro-Wilk test is sensitive with small samples but can be overly aggressive with large ones. A Q-Q plot lets you see the deviation visually, which is often more informative than a p-value alone. If the points roughly follow a diagonal line, you're probably okay. If they curve away, your data isn't normal. For a quick sample calculation in Python: import numpy as npdata = [12.3, 15.1, 14.7, 13.2, 16.0, 11.8, 14.5]
std_dev = np.std(data, ddof=1)
That gives you the sample standard deviation. If you're working with an entire population rather than a sample, remove the ddof argument or set it to 0. When your data is non-normal and you still need a standard deviation for comparison purposes, consider using the interquartile range instead. It's less sensitive to outliers and doesn't assume a specific distribution shape. The IQR divides your data into quartiles and measures the middle 50%. It's not a replacement for standard deviation in every context, but it's a better descriptor of spread for skewed data and it doesn't rely on the mean, which can be pulled far from the center by extreme values.
Common Pitfalls That Waste Time
Blending populations is another one I see constantly. If you combine measurements from two different machines, two different shifts, or two different factories into one dataset, the standard deviation will be inflated. Not because the individual processes are variable, but because the groups themselves have different means. The within-group variability is hidden. I once saw a standard deviation of 15 on a metric where each subgroup had a standard deviation under 3. The problem was entirely between-group variation that nobody had checked for. Another issue is rounding too early in intermediate steps. If you're manually calculating variance by hand and you round the mean to two decimal places before computing squared differences, your final standard deviation can drift noticeably. With small samples this matters more. Keep full precision through the calculation and round only at the end. Outliers deserve attention but don't just delete them because they inflate the standard deviation. A standard deviation of 10 versus 15 isn't just a number difference. It changes whether a value at three standard deviations from the mean is even possible under your model. If an outlier is a data entry error, fix it. If it's a real measurement, keep it and consider a robust estimator like the median absolute deviation instead.

When the Standard Deviation Isn't Enough
The standard deviation assumes constant variance across the range of your data. In regression analysis this is the homoscedasticity assumption. When variance changes with the mean, which is common in count data and financial returns, the standard deviation becomes misleading as a sole descriptor. A standard deviation of 5 around a mean of 10 means something very different than a standard deviation of 5 around a mean of 100. Relative measures like the coefficient of variation address this by expressing the standard deviation as a percentage of the mean. If you're working with financial time series, the standard deviation of returns is commonly used as a proxy for risk, but it penalizes upside volatility the same as downside volatility. Most investors don't consider a surprise gain to be risky. The semi-standard deviation, which only calculates dispersion for returns below the mean, gives a more relevant picture in those cases. The Normal Distribution Standard Deviation is a foundational tool and it's reliable when your assumptions hold. The assumptions don't hold as often as textbooks suggest. Check your data first, pick the right estimator for what you actually have, and don't let a single number give you false confidence in how well you understand your process.