Getting the Building Blocks Straight
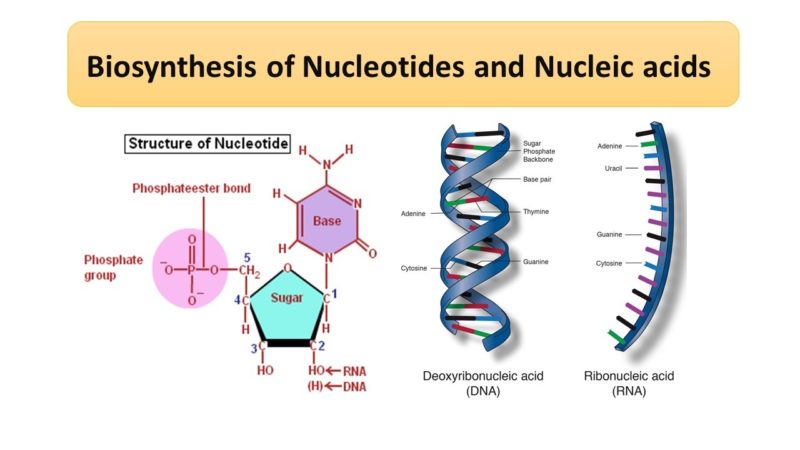
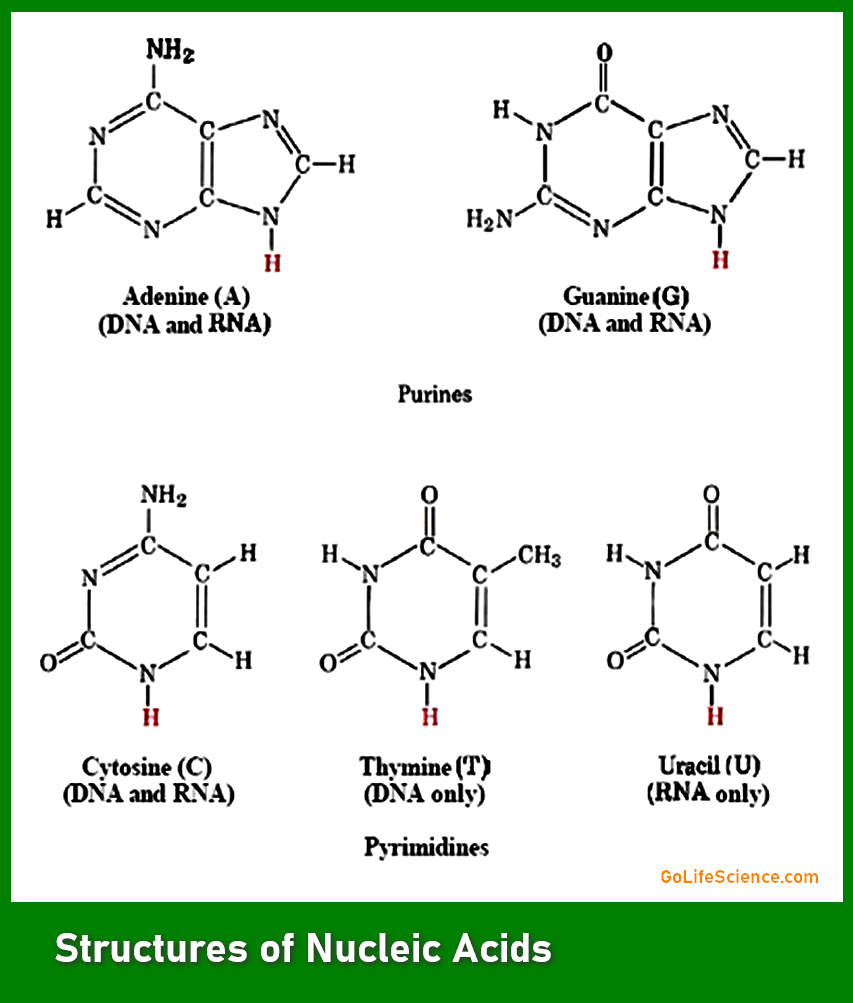
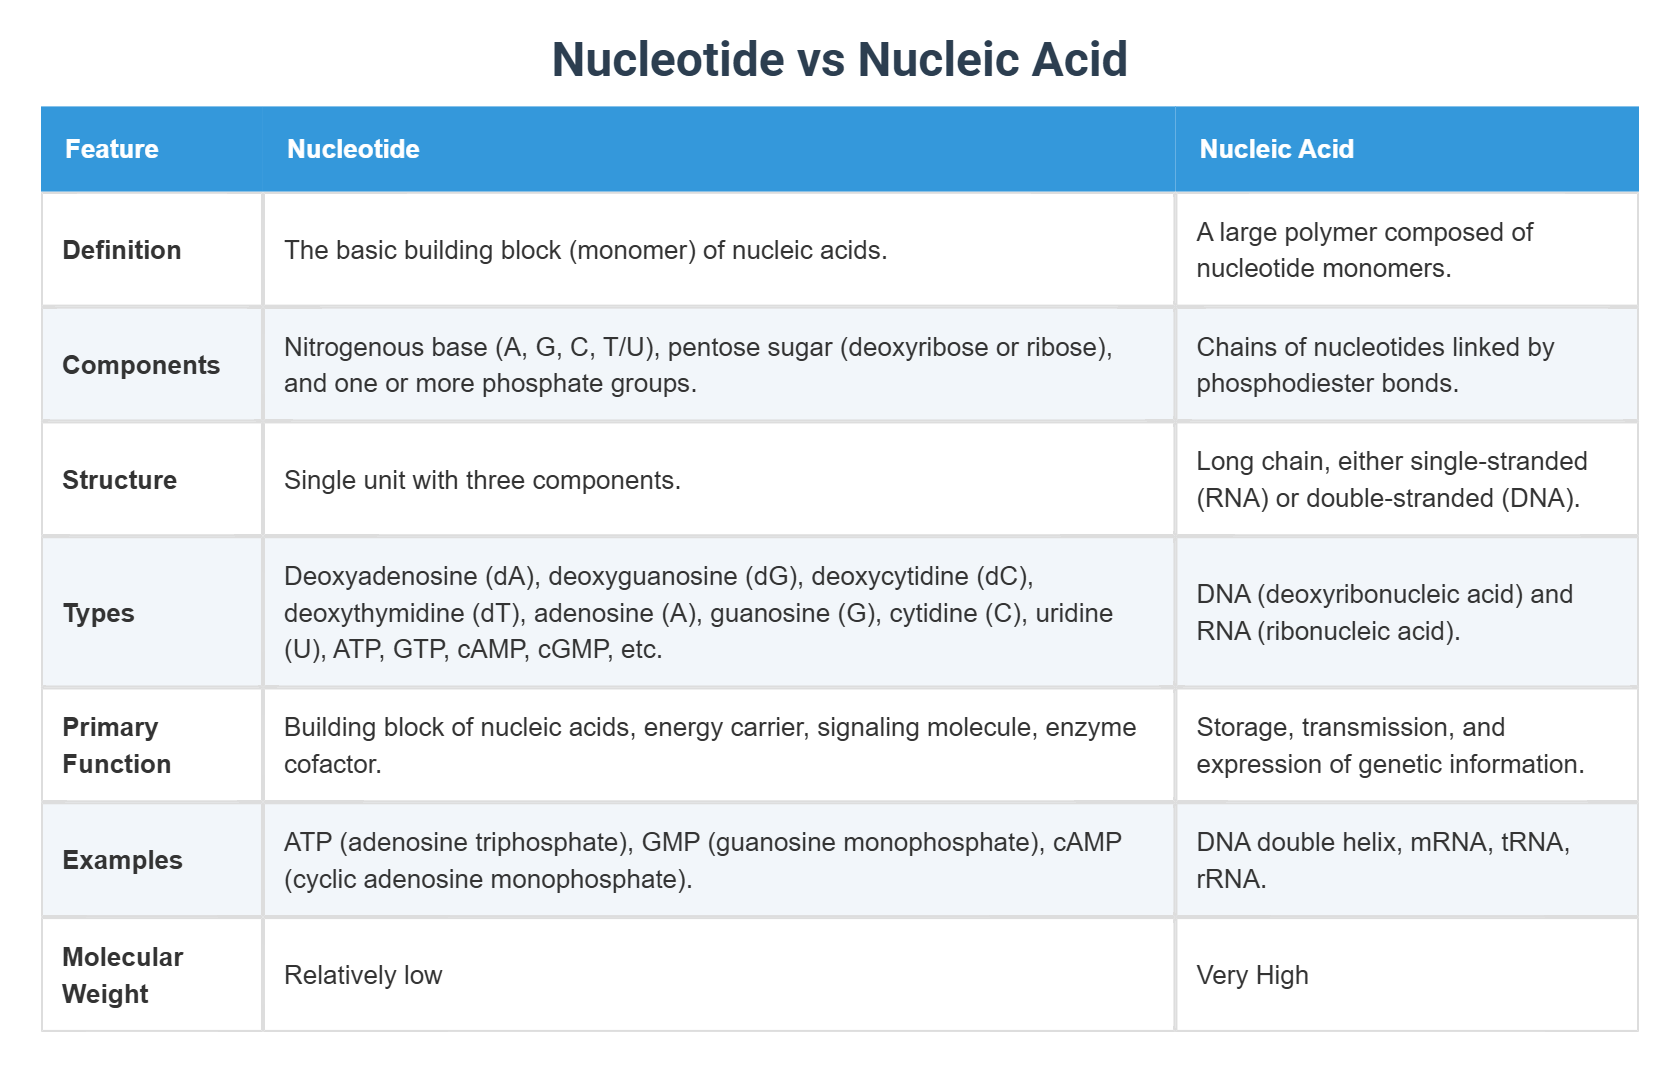
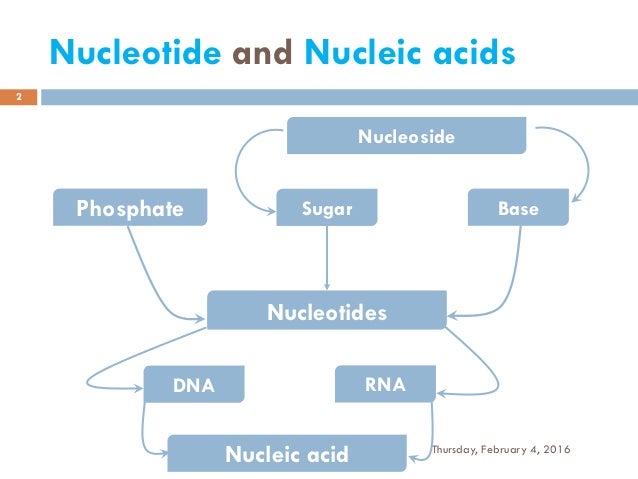
Nucleotides are the individual monomer units, and nucleic acids are the polymers made from them. That's the textbook answer, but in practice it's messier than people expect. A nucleotide consists of three parts: a nitrogenous base (adenine, guanine, cytosine, thymine, or uracil), a five-carbon sugar (deoxyribose in DNA, ribose in RNA), and at least one phosphate group attached to the 5' carbon of that sugar. When these units link through phosphodiester bonds between the 3' hydroxyl of one sugar and the 5' phosphate of the next, you get a nucleic acid chain. The confusion usually happens because the terms overlap in casual usage. Someone will say "nucleic acids" when they really mean the individual monomers, or they'll use the words interchangeably in a methods section without realizing the distinction matters for things like quantification calculations. Here's the practical way to think about it: every nucleic acid is made of nucleotides, but not every nucleotide is part of a nucleic acid. Free nucleotides float around in cells as metabolic intermediates — ATP, GTP, CTP, UTP for RNA metabolism, and the deoxy versions for DNA synthesis. These are substrates for polymerases, signaling molecules, and energy carriers. Once incorporated into a chain, they're technically called nucleotide residues or just nucleotides within the context of the polymer. I've seen this distinction matter most during oligonucleotide synthesis and QC. When a client sent me a 60-mer for sequencing validation, the spec sheet listed the concentration in µg/mL of "nucleic acid," but the actual pricing and yield calculations needed to account for the fact that each incorporated nucleotide residue loses a pyrophosphate group during polymerization. The molecular weight per residue is different from the molecular weight of the free triphosphate precursor by roughly the mass of PPi (about 158 Da per bond). If you calculate primer yield using the free nucleotide MW instead of the residue MW, your molarity will be off by roughly 15-20% depending on sequence length. I started using the Wallace rule with corrected residue weights and it brought my quantitation errors down from ±25% to under ±5% against UV absorbance readings.
Another counter-intuitive point: single-stranded DNA and RNA don't follow the same molar extinction coefficient rules. The hyperchromic effect means ssDNA absorbs about 30-40% more UV light at 260nm than the same sequence in dsform. If you're working with a stranded oligo and using a standard A260-to-concentration conversion factor (33 µg/mL per A260 unit for ssDNA), you're actually overestimating concentration if the sample has any significant secondary structure. I learned this the hard way when I was purifying siRNA duplexes and the A260 readings kept drifting after heating and slow cooling cycles. The workaround was straightforward — denature at 95°C for 2 minutes, immediately place on ice, then measure within 30 seconds before reannealing could partially occur. This cut my duplicate measurements from ±18% variance down to ±3%. There's also the matter of modified nucleotides, which complicates everything further. When someone orders a fluorescently labeled probe or a methylated CpG-containing oligo, the "nucleotide" being referenced isn't a standard A, T, G, or C at all. The modified base changes the extinction coefficient, which changes the concentration calculation, which changes how much you weigh out for a reaction. I worked on a project where we were synthesizing phosphorothioate-modified antisense oligos, and the sulfur substitution at the non-bridging phosphate oxygen shifted the UV absorption profile enough that the manufacturer's default conversion factors were off by about 12%. We had to generate a standard curve using gravimetric preparation and HPLC quantification rather than relying on the spectrophotometer alone. The practical takeaway is that nucleic acids and nucleotides occupy different layers of the same system, and treating them as synonyms gets you in trouble during experimental design, calculations, and troubleshooting. The distinction matters most when you're doing anything that requires precise molar quantities — cloning, qPCR, next-gen library prep, or any enzymatic reaction where the template or primer concentration directly affects efficiency. For routine PCR where you're adding microliters of a stock solution, the difference might not be noticeable. But once you move into quantitative work, digital PCR, or anything requiring sub-micromolar precision, knowing whether you're dealing with residues in a polymer or free monomeric units becomes the difference between a clean result and a failed run.