Setting up Hypothesis Testing Without Losing Your Mind
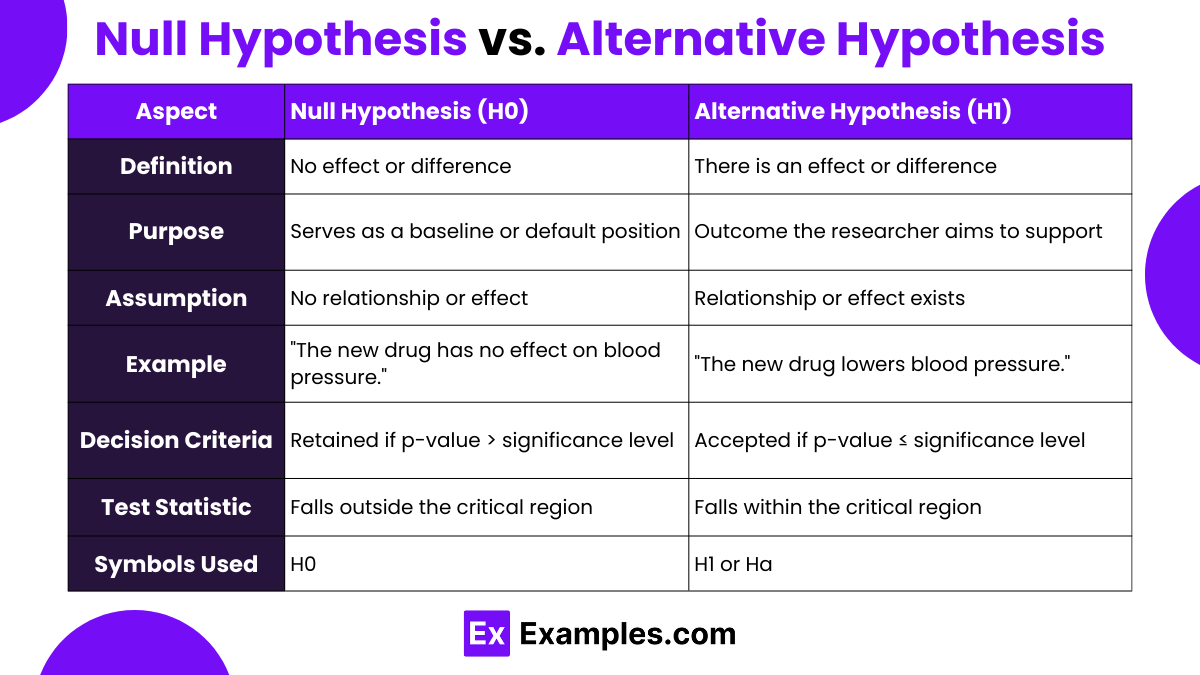
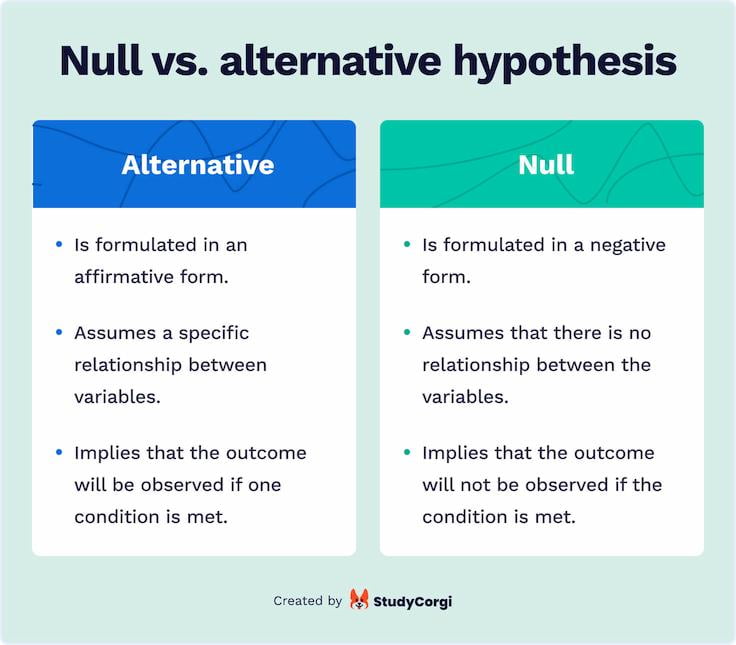
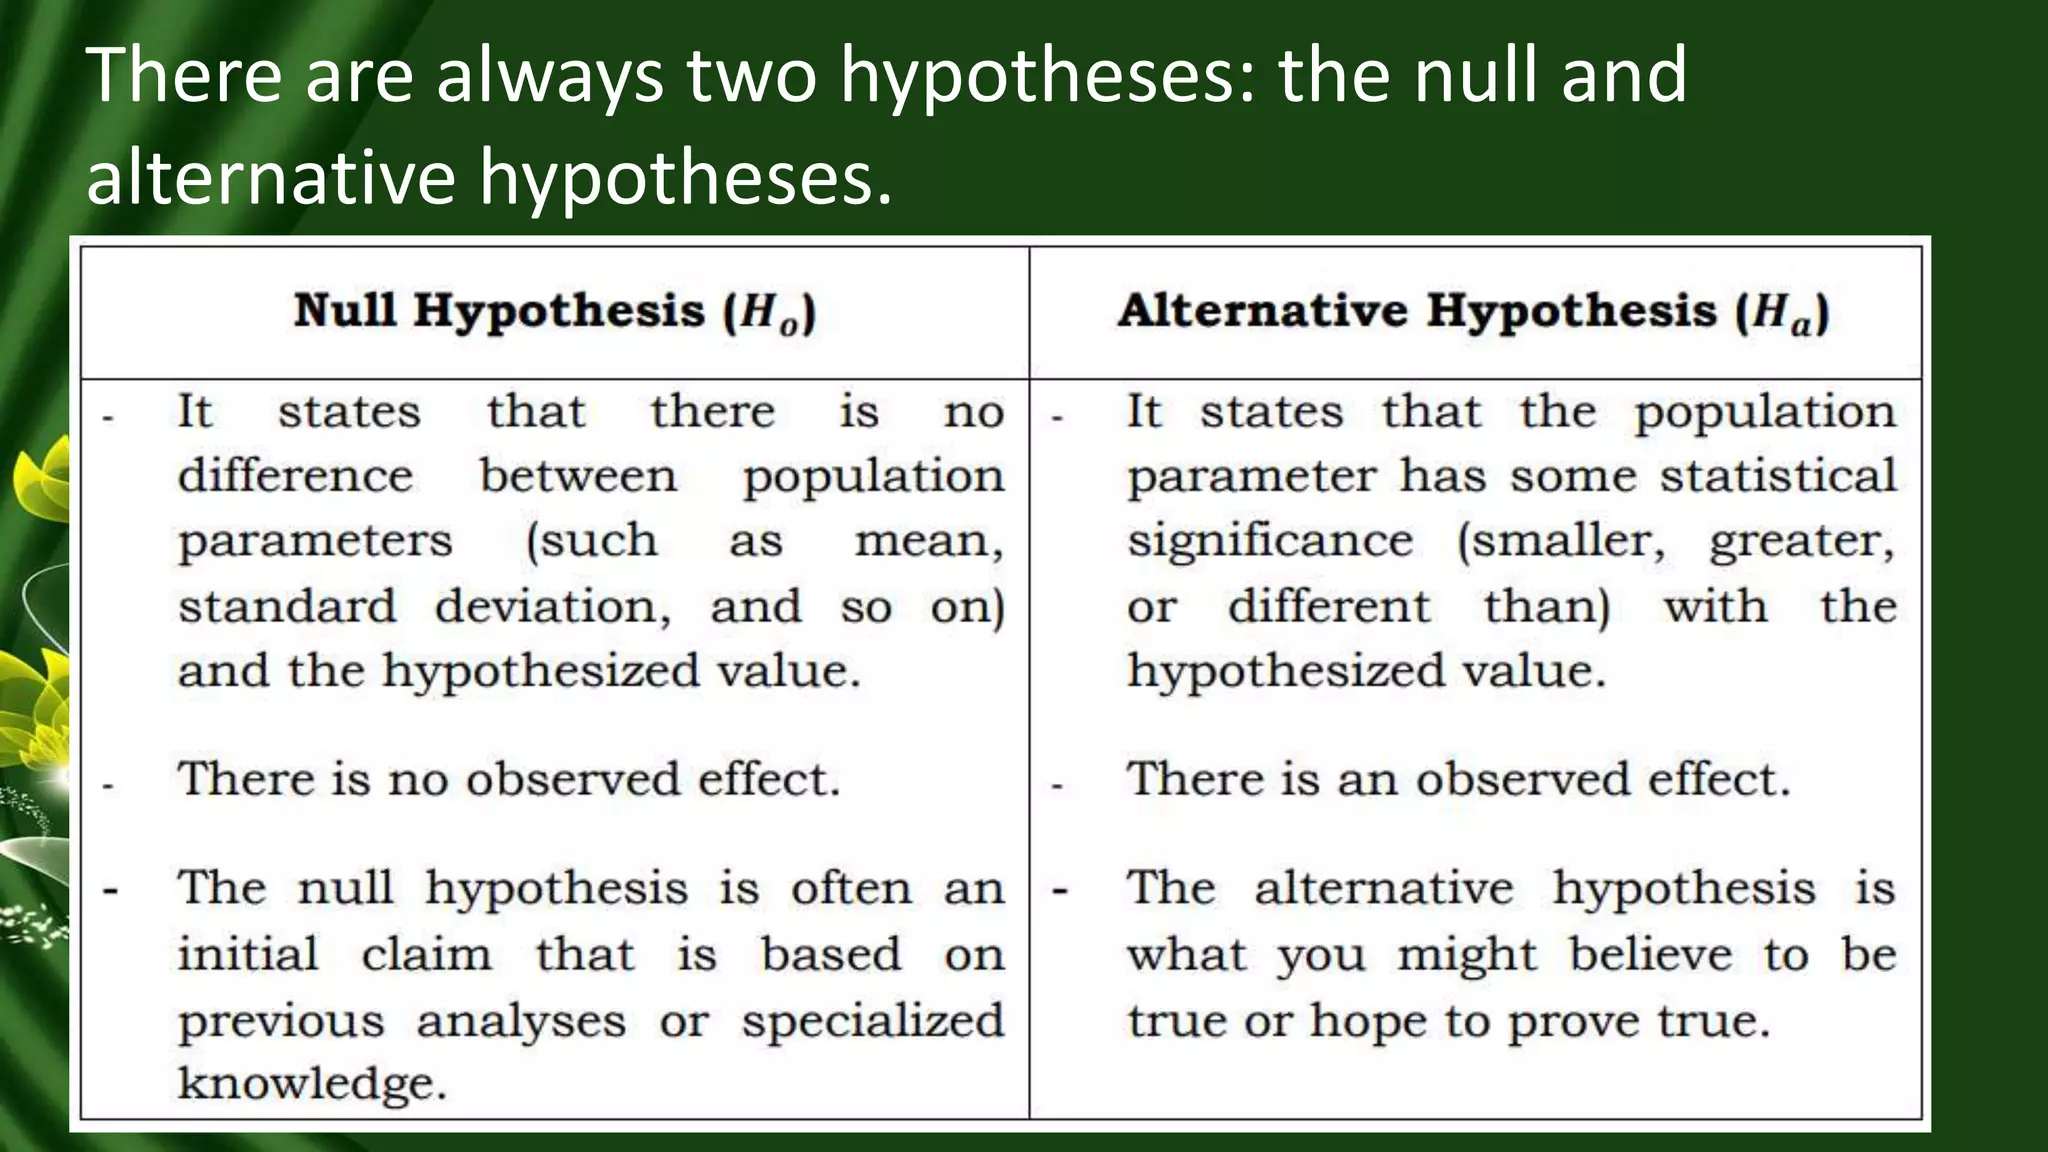
Most people mess this up because they skip the part where you actually define what you're looking for before running any tests. I remember working on a regression project where my initial analysis was showing a statistically significant effect that disappeared entirely once I realized my null hypothesis was poorly specified. I had been testing whether the coefficient was different from zero, but my actual question was whether it was different from a theoretically derived baseline value. That single shift took me from false confidence to actual insight. A hypothesis is just a claim about a population parameter that you want to test. The null hypothesis is the default position you assume is true until your data convinces you otherwise. The alternative hypothesis is what you'd conclude if the null doesn't hold up. That's it. There is no drama in the math. People overcomplicate it because they try to memorize procedures instead of understanding the logic. The procedure goes like this. You state your null hypothesis clearly. It should be something falsifiable, like H0: mu equals 50. Then you state the alternative, which could be H1: mu is not equal to 50 for a two-tailed test, or H1: mu is greater than 50 for a one-tailed test. You pick your significance level, usually 0.05, though I often recommend 0.01 when dealing with multiple comparisons or small sample sizes. You calculate your test statistic based on your data. Then you compare the p-value to your significance level. If the p-value is lower, you reject the null. If it is higher, you fail to reject it.
Failing to reject is not the same as accepting. That distinction matters more than most textbooks make it clear. When you fail to reject the null, you are simply saying your data did not provide strong enough evidence against it. It does not prove the null is true.
Common Pitfalls That Trip Up Everyone
The biggest issue I see is people treating a p-value of 0.06 as somehow fundamentally different from 0.07. Both results mean essentially the same thing. Your conclusion should not change between those two values. The arbitrary cutoff at 0.05 creates a false sense of precision. Report the exact p-value and let the reader interpret it. Another mistake is choosing your alternative hypothesis after seeing the data. If you run an experiment, look at the results, and then decide to switch from a two-tailed to a one-tailed test because the one-tailed path gives you significance, you are effectively double dipping. Your p-value is now wrong. I once caught this in a peer review of a study that claimed a treatment effect after switching hypotheses post hoc. The corrected analysis showed the effect was completely nonexistent at the proper significance level. Sample size also distorts results in ways people do not expect. With a large enough sample, even trivial differences become statistically significant. A p-value of 0.001 might correspond to a difference so small it has no practical meaning. Always report effect sizes alongside your p-values. Cohen's d or the raw mean difference tells you how big the effect actually is.
Get the Full Details
A Problem I Faced With Paired Data
I was analyzing pre-post intervention data where subjects served as their own controls. The data were clearly non-normal, and the transformation attempts made things worse rather than better. A standard paired t-test was inappropriate given the distribution. I ended up using a bootstrap-based approach instead. I resampled the differences with replacement thousands of times, built a confidence interval from that distribution, and tested whether the interval included zero. This took about twenty minutes to code in Python using numpy, and it gave me a result that was both statistically honest and robust to the non-normality. It would have taken me days to find a non-parametric alternative that matched the paired structure of the data. There are scenarios where the standard framework just does not work. If you have categorical data with low expected cell counts, the chi-squared test breaks down. Use Fisher's exact test instead, even though it is computationally heavier. If you are running dozens of comparisons simultaneously, like in gene expression studies, uncorrected p-values will give you a flood of false positives. Apply a Bonferroni correction or, better yet, use the Benjamini-Hochberg procedure to control the false discovery rate while preserving more statistical power. Bayesian methods are worth considering when your sample size is small or when you need to incorporate prior knowledge into your analysis. They do not rely on the p-value framework at all and can give you direct probability statements about parameters. The tradeoff is that your conclusions become sensitive to your choice of prior distribution. You should run sensitivity analyses across different priors to show that your results are not an artifact of your assumptions.
Practical Steps to Implement Null Hypothesis And Hypothesis Testing
Start by writing down your null and alternative hypotheses before you touch the data. Use specific notation. State whether your test is one-tailed or two-tailed and justify that choice. Check your data for assumptions. Normality, independence, equal variances. Run diagnostic plots and tests. If assumptions are violated, either transform the data or choose a method that does not require those assumptions. Calculate your test statistic and p-value using the appropriate software. R and Python both have well-documented functions for this. Interpret the result in terms of your original research question, not just as a pass-fail against 0.05. Report confidence intervals. They convey more information than a p-value alone. If you need code to get started, the scipy.stats module in Python handles most common tests. The ttest_ind function does independent samples, ttest_rel does paired samples, and chi2_contingency handles categorical data. Install scipy with pip if you do not already have it. That is the fastest route from zero to a working test without wrestling with package dependencies.