The Two Hypotheses That Actually Matter
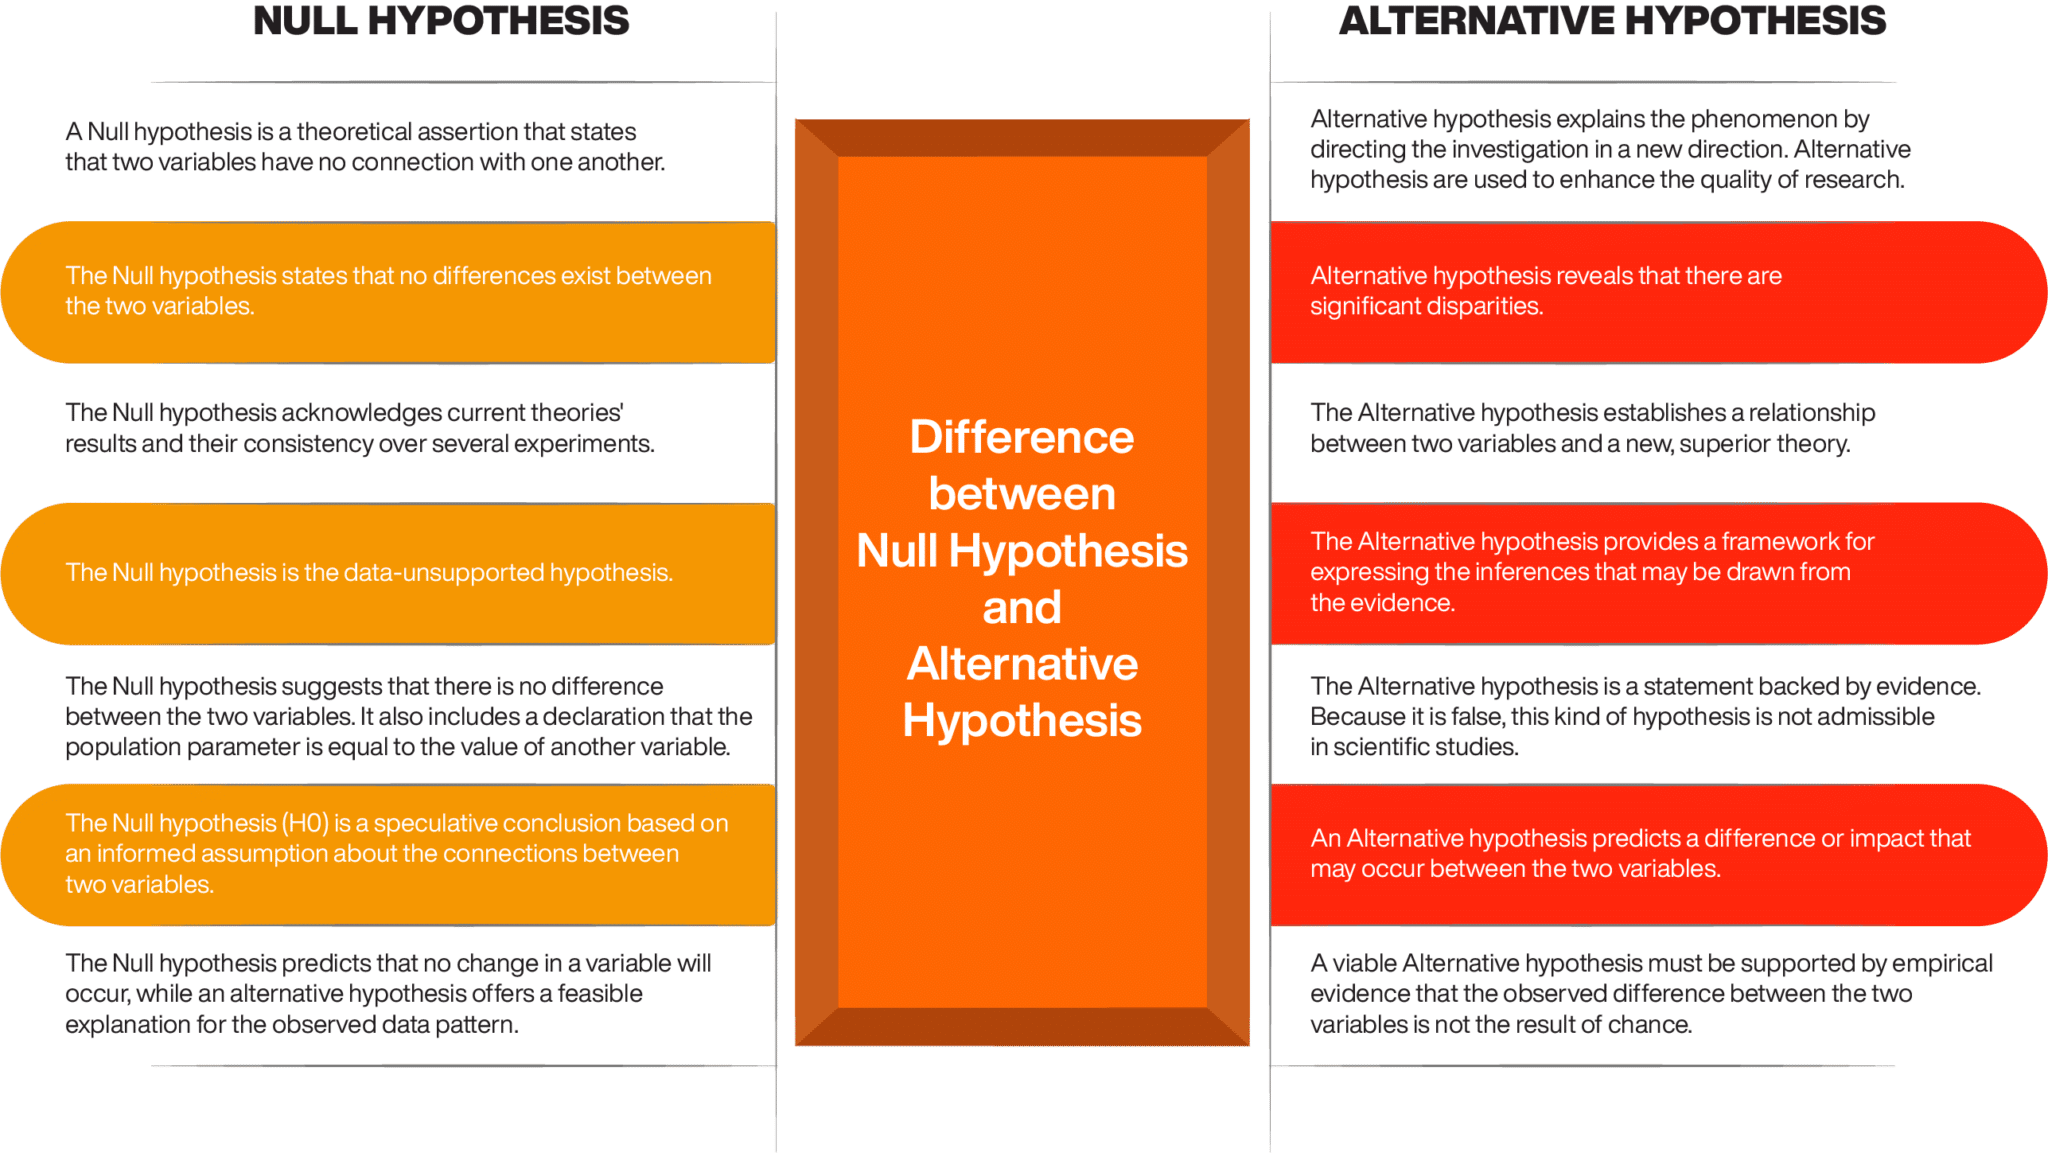
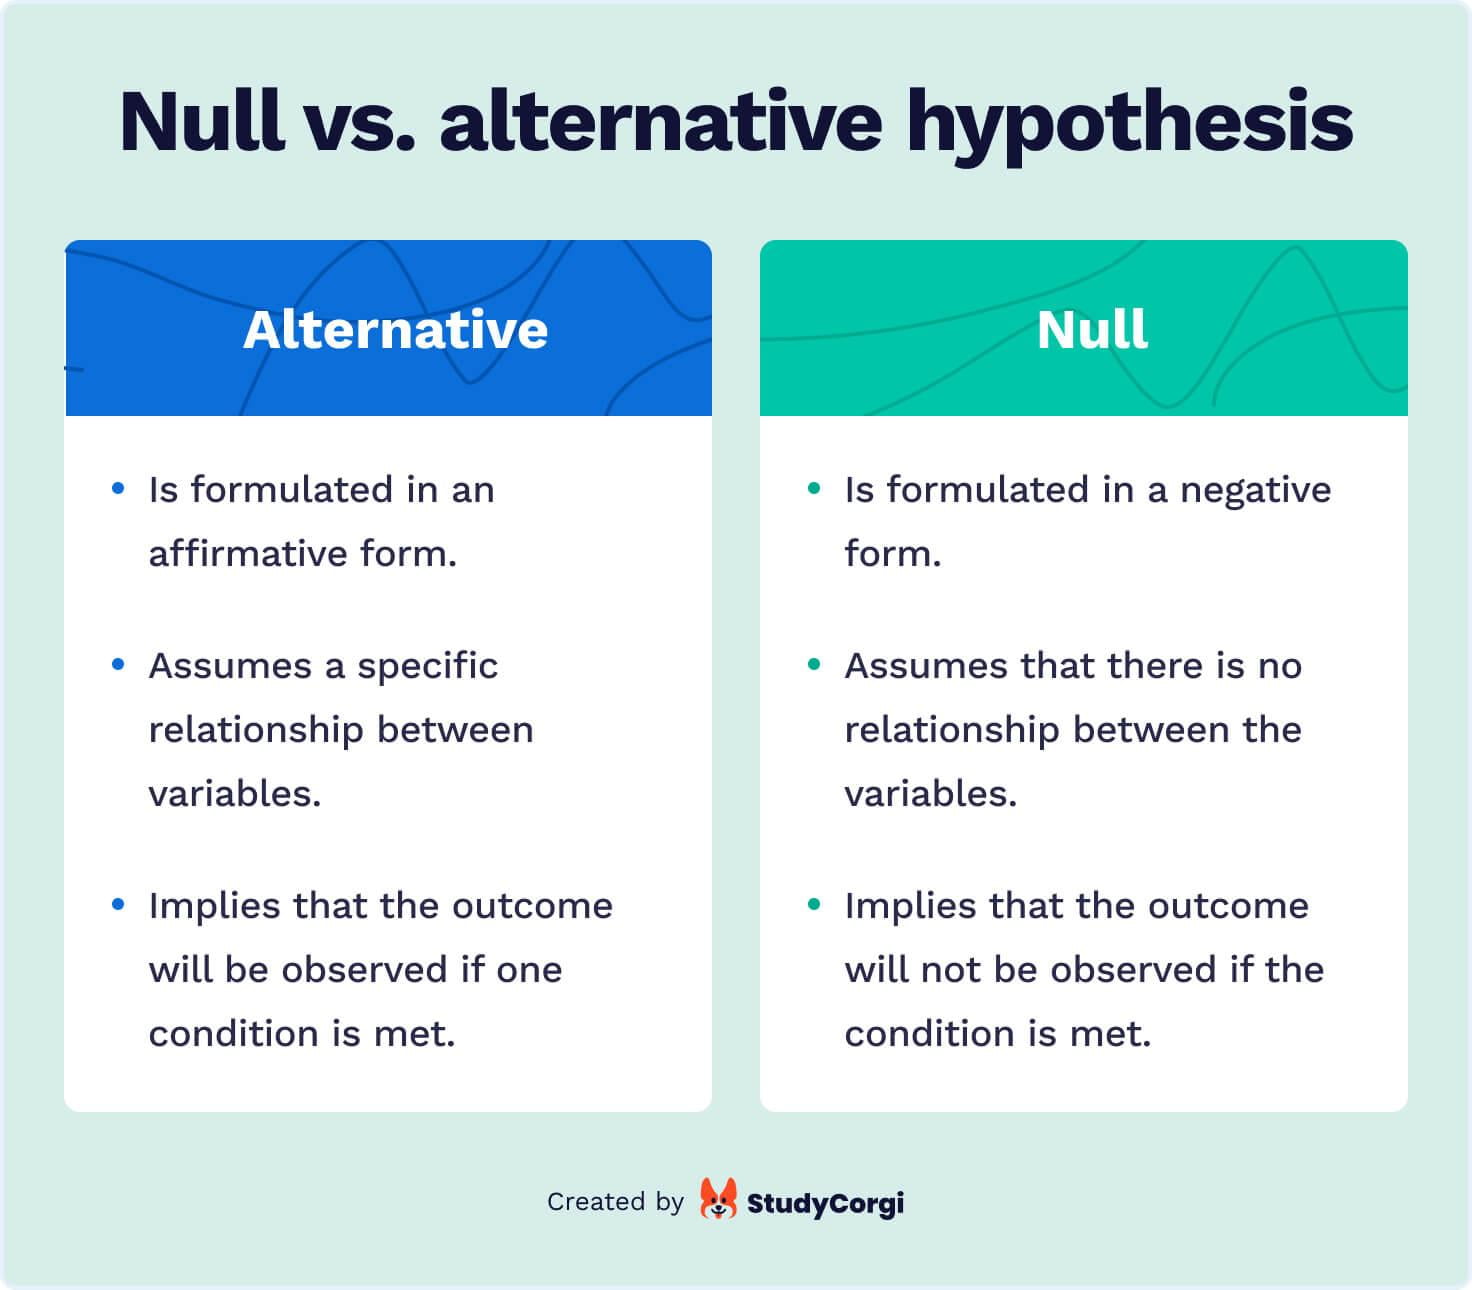
When you run a statistical test, you are always comparing two things against each other. The null hypothesis and the alternative hypothesis. That is the Null Versus Alternative Hypothesis framework, and it is the foundation of essentially every p-value you will ever encounter in a paper, a boardroom, or a regulatory filing. The null hypothesis is the default position. It is the statement of no effect, no difference, no relationship. You assume it is true until the data forces you to doubt it. The alternative is what you are actually trying to find evidence for. That is it. It is not fancy. It is not mystical. I spent three years working in clinical trial statistics, and the mistake that costs the most money is not getting the hypotheses wrong. It is letting the alternative hypothesis dictate your sample size calculation without thinking about what the null actually represents. You need to define both before you collect a single data point. If you flip them around after looking at the data, your p-value is meaningless.
Here is the practical setup. You state H0 and Ha. You pick an alpha level, usually 0.05. You collect data. You compute a test statistic. You check whether the probability of observing that statistic under H0 is small enough to reject H0 in favor of Ha. If it is, you report a statistically significant result. If it is not, you fail to reject H0. That last phrase matters. You never accept the null. You just fail to reject it.
How It Actually Works in Practice
Let me walk through a real example because definitions alone do not help when you are staring at a spreadsheet at 11pm. Say you are testing whether a new drug lowers blood pressure more than a placebo. Your null hypothesis is that the mean difference between the treatment group and the placebo group is zero or less. Your alternative is that the mean difference is greater than zero. You run a one-sided t-test because you only care about improvement, not worsening. You get a p-value of 0.03. You reject the null. You have statistically significant evidence that the drug works. Done, right. Not quite. The p-value tells you nothing about the size of the effect. It might be a two millimeter mercury drop. Clinically irrelevant. But statistically significant with a large enough sample. That is why you always report the effect size and confidence interval alongside the p-value. Any reviewer who asks for just a p-value is doing their job poorly. I encountered a case once where a marketing team was A/B testing a landing page. Their null was that the new page performs the same as the old one. Their alternative was that it performs better. They ran the test for two weeks and got a p-value of 0.041. They celebrated. Then I looked at the raw numbers. The conversion rate went from 2.1 percent to 2.3 percent. They had over 50,000 visitors and still barely crossed the significance threshold for a lift that would not pay for the server costs it generated. We killed the test and went back to the original page. That is the danger of treating hypothesis testing as a binary approve or reject machine without considering practical significance.
Get the Full Details
Common Pitfalls That Sink Projects
The biggest issue I see is people confusing statistical significance with practical importance. They are different things. A tiny effect can be highly significant if your sample is big enough. A large effect can be non-significant if your sample is too small. Both outcomes are true. Both are unhelpful if you do not think about them carefully. Another pitfall is multiple comparisons. Every time you run a test, you have a 5 percent chance of a false positive if the null is true. Run 20 tests, and you are almost guaranteed at least one false positive by chance alone. The Bonferroni correction exists, but it is overly conservative and destroys power. I prefer the false discovery rate approach when dealing with many simultaneous tests. It is less harsh and still controls for the inflation of Type I errors. There is also the problem of p-hacking. You run a test, the p-value is 0.07. You exclude an outlier. Now it is 0.04. You try a different covariate. Now it is 0.03. You are no longer testing a pre-specified hypothesis. You are mining the data until it confesses. Pre-registration solves this partially, but it does not fix the underlying incentive structure that rewards significant results.
When This Framework Fails Completely
Hypothesis testing breaks down in several scenarios. Small sample sizes with non-normal data are the first one. The t-test assumes normality, and with n less than 30 and a skewed distribution, your p-value is unreliable. Use a non-parametric test like the Mann-Whitney U test instead. It does not assume normality and it handles small samples better. Another failure mode is when the effect is directional but you specified the wrong tail. If you set up a one-sided test but the effect goes in the opposite direction, you cannot reject the null no matter how extreme the result is. I have seen this happen when a researcher has a strong prior belief about the direction of an effect and designs the test accordingly, only for the intervention to produce the opposite effect. The result is non-significant even though it might be worth investigating. The framework does not allow you to say anything useful about that outcome. Bayesian methods are a reasonable alternative when you care about the probability of the hypothesis itself rather than the probability of the data under the null. Frequentist hypothesis testing answers a very specific question that most people misinterpret. Bayesian inference answers a question that is closer to what people actually want to know. But Bayesian methods require priors, and choosing priors is where a lot of controversy lives. There is no free lunch here.
A Workflow That Does Not Waste Time
Write down H0 and Ha before you look at the data. Specify the test, the alpha level, and the sample size calculation based on an expected effect size. Collect the data. Run the test. Report the p-value, the test statistic, the effect size, and the confidence interval. Check the assumptions. If they are violated, switch to a robust or non-parametric method. Do not chase significance. Do not treat 0.05 as a magic boundary. Everything between 0.01 and 0.10 is uncertain, and you should communicate that uncertainty. The Null Versus Alternative Hypothesis is not complicated in theory. It is complicated in application because people want simple answers to messy questions. The framework gives you a structured way to think about evidence. It does not give you truth. Use it appropriately, and it serves you well. Use it blindly, and it will mislead you every time.