What the Digits Actually Are
The symbols we call Hindu-Arabic numerals are 0 through 9, and they made their way into European mathematics through the work of Al-Khwarizmi in the ninth century and later Fibonacci in the thirteenth. Before that system took over, merchants and scholars were using Roman numerals, which is not a great way to do multiplication at scale. I spent a summer in college helping a professor digitize medieval trade ledgers, and the first thing I learned was that most of the difficulty in those old manuscripts isn't the math — it's figuring out which scribal convention the copyist was following. Some used a variant of the Venetian abacus notation that looks nothing like the standard digits we recognize today. The core idea behind Numbers In Hindu Arabic is place value. Each digit position represents a power of ten, and the zero placeholder makes the system complete. That sounds trivial now, but you'd be surprised how many people trying to understand the basics skip past that insight and immediately jump to applications. The positional system changed how calculation works more than the individual symbols did. Without zero sitting in the ones place, you can't distinguish between 105 and 15 without extra notation, which is why early systems always had some clumsy workaround for empty positions.
Installing and Configuring Numbers In Hindu Arabic for Practical Use
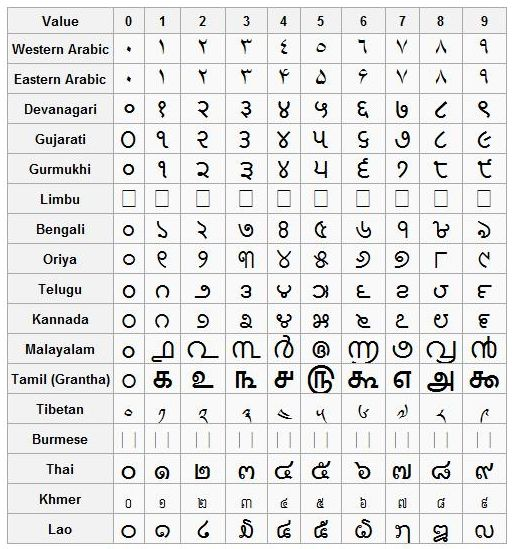
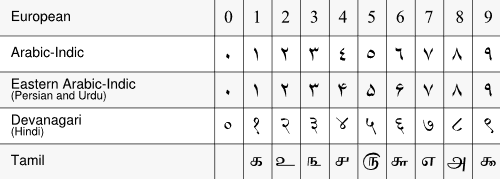
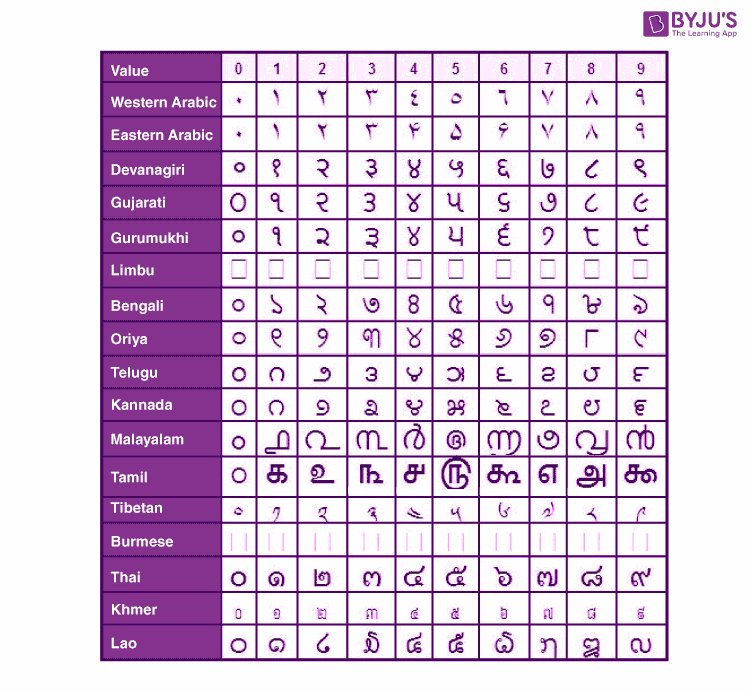
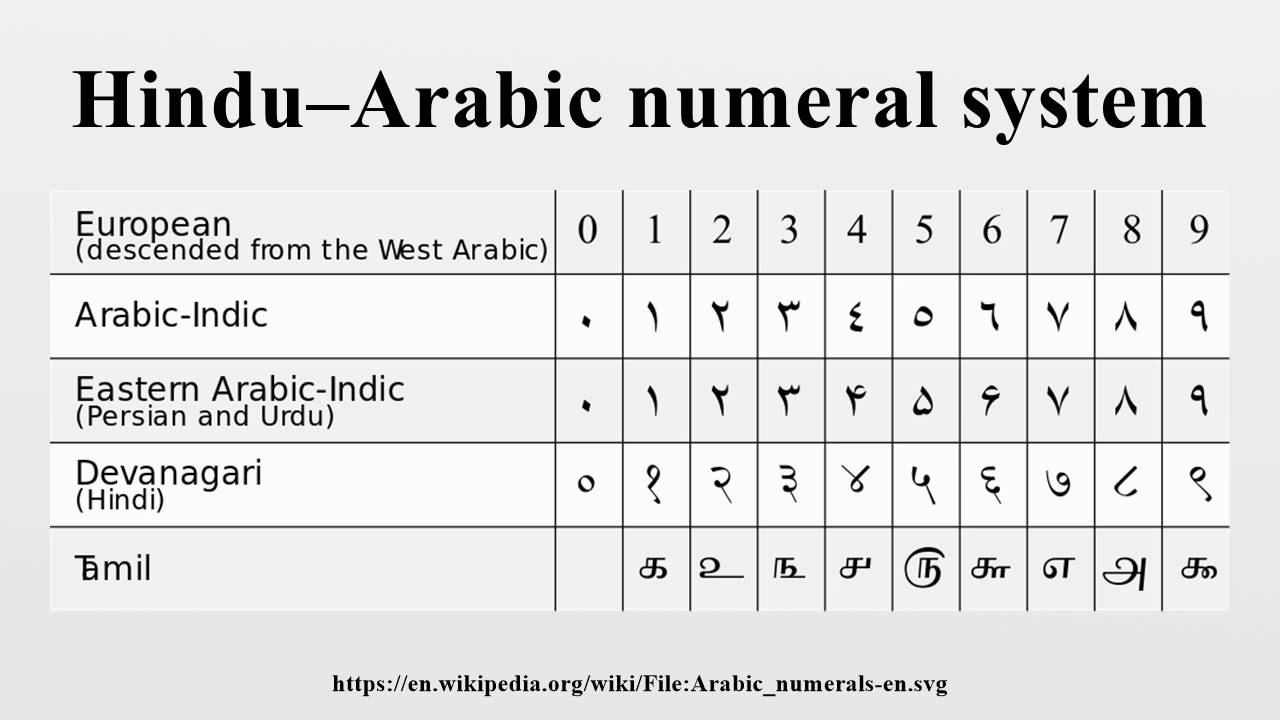
If you are working with digitized texts and need a rendering solution that handles these numerals consistently, you will run into font support issues pretty quickly. The Unicode block covers U+0660 through U+0669 for Eastern Arabic numerals ( through ) and U+06F0 through U+06F9 for Extended Arabic-Indic numerals ( through ). Most modern fonts handle the basic block, but older systems and some web environments drop them silently. I use a setup where I combine the Noto Sans Arabic font with a CSS fallback stack, and I explicitly set the lang attribute on every element containing these digits so the browser picks the right shaping rules. Without that lang attribute, OpenType features can render the digits in the wrong variant, which looks wrong to anyone who knows the difference even if they can't say exactly what is wrong. For anyone building a document pipeline, the practical approach is to normalize all numeric input to a single variant at the earliest stage possible. I wrote a short Python script that uses the unicodedata module to map every Arabic-Indic digit variant to the standard form and flags any mismatches in the source data. Running that over a batch of scanned documents usually surfaces conversion errors that would be invisible at first glance. One common problem: some older OCR engines transcribe the Persian-Indic numeral (U+06F4) as the Devanagari character (U+096A) because the glyphs look similar at low resolution. That kind of swap breaks search and sorting, and it is nearly impossible to catch without a normalization step. I also maintain a small reference table for regional variants. The Eastern Arabic numerals are standard in Egypt, Sudan, and parts of the Gulf. The Extended Arabic-Indic set with those more angular glyphs is what you see in Iran, Afghanistan, and Pakistan. The Indian subcontinent uses its own separate Indic numeral systems — Devanagari, Bengali, Tamil, and so on — which are technically distinct even though they share the same historical origin. Mixing these up in a dataset introduces systematic errors that compound over time, especially if you are doing cross-lingual text processing. I keep a lookup script on hand that maps each variant to its ISO number name and region code, and I run it as a pre-processing step before any analysis.