Converting Numbers to Arabic Numerals: What Actually Works
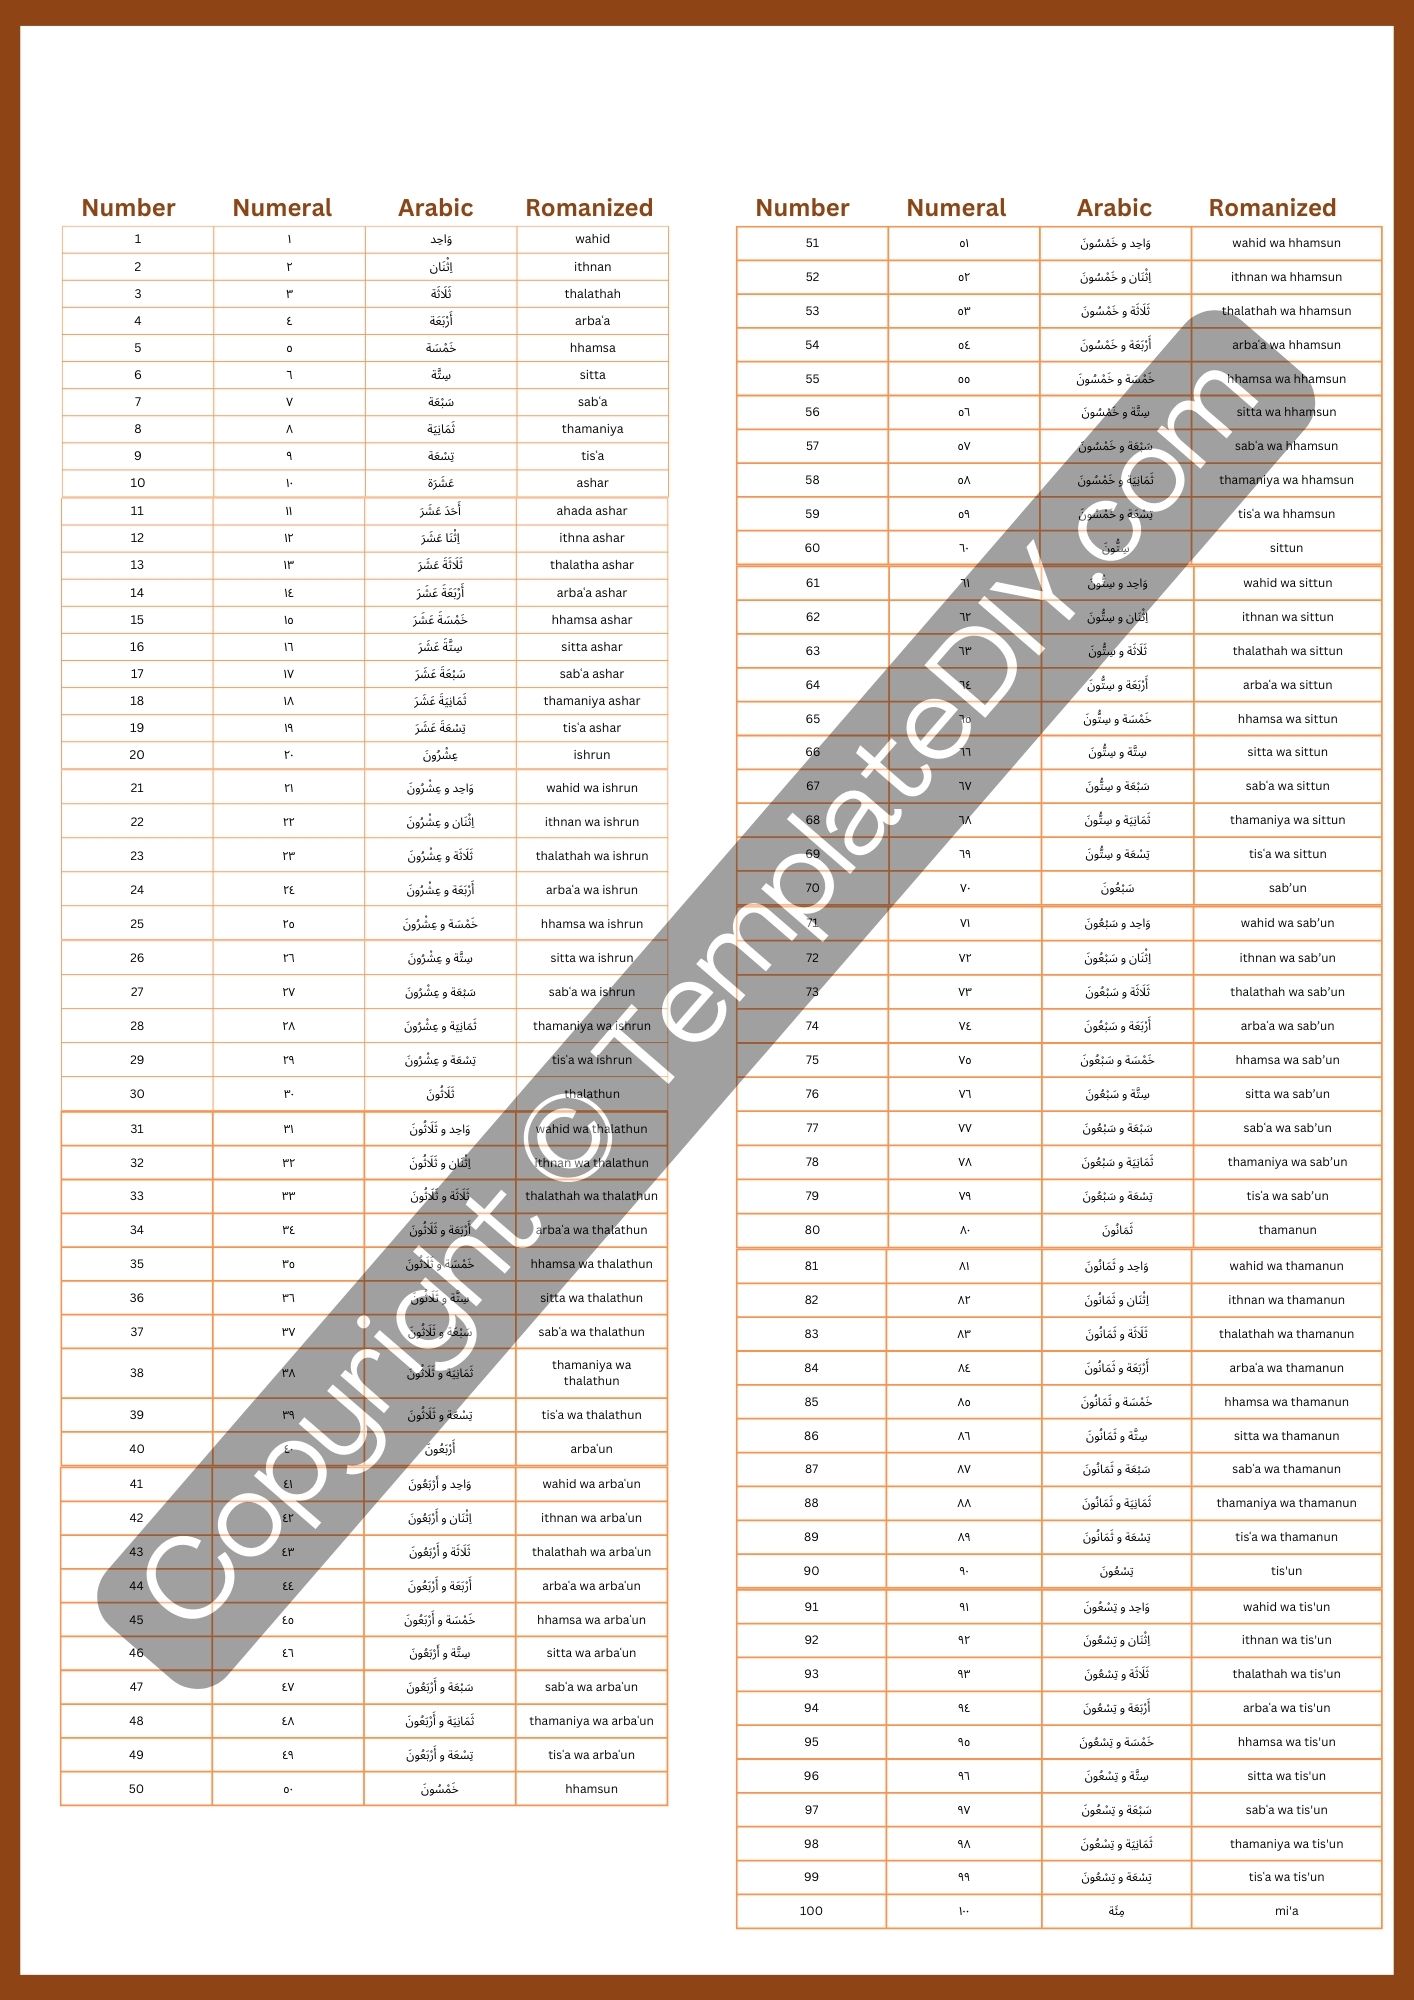
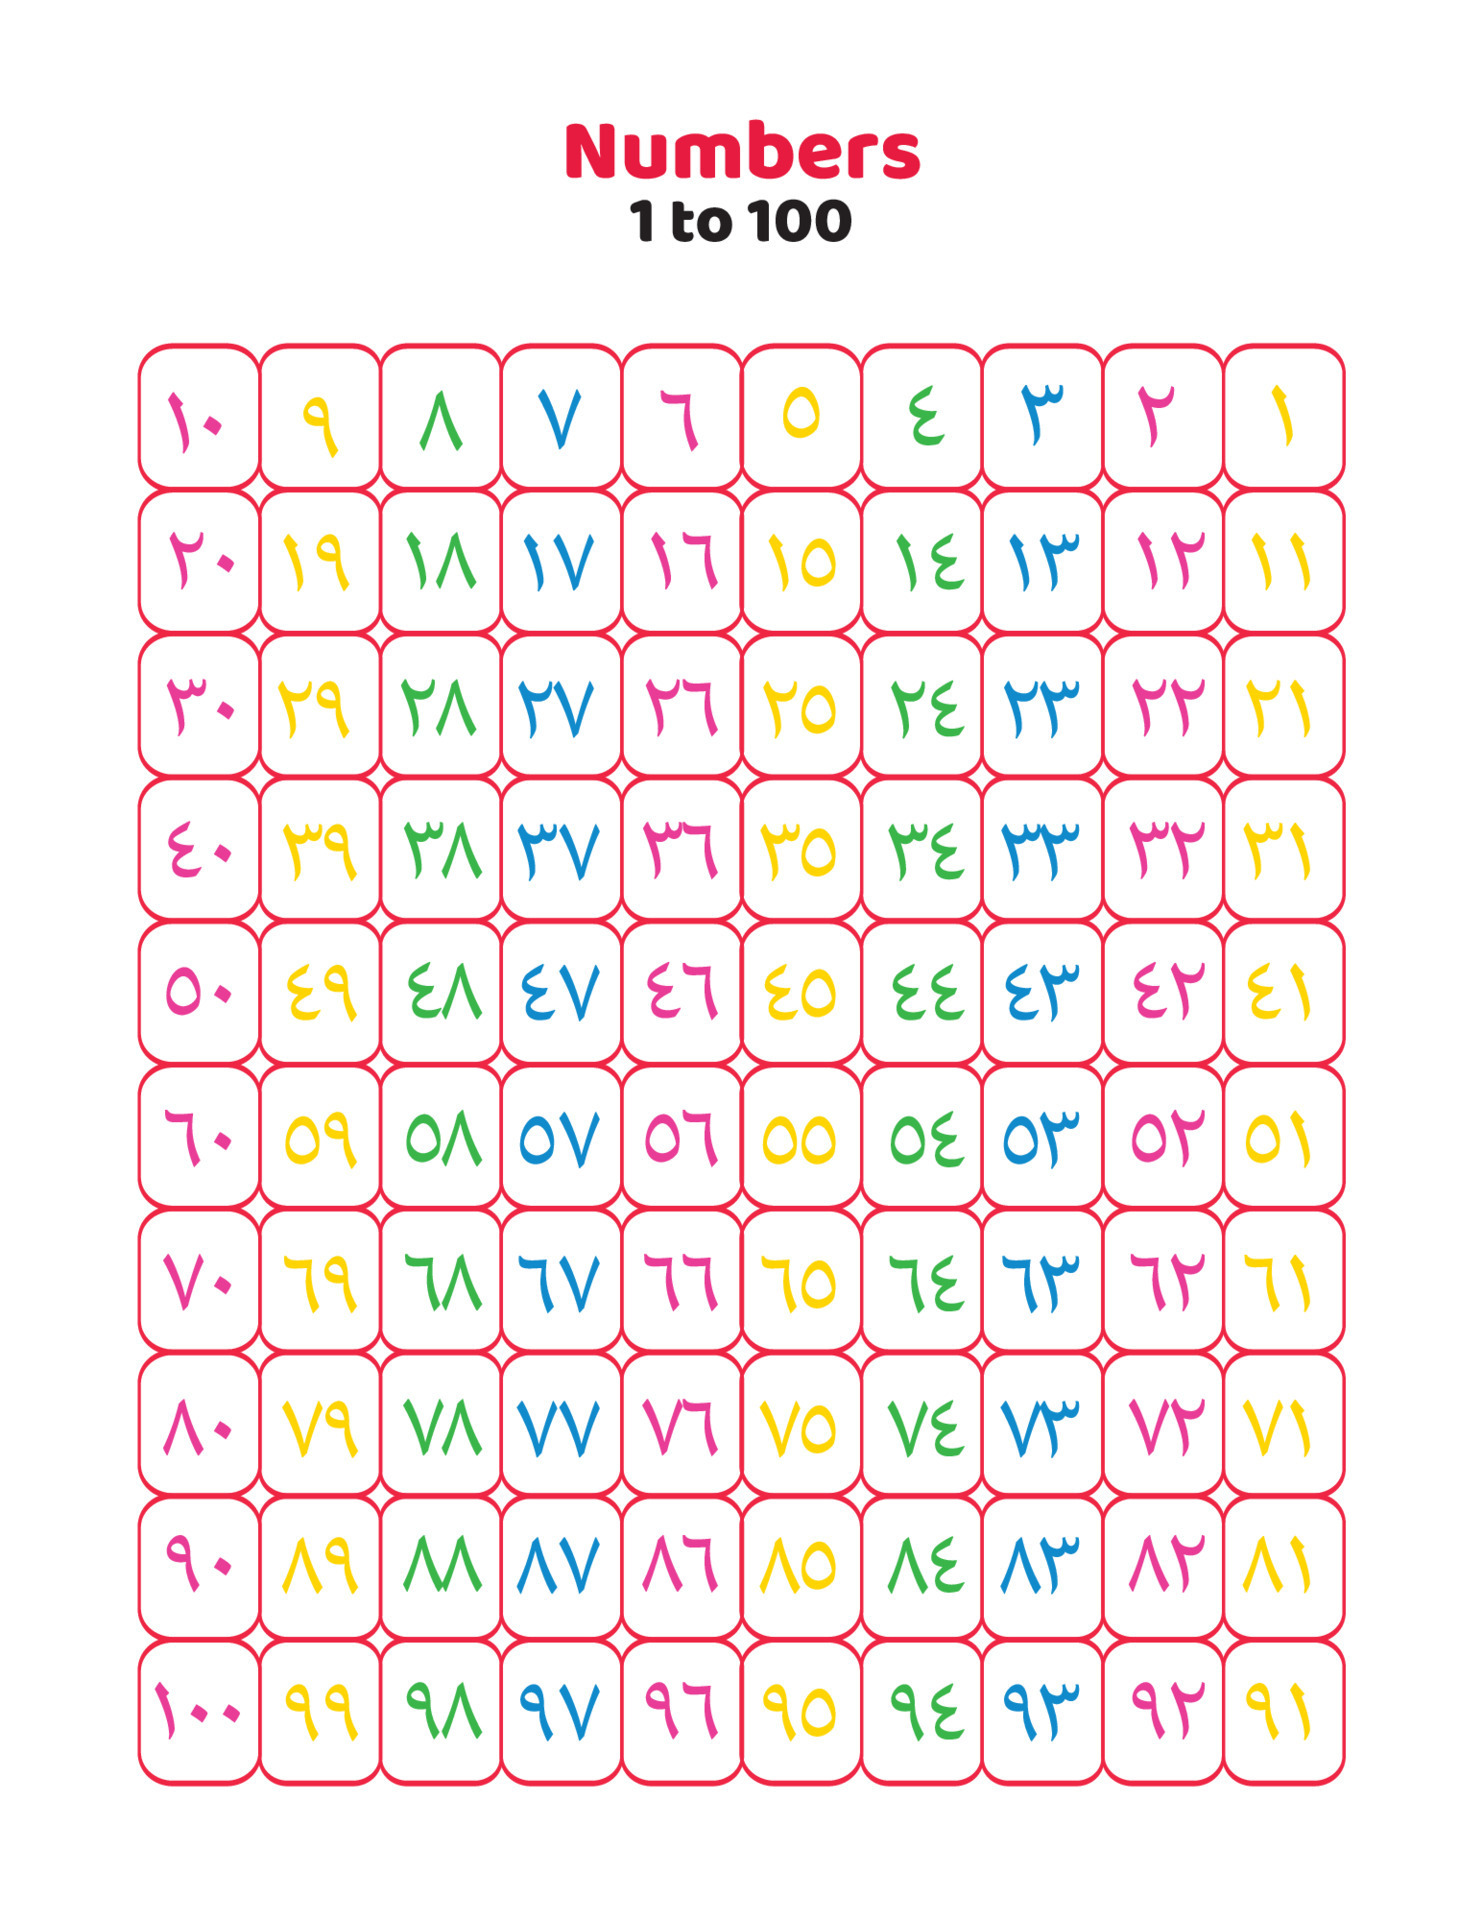
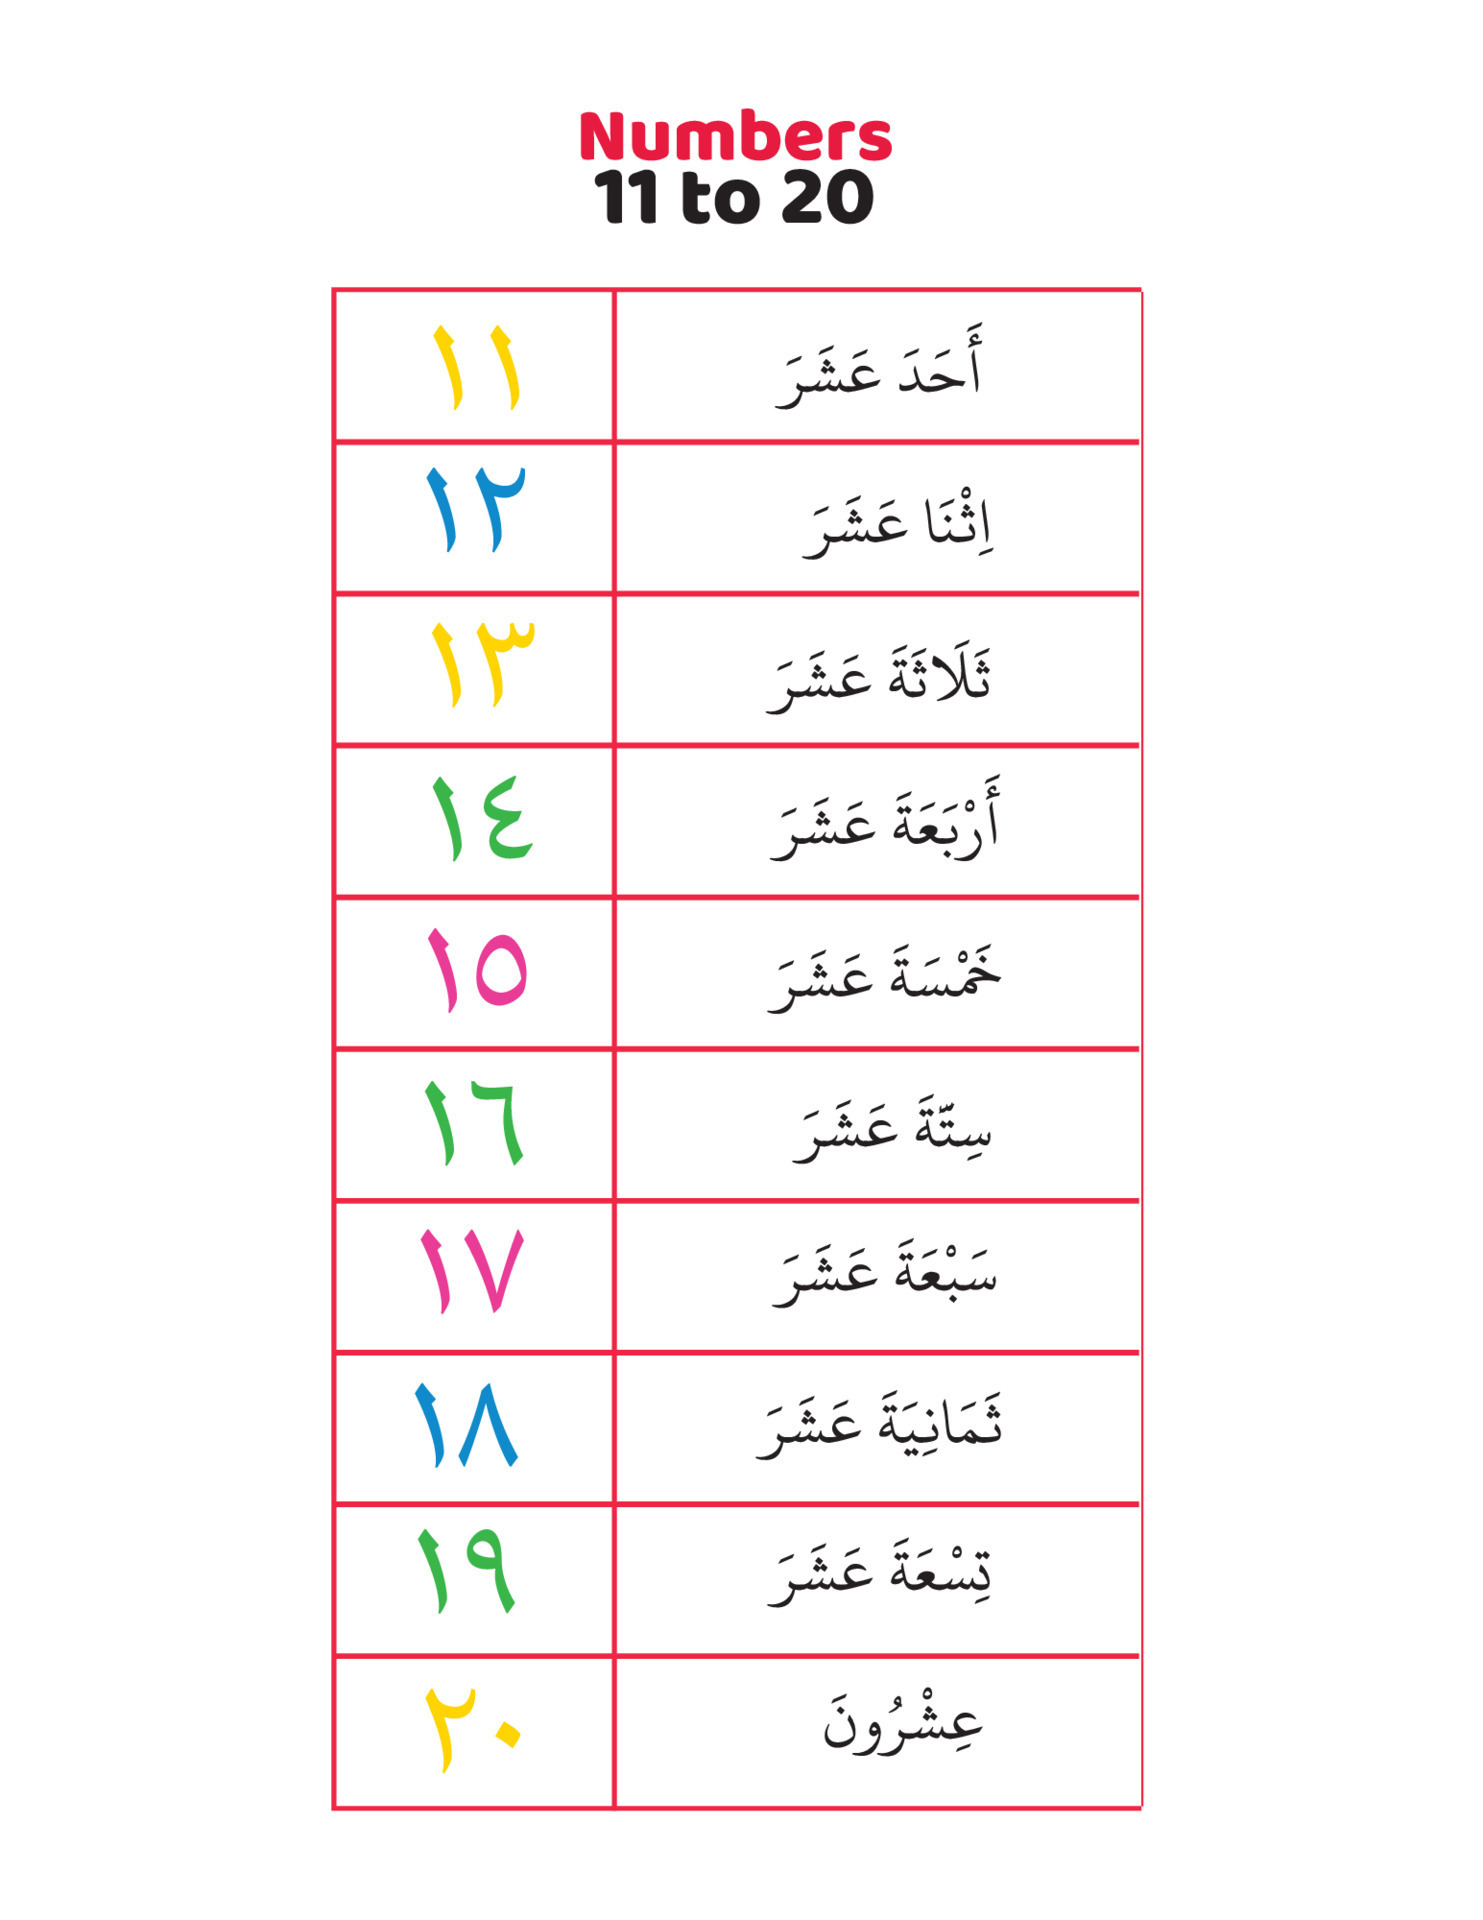
Most people don't realize there are two competing systems called "Arabic numerals." Western Arabic numerals are what we use in English-speaking countries — 0, 1, 2, 3, and so on. Eastern Arabic numerals, used across the Middle East, look completely different: . When someone asks about Numbers To Arabic Numbers conversion, they usually mean one of those two, sometimes both at the same time, and that ambiguity is where most tools break down. I spent a few years building number-formatting routines for a regional finance platform, and one of the first things I learned was that nobody checks the input encoding before running a conversion. You grab a string that looks like "" and run it through a standard Western-to-Western numeric parser, and it either spits out garbage or silently returns zero. The string isn't stored as Latin digits — it's stored as Eastern Arabic-Indic digits in Unicode block U+0660 through U+0669. A basic parseInt or Number() cast on a plain JavaScript string will just return NaN. You have to explicitly map the characters before anything downstream works.
How Numbers To Arabic Numbers Conversion Actually Works
The core mechanism is character-by-character mapping. For Western to Eastern Arabic conversion, each digit 0-9 maps to its U+0660-U+0669 equivalent. The reverse works the same way in the other direction. The tricky part is handling mixed input — a string like " 12 " contains both scripts, and a naive replace-all approach that targets only one block will leave the other untouched or, worse, corrupt it if you've got overlapping character ranges in your replacement table. Here's what a practical implementation looks like: ```javascript const westernToEastern = { '0': '', '1': '', '2': '', '3': '', '4': '', '5': '', '6': '', '7': '', '8': '', '9': '' }; const easternToWestern = Object.fromEntries( Object.entries(westernToEastern).map(([k, v]) => [v, k]) ); function convertNumbers(str, target) { const map = target === 'eastern' ? westernToEastern : easternToWestern; return str.replace(/[0-9-]/g, ch => map[ch] ?? ch); } ```
This handles mixed-input strings cleanly because the regex matches both Unicode ranges in a single pass. One substitution loop, no double-processing. I've seen people write two separate passes — one for each direction — and end up with half-replaced strings when the input already contained the target characters. That bug is hard to catch in unit tests because the test inputs are usually pure, not mixed like real-world data.
For locale-aware conversion, things get more complicated. Some regions use extended digits beyond the basic 0-9 block. Persian and Urdu use the same Eastern Arabic digit shapes but with different glyph renditions depending on the font. Arabic interfaces in apps often switch digit shapes contextually based on the surrounding text direction. A number embedded in a left-to-right English sentence may render differently than the same number in a right-to-left Arabic sentence, even though the underlying Unicode code points are identical. This isn't a bug — it's just how Unicode handles it. The renderer decides the glyph shape, not your string.
Get the Full Details

Edge Cases That Will Bite You
The biggest practical issue I ran into was date parsing. Many systems store dates as formatted strings like "//" in the Hijri calendar. If you convert those Eastern Arabic digits to Western before parsing, you get a valid Gregorian date — but only if your parser handles the Hijri-to-Gregorian translation correctly. Most standard Date objects in web browsers assume the input is Gregorian. So converting "" to "1445" and feeding it to new Date() gives you the year 1445 AD, not the Hijri year 1445. That's roughly 2024 in the Gregorian calendar, but the Date constructor doesn't know that. My workaround was to run the digit conversion first, then explicitly pass the resulting string to a Hijri-aware library like moment-hijri or umalqura before constructing any Date object. The conversion step is trivial. The calendar translation step is where everything falls apart if you skip it. Another edge case: superscript and subscript digits. Unicode has dedicated blocks for superscript (U+2070–U+2079) and subscript (U+2080–U+2089) numerals. These are technically distinct characters from the base digits, but some conversion tools don't account for them. A string like "m³" or "HO" won't match a regex looking for plain [0-9]. If your use case involves scientific notation or chemical formulas, you need to extend your character class to include those blocks as well.
When to Use Which Approach
If you're building for a general audience and need to display numbers in Arabic-language interfaces, server-side conversion during rendering is fine. The latency is negligible for small payloads. If you're processing large datasets — say, importing transaction records from multiple Gulf region banks where some columns use Eastern Arabic digits and others use Western — you should do the conversion in a batch pipeline before the data hits any database. I once watched a team try to do live conversion on every row read from a PostgreSQL query, and the response times went from 200ms to over 8 seconds as the table grew past a million rows. Database-level triggers or ETL steps solve this cleanly. For client-side applications where the user is typing in a mixed-script form, a real-time input converter that normalizes digits on the fly tends to work better than asking users to pick a format beforehand. It's smoother UX and reduces validation errors. The trade-off is that you're masking the user's input, which some accessibility advocates flag as a concern. Screen readers may announce the converted digit differently than what was physically typed. Test with NVDA or VoiceOver before shipping this in a production app.
What Breaks and What Doesn't
Simple digit substitution works for pure number strings. It also works reasonably well for mixed text where numbers appear as standalone tokens. It breaks down when numbers are part of a larger encoded value — credit card numbers, IDs, or barcodes where the digit script carries semantic meaning beyond the numeric value. Converting a barcode printed with Eastern Arabic digits to Western digits changes the physical representation enough that a scanner expecting the original script may reject it. Don't convert identifiers. Only convert values that are purely numeric in intent. There's no single download link for a reliable tool because this isn't really a software product — it's a character encoding problem that gets solved differently depending on your stack. Python has the arabic_reshaper and python-bidi packages for bidirectional text, but those handle text direction, not digit conversion. For actual digit conversion, a small custom function like the one above is usually faster and more transparent than pulling in a heavyweight library. Node.js, PHP, and Java all handle this the same way — explicit character mapping with a combined regex for both Unicode ranges. If you need a ready-made solution, the ICU library's number formatting routines handle digit substitution as part of their locale-aware formatting. It's overkill for a simple one-off conversion, but if you're building an i18n layer for an app that serves multiple Arabic-speaking regions, ICU saves you from reimplementing the same logic across every service. The library itself is maintained by the Unicode Consortium, so the digit mapping tables are current and cover all the variant forms.