Reading nutrient budgets in the field isn't as straightforward as the textbooks make it look
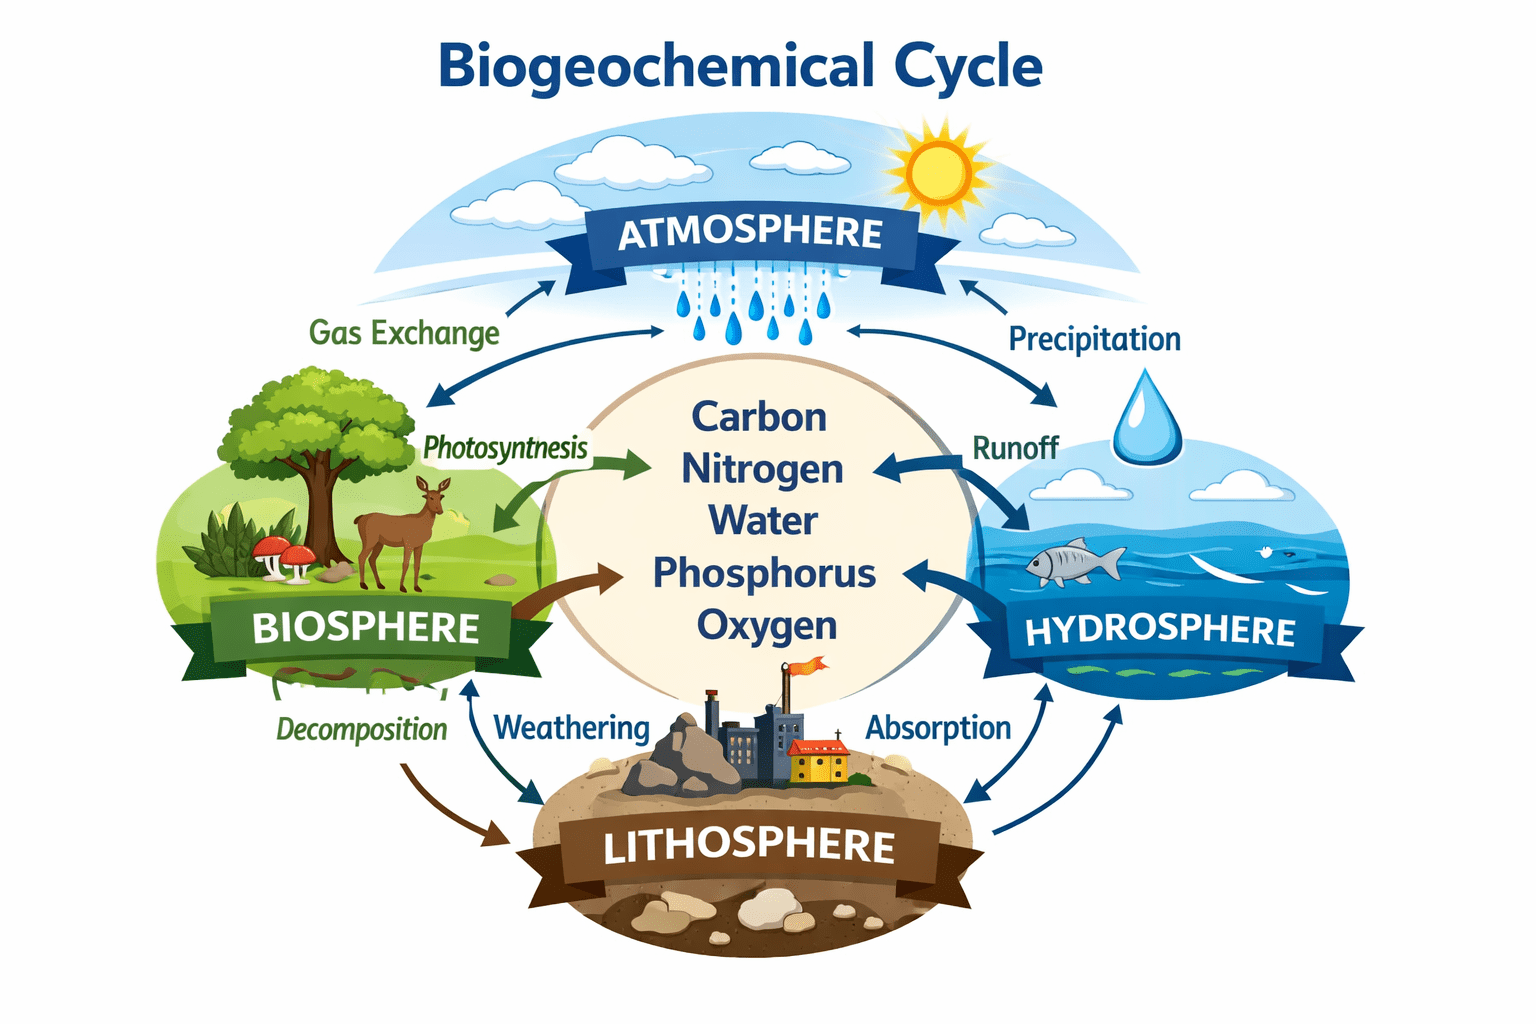
Most people learning about Nutrients In Biogeochemical Cycles start with clean, closed-loop diagrams. The nitrogen cycle chart you see in every high school biology book shows a neat loop: fixation, nitrification, assimilation, denitrification. Everything connects. Everything balances. That's useful as a starting point, but it's also mildly misleading because real ecosystems don't work that way. They leak. They accumulate. They stall out under certain conditions. I spent three seasons running nutrient budgets on a riparian wetland in western Washington, and the first thing that hit me was how wrong the closed-system assumption made my early calculations. I was trying to balance nitrogen inputs and outputs across a 40-hectare site, and the numbers just wouldn't close. Turns out, a chunk of the nitrate was cycling through a subsurface flow path that wasn't showing up on any of my monitoring wells. The water was moving through a gravel lens at about two meters depth, bypassing the surface stream entirely. I spent two extra weeks drilling test pits and installing piezometers before I even started to understand the hydrology well enough to model the nutrient transport correctly.
Why Nutrients In Biogetochemical Cycles are harder to track than you'd expect
The core issue is that biogeochemical cycles operate across multiple spatial and temporal scales simultaneously. A phosphorus atom might cycle through a plant, into soil organic matter, get buried in sediment, and then be released through weathering over millennia. Meanwhile, a nitrogen molecule could complete its entire transformation loop in a single rainy season. When you're trying to measure fluxes, you need to know which scale you're actually looking at. Mixing them up gives you garbage numbers. Here's something that trips up a lot of people: the difference between a cycle and a reservoir. The atmosphere holds about 800 gigatons of carbon as CO2. That's a reservoir, not a cycle. The actual cycling happens through photosynthesis, respiration, ocean exchange, and combustion. Understanding where matter sits versus where it moves is critical because your sampling strategy changes completely depending on which one you're trying to measure. A reservoir requires stock measurements. A cycle requires flux measurements. Using a stock-based approach for a flux-driven process will give you results that are off by orders of magnitude. On the phosphorus side, the cycle is what we call a sedimentary cycle, and that means it has a major bottleneck. Unlike carbon or nitrogen, phosphorus doesn't have a significant atmospheric phase under normal conditions. It moves from rock to soil to water to sediment and back through geological uplift, which takes millions of years. In practical terms, this means phosphorus is almost always the limiting nutrient in terrestrial and freshwater ecosystems. When you're modeling nutrient dynamics, assuming phosphorus behaves like nitrogen is one of the most common errors I see. It won't cycle fast enough to support that assumption in any ecosystem you'd actually study.
Practical approaches to measuring nutrient flux
Mass balance is the standard approach. You quantify inputs, outputs, and internal transformations, and the difference tells you what's accumulating or depleting. The equation is straightforward: Input minus Output plus Internal Production equals Change in Storage. In theory. In practice, each term in that equation is hard to measure accurately, and the errors compound quickly. I've found that isotope tracing gives you much cleaner data than bulk mass balance when you're dealing with complex systems. Stable isotopes of nitrogen, like 15N, let you distinguish between different nitrogen sources and track where that nitrogen actually goes. You can tell whether the nitrogen in a stream came from atmospheric deposition, fertilizer, animal waste, or soil organic matter mineralization. Without isotope data, you're basically guessing at source attribution, and those guesses are usually wrong by a significant margin. For phosphorus, the problem is worse because there aren't useful stable isotopes for routine field tracing. Phosphorus-33 is a radioisotope with a half-life of about 25 days, which makes it impractical for anything beyond controlled lab experiments. What people actually do in the field is use sequential extraction protocols to fractionate phosphorus into different chemical forms: orthophosphate, organically bound phosphorus, iron-bound phosphorus, aluminum-bound phosphorus, and calcium-bound phosphorus. Each fraction tells you something different about bioavailability. The water-extractable fraction is what organisms can use right now. The iron-bound fraction becomes available only when redox conditions shift, like during seasonal flooding. Knowing which pool you're looking at changes your entire interpretation of the data.
Get the Full Details

One technique that's underutilized but really useful is combining eddy covariance flux towers with soil chamber measurements. The tower gives you whole-ecosystem scale gas fluxes for CO2 and water vapor, while the chambers give you targeted nitrogen gas measurements at specific points. Cross-referencing the two datasets helps you validate whether the site-level measurements are actually representative of the broader area. I've seen people use chamber data from three sampling points to make claims about an entire watershed, and the spatial variability in that setup was typically a factor of four or five. That's not precision. That's a rough estimate with false confidence.
Common pitfalls that waste time and money
Seasonal timing is the biggest factor people ignore. Nitrogen mineralization rates can vary by a factor of ten between summer and winter in temperate forests. If you sample once in October and assume that represents the annual average, your budget will be significantly off. The same problem exists for phosphorus release from sediments, which peaks during spring turnover and thermal stratification breaks in lakes. Sampling at the wrong time doesn't just give you bad data. It gives you data you think is good, which is worse because you'll build models on top of it. Another issue is the assumption that biogeochemical cycles are balanced at the ecosystem scale. They rarely are. Nutrients accumulate in soils over decades. They accumulate in lake sediments over centuries. They leach into groundwater and eventually reach the ocean. The concept of a closed cycle is an abstraction that's useful for teaching but inaccurate for any real management decision. When I consult on watershed restoration projects, the first question I ask is always whether there's a net import or export occurring, not whether the cycle is balanced. The answer is almost never balanced. Soil texture creates a hidden problem for phosphorus cycling. Sandy soils have low phosphorus retention because they lack the clay minerals and iron oxides that bind phosphate. That means phosphorus applied as fertilizer leaches through quickly, but it also means the soil has minimal reserve capacity. You're constantly adding and losing phosphorus with little buffer. In contrast, clay-rich soils hold phosphorus tightly, sometimes making it unavailable to plants even when total soil phosphorus levels are high. This is called phosphorus fixation, and it's a major reason why soil tests that only measure total phosphorus are nearly useless for determining fertilizer needs. Available phosphorus tests, like the Olsen method for calcareous soils or the Bray method for acidic soils, are what you actually need.
What the models can't tell you
Process-based models like DAYCENT, DNDC, and biogeochemical models in the Century family are useful tools, but they have well-known limitations. They tend to overestimate nitrogen mineralization in cold climates because temperature response functions are calibrated on temperate data. They tend to underestimate phosphorus limitation because most of them treat phosphorus as a passive co-factor rather than an actively regulated nutrient. This is changing with newer models like FUN-DALSIM that include fungal dynamics and phosphorus regulation, but those models require far more input data than most practitioners have access to. The honest assessment is that no model replaces careful site-specific measurement. Models are best used to interpolate between your data points and to explore scenarios, not to generate estimates where you have no empirical data at all. I've reviewed reports where people ran a model with default parameters for an entire watershed and presented the output as measured data. That's not science. That's fiction with a graph. Long-term monitoring is the single most valuable thing you can do, and it's also the hardest thing to maintain. The Hubbard Brook Experimental Forest has been running nutrient budgets since the 1960s, and that continuity is what allowed them to detect ecosystem nitrogen saturation before it became a visible problem. Most sites don't have that kind of funding. If you're working with limited resources, focus on measuring the variable that has the highest uncertainty and the biggest impact on your conclusions, not everything equally. You'll get better answers faster that way.