Getting Started with Qualitative Analysis Without Losing Your Mind
Nvivo is one of those tools that sounds simpler than it actually is. You drop in interview transcripts, focus group recordings, survey open-ends, whatever you've got, and then you code it. That part is straightforward. The part where people run into trouble is everything after the initial data import. I spent roughly six months wrestling with a project that had about 40 hours of recorded interviews and somewhere around 120 transcripts when I really understood how this software works. It was not fun at the beginning. At its core, Nvivo is a qualitative data management and analysis program made by Lumivero. It handles text, audio, video, surveys, social media feeds, and some structural data types. You use it to code qualitative material, find patterns across coded segments, build frameworks, and generate reports or visualizations. It is not a statistical package. If you need SPSS or R for quantitative work, this is not going to replace it. It sits alongside that kind of work rather than competing with it. The interface has gotten less hostile over the years, but it still assumes you understand research methodology before you touch it. The menus do not walk you through your analytic choices. They wait for you to already know what you are doing and then provide the tools to do it. That is why beginners often feel stuck after their first hour.
For the download, you go straight to the Lumivero website at nvivo.qsrinternational.com. There is a free trial that runs for 14 days on Windows and Mac. If you are a student or researcher at a university, check whether your institution already holds a site license before buying anything. I found out about that the hard way after accidentally purchasing a license I did not need.
The Actual Workflow
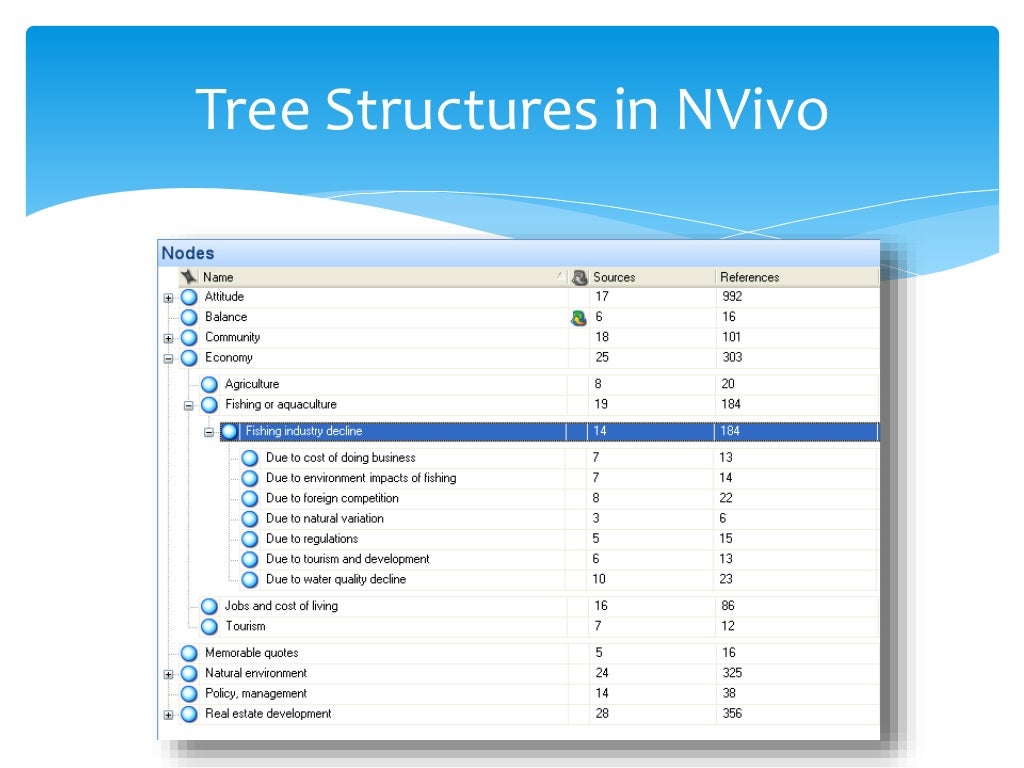
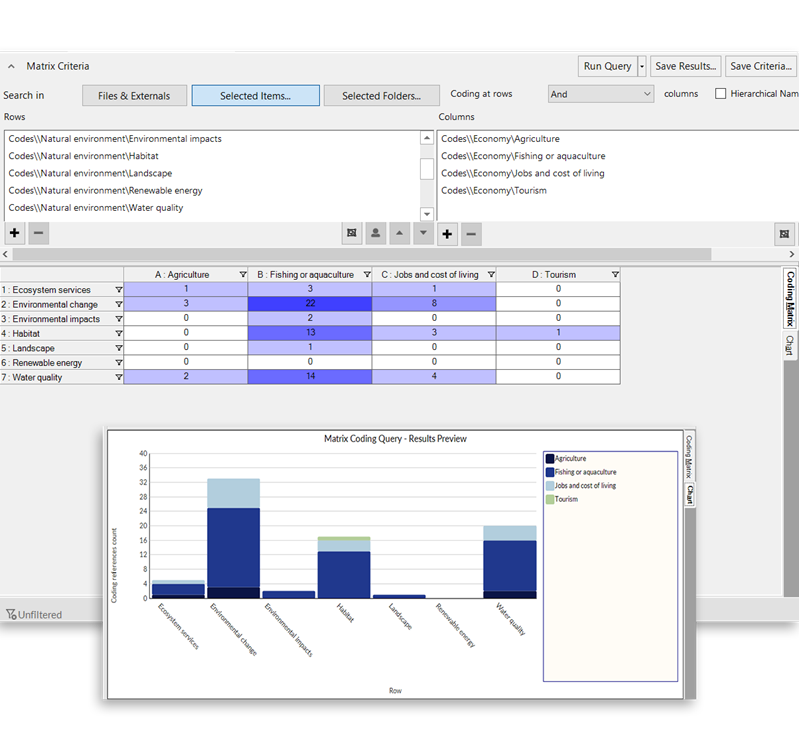
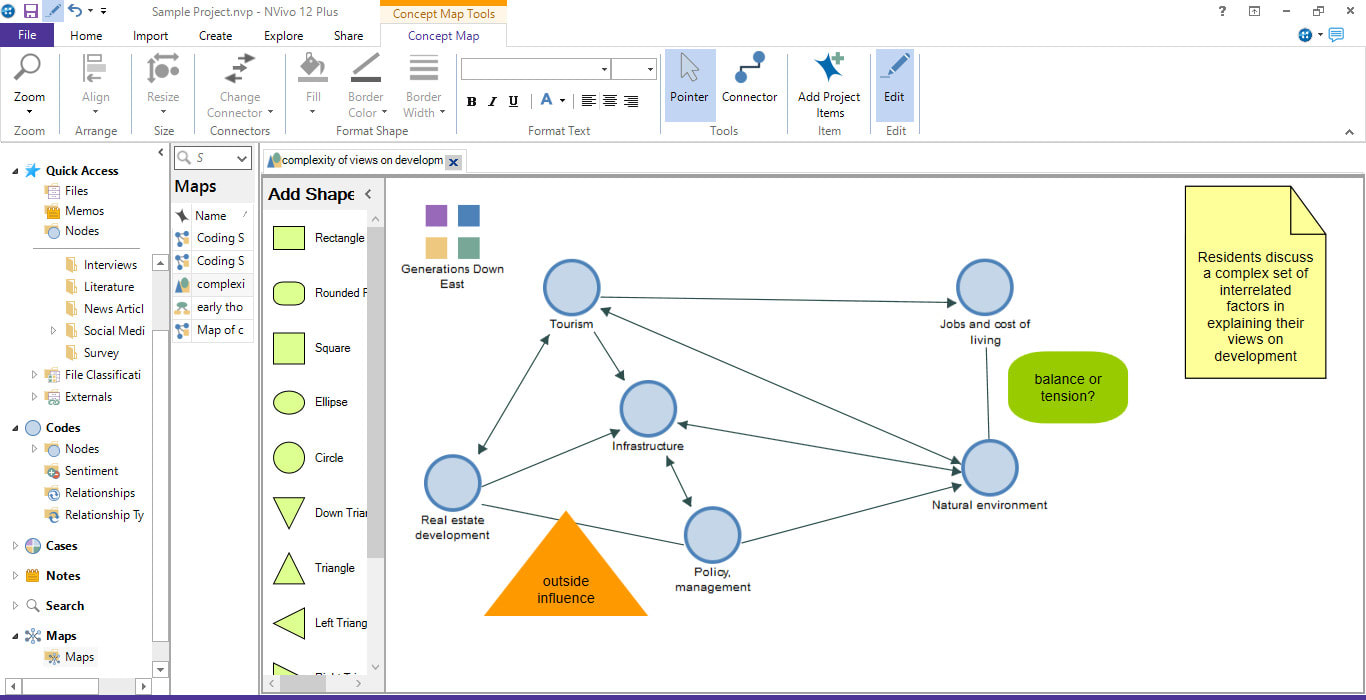
Import your data first. Nvivo supports PDFs, Word documents, audio and video files, Excel sheets, CSVs, and a handful of survey platforms. One thing beginners miss is that you can import from Google Drive, Dropbox, and Salesforce directly. If you are working with material scattered across five different cloud folders, use the direct import rather than downloading everything locally first. It saves time and keeps file paths consistent. Once the data is in, create a project structure. I recommend nodes organized hierarchically from the start, even if your coding framework is still forming. Start with broad thematic nodes and break them down as your analysis progresses. When I was working on that 40-hour interview project, I began with parent nodes like participant experiences, institutional barriers, and policy concerns, then subdivided each into child nodes. I also used cases to classify participants by attributes such as role, years of experience, and organization type. That attribute layer turned out to be the single most useful feature in the entire project. Coding happens by selecting text segments and assigning them to nodes. You can also drag text onto nodes or use keyboard shortcuts once you get comfortable. The search and query tools are where Nvivo earns its keep. Text searches, word frequency queries, matrix coding comparisons, and model visualizations are all built in. A matrix query comparing coded segments by case attributes usually takes about two minutes to run on a decent machine with a dataset under 100,000 words. Larger datasets will take longer, sometimes several minutes depending on your hardware.
Get the Full Details

When I hit a specific problem that nearly ended my project, it involved audio transcription accuracy. I was working with heavily accented interviewees and automated transcription came back with roughly 78 percent accuracy. Nvivo does have some built-in transcription assistance, but it is not enough for this level of distortion. What actually worked was exporting the audio to Happy Scribe, running the transcription there first, then importing the corrected text into Nvivo. The alignment between the transcript and the original audio file in Nvivo lets you play the segment while viewing the text, which makes verification fast. I spent maybe 20 minutes per interview doing this correction pass, which was far better than trying to code directly from poor auto-transcripts.
Things Beginners Get Wrong
The biggest mistake is treating coding like keyword searching. Coding requires interpretation. If you just search for the word fatigue and assign every match to a node, you are doing search, not qualitative analysis. Fatigue means something different when a participant says I am fatigued from commuting versus I am fatigued by the meeting schedule. The context matters. Nvivo lets you code the same segment to multiple nodes, so use that. Overlapping codes reflect the reality of qualitative data better than rigid single-category assignments. Another common error is creating too many nodes too early. People make 50 nodes in the first week and then spend three weeks reorganizing them. Start with eight to twelve nodes, code for a couple of weeks, then restructure. The nodes will reveal their own hierarchy as you code. Forcing a framework onto raw data before you have read it thoroughly is a fast track to wasted effort. Documentation is another area where people skip ahead. The audit trail feature in Nvivo is not decorative. It records every coding decision, memo, and query you run. If you ever need to justify your methodology to a reviewer or supervisor, that log is what they will ask for. Turn it on immediately and keep it updated. I learned this after a peer reviewer asked me to show my coding decisions and I had essentially no paper trail because I had been coding for three weeks before remembering to enable the feature.
Performance Limits and When to Look Elsewhere
Nvivo can handle large projects, but there are practical limits. On a standard laptop with 16 gigabytes of RAM, you should expect smooth performance up to roughly 200,000 words of text or about 10 hours of audio and video. Beyond that, queries slow down noticeably, and the software may freeze during certain operations. If you are working with massive datasets, you have a few options. You can split the project into themed sub-projects and merge them later, or you can use the cloud-based Nvivo clouds, which offloads some of the processing. I find the sub-project approach more reliable because merging sometimes introduces node naming conflicts. There are also genuine limitations that no amount of training fixes. Nvivo is not designed for mixed-methods integration in the way some other tools allow. If your project requires tight coupling between coded qualitative segments and statistical outputs, you will need to export your Nvivo results and work in another environment. The export features exist, but the round-trip workflow is clunky. Factor that in before committing to Nvivo as your sole tool. Another scenario where Nvivo struggles is multilingual projects with heavy switching between languages in the same transcript. The coding interface works, but the query tools and word frequency features are optimized for English-language text. You can still code in multiple languages, but reporting becomes more labor-intensive. If bilingual or multilingual analysis is central to your work, you might want to test the software with a small pilot dataset before purchasing a full license.

Pricing runs around 1,639 dollars for a single-user perpetual license on Windows or Mac, with annual subscription options available at lower upfront cost. Academic pricing is significantly reduced, often around 400 to 600 dollars depending on the license type. The subscription model makes sense if you only need the software for a year-long project, while the perpetual license is worth considering if you plan to use it across multiple projects over several years.
Should You Use Nvivo Qualitative Data Analysis Software
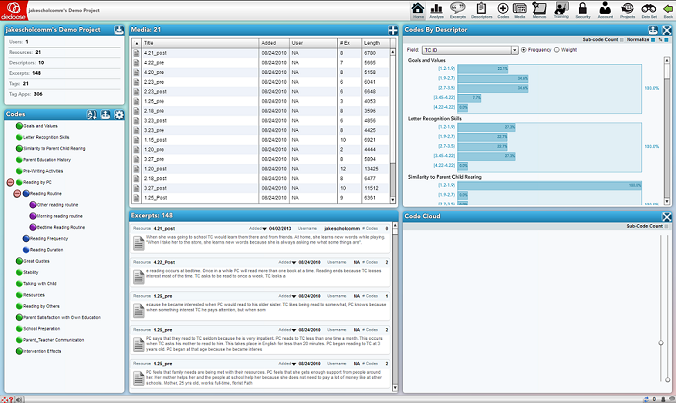
It depends on what you are actually doing. If you have structured qualitative data and need systematic coding, querying, and reporting, Nvivo is one of the more mature options available. It is not the only option, and for some workflows it is not the best option. Atlas.ti handles multimedia projects more fluidly. Dedoose is better if you need real-time collaborative coding across remote team members. MaxQDA is lighter and faster on lower-end machines. The main reason people choose Nvivo is familiarity within their discipline and the depth of existing tutorials and training materials. That ecosystem matters more than raw feature comparison when you are on a tight timeline. If your department already uses Nvivo and your advisor is comfortable troubleshooting it, that practical advantage outweighs the marginal differences between programs. The learning curve is real but manageable. Expect roughly two weeks of regular use to reach basic competence and another month before you feel efficient with queries and matrix comparisons. During that first month, your productivity will feel slower than it should because you are constantly navigating menus you have not yet memorized. That is normal. Do not switch tools mid-project just because the interface feels awkward in week two. The awkwardness fades faster than people expect, and the alternative is losing all the project setup you have already done.
Start small, code a few transcripts manually before relying on automated features, keep your memo logs current, and do not overbuild your node structure on day one. The software will do what you tell it to do. The challenge is figuring out what you actually need it to do.