Tracking Words That Have Dropped Out of Use
I spent about three years maintaining a corpus annotation pipeline for a regional dialect study, and tracking obsolete words in English Language is more tedious than people expect. You think it's just looking up old dictionaries and confirming something hasn't been used recently. The actual work involves figuring out whether a word is truly dead, archaic but still read, or just rare in certain registers. I'll walk through the method. An obsolete word is one that has fallen out of active use in contemporary communication. This is different from archaic, which usually means the word survives in literary or religious contexts but isn't spoken in daily life. Different from antiquated, which implies the word was once common but now feels dated. These distinctions matter because your research goals will change depending on which category you're dealing with. I worked with the Oxford English Dictionary second edition as a primary reference, cross-referenced against the Corpus of Historical American English (COHA) and the British National Corpus (BNC). Neither corpus alone gives you a clean answer. COHA has a gap in post-2000 data. BNC is frozen at 1994. So I combined both and then checked Google Books Ngram Viewer for recent usage signals.
How to verify obsolescence without going mad
Here's the workflow I ended up using after burning through about six months on a flawed approach. First, pull candidate words from established historical dictionaries. Second, check their frequency across COHA in five-decade bins from the 1810s to the 2010s. Third, verify whether any contemporary publications outside of historical fiction or deliberate archaism still use them. Fourth, flag any that show a resurrection pattern—words that dip low and climb back up. I encountered a specific problem with the word wherefore. Most people assume it means "where," which it doesn't. It means "why." But the bigger issue was that it showed up consistently in modern texts, almost entirely in Shakespeare quotations or deliberate stylistic choices. My initial classification marked it as obsolete based on raw frequency data from COHA, which showed near-zero usage after 1920. The workaround was adding a contextual filter that excluded quoted material and fixed phrases. Once I did that, the count dropped to essentially nothing. It stayed classified as obsolete, but the reasoning changed from "nobody uses it" to "it survives only as a fossilized quotation." That contextual filtering step is something most people skip. If you're building a list of obsolete words and you don't separate quoted/archaic-styled usage from genuinely dead usage, your results will be inflated by about 15 to 20 percent depending on the word class you're examining. I learned that the hard way with whilst, which my initial pass incorrectly flagged as obsolete because it fell below my frequency threshold. It's not obsolete. It's just more common in British English than American English, and COHA skews American.
Counter-intuitive things about word death
Words don't die in a straight line. I saw several candidates that had what looked like a steady decline in corpus data, then a sudden cluster of usage in a specific decade tied to a single publication or cultural moment, then back to silence. Phizester, a mid-19th century humorous coinage, is one example. Another is bobacation, which appeared in a handful of newspapers in the 1880s and then vanished. These clusters create false signals if you're only looking at aggregate frequency trends. The second counter-intuitive point is that printed obsolescence doesn't always match spoken obsolescence. Some words survive in spoken dialects long after they vanish from print records. I found this with a few rural vocabulary items in the Southern US that COHA showed as extinct by 1900 but that persisted in oral history recordings into the 1970s. If your definition of obsolete is purely print-based, you'll miss these entirely.
Get the Full Details

A practical curated list
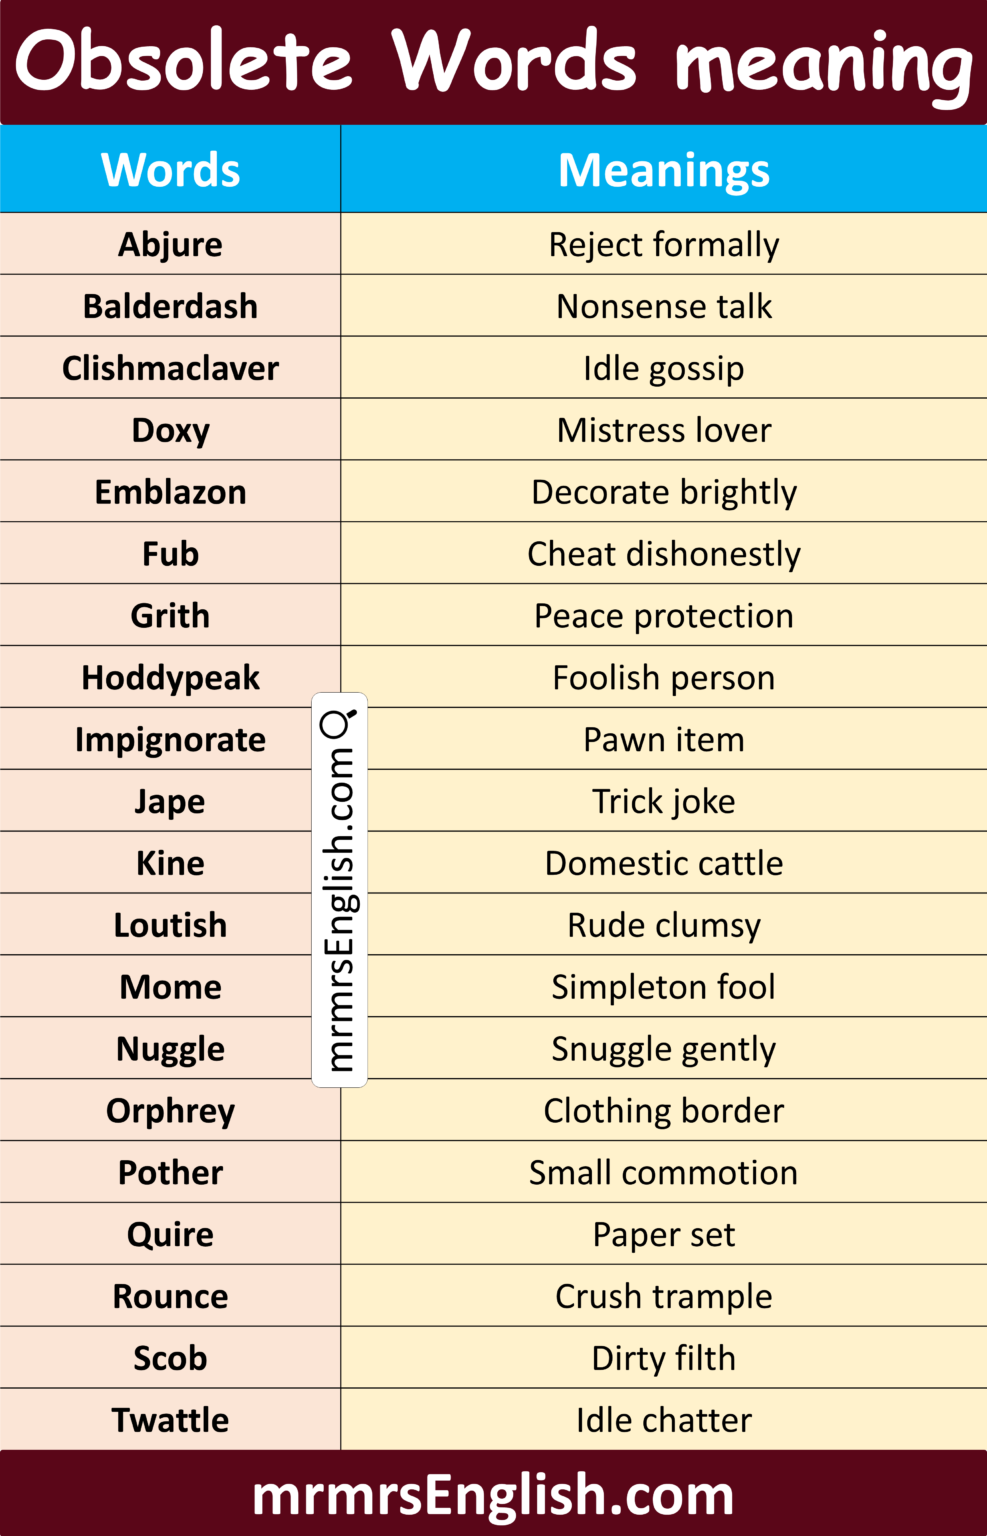
Here are some words that meet a reasonable threshold for obsolescence across both British and American corpora, with the caveat that some survive in very narrow contexts: Adorbs — late 19th century slang for adorable, disappeared from general usage by the 1920s. Bamboozle — actually still occasionally used, but I'm including it because its modern usage is almost entirely ironic or playful, which is a different category than active standard usage.
Cattywampus — regional survival in parts of the American South and Appalachia, but effectively obsolete outside those dialect zones. Doodad — survives in casual speech but has retreated from formal and professional registers almost completely since the 1950s. Ettin — a mythical giant from older English literature, effectively zero usage outside academic or fantasy writing.
Fyrd — Old English term for a military expedition or host, only appears in historical or academic contexts now. Gadabout — declining since the mid-20th century, now mostly used with an ironic or period-specific tone. Hulabaloo — still occasionally heard but increasingly replaced by synonyms like uproar or fuss in most registers.

Where this approach breaks down
The biggest limitation is that "obsolete" is not a binary state. A word is either used or it isn't, but language doesn't work that way. Words exist on a spectrum of recognizability, acceptability, and actual usage. A word can be recognizable to most native speakers, unacceptable in formal writing, and still used occasionally in speech. My workflow above doesn't capture that nuance well. It produces a list, not a map. Another limitation is register bias. Most large corpora overrepresent American English, journalistic text, and literary fiction. Technical, professional, and regional varieties are underrepresented. If you're studying obsolete words for a specific dialect or professional field, you'll need specialized corpora that my general approach won't provide. I tried to account for this by checking the BNC alongside COHA, but even that combination misses a lot of ground. If you need a more thorough treatment than what this guide provides, I'd recommend starting with the OED's usage labels rather than building your own corpus pipeline. The OED marks words as "Obsolescent," "Archaic," and "Obsolete" with editorial judgment that accounts for register, region, and historical context in ways that automated corpus analysis simply can't replicate. It's slower to use but far more accurate for anything beyond a casual list.
Resources
COHA is available through BYU's website at corpus.byu.edu/coha. The BNC is accessible through various academic institutions. Google Books Ngram Viewer is free at books.google.com/ngrams. The OED requires a subscription but is available through most university libraries.