A Practical Guide to Odds Ratios and Relative Risk in Epidemiology
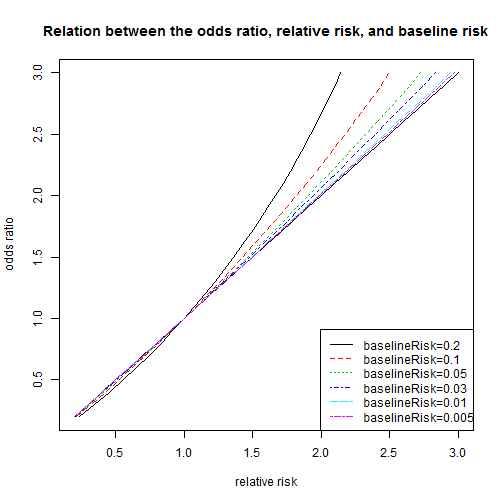
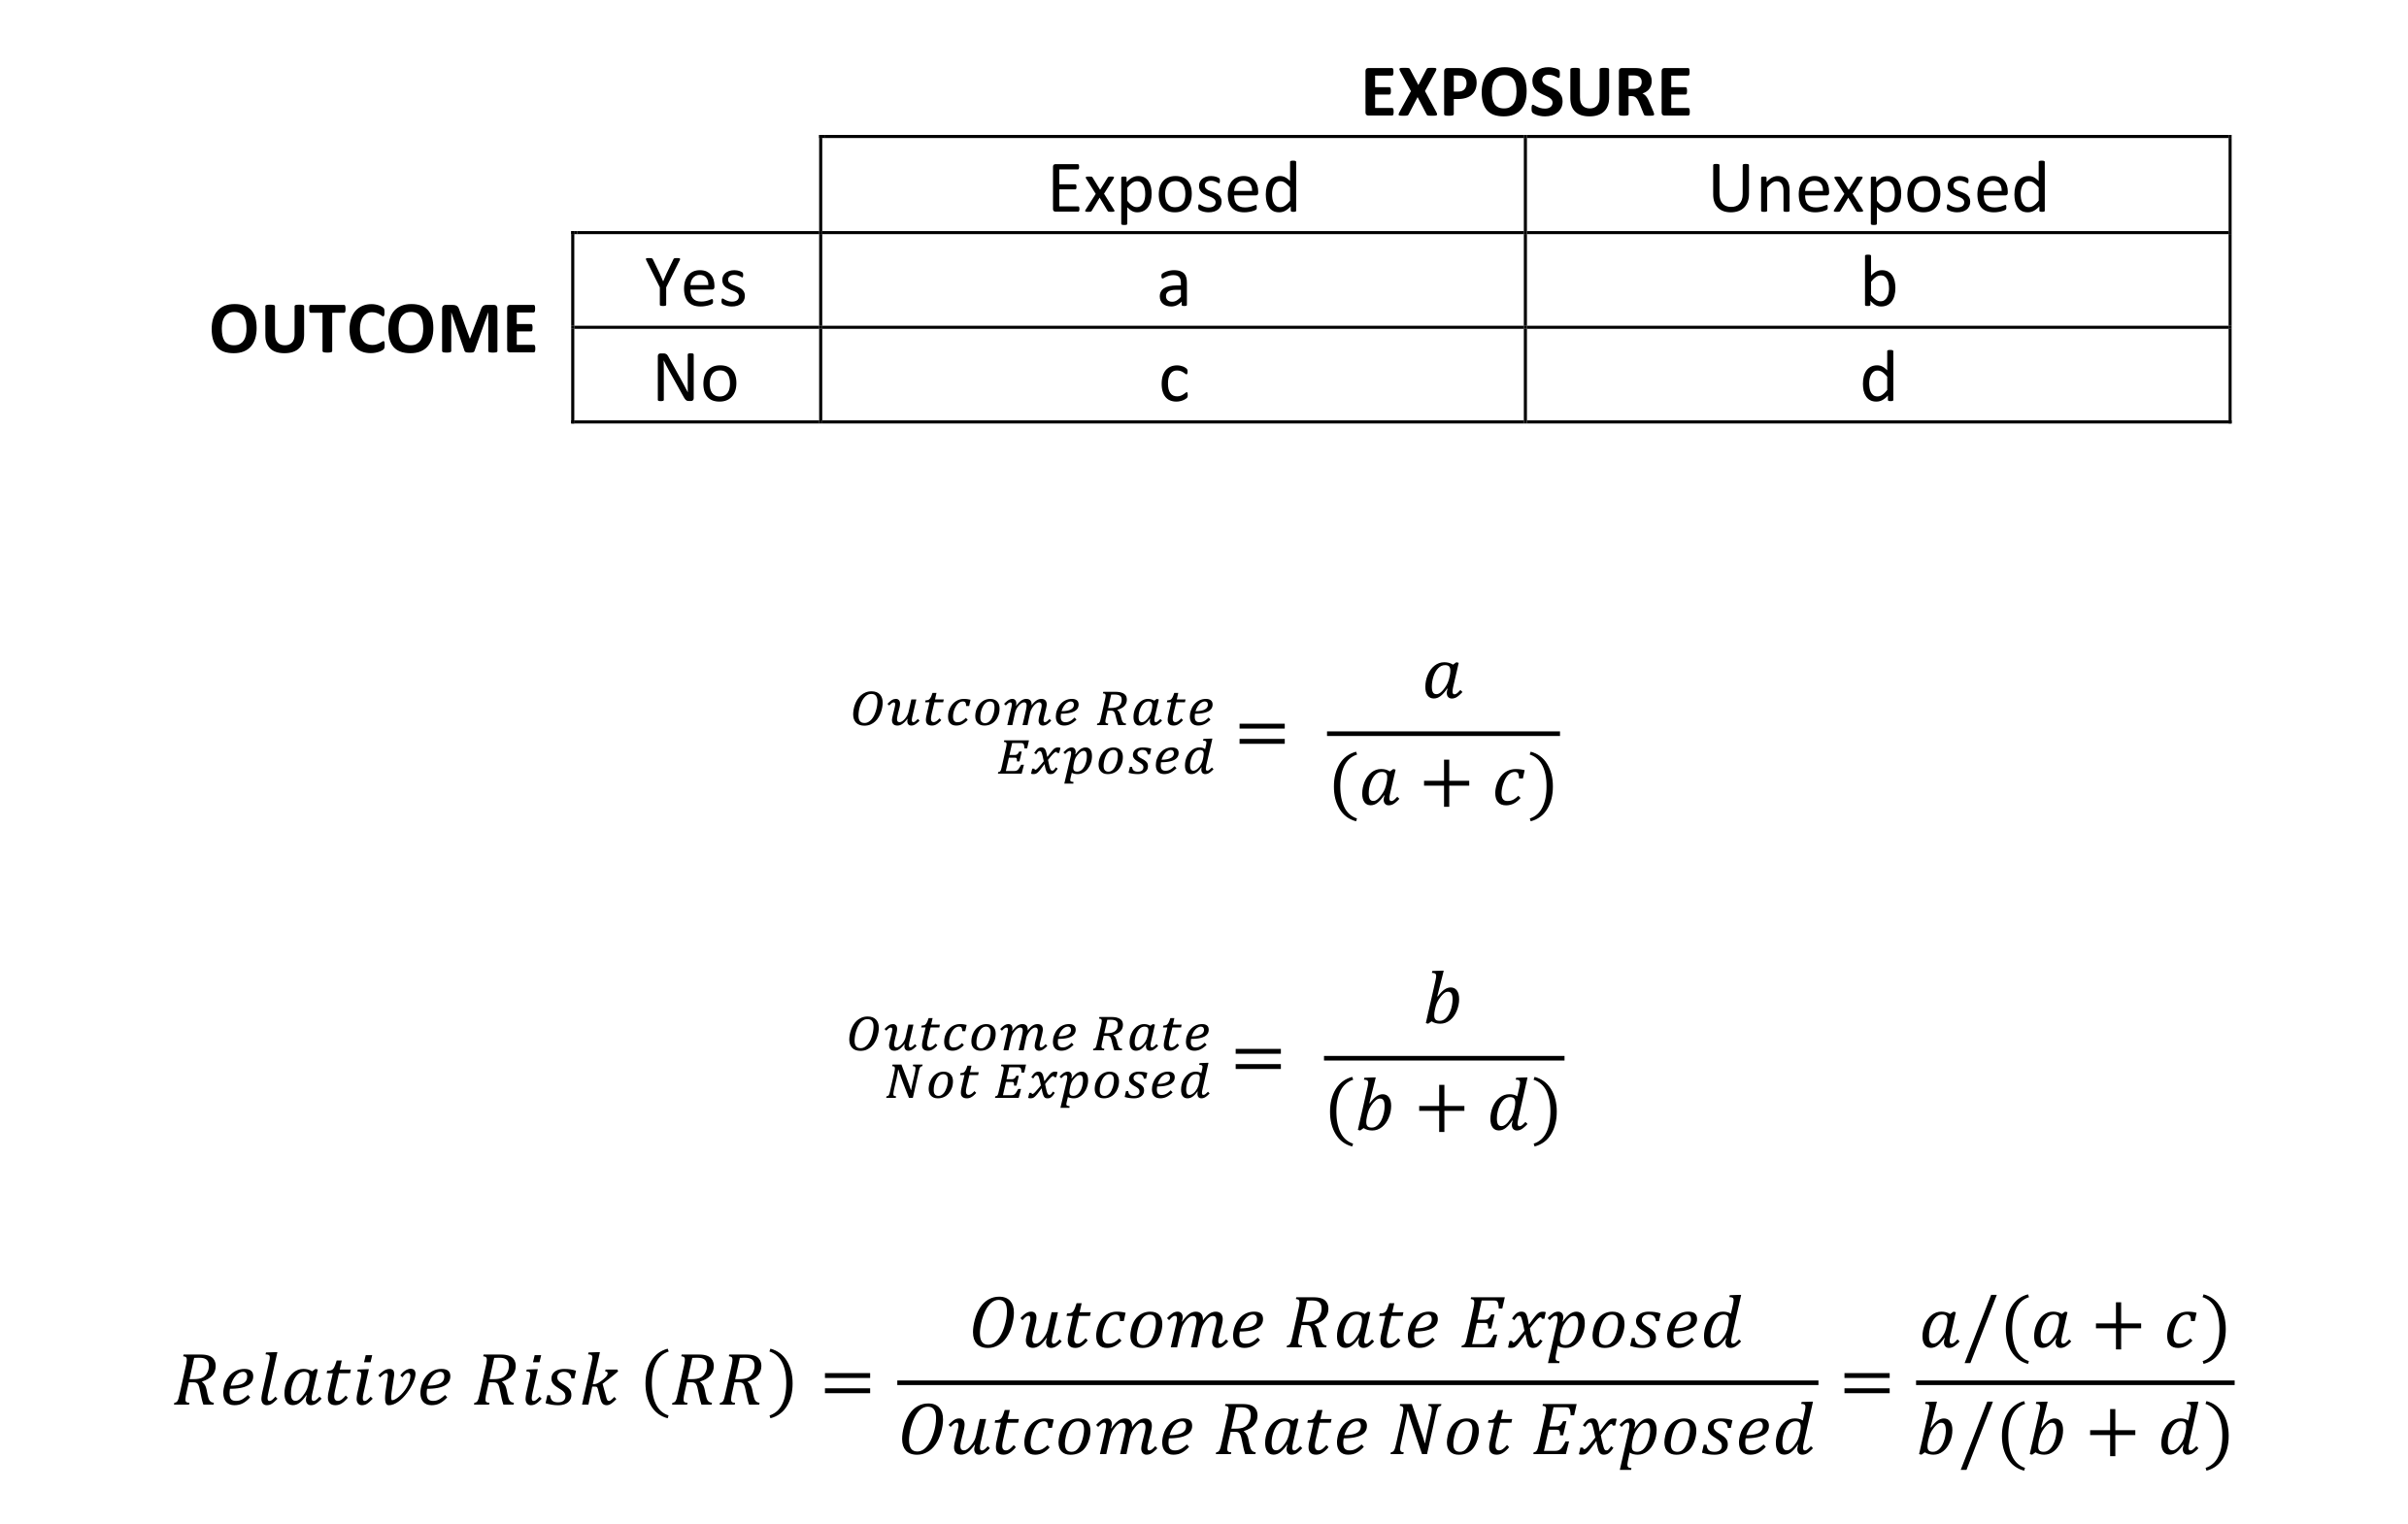
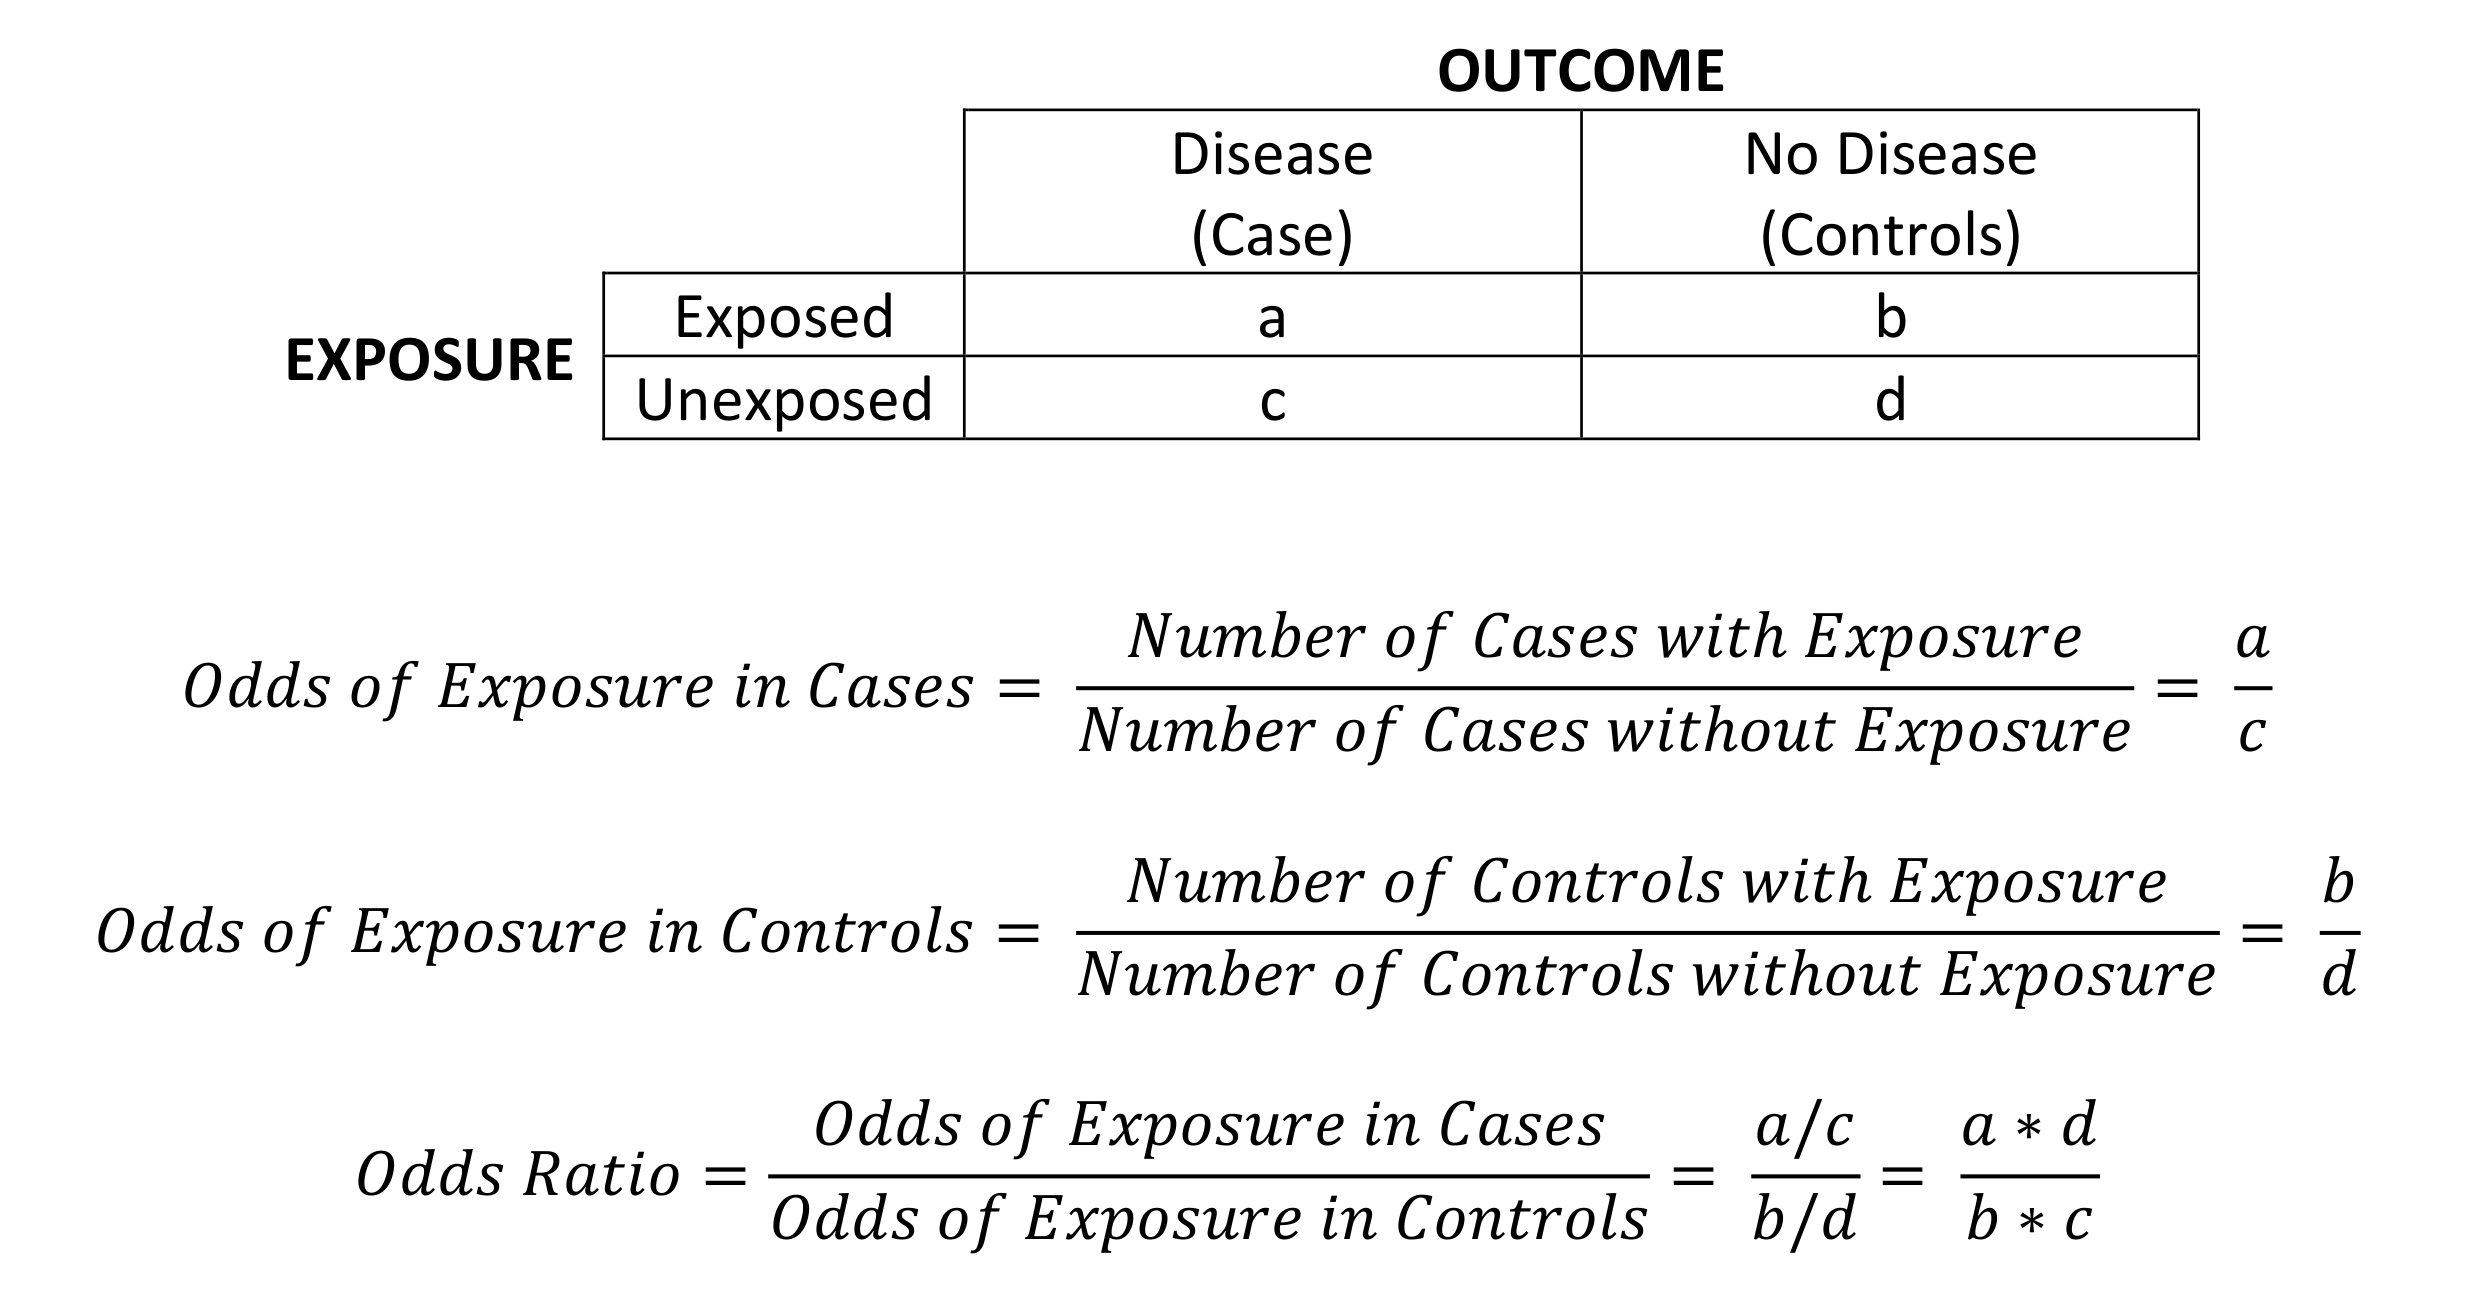
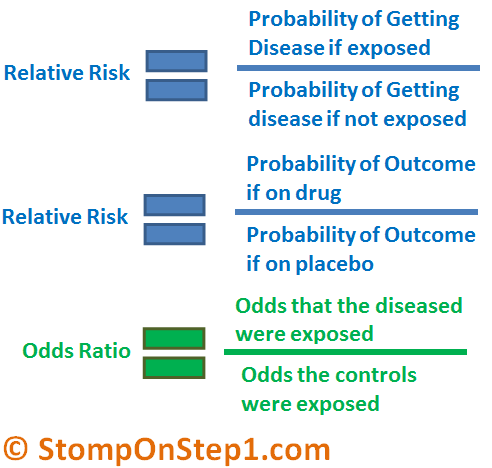
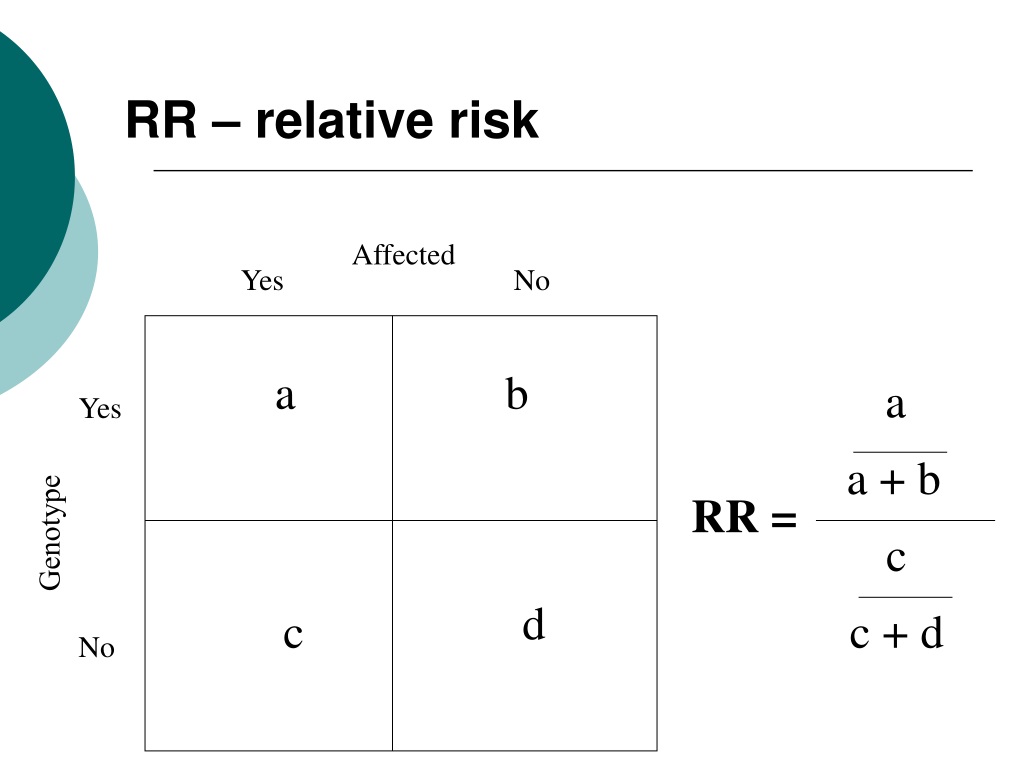
I deal with these every day in my work reading and designing studies, and honestly, they still trip people up more than any other basic concept in biostats. Let me walk through how they work in practice, not just textbook definitions. The odds ratio is what comes out of a logistic regression model. It's calculated as (a/b) / (c/d) where a is exposed cases, b is exposed non-cases, c is unexposed cases, and d is unexposed non-cases. The relative risk is simpler in theory — it's just the incidence proportion in the exposed group divided by the incidence proportion in the unexposed group: [a/(a+b)] / [c/(c+d)]. Both tell you about association strength, but they answer slightly different questions and their numerical values diverge as outcomes get more common. Here's the thing nobody warns you about early enough: when the outcome is rare, OR approximates RR well. But once outcome prevalence hits anything above 10%, the odds ratio starts overestimating the relative risk significantly. I remember working on a cardiovascular study back in 2019 where the published odds ratio was 1.8 for a particular exposure, but when I recalculated the relative risk from the raw contingency table, it was closer to 1.3. The outcome incidence in the cohort was about 22%, which is absolutely not rare. The journal reviewers almost missed it because the OR looked substantively meaningful on its own.
The workaround I use now is straightforward — I always compute both and flag the discrepancy in any manuscript or report I produce. For prospective cohort studies and randomized trials, relative risk is the preferred measure because the denominator is well-defined. Odds ratios make sense in case-control studies where you can't estimate incidence directly. But I've seen too many researchers blindly report odds ratios from cohort data and pretend they're equivalent to risk ratios without checking. If you need to convert an odds ratio to an approximate relative risk, there's a formula: RR OR / [(1 - P0) + (P0 × OR)] where P0 is the baseline risk in the unexposed group. This comes from Zhang and Yu, 1998. It's not perfect but it's better than nothing when you only have an odds ratio reported and need a risk interpretation. The conversion breaks down when P0 itself is uncertain or poorly estimated. In R, if you want relative risk directly from a glm framework, you can fit a binomial model with log link instead of the default logit. It doesn't always converge cleanly though — that's a real practical headache. I've had models fail to converge because the log link pushes fitted probabilities outside the [0,1] interval during iteration, whereas the logit link keeps everything bounded. For those cases, a sandwich robust variance estimator on the logit model sometimes helps, or you just fall back to the Zhang-Yu approximation.
The main pitfall I see repeatedly is interpreting an odds ratio of, say, 2.0 as meaning the risk doubles. That's only approximately true at low outcome frequencies. At higher frequencies, the same OR of 2.0 could correspond to a much smaller relative risk. In a 2021 meta-analysis I reviewed, twelve out of forty-seven included studies reported odds ratios but the outcome prevalence across them ranged from 5% to 35%, meaning roughly a third of those estimates were materially misinterpreted as risk ratios by the original authors. That's not a trivial error margin. Another thing worth noting: the odds ratio has a mathematical property that makes it invariant to how you slice your data. If you condition on different covariates in a logistic model, the odds ratio for a given exposure stays the same in the population average sense, whereas the relative risk does shift depending on which confounders you adjust for. This is part of why logistic regression and odds ratios remain so entrenched in epidemiology — they're stable estimands even when the underlying risk structure is messy. But stability isn't the same as interpretability, and that's the tension you're always working with.
Get the Full Details
When to Use Which Measure
Use relative risk when you have a cohort or trial design and want results that clinicians and patients actually understand. A risk ratio of 1.5 means one in three people read this as a fifty percent increase in risk. It maps directly to how people think about disease. Use the odds ratio when your study design forces you to — case-control studies, or when you're running a standard logistic regression and don't want to wrestle with convergence issues from a log-binomial model. And always, always check whether the outcome is rare enough for the approximation to be defensible. There's no shortcut around that check. I typically include both measures in my outputs whenever possible. If I'm reporting an odds ratio, I make sure to state the baseline risk and the corresponding relative risk alongside it. It takes about three extra minutes of work and it prevents the single most common miscommunication in the literature. Most statistical software packages let you do this — in Stata, the cloglog command or margins after logistic will give you both. In R, using the riskRegression package handles the conversion and uncertainty estimation cleanly. One last note on sample size: power calculations based on odds ratios versus relative risks will give you different required sample sizes when the outcome is common. If you plan your study around an expected odds ratio but the true effect is better expressed as a risk ratio, you might be underpowered. I learned this the hard way on a diabetes prevention trial where our power calculation assumed a rare outcome approximation, the control group event rate turned out to be 18%, and we ended up with 85% power instead of the planned 90%. Not catastrophic, but fixable if you catch it before data collection starts.
There's no universal rule that one measure is better than the other in every context. The right choice depends on your study design, outcome frequency, analytical model, and who needs to read your results. The wrong choice is picking one blindly and never checking the assumptions.