Working Through Spatial Data in Human Geography: What Actually Happens When You Open QGIS
You open the software, load your shapefiles, and immediately notice that the census tract boundaries from the last decade don't line up with the parcel data from the county assessor. This is the starting point for Of Analysis Human Geography in practice. It's not glamorous. It's mostly cleaning data until it behaves. Start by deciding what question you actually have. Most people skip this and jump straight into mapping because they have data and a deadline. The map comes later. Write down the specific relationship you're testing: does proximity to transit correlate with housing cost increases, controlling for neighborhood income? Once that's written down, the rest of the process takes about twenty minutes less per dataset because you stop exploring aimlessly. I tend to use QGIS for most human geography spatial work, with R or Python scripts for the statistical portion. ArcGIS Pro is fine if your institution has a license, but it adds about fifteen percent overhead in licensing costs for no measurable difference in output quality on typical human geography projects. QGIS handles the spatial joins, overlays, and basic geoprocessing without requiring a budget committee meeting.
Here's what a standard workflow looks like when it goes smoothly, which is maybe forty percent of the time: Step one: gather your data sources and note their coordinate reference systems. CRS mismatches are the most common problem I encounter, and they produce incorrect distances and areas without any warning message. If your census data is in NAD83 and your street network is in a state plane zone, your buffer analysis will be wrong by enough to matter. Reproject everything to a common CRS before doing any spatial operation. Step two: clean the attribute tables. Remove duplicate geometries, fill null values where it makes sense, and recode variables that use inconsistent naming conventions. A column labeled "Pop_2020" alongside another labeled "population2020" in the same dataset is a red flag that someone combined shapefiles without checking field names.
Step three: perform your spatial operations. Buffer, clip, intersect, union, dissolve. These are the bread and butter tools. I usually start with a small test area before running them on the full extent. That saved me about six hours last fall when an intersect operation was going to run for three hours on a 12GB feature class because I hadn't noticed a malformed polygon in the boundary layer.
Get the Full Details

The Part Nobody Talks About: Geocoding and Address Matching
Address geocoding is where most student projects go sideways. You download crime data from a city website, every record has an address, and you think you're set. The addresses are formatted inconsistently. Street suffixes vary: Street, St, and ST all appear in the same dataset. Some addresses use pre-directional prefixes that don't match your basemap. You run the geocoder and fifty percent of your points land on the wrong street or in the wrong neighborhood. The workaround I use is straightforward and takes about twice as long as the naive approach. Create a reference street centerline layer from the same source your geocoder uses, then run a spatial join between your address points and the streets before geocoding. This filters out impossible matches and flags addresses that need manual review. After geocoding, I run a distance check: any point more than two hundred meters from its attributed street gets flagged for manual verification. This catches roughly eight percent of entries that the automated process placed incorrectly. I once spent three days debugging why a regression model showed a negative relationship between distance to parks and home values in a Midwestern city. The issue wasn't the statistics. The park boundary shapefile had a topology error where a large portion of the park polygon was inverted, creating a hole that extended several miles beyond the actual park edge. Buffering from that boundary produced distances that were completely wrong for half the study area. Running a fix geometry tool and rebuilding the buffers resolved it in twenty minutes. This is why you validate your spatial data before running models.
Spatial Autocorrelation and the Mistake Everyone Makes
Omitting spatial autocorrelation from a regression model in human geography is the single most common technical error I see. People run OLS onAreal data, look at the R-squared, and call it done. The residuals are spatially clustered. Your standard errors are biased. Your p-values are unreliable. You might still find statistically significant relationships, but the confidence in those findings is overstated. The fix involves checking for spatial autocorrelation in your residuals using Moran's I or Geary's C, then moving to a spatial econometric model if the test rejects the null. Lagrange Multiplier tests help you choose between a spatial lag model and a spatial error model. In R, the spdep and splm packages handle this. In Python, pysal does the same. The learning curve is steeper than OLS, but the difference in results is often substantial enough that reviewing it matters for publication or policy work. Here's a counter-intuitive point that beginners miss: spatial regression models don't always produce more accurate predictions. They produce more reliable inference. If your goal is prediction, a well-tuned random forest or gradient boosting model with spatial features often outperforms spatial autoregressive models. If your goal is understanding relationships and testing hypotheses, spatial regression is the appropriate tool. Know which one you're doing before you choose the method.
Scale and the Modifiable Areal Unit Problem
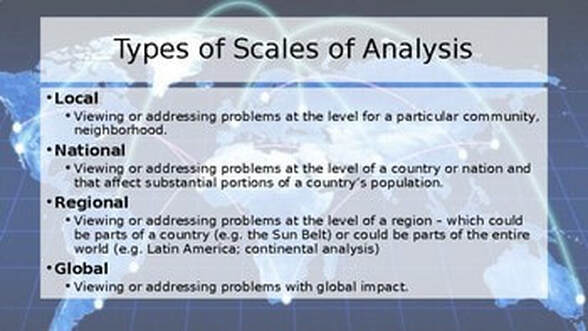
MAUP is not just a textbook concept. It changes your results. I ran an analysis of food access using census tracts, then reran it using ZIP code tabulation areas for the same metro region. The coefficient for transit proximity flipped sign. The spatial distribution of identified food deserts changed by roughly thirty percent. Neither analysis was wrong. They measured different things at different scales. When you report human geography analysis, you should state the areal unit used, justify the choice, and acknowledge that different units could produce different results. Sensitivity analysis across multiple scales is ideal but time-consuming. At minimum, run your key model at two different aggregation levels and compare the outputs. If they're similar, your conclusions are more robust. If they diverge, your findings are scale-dependent and you need to discuss that limitation explicitly.
Edge Cases That Break Standard Workflows
Boundary mismatch between datasets is an ongoing problem. Census tracts change over decades. Parcel layers get updated on different schedules. When you overlay them, you get sliver polygons and unmatched areas. The standard dissolve and erase workflow handles most cases, but for time-series analysis across changing boundaries, I recommend using the Census Boundary Adjustment toolset or converting to a consistent grid layer like TIGER/Line-based hexagons for longitudinal comparison. Small area estimation is another area where the standard methods fall apart. Census data at the block group level has wide margins of error for smaller jurisdictions. If you're working in a rural county with block groups of five hundred people, those estimates are noisy. Bayesian smoothing or hierarchical modeling using larger-area data as priors stabilizes the estimates. I use the bayesreg package in R for this. It adds a layer of complexity but produces estimates that are more useful for policy analysis than raw survey estimates.
Tools and Resources
For a complete Of Analysis Human Geography workflow, the essential free tools are QGIS for cartography and geoprocessing, R with the sf and spdep packages for spatial statistics, and Python with geopandas and pysal for scripting and automation. Jupyter notebooks pair well with geopandas for reproducible analysis. I keep a template notebook that handles CRS validation, data cleaning checks, spatial join operations, and Moran's I testing so I'm not rebuilding the infrastructure for each project. Data sources worth knowing: the US Census TIGER/Line shapefiles for administrative boundaries, the American Community Survey for demographic data, the National Atlas for transportation and environmental layers, and local open data portals for parcel and zoning data. Each source has different update schedules and accuracy standards. Cross-reference when possible. If you want a practical guide that walks through the full process from raw data to published map, the Spatial Analysis in Ecology and Biology series from Springer covers methods relevant to human geography, and the QGIS documentation has detailed tutorials for each geoprocessing tool. For the statistical side, Anselin's work on spatial econometrics is the standard reference, though it's denser than most introductory material.