What You Actually Need To Know About Formal Language Theory
Most people who come across formal languages for the first time are looking at a textbook chapter about Chomsky hierarchies and they immediately glaze over. They see automata diagrams, production rules written in a notation that looks like broken programming syntax, and they assume it's pure abstraction with no connection to anything they'll ever actually build. That assumption is wrong, and it costs people a lot of time later when they hit parsing problems they don't understand the root of.Understanding Of Computation And Formal Languages
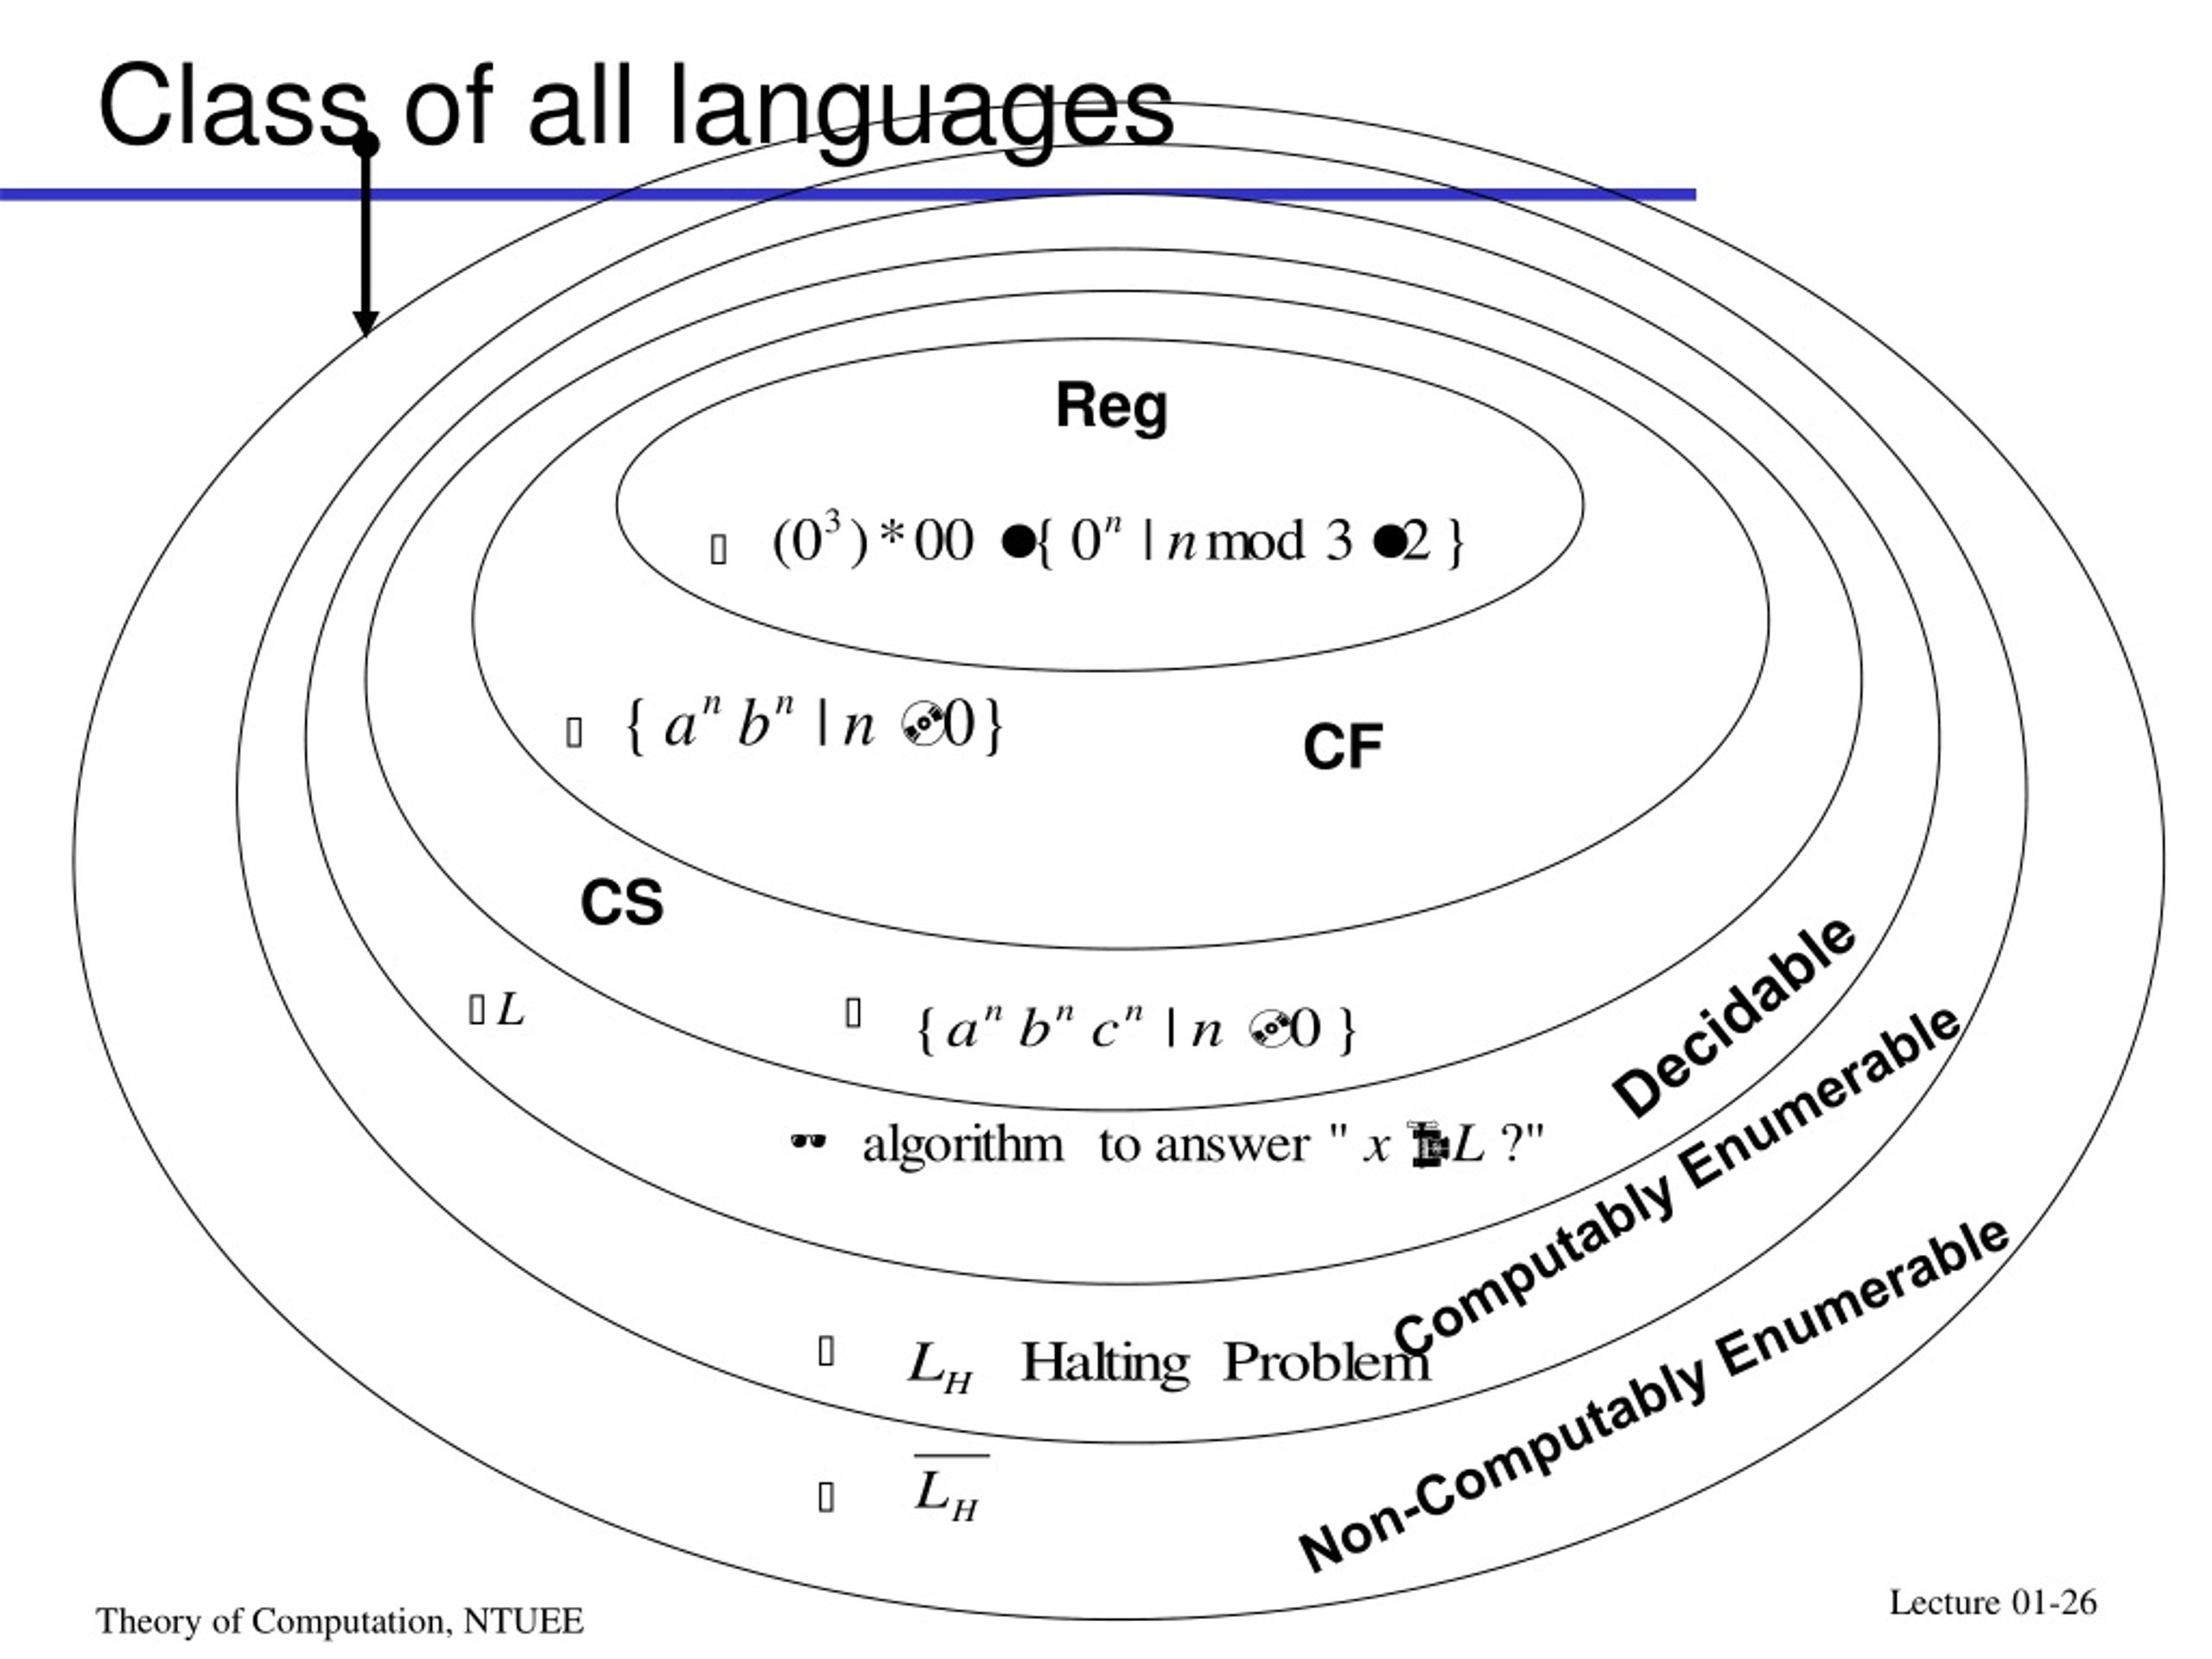
At its core, formal language theory is the study of what languages can be described by what kinds of grammatical rules, and more importantly, what machines can recognize them. The Chomsky hierarchy gives you four levels, and knowing which level your problem lives in determines which tool you should reach for. Type-3 regular languages map to finite automata and regular expressions. Type-2 context-free languages map to pushdown automata and CFGs. Type-1 context-sensitive and Type-0 recursively enumerable go into territory where you're basically doing general computation with no guarantee of termination. The practical takeaway is that most real-world parsing problems sit between Type-2 and Type-3. HTML, configuration files, programming language syntax, protocol message structures — these are all context-free or close to it. When someone tries to parse nested structures with a regex, that's a fundamental category error. Regular expressions cannot count arbitrary nesting depth. This isn't a limitation of implementation. It's a mathematical fact proven by the pumping lemma for regular languages. People learn this the hard way when their "simple config parser" breaks on the third level of brackets. I spent about three weeks debugging a parser that kept failing on deeply nested JSON-like structures. The input generator had edge cases we hadn't considered, and the regex-based validation we'd slapped on top was silently accepting malformed data while rejecting some valid inputs. The fix was rewriting the validation layer as a proper recursive descent parser with explicit stack management. It took roughly two days to implement correctly and eliminated the entire class of bugs. The regex approach would have required an unbounded series of patches that never actually solved the underlying problem.
How Context-Free Grammars Work In Practice
A context-free grammar consists of terminals, non-terminals, a start symbol, and production rules. That's it. The notation looks dense because textbooks write it that way, but the concept is straightforward. You define how larger structures break into smaller ones. A simple arithmetic expression grammar might look like: expr expr + term | term
term term * factor | factor
factor ( expr ) | number This grammar generates all valid infix arithmetic expressions with addition and multiplication. It's ambiguous, which matters more than people expect. The same string "3 + 4 * 5" can be parsed in two different ways, yielding different results depending on which derivation you pick. That's why real parsers don't just use raw CFGs — they resolve ambiguity through precedence rules or rewrite the grammar to be unambiguous. Operator precedence parsing, LL parsers, LR parsers, GLR parsers — these are all strategies for turning a grammar into something a machine can execute deterministically.
One thing beginners consistently miss is that CFGs don't capture everything you might want to enforce. Balanced parentheses? Sure, a CFG handles that easily. But "the number of a's equals the number of b's" in a string like a^n b^n is also context-free. Meanwhile, the language {a^n b^n c^n | n 0} is context-sensitive — no CFG can express it. This matters when you're validating things like matching opening and closing tags across three different nested scopes, which appears more often in markup languages than people realize.
Get the Full Details
Pushdown Automata And Why They Matter
A pushdown automaton is essentially a finite state machine with a stack attached. That single stack gives it enough power to handle context-free languages. The stack operates on last-in-first-out ordering, which is exactly what you need for matching nested constructs. Each transition can push a symbol onto the stack, pop one off, or do neither. Acceptance happens either by reaching a final state or by emptying the stack, depending on the variant. The reason this matters practically is that understanding PDA behavior helps you debug why certain parsing approaches fail. If your grammar requires matching counts across arbitrarily deep nesting, a finite state machine without a stack can't do it. I've seen teams try to validate XML-like documents with state machines because the alternative felt too complex. It works until the document has three levels of nesting instead of two, and then you're doing damage control on a production bug.
Turing Machines And What They Tell You
Turing machines are the formal model behind general computation. A TM has an infinite tape, a read-write head, and a finite set of states with transition rules. It's the simplest possible machine that can compute anything computable. The formal language class corresponding to TMs is Type-0 — recursively enumerable languages. These are the languages recognized by algorithms that may or may not terminate. The halting problem is the most important result here. There is no general algorithm that can determine whether an arbitrary TM will halt on an arbitrary input. This isn't a gap in current technology. It's provably impossible. The consequence for practical work is that any tool claiming to fully validate arbitrary computations — static analyzers, linters, type checkers that guarantee completeness — is making a claim that runs into this fundamental limit. They can catch some classes of errors reliably, but they cannot catch all of them without giving up on termination, which makes them useless. When I built a constraint solver for a scheduling problem, I hit this directly. The naive approach of enumerating all valid configurations was theoretically correct but computationally infeasible beyond about thirty variables. I switched to a SAT-based encoding with CDCL solving, which cut the runtime from hours down to under forty seconds for the cases that mattered. The theoretical foundation — reducing the problem to propositional logic and leveraging decades of optimization in SAT solvers — came straight from this area of theory. The Wikipedia page won't tell you that.
Where This All Falls Apart
Formal language theory has real limitations that practitioners ignore at their peril. CFG parsing is O(n^3) in the general case with CKY algorithm, and while LR parsers bring that down to O(n), they require grammars that fit the strict LR(k) constraints. Real-world languages like SQL, C++, and Python deliberately bend or break those constraints because pure formal grammar alone can't express everything programmers need. C++ template metaprogramming is Turing-complete, which means static analysis of C++ code is undecidable in the general case. Tooling that claims full correctness for C++ is lying to you. Another issue is that formal grammars describe structure, not meaning. A parser can verify that your code has correct syntax without understanding that the variable you're passing is null at runtime. Type systems bridge part of this gap, but even they operate within formal limits. Goedel's incompleteness theorems and the undecidability results from computability theory mean there will always be true statements about your program that your formal system cannot prove. This isn't a software problem. It's a mathematical one. If you're coming into this from a practical angle, start with regular expressions and finite automata, then move to CFGs and parsing. Learn to build a recursive descent parser by hand before you touch a code generator. The tools will abstract away the mechanics, but they won't help you when the generated parser fails on an edge case, and it will. Understanding the formalism beneath the tooling is what separates someone who can debug a parser from someone who just switches to a different parser generator and hopes.


