How We Actually Handle Personal Data In Tech Systems
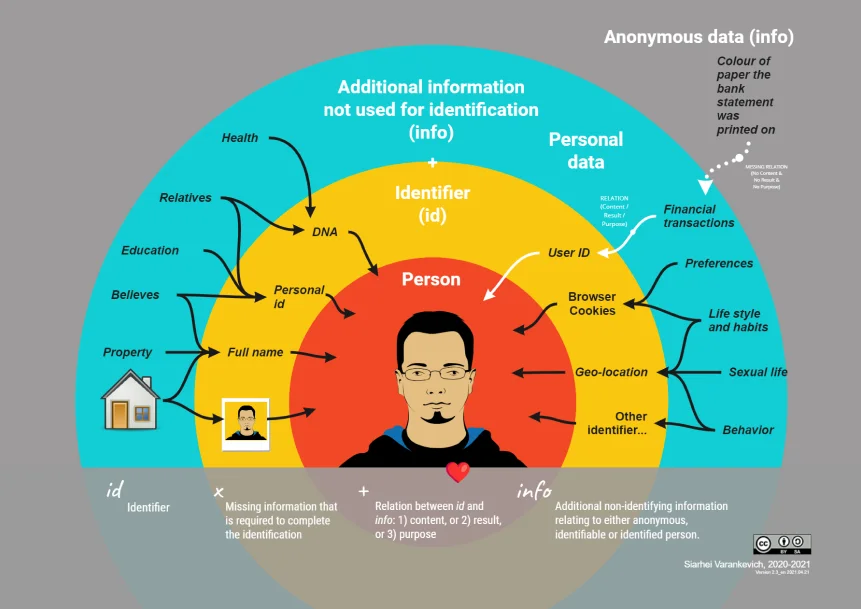
Most people think personal data is just names and email addresses. It isn't. The stuff that keeps engineers up at night is device fingerprints, location history, behavioral metadata, cross-referenced purchase patterns, and the invisible keys that tie everything together. I spent years building systems that had to collect, store, and delete this kind of information across dozens of services. It's more tedious than glamorous. Here's what nobody tells you during the architecture phase. When you're designing for personal data, you're not just thinking about GDPR or CCPA compliance. You're thinking about what happens when a user requests deletion from three separate microservices that share a database, two of which were acquired through mergers and still use legacy schemas. That scenario isn't theoretical. I dealt with it directly. The hard part is tracing data lineage. Not the official kind you document for auditors. The real kind. The version that exists in cache layers, in log aggregation pipelines, in analytics exports that got pulled into a warehouse, and in backup snapshots that nobody restored from after a failed migration in 2021.
I built a data mapping tool once. Took about six weeks. Worked perfectly for our primary service. Broke completely when we tried to extend it to third-party integrations that never updated their schema contracts. The workaround was manual reconciliation using a combination of log timestamps and field-level hashing. If a record's hash matched a deletion request within a sliding window, we flagged it. Otherwise we escalated it to a review queue. Cut our response time from roughly four days per request down to about twelve hours.
Setting Up A Practical Personal Data Handling System
Start with classification. Don't just tag everything as PII and move on. That's how you end up treating a publicly listed company name the same way you treat a biometric hash. Break it down into tiers. Direct identifiers. Indirect identifiers. Derived data. Publicly available information. Each tier needs a different retention and deletion policy. I learned this the slow way after an automated deletion script wiped customer display names from a public leaderboard because we'd misclassified them as direct identifiers. Build your data flow diagram before you touch any code. Map every system that touches personal information, including the ones that receive it indirectly through exports or webhook callbacks. Most teams skip this step. They rely on their database schema to serve as documentation. It doesn't. A schema shows you what's stored. It doesn't show you where data flows after it leaves that table. Implement deletion as a first-class operation, not an afterthought. The delete endpoint should trigger a chain reaction across your stack. When I ran production services, I structured deletion requests around a correlation ID rather than a primary key. Using just a user ID wasn't enough because the same person could exist under multiple accounts, and some of those accounts needed different treatment. A correlation ID that followed the data through ingestion, transformation, storage, and export made it possible to trace exactly which records to touch.
Get the Full Details

Use soft deletion with a configurable retention period. Hard deletion is fine for non-sensitive data. For anything that crosses into regulated territory, keep a tombstone record for at least thirty days. You need that window to catch deletion requests that arrive after the data has already been replicated to a secondary region or copied into a backup snapshot. I've seen teams try to go straight to hard deletion to save storage costs. They saved maybe two hundred dollars a month and lost the ability to prove they'd actually complied with a request within the legal timeframe.
Common Mistakes That Waste Time
Assuming your backups don't count. They count. Regulators and auditors treat backup data as personal data. The difference is the response time. Backups usually get a longer window because restoring from backup to delete a single record is operationally expensive. Document that window clearly in your policy and stick to it. I've seen companies claim they delete data within thirty days while their most recent restore-capable backup was four months old. That gap becomes a problem when someone asks why their information is still recoverable. Another mistake is treating pseudonymization as equivalent to anonymization. They aren't. Pseudonymized data still falls under most privacy regulations because the key exists somewhere and can re-identify the subject. I once configured an analytics pipeline to pseudonymize IP addresses before storing them. We were comfortable with that arrangement until a security audit revealed the hashing key was stored in the same vault as the data. At that point the pseudonymization was purely cosmetic. Moving the key to a separate service with its own access controls changed the classification entirely. Third mistake: not testing deletion at scale. A deletion request against five thousand records behaves differently than one against five million. Query plans change. Indexes get stressed. Background jobs pile up. I learned this during a load test where our deletion job was supposed to run in under a minute but actually took forty-seven minutes because it wasn't using partition pruning. Adding the right filter condition dropped it to about fourteen seconds.
What To Do If Your Infrastructure Isn't Ready
If you're running on a platform that doesn't support column-level encryption or per-record deletion, don't pretend it does. Document the limitation explicitly. State what you can delete, what you can't, and how long each process takes. That transparency matters more than claiming features you don't have. Users and auditors both prefer honesty over a polished but false promise. Consider a data access registry if you have multiple services. It's a simple database table that logs which service holds which type of personal data, how long it's retained, and who is responsible for deletion requests. It doesn't replace proper tooling. It replaces the panic that happens when you're asked to produce a data map during an audit and every engineer has a different answer about where customer data lives. The tools themselves are mostly commodity. Look for solutions that support both active deletion and backup immutability policies. Some platforms offer built-in data subject access request workflows. Others require you to build them. Either way, the implementation details matter more than the product name. A well-implemented open-source solution beats a poorly configured enterprise product every time.
If budget is tight, start small. Pick one service. Map its data flows. Implement classification. Set up deletion with correlation IDs. Extend to the next service when that one works reliably. Don't try to fix everything at once. The second you attempt a full-stack rollout, you'll hit edge cases you didn't anticipate and waste weeks going backward.