What You Actually Get When You Run On A Cloud Composer
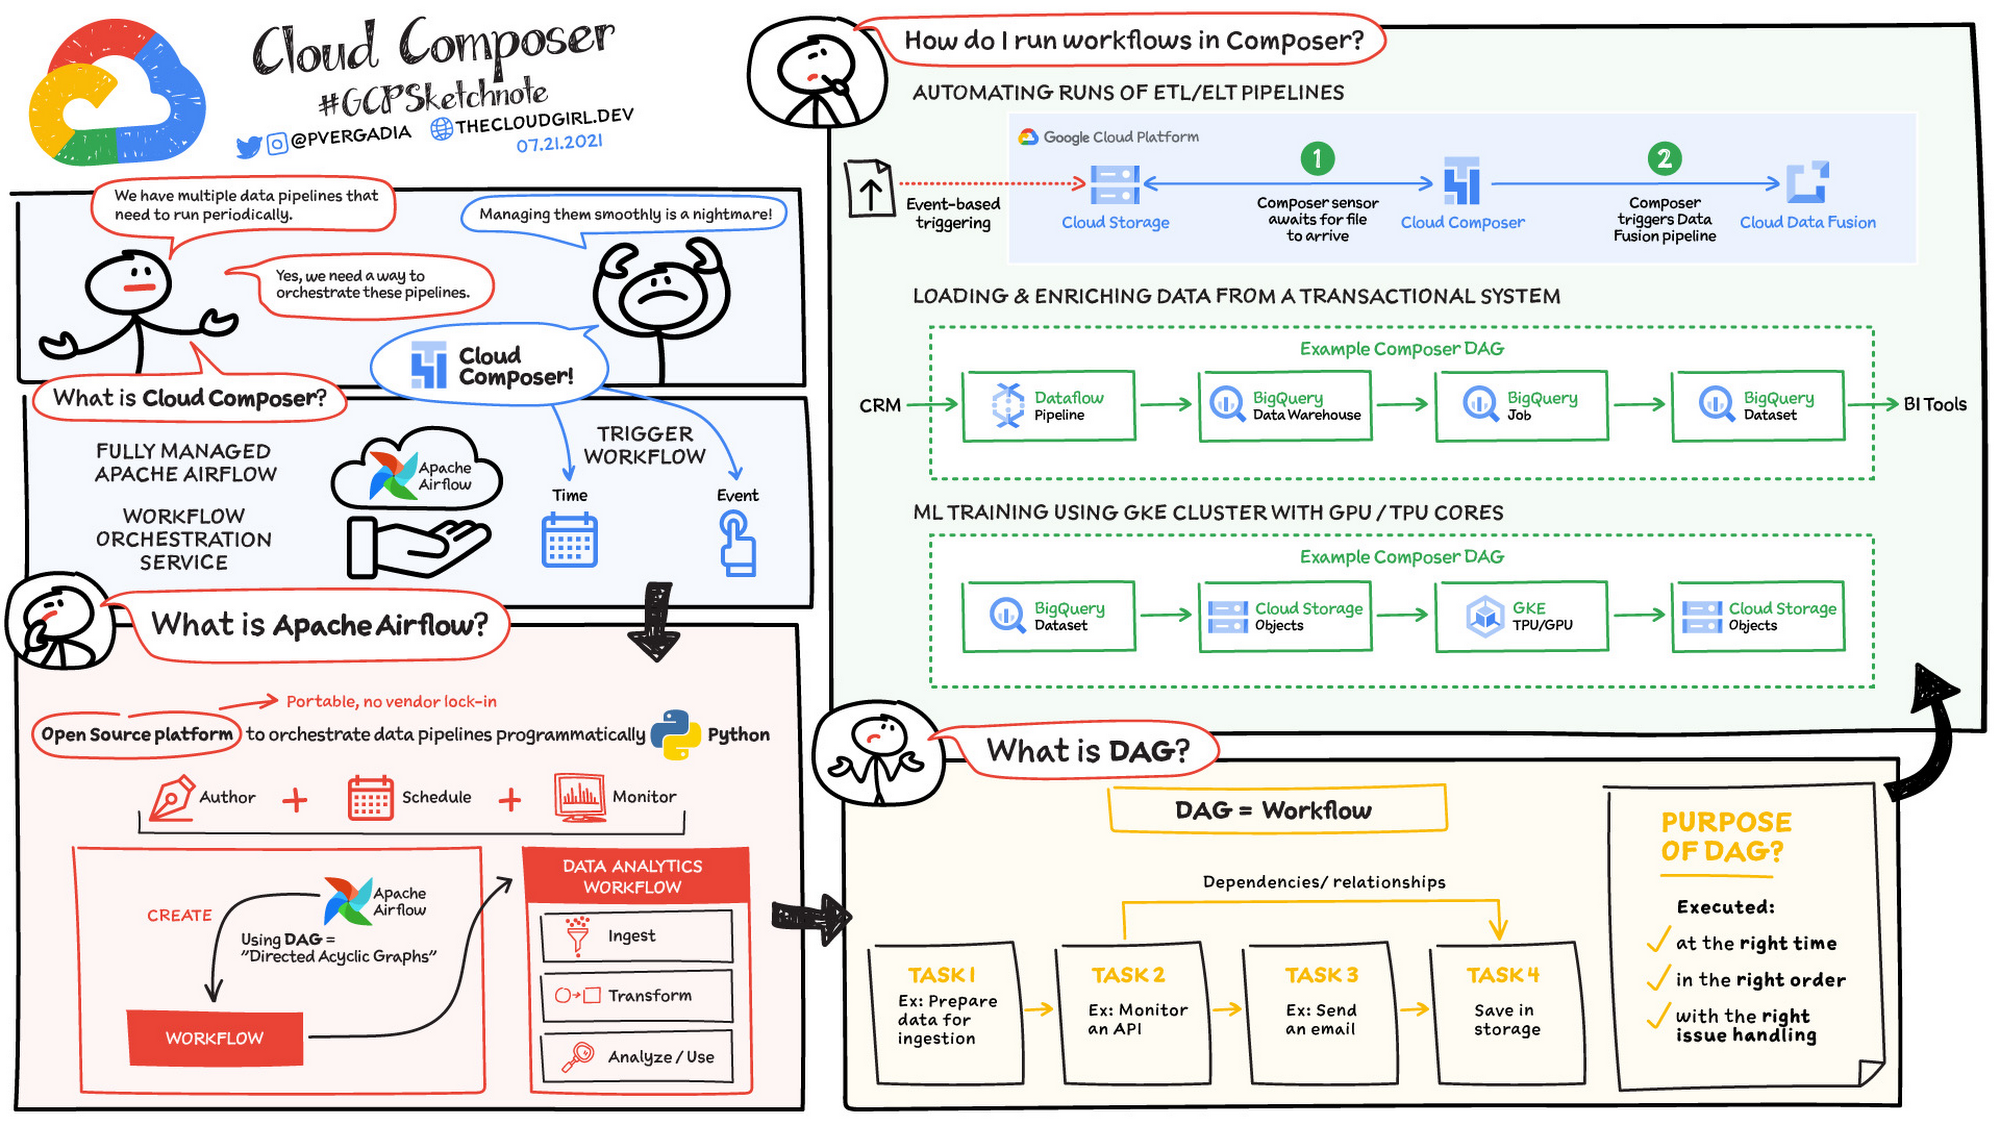
Cloud Composer is Google's managed Airflow environment. You spin up a project, it provisions a GKE cluster, installs Airflow, and you get a web UI at the end of it. The documentation makes it sound simple. It is simple until you hit the parts that aren't covered in the quickstart guide. I've deployed and maintained a handful of Composer environments across different industries. The ones that survive long-term are the ones where someone actually understands what's underneath the abstraction layer. If you just want a DAG to run once and forget about it, you'll probably be fine. If you need something that runs reliably at scale over months, you need to know how the pieces fit together before you start typing code.
Setting Up On A Cloud Composer for the First Time
The first step is creating a Composer environment. You do this through the Google Cloud Console or the gcloud CLI. Pick a region, choose your Airflow version, and decide on the machine type. The default settings will get you running in maybe twenty minutes if nothing goes wrong. Most things go wrong because people skip the configuration details. Here's what matters that the default screen won't tell you: the Python version you're working with needs to match what your DAGs actually require. Airflow 2.3 runs on Python 3.7 by default in Composer, but many packages you'll install have dropped support for that version. You'll hit import errors that look like configuration problems when they're really version incompatibilities. Pin your dependencies carefully in your requirements.txt file and test them before you commit anything. I had a situation where a data pipeline worked perfectly in local development on Python 3.9 and then failed silently in Composer because the environment was locked to 3.7. The error wasn't obvious either. It showed up as a module not found error for a dependency that should have been there. Took me about three hours to realize the Python version mismatch was the root cause. Downgrading the dependency to a version that supported 3.7 fixed it.
How the Architecture Actually Works
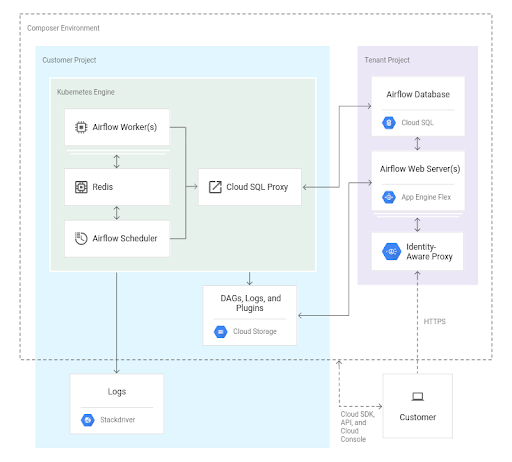
Under the hood, Composer runs on Kubernetes. Your Airflow components — scheduler, webserver, worker — are all pods in a GKE cluster. The environment you create is really a wrapper around that cluster. Understanding this matters because it determines how you scale, how you debug, and what happens when something breaks. The GCS bucket attached to your environment stores your DAG files, logs, and configuration. When you upload a new DAG through the UI or by placing a file in the bucket, the scheduler picks it up within a few seconds. That's the simple path. The complicated path involves custom images, private pools, and network configurations that change how everything connects. One thing most guides don't emphasize enough: Composer environments have two separate scaling concerns. The scheduler can be scaled independently from the worker. If your DAGs are mostly sequential and lightweight, you might not need a large worker pool at all. If you're running heavy parallel jobs, the scheduler becomes the bottleneck before the workers do. I learned this the hard way when a single environment started missing task deadlines because the scheduler was too busy checking task states to actually dispatch work. Scaling the scheduler pods solved it immediately.
Get the Full Details
Common Problems and What Actually Fixes Them
The most frequent issue I see is people trying to install system-level packages through pip inside their environment. This doesn't work the way you'd expect. Composer environments run in containers, and while you can use custom images to include system dependencies, the default setup only supports pip-installable Python packages. If your pipeline needs something like a C library or a compiled tool, you need to build a custom Docker image and point your Composer environment at it. Another thing that catches people out is the difference between the Composer environment's networking mode and your own VPC setup. If you're running data tasks that need to reach internal services — databases, APIs, other GCP products — your Composer environment needs proper VPC access configured. The default setup uses a shared VPC by default, but if you're on a custom VPC with private Google access disabled, your tasks will fail with connection timeouts that look completely random. I once spent a full day debugging what I thought was a broken database connection. The error logs pointed to connection refused, which could mean anything. It turned out the Composer environment's subnet didn't have access to the internal IP range of the database. Enabling private Google access and adjusting the VPC peering configuration fixed it in about ten minutes. But finding that as the cause took a lot of trial and error because the error messages don't point you in that direction at all.
Cost Management Without Losing Your Mind
Composer isn't free. You pay for the GKE cluster underlying your environment, plus any additional resources you scale up. A small environment running constantly will set you back maybe a hundred dollars a month at minimum. If you're running heavy workloads or scaling up workers frequently, it adds up quickly. The practical approach is to schedule environments to shut down when they're not needed and restart them when you need them. This works well for development and testing environments but less so for production pipelines that need to run on strict schedules. You can also use Cloud Composer's built-in scaling policies to reduce costs during low-activity periods without completely shutting things down. One thing to keep in mind: even when your Composer environment is idle, the GKE cluster is still running and still costing money. The only way to truly stop paying is to delete the environment entirely and recreate it later. If you're doing that, make sure you have your DAG files backed up somewhere outside of Composer, because deleting an environment deletes everything associated with it.
When Composer Is the Right Tool and When It Isn't
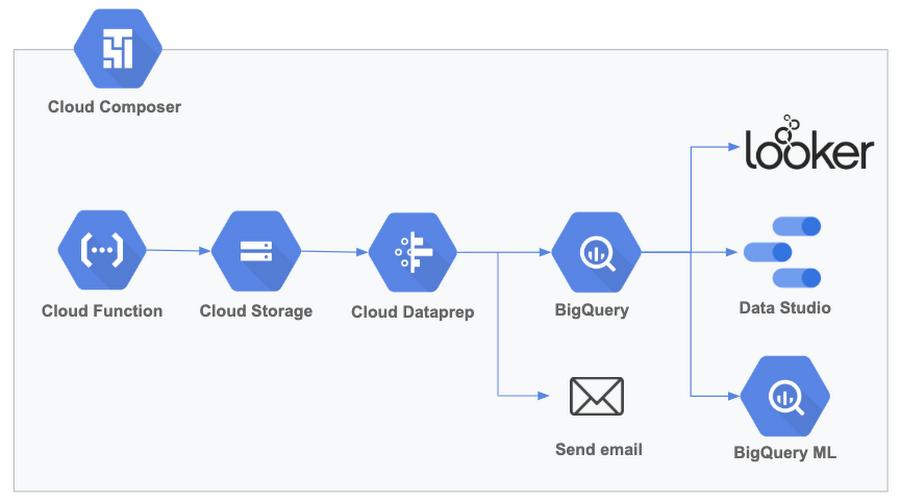
Cloud Composer works well if you already live in GCP and your workflows are fairly standard ETL or orchestration tasks. It integrates cleanly with BigQuery, Cloud Storage, Dataflow, and the rest of the platform. If your team already knows Airflow, the learning curve is minimal. It doesn't work well if you need sub-minute task execution, if your workflows require custom runtime environments that can't be containerized, or if you're running on a tight budget with unpredictable workloads. For those cases, something like Prefect on Kubernetes or even a simple Cloud Run-based scheduler might give you better control over costs and performance. The main limitation I see repeated is that Composer environments take time to start up. A fresh environment can take fifteen to thirty minutes to become fully operational. If you're spinning up environments on demand for one-off tasks, that overhead eats into whatever time savings you were hoping to get. In those situations, a lighter-weight solution makes more sense.
If you want the official documentation, it's all available at cloud.google.com/composer. Start there if you need the reference material. Just don't expect it to cover the edge cases that only show up after you've been running these environments for a while.