Understanding and Running a One Sample T Test
A one sample t test checks whether a group's average is meaningfully different from some predetermined benchmark. You aren't comparing two treatments against each other. You're asking if your data's mean diverges from a fixed number, and whether that gap could plausibly be due to random sampling noise. The mechanics are straightforward enough, but people routinely screw it up because they skip the assumptions check. Here's how it actually works when you're sitting at your laptop and need a real answer.
One Sample T Test: When to Use It and How to Run It
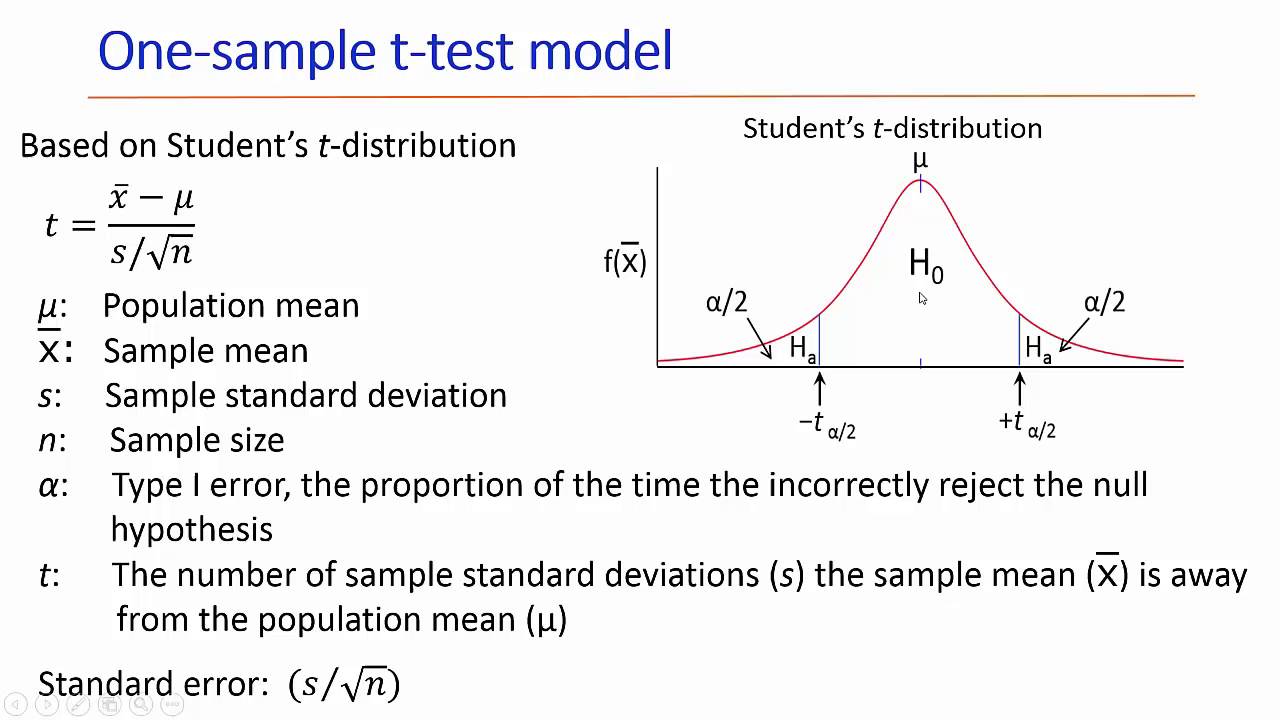
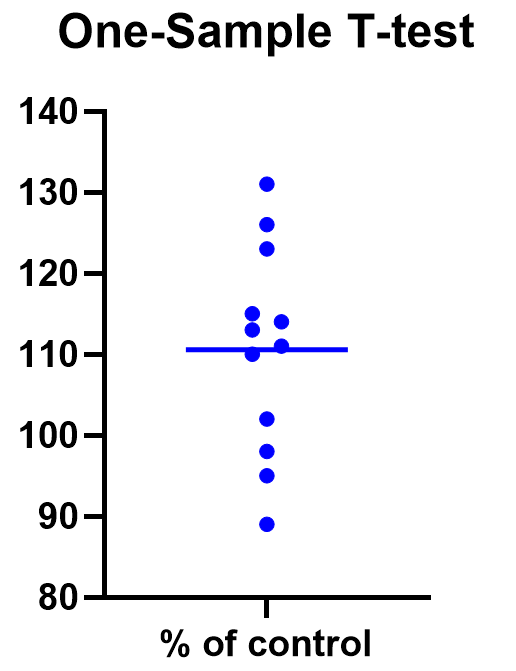
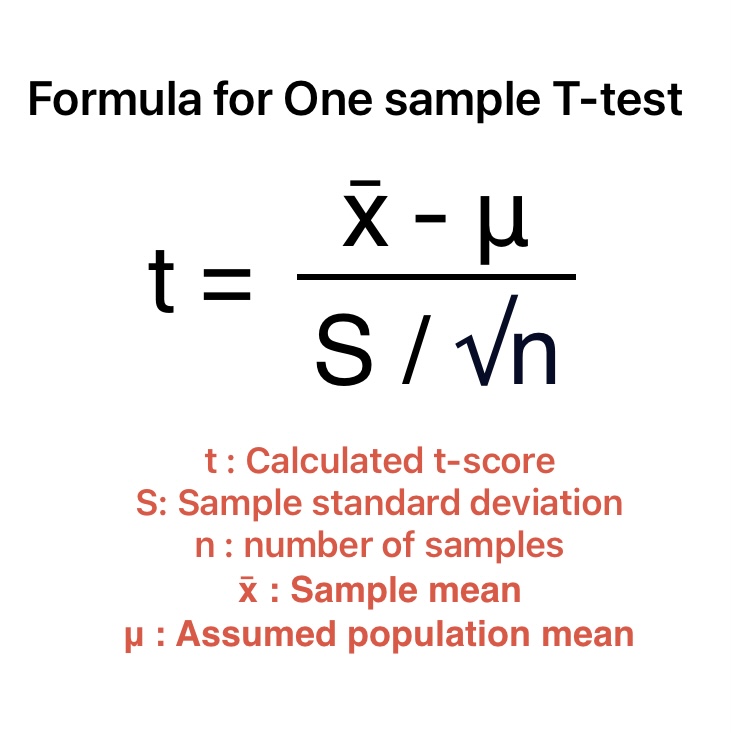
You need three things before touching any software: a continuous outcome variable, a single sample, and a reference value you care about. That reference value might come from a regulatory threshold, a prior study's mean, a manufacturing spec, or even a theoretical midpoint. For example, a quality engineer might test whether the average diameter of machined parts differs from a target of 12.5 millimeters. A clinical researcher might compare a new pill's effect on blood pressure against the known population baseline of 120 overlying mmHg. The test statistic is calculated as the difference between your sample mean and the reference value, divided by the standard error. The standard error is your sample standard deviation divided by the square root of your sample size. So the formula collapses into something like this: t equals (x-bar minus mu-zero) divided by s over root n. That's it. It's not complicated math. The complication comes from interpreting what the result means. Let me walk through a practical scenario. I was once working on a project where a client wanted to validate whether their automated packaging line was hitting a labeled weight target of 500 grams. They collected 37 samples and ran the test. The output showed a t-value of 2.14 with a p-value of 0.041. Since that p-value dipped below 0.05, they declared the machine was off-target. But here's where it got interesting. When I looked at the raw distribution, there was a single outlier at 420 grams caused by a jammed hopper. Removing that one data point changed the mean by nearly eight grams and shifted the p-value to 0.12. The conclusion flipped entirely. That's the kind of thing that happens when you treat the t test as a black box.
Before you run anything, check these assumptions. The data should be approximately normally distributed, particularly when your sample size is small. With n greater than 30, the central limit theorem usually carries you through, but don't rely on that rule blindly. Heavy skew or extreme outliers can distort the mean and inflate the standard error, giving you unreliable results even at n equal 50. You can check normality with a Shapiro-Wilk test or just look at a histogram and a Q-Q plot. A Q-Q plot will show you immediately if the middle of your distribution hugs the diagonal while the tails swing away. That tail behavior matters more than you think for this particular test. Another assumption people forget: the observations must be independent. If your data points are correlated — say you measured the same subject repeatedly, or samples came from clustered batches — the standard error estimate is wrong and your p-value is garbage. I've seen this happen in manufacturing where consecutive products from the same batch share subtle environmental variance. The effective sample size is nowhere near the nominal count. In those cases, treating each measurement as independent gives you a false sense of precision. When you're ready to execute this, most statistical software handles it in a couple clicks. In R, you'd run t.test() with your data vector and specify the mu parameter as your reference value. The function returns the t-statistic, degrees of freedom, confidence interval, and p-value in one go. In Python, you'd use scipy.stats.ttest_1samp(). SPSS and SAS have point-and-click menus for this. Regardless of the tool, the underlying calculation is identical. What varies is the extra diagnostic output you get, so pick the platform that gives you access to the raw statistics and residuals you might need later.
Get the Full Details

Here's something most beginners miss. The confidence interval from a one sample t test is just as important as the p-value, and often more useful. A p-value of 0.03 doesn't tell you whether the difference is practically significant. The confidence interval will. If your sample mean is 502 grams against a target of 500 grams with a 95 percent CI ranging from 500.3 to 503.7, you can see immediately that while the deviation is statistically detectable, it might be meaningless for your application. A five-gram drift could be irrelevant in your industry. The interval makes that visible. The p-value alone hides it. There's also the question of one-sided versus two-sided testing. By default, every tool runs a two-sided test. That's usually correct. A one-sided test doubles your effective alpha at one tail and cuts it at the other, which means you're making a stronger claim with the same amount of evidence. I've seen too many researchers switch to a one-sided test after seeing a two-sided p-value of 0.08, hoping to squeeze out significance. That's not how science works. You specify the direction of your hypothesis before you look at the data, and if you didn't pre-register it, stick with two-sided. The conservative approach costs you nothing except a slightly wider confidence interval. If your data violates the normality assumption badly and you can't transform it — log, square root, inverse — into something reasonable, consider the Wilcoxon signed-rank test as a nonparametric alternative. It tests the median rather than the mean, which changes the interpretation slightly, but it's far more robust to skewed distributions and outliers. It's not a drop-in replacement in every situation, but it's worth having in your toolkit when the t test's assumptions fall apart.
One more practical note. Power analysis matters here too. If you're designing a study and want to know what sample size you need to detect a specific difference from your reference value, you'll need to estimate the population standard deviation. Getting that wrong skews your entire planning process. A rough pilot of 10 to 15 observations usually gives you a decent ballpark for sigma, though the estimate itself will be noisy. Don't treat a pilot-based power calculation as gospel, but it's better than guessing. Underpowered studies waste resources and produce null results that look like no effect when they're actually just inconclusive. The one sample t test is a workhorse because it's simple and it works well when its conditions hold. It breaks down quietly when they don't, which is the real danger. You run it, get a result, and never realize the foundation was rotten. Pay attention to the distribution, respect the independence assumption, report the confidence interval alongside the p-value, and don't chase significance by fishing for one-sided tests. That's the practical approach. The rest is just software clicks.