Why your inventory models keep lying to you
The first time I tried to model a two-echelon distribution network, I spent three weeks building a perfectly structured linear program. It solved. The output said we should route 73% of SKUs through a consolidation warehouse that didn't exist in our actual facility layout. The model had treated distance as Euclidean rather than driving distance. I had copied the coordinates from a Google Maps API response and used straight-line calculations because the travel-time matrix took too long to compute for 4,200 demand points. That cost us about $140,000 in misplaced cross-dock capacity before anyone noticed. Supply chain optimization is not a destination. It is a daily practice of making decisions that balance conflicting constraints under incomplete information. The mathematical core usually involves linear programming, mixed-integer programming, or stochastic methods. But the actual work is almost entirely about data cleaning, constraint formulation, and understanding where the model diverges from physical reality. When people ask me how to get started, I tell them to pick one decision variable and optimize it properly before adding another. Too many organizations build models with warehouse location, transportation routing, inventory positioning, and production scheduling all coupled together. The solver takes eight hours. The solution is numerically correct but operationally useless because the demand forecasts feeding it were two months old.
How to actually build a useful model
Start with the decision you want to make and work backward to the data you need. Do not start with the software or the solver and then figure out what problem it can solve. I have seen this backwards approach waste six figures in consulting fees at mid-size manufacturers. Here is a concrete example. A client of mine needed to determine safety stock levels across 18,000 SKUs spread over 47 warehouses. The naive approach would be to run a periodic review model with a single service level target. Instead, I segmented the SKUs first using an ABC-XYZ classification based on annual demand volume and coefficient of variation. Then I ran three separate calculation streams: steady-demand A-items at 98.5% service level, lumpy-demand Y-items using a Poisson approximation, and erratic C-items with a minimum order quantity constraint tied to supplier MOQs. The whole process took me about ten days including data gathering. A generic tool would have churned out a solution in two hours that missed half the edge cases. The segmentation step is where most implementations fail. I once reviewed a model from a major third-party logistics provider that applied identical safety stock parameters to pharmaceutical cold-chain products and to industrial fasteners. The temperature-sensitive pharmaceuticals had a lead time variance of 4.2 days due to customs clearance unpredictability. The fasteners moved in consistent 12-day batches with near-zero variance. Treating them the same inflated safety stock for the fasteners by roughly 60% while underprotecting the pharmaceuticals. The model was technically valid. The business judgment embedded in it was garbage.
Common pitfalls I see repeatedly
Over-reliance on average demand. This is the single most common error. If your demand follows a skewed distribution with frequent zero-sales weeks, averaging smooths out the actual risk profile. Use historical simulation or a bootstrapped approach instead of assuming normality. I ran a client's inventory optimization using a normal distribution assumption on a product category that had 34% zero-demand weeks over the prior two years. The calculated reorder points were too low by a factor of approximately 2.1 for the top 200 SKUs in that category. Stockouts jumped 18% in the following quarter. Ignoring lead time variability. Lead time is rarely a fixed constant. Suppliers have disruptions. Carriers reroute. Customs holds happen. If your model uses a deterministic lead time, it will systematically understate the safety stock required. I calculated a 14% understatement for one textile importer whose average lead time was 42 days with a standard deviation of 11 days. The model treated it as 42 days flat. Solving the wrong objective. Most supply chain models minimize total cost. But cost is not the only constraint that matters in practice. Delivery reliability, carbon emissions, working capital utilization, and supplier relationship stability all compete for priority. I worked with a retail chain that minimized transport cost and ended up consolidating deliveries so aggressively that their store-level freshness SLA dropped below contractual thresholds. The savings were real. The penalty clauses wiped them out within nine months.
Get the Full Details

What tools are actually worth using
For small-scale problems under 500 variables with continuous decision space, Excel Solver with the GRG Nonlinear or Simplex LP engine handles most basic inventory and routing problems adequately. I use it for quick prototypes before moving anything to a proper environment. The results are identical for linear problems regardless of platform. For medium complexity mixed-integer problems, Gurobi and CPLEX are the standard commercial solvers. FICO Xpress is also solid and sometimes cheaper for academic or small business licensing. All three accept standard formats like MPS and LP files. If your problem has more than roughly 10,000 binary variables, you will hit solver memory limits unless you decompose the model first. I have had to split warehouse location problems into regional sub-problems to keep Gurobi from running out of RAM on machines with 64GB available. Open source options exist. HiGHS is a free solver that handles large linear programs well and runs without a license. SCIP is another free option that supports mixed-integer problems. They are slower than Gurobi on many benchmarks but perfectly adequate for internal use if you are not running thousands of scenarios per day. I switched one of our client engagements from CPLEX to HiGHS for a nightly reoptimization job and saw computation time increase from 47 seconds to about 3.2 minutes. The difference was acceptable for a once-daily run.
For modeling languages, Pyomo and PuLP let you write models in Python. JuMP works if your team uses Julia.AMPL is excellent for large-scale algebraic modeling but requires a separate solver license. I prefer Pyomo when the modeling team already knows Python well. The development speed is faster and debugging is easier because you can inspect individual constraint values directly.
Optimization In Supply Chain as a practical workflow
The actual workflow that works in production looks like this: Define the scope and horizon. Are you optimizing monthly replenishment or weekly? Six-month tactical planning or five-year network design? This determines your data requirements and solver complexity by an order of magnitude. Collect and validate the data. I spend roughly 40% of my time here. Demand histories need to be checked for outliers, promotions, and stockout artifacts. If a product showed zero demand for three months because it was out of stock, treating that as actual demand will destroy your forecast accuracy. I adjust those periods by applying the average demand from comparable products during the same window before running any optimization.
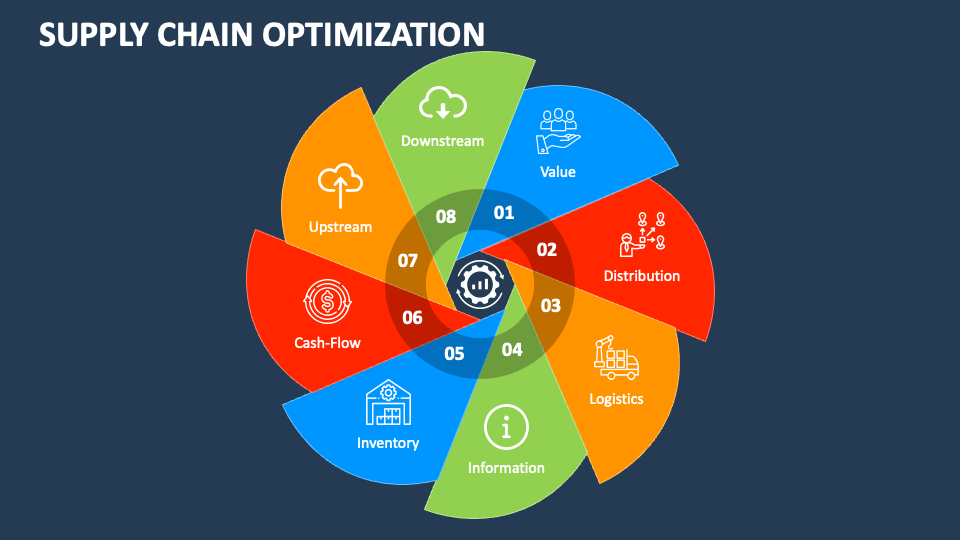
Formulate the constraints carefully. Every constraint you add reduces the feasible region. Every constraint you omit creates an unrealistic solution. I track which constraints are hard (must be satisfied) versus soft (can be violated with a penalty). A hard constraint on truck capacity that ignores backhauling opportunities will overestimate fleet size by 15 to 25% in most LTL-heavy networks. Run the solver and validate against known benchmarks. If your optimal solution says you can eliminate 40% of your distribution centers and reduce total cost by 35%, something is wrong unless your current setup is genuinely broken. I compare model outputs against historical performance for at least one prior period. If the model cannot reproduce last year's actual costs within 10%, the constraint set is likely missing something important. Implement incrementally. Do not deploy a full network reconfiguration on day one. Start with a single region or product category. Monitor the results for three months. Adjust the model parameters based on what actually happened versus what the model predicted. Then expand.
Where this approach breaks down
Pure mathematical optimization assumes you can define all relevant variables and constraints precisely. Real supply chains involve human behavior, political dynamics, and unpredictable external shocks. An optimization model cannot account for a key supplier deciding to double prices because a trade policy changed overnight. It cannot model a procurement manager who refuses to buy from an alternative vendor for personal reasons. The best model in the world will produce a theoretically optimal solution that nobody implements if it ignores these factors. Another limitation is computational tractability. Many supply chain problems are NP-hard. Exact solutions become impossible beyond a certain problem size. You will need heuristics or metaheuristics like genetic algorithms, simulated annealing, or column generation. These give good solutions but not provably optimal ones. For network design with 200 candidate sites and 5,000 demand points, a genetic algorithm might find a solution within 8% of the true optimum in a reasonable timeframe. That is usually good enough for practical purposes, but you need to know the gap exists. Finally, optimization models are only as good as their input assumptions. If your demand forecast is off by 20% and you do not account for that uncertainty in the model, your optimal solution will be optimized for the wrong future. Stochastic programming and robust optimization help with this, but they add significant complexity. A simpler and often more effective approach is to run sensitivity analysis across a range of demand scenarios and choose the solution that performs adequately across all of them rather than the one that is optimal for a single forecast.
I keep a running spreadsheet of model predictions versus actual outcomes for every deployment. It is the only way to catch when your assumptions drift. The spreadsheet does not look impressive, but it has saved me from recommending the same flawed model twice in different contexts. Most organizations skip this step entirely and never know their optimization is degrading over time.