Optimization Modeling With Spreadsheets Solution Manual
Verma
2025-05-03
Why Spreadsheet Optimization Modeling Still Matters
Most people treat spreadsheets as a glorified calculator. They should be doing so much more. When you set up a linear programming model in Excel with the Solver add-in, you are essentially building a simulation of a decision problem and letting mathematics find the best answer. That process has been around since the 1990s and it still handles a surprising amount of real business work. The
Optimization Modeling With Spreadsheets Solution Manual
that circulates online is meant to walk you through the exercises in the classic textbook by Nicholas J. Higham and related authors, giving you worked examples you can check your own work against.
I spent three years building production scheduling models in Excel for a mid-size logistics company before we moved the heavy lifting to Python. The spreadsheet models handled the quick-turnaround requests that came from regional managers who needed answers in hours, not days. Those same models would have collapsed under their own complexity if anyone pushed them past a few thousand variables.
How the Solver Actually Works Under the Hood
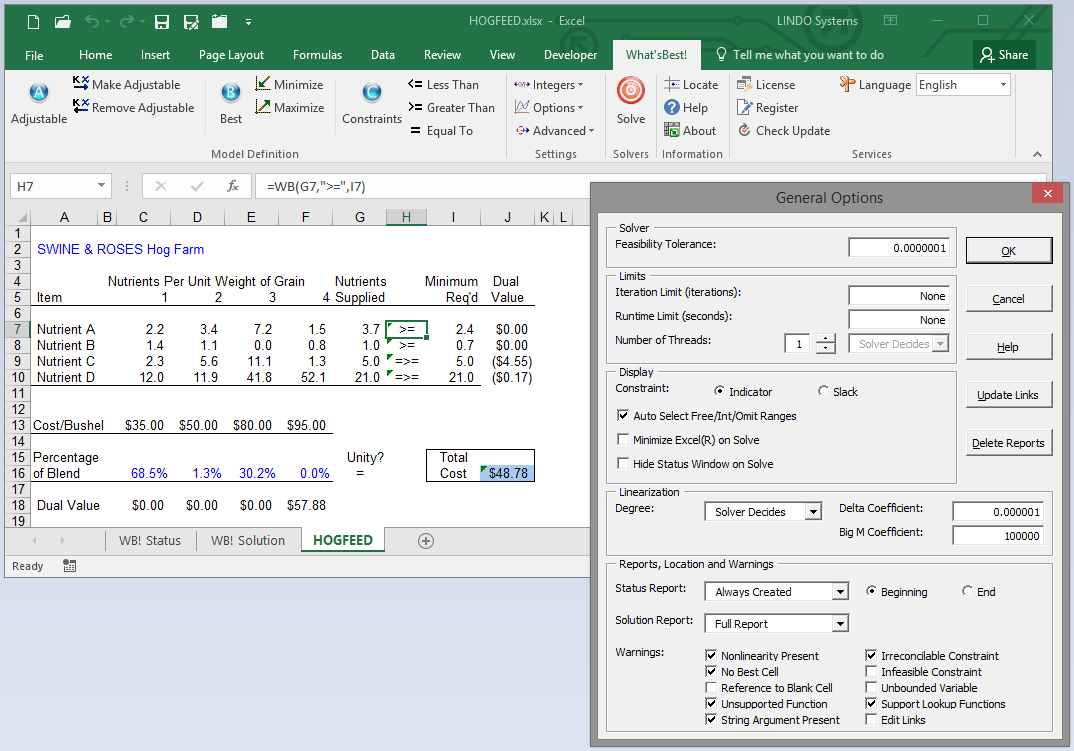
The standard engine behind spreadsheet optimization is the Simplex method, with a branch-and-bound layer added for integer constraints. You define a target cell, set changing cells, and add constraints. Then you hit Solve and let it iterate. The mechanics are straightforward, but the model setup is where everything tends to break down.
I once built a vehicle routing model with around 400 decision variables and sixty constraints. The Solver crashed on the first run because I had used a >= constraint on a resource limit without realizing that Excel's solver uses a tolerance of 0.0001 by default. Solutions that were technically infeasible at that precision level still passed validation. I resolved it by tightening the tolerance to 0.00001 and switching to the GRG Nonlinear engine for the subset of variables that weren't purely linear. That adjustment cut my debug time from six hours to something closer to twenty minutes.
The most common mistake beginners make is treating the objective function as if it exists in isolation. It does not. Every constraint interacts with every other constraint. When you change a binding constraint, the optimal solution can jump in ways that feel counterintuitive if you have not traced through the algebra. I learned this the hard way when a warehouse allocation model suddenly sent inventory to a location that was strictly more expensive than every alternative. The constraint I had tightened on transportation budget had flipped which facility the solver found cheapest once I removed it.
Setting Up a Clean Model Structure
Good model architecture follows a strict separation between data, calculations, and results. Your input assumptions live in one clearly labeled block. Your formulas live in a separate calculation area. Your outputs and Sensitivity Report data live elsewhere entirely. Mixing these layers is what turns a 30-minute debugging session into a half-day nightmare.
I keep my variable cells highlighted in yellow, my constraint constants in light blue, and my hardcoded numbers in no color at all. When someone asks to change a parameter, I know exactly where to look. The solver only touches the yellow cells. The blue cells feed the constraints. Everything else stays fixed. This color coding took me a while to adopt because it felt tedious at first, but it has saved me repeatedly when models became large enough that tracking formulas by name alone was no longer viable.
The Sensitivity Report in Excel's Solver output gives you shadow prices and allowable increases and decreases for each constraint. Those numbers tell you which constraints are binding and how much slack exists. A shadow price of zero means the constraint is not affecting the optimal solution at that point. A non-zero shadow price means tightening that constraint further will worsen the objective function by a predictable amount per unit. Most people ignore this report entirely, which is a waste.
Common Pitfalls That Cost Real Money
Non-linear models in spreadsheets are unstable by nature. The GRG engine can converge to a local optimum that looks correct but is nowhere near the global best. I ran into this with a pricing optimization model where the solver kept finding a locally optimal price point that left significant margin on the table. The fix was running the solver from multiple starting points and comparing the results. That alone doubled the time required for each model run but produced a solution that was measurably better.
Integer solutions introduce another class of problems. The branch-and-bound algorithm does not guarantee a solution within a reasonable timeframe for complex integer programs. I have watched a model sit for forty-five minutes before returning a result that violated a constraint I had not explicitly checked. The workaround was adding explicit integer constraints to every cell that needed to be whole and setting a tighter optimality tolerance in the Solver Options dialog.
Another issue that trips people up is scaling. If your objective function values are in the millions while your constraint coefficients are in the single digits, the solver struggles with numerical precision. Normalize your data. Divide everything by a common factor so the magnitudes are roughly comparable. This alone often resolves convergence failures that people attribute to model logic errors.
When to Abandon the Spreadsheet
Spreadsheet-based optimization breaks down when your model exceeds a few thousand variables or requires advanced features like stochastic programming, network flow decomposition, or integer programming with thousands of binary decisions. At that scale, the Solver simply cannot keep up. I transitioned a demand forecasting model to PuLP after it grew past approximately 8,000 variables and began timing out consistently. The move reduced model run time from twenty minutes per iteration to about forty seconds.
Even within the spreadsheet, there are practical limits. The Solver add-in caps out at 200 variables and 100 constraints in the default configuration unless you install a third-party extension. Those limits are hard walls. If you need more, you need a different tool. The transition from spreadsheet to a proper optimization library is not as dramatic as some people make it sound. The mathematical structure stays the same. Only the interface changes.
Using the Solution Manual Effectively
The solution manual should be a verification tool, not a shortcut. Work through the exercise yourself first, then compare your setup and answer to the manual. If your model produces a different optimal value, trace your constraints line by line against the solution manual's approach rather than assuming the manual is wrong. More often than not, the discrepancy comes from a slightly different interpretation of the problem statement or a constraint that was inadvertently omitted.
Pay particular attention to how the manual formats its answer cells. Spreadsheet solutions are only as good as their documentation. A model that produces the right number but cannot be audited six months later when someone else inherits it is a liability, not an asset.
The real value of this kind of manual is in the edge cases. The textbook exercises cover the standard forms. The solution manual occasionally reveals how the author handled situations that do not fit neatly into any single chapter, like piecewise linear approximations or conditional constraints that require binary variables. Those examples are where you learn what the formal chapters do not cover.
Gallery Optimization Modeling With Spreadsheets Solution Manual
Optimization Modeling With Spreadsheets Solutions Manual inside ...
Optimization Modeling With Spreadsheets Solutions Manual — db-excel.com
Optimization Modeling With Spreadsheets Solutions Manual within What ...
Optimization Modeling With Spreadsheets Solutions Manual 45+ Pages ...
Optimization Modeling With Spreadsheets Solutions Manual for Pdf ...