What You're Actually Measuring When You Assess Change Readiness
An Organizational Readiness To Change Assessment is not a satisfaction survey dressed up in different clothes. It measures whether a workforce has the cognitive, motivational, and material capacity to absorb a specific change. Most tools you will find online conflate employee morale with change readiness and return results that look positive while hiding the structural barriers that will kill a rollout. The difference matters. Morale questions ask how people feel right now. Readiness questions ask whether people can and will do something new under the conditions they will face when the change hits.
Where the Organizational Readiness To Change Assessment Comes From
The concept traces back to three main streams of research. The first is the work by Rogers and colleagues on organizational readiness for organizational change. Their two-factor model splits readiness into change commitment and change self-efficacy. Change commitment asks whether people value the change. Change self-efficacy asks whether they believe they can execute it. The second stream is the work by Weiner on theory of organizational readiness for change. Weiner separates affective and cognitive dimensions within each of those same two factors. Affective commitment is emotional attachment to the change. Cognitive commitment is rational endorsement based on perceived benefits. Affective self-efficacy is confidence built from past experience. Cognitive self-efficacy is confidence built from understanding the change requirements. The third stream is the work by Contu and others who expanded the measurement to include resource allocation and environmental support as separate constructs. The most widely used instrument is the Organizational Readiness for Change questionnaire developed by Rogers and coworkers. It has 16 items across four subscales. You score it on a Likert scale. The standard format asks respondents to rate statements from strongly disagree to strongly agree. Higher scores indicate stronger readiness. You compute subscale scores separately. That is important because you can have high commitment but low self-efficacy, or the reverse. Reporting a single aggregate number hides that pattern and leads to bad decisions.
How to Run the Assessment Without Wasting Three Weeks
I used to run these assessments through a survey platform with branching logic and export everything to SPSS. That process took about two weeks from launch to cleaned dataset. The current approach I use is faster and more reliable. I build the instrument in Qualtrics using the standard 16-item ORC scale. I add eight demographic and contextual items at the end. I send the link through the internal communication system and set a seven-day response window. I monitor completion rates daily and send one reminder at day four. If the response rate drops below 50 percent by day six, I extend the window by three days and target specific departments with low uptake rather than blasting another generic reminder. Data cleaning takes about fifteen minutes. I check for straight-lining. I remove responses completed in under two minutes because someone is speed-tapping. I compute subscale means. I flag departments where any subscale falls below 2.5 on the 5-point scale. That threshold is arbitrary but it works as a warning light. It does not mean the department is doomed. It means you need to dig into that area before launching change activities there.Here is a practical trick most guides miss. You should administer the assessment during a period of relative stability, not during an active crisis or merger. People under acute stress rate everything lower across all subscales. You will read that as low readiness when it is really just temporary anxiety. If you cannot avoid assessing during turbulence, add a brief stress control item at the top of the survey and use it as a covariate in your analysis.
A Real Problem I Faced With Organizational Readiness To Change Assessment
Last year I ran an Organizational Readiness To Change Assessment for a mid-size healthcare system planning an electronic health record upgrade. The overall scores looked fine. The aggregate commitment and efficacy numbers were solid. We scheduled the rollout for the first available window. Two weeks before launch, the clinical operations team pushed back hard. They had not filled out the survey honestly because they assumed the tool was a management trick to force compliance. Several senior clinicians later admitted they selected neutral or mildly positive options because they did not want to appear obstructive while also not wanting to look like they were blindly supporting the project.Get the Full Details

The workaround was straightforward but required admitting the first assessment was unreliable. I stopped using the full organizational aggregate. Instead I split the data by professional role and tenure band. I ran separate analyses for physicians, nurses, administrative staff, and IT personnel. The role-specific data revealed that physician commitment was actually low while nurse commitment was high. The aggregate score had masked that split because the two groups were roughly equal in size. I then conducted targeted focus groups with the physician cohort before touching the schedule. The focus groups uncovered legitimate workflow concerns that the survey had never captured. We adjusted the EHR configuration and training plan based on those findings. The rollout stayed on time because we fixed the real problem before it became a crisis. The lesson is that role-specific segmentation often matters more than the overall score. You should always analyze by function, level, and tenure. Surface-level aggregates are useful for tracking trends over time but dangerous for making go-no-go decisions.
Common Mistakes That Waste Money and Time
Most organizations mess up the timing. They run the assessment right before a change is already locked in. At that point the tool functions as a validation exercise rather than a diagnostic. People know the decision is made. They respond strategically. The data reflects impression management more than actual readiness. You should run the assessment early enough that the results can change the plan. If the plan cannot change based on the results, you are not doing an assessment. You are doing propaganda. Another frequent error is confusing readiness with resistance. Readiness is about capacity and willingness. Resistance is about opposition or obstruction. You can have high readiness with low resistance and get smooth implementation. You can have high readiness with high resistance and get a technically sound but politically toxic rollout. The ORC questionnaire does not measure resistance directly. It measures readiness. If you need resistance data, you must add separate items or use a different instrument. Mixing the two constructs in one survey produces incoherent results. A third mistake is treating readiness as a static property. It is not. Readiness changes as information flows, as people experience early signals, and as the organizational context shifts. A single snapshot tells you the state at that moment. It does not tell you whether the state will hold. If you are running a major transformation, I recommend at least two measurement waves. The first wave establishes a baseline before any public announcement. The second wave comes after initial communication but before execution begins. The delta between waves is often more informative than either score alone. It shows whether your messaging and early actions are moving the needle or creating reactive dips.
Advanced Nuances Beginners Miss
One counter-intuitive finding from the research literature is that high readiness does not guarantee successful implementation. The correlation between readiness scores and implementation outcomes is moderate at best, usually around 0.4 to 0.5 in published studies. Readiness is a necessary but not sufficient condition. You still need adequate resources, competent leadership, coherent change design, and ongoing support structures. A team can be highly ready and still fail because the change design is flawed or the resource plan is underfunded. Do not let high readiness scores make you complacent. Treat them as a green light to proceed, not as a prediction of success. Another nuance is the difference between individual and group readiness levels. The ORC scale is administered at the individual level but interpreted at the group level. When you aggregate individual responses to create a departmental score, you assume homogeneity within the group. That assumption is often wrong. A department might have a mean score of 3.8, which looks acceptable. But if the distribution is bimodal with half the team at 2.0 and half at 5.6, the mean hides a serious fracture. Always check the standard deviation and distribution shape before trusting the mean. If the standard deviation exceeds 0.8 on any subscale, flag the group for qualitative follow-up even if the mean passes your threshold.
There is also a cultural dimension that most Western-developed instruments underweight. In high-power-distance cultures, respondents tend to avoid negative ratings because they do not want to contradict authority. In collectivist cultures, respondents may rate commitment higher than they personally feel because they prioritize group harmony over individual dissent. If you are running this assessment across multiple countries or cultural contexts, you need to validate the instrument for each context or adjust your interpretation accordingly. A score of 3.5 in one cultural setting may represent the same underlying readiness as a score of 4.2 in another.
When This Approach Fails Completely
Readiness assessments do not work when the organization is in survival mode. If layoffs, acquisition, bankruptcy proceedings, or regulatory intervention are active, people cannot engage with hypothetical change scenarios honestly. Their cognitive bandwidth is consumed by immediate threats. Any scores you collect in that environment are noise. I have seen projects waste months on readiness assessments during active restructuring and then wonder why the data looked flat and uninformative. Skip the assessment in survival scenarios. Rely instead on direct observation, exit interview data, and informal check-ins with people who understand the operational landscape.The tool also fails when the change is so radical that people lack the reference points to evaluate it. If you are asking whether a team is ready for an AI-driven workflow redesign and they have never encountered that technology, their responses will be random or heavily influenced by fear rather than informed judgment. In those cases, you need a different approach. Run exploratory sessions first. Provide education and exposure. Then reassess. Readiness requires a minimum level of understanding. You cannot measure willingness to adopt something people do not comprehend.
Practical Steps for Your Next Assessment
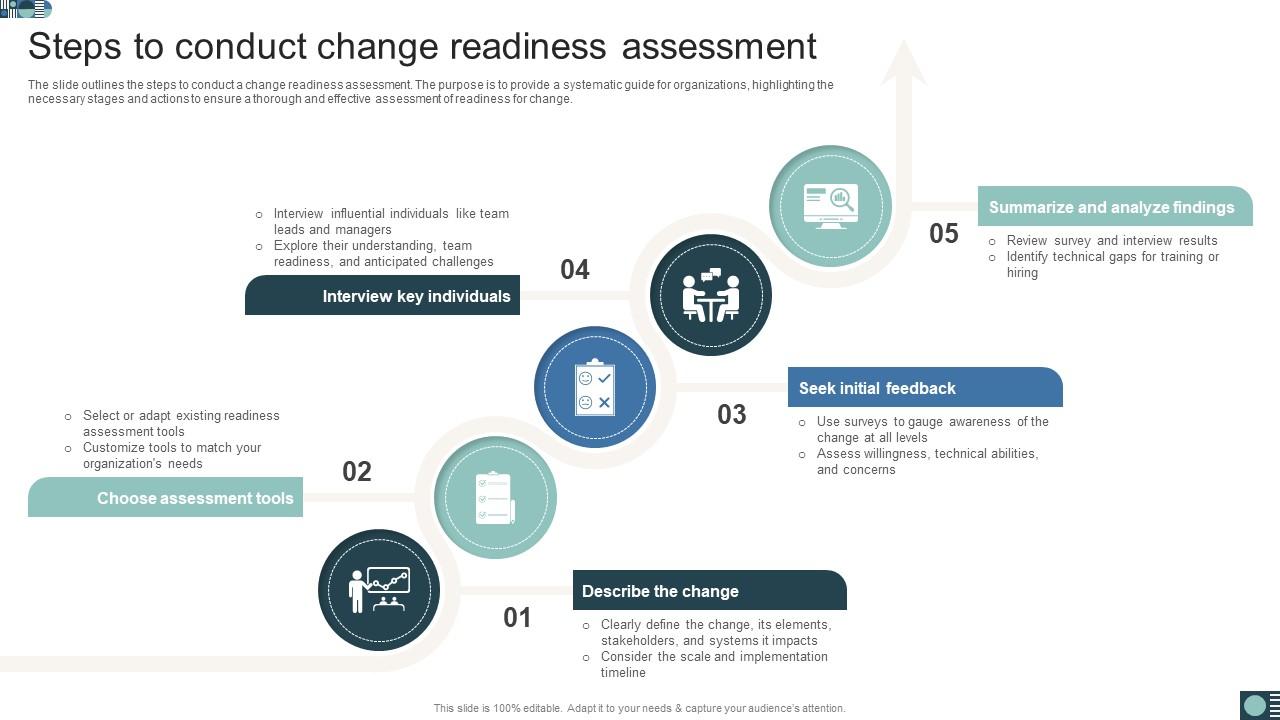
Start by defining the specific change you are assessing readiness for. Generic readiness is meaningless. You need to know exactly what behavior, process, or system the organization must adopt. Write that down in one sentence before you touch any instrument. Then select the measurement tool. The 16-item ORC scale is the default choice for most situations. If your change involves significant resource requirements, add items from the Organizational Resources for Change scale. If your change crosses cultural boundaries, validate the instrument or use a culturally adapted version.Next, decide on your sampling strategy. A full census is ideal but rarely practical. Stratified random sampling by function, level, and tenure gives you representative data with reasonable sample sizes. Target at least 30 respondents per stratum for stable subscale estimates. Fewer than that and the confidence intervals become too wide to act on. If your organization is small, a full census is cheaper than dealing with uncertain estimates. Administration should happen in a low-pressure environment. Do not frame the survey as a high-stakes test. People perform differently when they think they are being evaluated. Position it as a tool to help the organization prepare adequately. Be transparent about what you will do with the data and who will see it. Anonymity increases honest responding. Confidentiality at the group level prevents individual identification. Both matter for data quality. Analysis should produce three outputs. First, subscale scores by demographic and functional segment. Second, distribution diagnostics including standard deviations and skewness. Third, a gap analysis comparing current readiness against the threshold needed for your specific change type. Not all changes require the same readiness level. A minor software update needs lower readiness than a fundamental business model shift. Define your threshold explicitly rather than applying a universal cutoff.

The final output is not a report. It is a set of action recommendations. Each low-scoring segment should have a targeted intervention plan. Low commitment might require clearer communication about why the change matters. Low self-efficacy might require training or pilot programs. Low resource confidence might require budget reallocation. Map each gap to a specific remedy. An assessment without an action plan is just a data collection exercise that consumes time and generates cynicism. I have seen organizations repeat this process every twelve to eighteen months as part of normal governance. Others run it once per major initiative. There is no universal rule. The cadence should match the pace of change in your environment. Fast-moving organizations benefit from more frequent measurement. Stable organizations can space it out. What matters is treating the assessment as a living diagnostic rather than a box-checking ritual. The moment you treat it as a compliance task, the data degrades and the process becomes expensive theater.


