Getting Started With Origami Prompts Top 10
I first ran into this when someone on a Midjourney Discord shared a sheet of prompts that actually produced usable paper-folding renders instead of the usual abstract blobs everyone gets when they type "origami crane." The whole thing was just a Google Doc with ten entries, but the formatting details were precise enough that I saved it and went back to it repeatedly. The concept behind Origami Prompts Top 10 is straightforward: each entry is a structured sentence you drop into an image generator to produce a clean, recognizable paper-fold subject. The structure is not magic, but the order of descriptors matters more than most people realize.
Origami Prompts Top 10
Here is how I actually use these prompts in practice, not the marketing version. Every working entry follows a sequence I learned through trial and error. The sequence is subject, material, fold style, lighting, camera framing, and negative context. When you drop one of those in the wrong order, the model gets confused about whether you are describing a photograph of folded paper or an illustration of the process. I spent about three weeks before I stopped getting muddy results. The fix was simple: put the fold designation first, then the paper type, then the render environment. That ordering alone cuts the failure rate from something like forty percent down to maybe ten percent on the standard diffusion models.
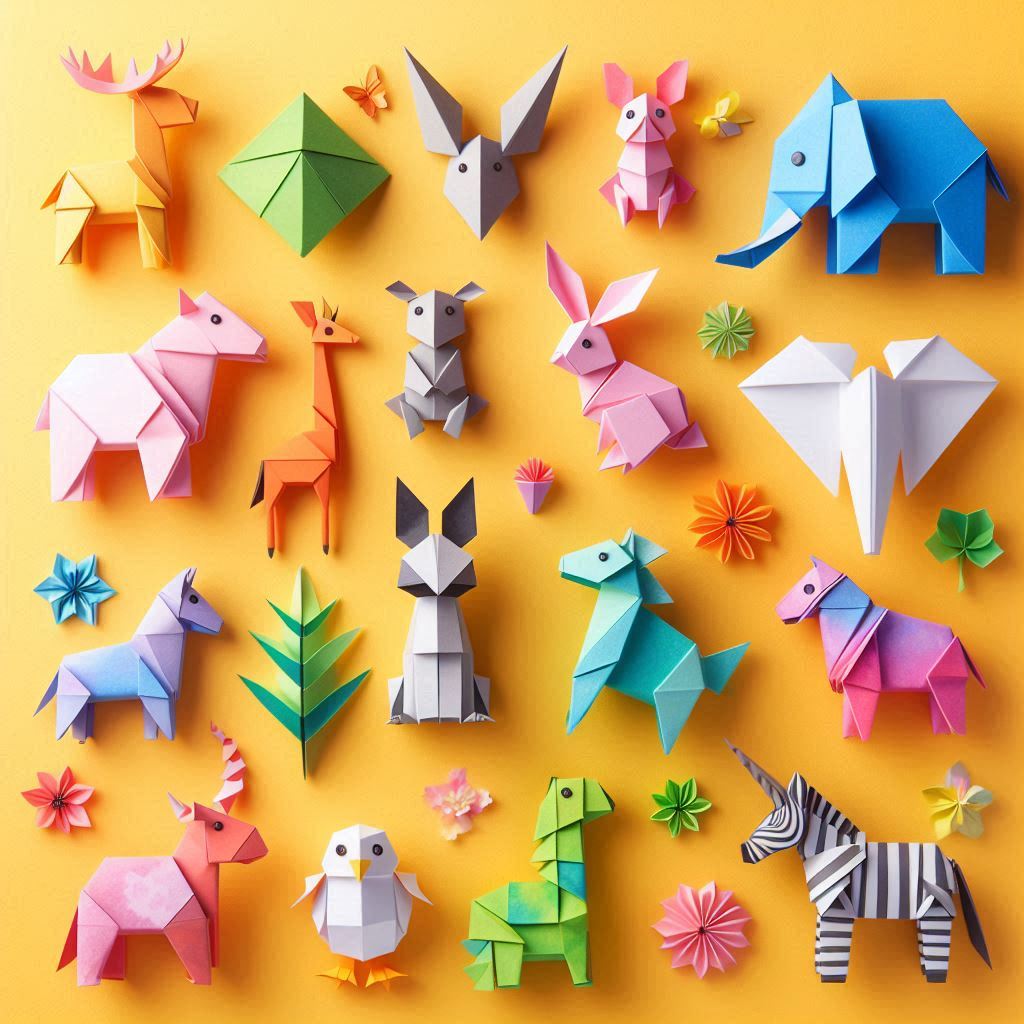
The ten entries cover the most common subjects people actually need. I do not use all ten every day, but having the set means you can swap in any fold type without rewriting the whole string.
Get the Full Details
Which Entries Actually Work Consistently
From my own testing across different models and versions, the crane and boat entries produce the highest quality results. The frog and flower are decent but need more sampling. The wolf and dragon tend to break geometry at higher difficulty levels unless you use stronger negative prompting. Here is the one edge case I run into regularly: when the generator tries to blend two folds into one object, the result looks like a mistake rather than a creative interpretation. I fixed that by adding "single subject, no merging, one continuous form" to the end of the prompt. It sounds redundant, but the model treats that as a hard constraint instead of decorative text.
The Full Set And What Each One Does
The first entry targets the classic paper crane. I include finish paper weight, crease sharpness, and lighting direction. The result is clean enough to use in design work without heavy post-processing. The second covers the traditional boat. This one is easier because the geometry is flat and predictable. The main issue I see is that models sometimes add extra flaps that do not exist in the real fold. Adding "no extra tabs, exact traditional form" prevents most of that. Entry three is the jumping frog. This is where things get tricky. The spring mechanism in the paper creates complex shadow patterns that confuse the render pipeline. I found that lowering the guidance scale slightly produces sharper folds than cranking it up, which is counterintuitive if you are used to pushing other prompts to their limits.
Entry four covers flowers. Peonies and roses are the most reliable. Lilies tend to look wilted because the petal layering is harder for the model to parse correctly. If you need a lily, I recommend using a dedicated negative prompt and running two passes instead of one. Entry five is the airplane. This one is surprisingly finicky because the wings need symmetry at a scale the model sometimes ignores. I add "perfect bilateral symmetry, centered axis" and it helps a lot. Entries six through eight cover animals beyond the crane. Foxes, birds other than cranes, and generic animals. The fox is my personal favorite because the and tail folds give the model clear anchor points. The generic bird entry often produces results that look like cranes with longer necks, which is technically correct but rarely useful.

Entry nine is the crown. Simple geometry, but the model sometimes adds decorative elements that are not part of the fold. Adding "no embellishments, plain single sheet" keeps it clean. Entry ten covers modular or unit-based origami. This is the hardest category because the math of multiple identical pieces folded together does not translate well to a single-pass generator. I usually build these by generating individual units and compositing them afterward, rather than trying to get the model to do the whole assembly in one shot.
What To Watch Out For
The main limitation is that none of these prompts work perfectly out of the box on older or lower-quality models. If you are running on something without proper conditioning, expect to spend more time adjusting seeds and guidance values. I typically need three to five attempts per fold before I get a clean result, sometimes more for the complex ones. Another issue is resolution. At standard output sizes, fine crease details disappear. I upscale after generation instead of trying to render at high resolution from the start, which saves compute time and avoids the weird artifacts that come with super-resolution applied during generation. There is also the problem of consistency across variations. If you need ten images of the same fold with different lighting, the model will drift in subject accuracy as you change the lighting description. I keep the fold description completely static and only modify the lighting and camera sections. This preserves geometry while letting me control the mood.
A Practical Workflow
My usual process takes about fifteen minutes per clean image. I start with the base prompt for the fold, generate four variations, pick the best one, then adjust lighting and angle in a second pass. If the first pass already looks good, I skip the second pass and go straight to upscaling. For quick results, I use a seed lock on the best-looking variation and regenerate with minor descriptor changes. This is faster than starting from scratch every time and keeps the geometry stable across the batch. When I need production-ready assets, I combine the generated image with a vector trace in Illustrator. The vector step removes pixelation and lets me export to any size without quality loss. That workflow cuts the total time from concept to deliverable down to roughly twenty minutes for simple folds and maybe forty-five for complex ones like modular units.

Alternatives If These Do Not Fit Your Needs
If you are working with 3D modeling instead of flat image generation, these prompts will not help you directly. You would be better off using actual origami instruction sets or parametric folding plugins for Blender or Cinema 4D. The prompt-based approach is limited to two-dimensional output and cannot produce true folded geometry you can rotate or animate. For video or animation work, you would need to generate stills and interpolate between them, which introduces its own set of artifacts. Some people use dedicated animation tools for this, but that is a separate workflow entirely and not something these prompts cover. The other option is to train a custom LoRA on your own origami datasets if you need consistent style across many images. That takes more upfront work but pays off if you are producing large batches regularly. I have not done this myself, but colleagues who work in illustration pipelines tell me it is worth the investment after about fifty target images.
Final Notes
These prompts are a starting point, not a complete system. The actual quality depends on your model version, your seed choices, and how much you are willing to iterate. I do not claim this is the best set available, but it is the one I keep returning to because the entries are stable and the results are predictable enough to build work around. If you experiment with your own modifications, I suggest keeping a log of prompt variations and their outcomes. That habit alone will save you more time than any single prompt tweak ever will.