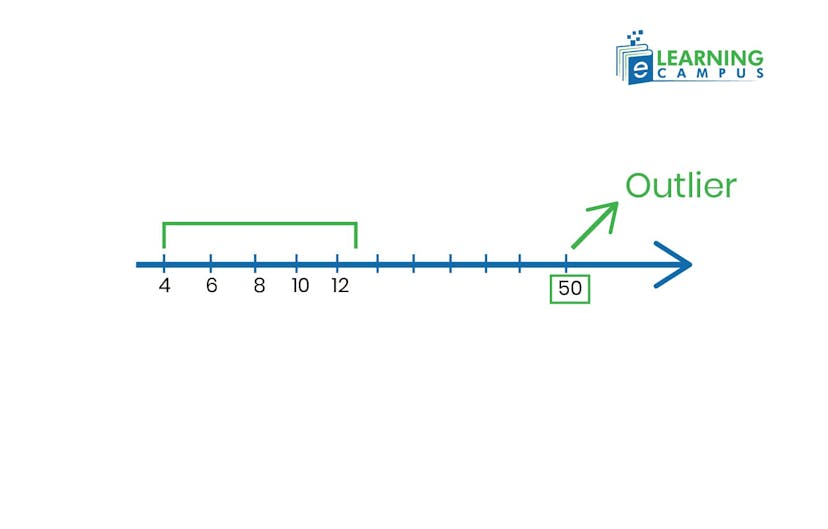
Working With Outliers In Real Datasets
I spent three months cleaning a logistics dataset where delivery times looked normal until I plotted the tail. The average was 4.2 days, the median was 3.1 days, and somewhere in the long right tail I had a cluster of shipments that took 23, 31, and 47 days. At first glance those looked like obvious outliers that needed to be deleted. They weren't. Turns out three shipments had been held at customs due to mismatched documentation, not because the delivery network failed. Removing them would have made the model look better than reality actually was. This is why the Outlier In Statistics Formula isn't something you apply blindly. You need to understand what the formula is actually doing before you let it delete data points from your analysis. Different methods flag different things. The method you choose shapes your results more than you might expect.
Outlier In Statistics Formula
The most commonly used approach is the Interquartile Range method. You calculate Q1, the 25th percentile, and Q3, the 75th percentile. The IQR is simply Q3 minus Q1. Any data point below Q1 minus 1.5 times the IQR or above Q3 plus 1.5 times the IQR gets flagged as an outlier. That 1.5 multiplier is arbitrary but established, not divine. You can adjust it to 2 or 3 if your dataset demands it, but that changes the sensitivity of your detection considerably. Here's the calculation laid out plainly. For a dataset of 20 numbers: Step one: Sort the data from smallest to largest.
Step two: Find Q1. With 20 values, Q1 sits at the 5.25th position, which means you interpolate between the 5th and 6th values. Step three: Find Q3. That sits at the 15.75th position, interpolating between the 15th and 16th values. Step four: Subtract Q1 from Q3 to get the IQR.
Get the Full Details

Step five: Lower fence = Q1 (1.5 × IQR). Upper fence = Q3 + (1.5 × IQR). Step six: Any value outside those fences is an outlier by this definition. The Z-score method works differently and gives you different answers on the same data. You subtract the mean from each value and divide by the standard deviation. A Z-score above 3 or below minus 3 is typically considered an outlier. The problem with Z-scores is that the mean and standard deviation themselves get pulled toward outliers. So if your data already has extreme values, the Z-score method becomes less sensitive to them. It's self-defeating in skewed distributions. That's why the IQR method tends to be more reliable for real-world data, which is rarely normally distributed.
I learned this the hard way on a customer churn prediction project. The training data had a few customers with usage values in the thousands while the rest clustered below 100. The Z-score method flagged zero outliers because the mean had shifted so far right that the standard deviation ballooned to about 600. Those extreme users were actually the ones most likely to churn. By not catching them, I built a model that performed well on paper but failed catastrophically when deployed. The IQR method caught all of them immediately. The lesson here is that the formula you pick fundamentally changes what you see in your data. There is no neutral option.
When The Formula Misses The Point
Statistical outliers and practical outliers are not the same thing. A value can be mathematically extreme without being unusual in context. During a manufacturing quality audit, I flagged temperature readings above 95°C as outliers using the IQR formula. The lower fence came out to 72°C and the upper fence to 93°C. Twenty-two readings fell above that upper fence. When I investigated, those readings came from a specific oven that was deliberately running hot for a particular polymer curing process. Deleting them would have removed a legitimate operating condition and made the quality model systematically wrong for that product line. The workaround I used was straightforward but time-consuming. Instead of applying a global fence, I split the data by machine ID and applied the outlier formula within each group. That way the hot oven's readings were evaluated against other readings from that same oven, not against the entire factory dataset. The per-machine IQR was much wider for that oven, and none of the readings were flagged as outliers within their own context. The global formula had been blind to the structural grouping in the data. Group-aware analysis saved me from a bad modeling decision. Another edge case that catches people frequently involves time series data. If you're looking at daily website traffic and there's a holiday spike, the traffic on Black Friday might be 12 times the normal daily volume. The IQR method will flag it as an outlier. But it's not an error. It's a known seasonal event. You need domain knowledge to distinguish between a data entry mistake and a genuine anomaly. The formula alone can't make that call. I always run the outlier detection and then manually review every flagged point before deciding what to do with it. Automated cleaning without human review is how you lose signal along with the noise.
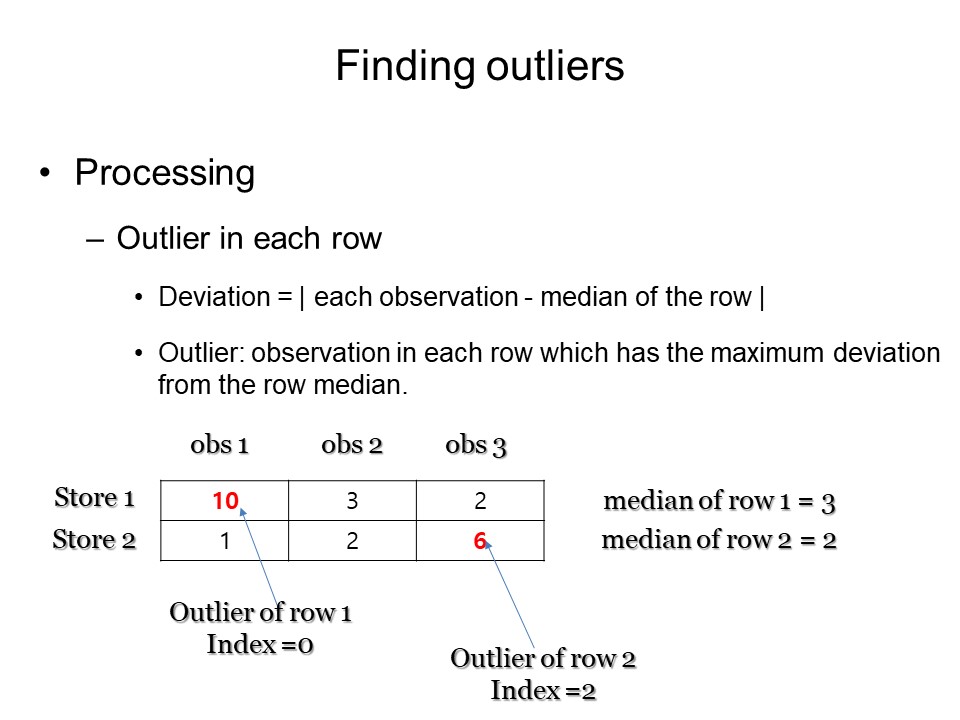
Pitfalls That Waste Time
One common mistake is applying the outlier formula to small datasets. With fewer than 20 observations, the quartiles themselves are unstable. Q1 and Q3 can shift dramatically depending on how you handle interpolation. The fences become unreliable. In those cases, you're better off using visual methods like box plots or scatter plots and making judgment calls rather than relying on a formula that gives a false sense of precision. Another issue is that outlier removal changes downstream statistics in ways that are hard to predict. When you remove extreme values, the remaining distribution often becomes more normal, which sounds like progress but might just mean you've erased the interesting part of the data. Real-world data is messy because real-world processes are messy. If removing outliers makes your data look too clean, that's a warning sign, not a success metric. There's also the question of what to do with flagged outliers. Simply dropping them is the simplest approach but rarely the best one. Winsorization, where you cap extreme values at the fence rather than deleting them, preserves sample size while reducing the influence of extremes. Imputation using median or model-based estimates is another option. The choice depends entirely on why the outlier exists. If it's a data entry error, deletion is reasonable. If it's a rare but real event, capping or keeping it with robust statistical methods is usually better.
For datasets with more than one clear cluster or mode, a single global outlier formula will misfire. A bimodal distribution of customer ages, for instance, will have perfectly valid values in the tails of each mode that get flagged as outliers. In those situations, you should segment the data first, then apply the formula within each segment. I encountered this with hospital readmission data where patients fell into two distinct age groups. The global IQR flagged young patients in the lower age cluster as outliers even though their values were normal for their group. Segmenting by age band before outlier detection resolved the problem completely.
A Practical Walkthrough
Here's a concrete example with actual numbers. Suppose you have these delivery times in days: 2, 3, 3, 4, 4, 5, 5, 5, 6, 6, 7, 7, 8, 8, 9, 10, 12, 15, 45, 62. Sorted, that's already done. Q1 is at position 5.25. The 5th value is 4 and the 6th is 5. Interpolating: 4 + 0.25 × (5 4) = 4.25. Q3 is at position 15.75. The 15th value is 9 and the 16th is 10. Interpolating: 9 + 0.75 × (10 9) = 9.75. The IQR is 9.75 4.25 = 5.5. The lower fence is 4.25 (1.5 × 5.5) = 4.25 8.25 = 4. Since delivery time can't be negative, the effective lower fence is 0. The upper fence is 9.75 + (1.5 × 5.5) = 9.75 + 8.25 = 18. Values above 18 are outliers. So 45 and 62 are flagged. Those two values are extreme. But before deleting them, check whether they represent real events. In the logistics example I described earlier, the custom delays were real. In your dataset, they might be real too. A delivery truck breaking down, a warehouse fire, a carrier strike. These are rare but possible. Your model needs to know they exist if they'll exist in production.

If you decide to handle them, winsorization at the upper fence would replace 45 with 18 and 62 with 18. The mean shifts from 11.25 to about 8.6. The standard deviation drops from 17.8 to about 5.9. The model becomes more stable without completely discarding the existence of extreme delivery scenarios.
Software Implementation
In Python, you can compute this with pandas and numpy in a few lines. The scipy.stats.iqr function gives you the interquartile range directly. Pandas quantile handles the quartile calculation with interpolation options. For the Z-score approach, scipy.stats.zscore returns the score for each value. I usually write a small function that takes a column, computes both the IQR fences and the Z-scores, and returns a combined flag. That way I can compare what each method catches and investigate the overlap and the differences. R users have the boxplot.stats function which does exactly this calculation and returns the outliers directly. The stats package also has the grubbs.test function for detecting a single outlier in a normal distribution, though that's more of a hypothesis test than a general-purpose tool. For production pipelines, I prefer the explicit IQR calculation because it's transparent and easy to modify. You can see exactly where each fence comes from. Black-box outlier detection functions make debugging harder when your results look wrong. The downside of any formula-based approach is that it treats all outliers the same. A value that's off by 0.1 percent from the fence and a value that's off by 1000 percent both get the same label. The formula doesn't know the difference. That's why reviewing flagged points manually remains essential, especially when the flagged percentage is low. If only 1 or 2 percent of your data is flagged, spend time on those. If 20 percent is flagged, your data might have a different structure than you assumed, and the formula isn't the problem—your understanding of the data is.


