How to Actually Get Pages Out of a PDF Without Breaking Everything
Removing pages from a PDF is one of those things that sounds trivial until you actually do it and realize every tool handles it slightly differently. I've spent years dealing with this, mostly because people send me PDFs that were generated by systems that don't treat page deletion as a simple operation. The result is often a corrupted file or one that looks fine but breaks downstream workflows like OCR, form filling, or batch printing. The process depends heavily on what you're starting with. If you have a straightforward PDF where pages are independent content blocks, extraction is mechanical. You open the file, select the pages you want to keep or discard, and the tool rewrites the document structure. But PDFs are not always well-behaved. Sometimes pages share resources, fonts are embedded inconsistently, or the page object tree is tangled from a scanner or a poorly configured export. That's where most people run into trouble.
The Straightforward Page Remove From Pdf Approach
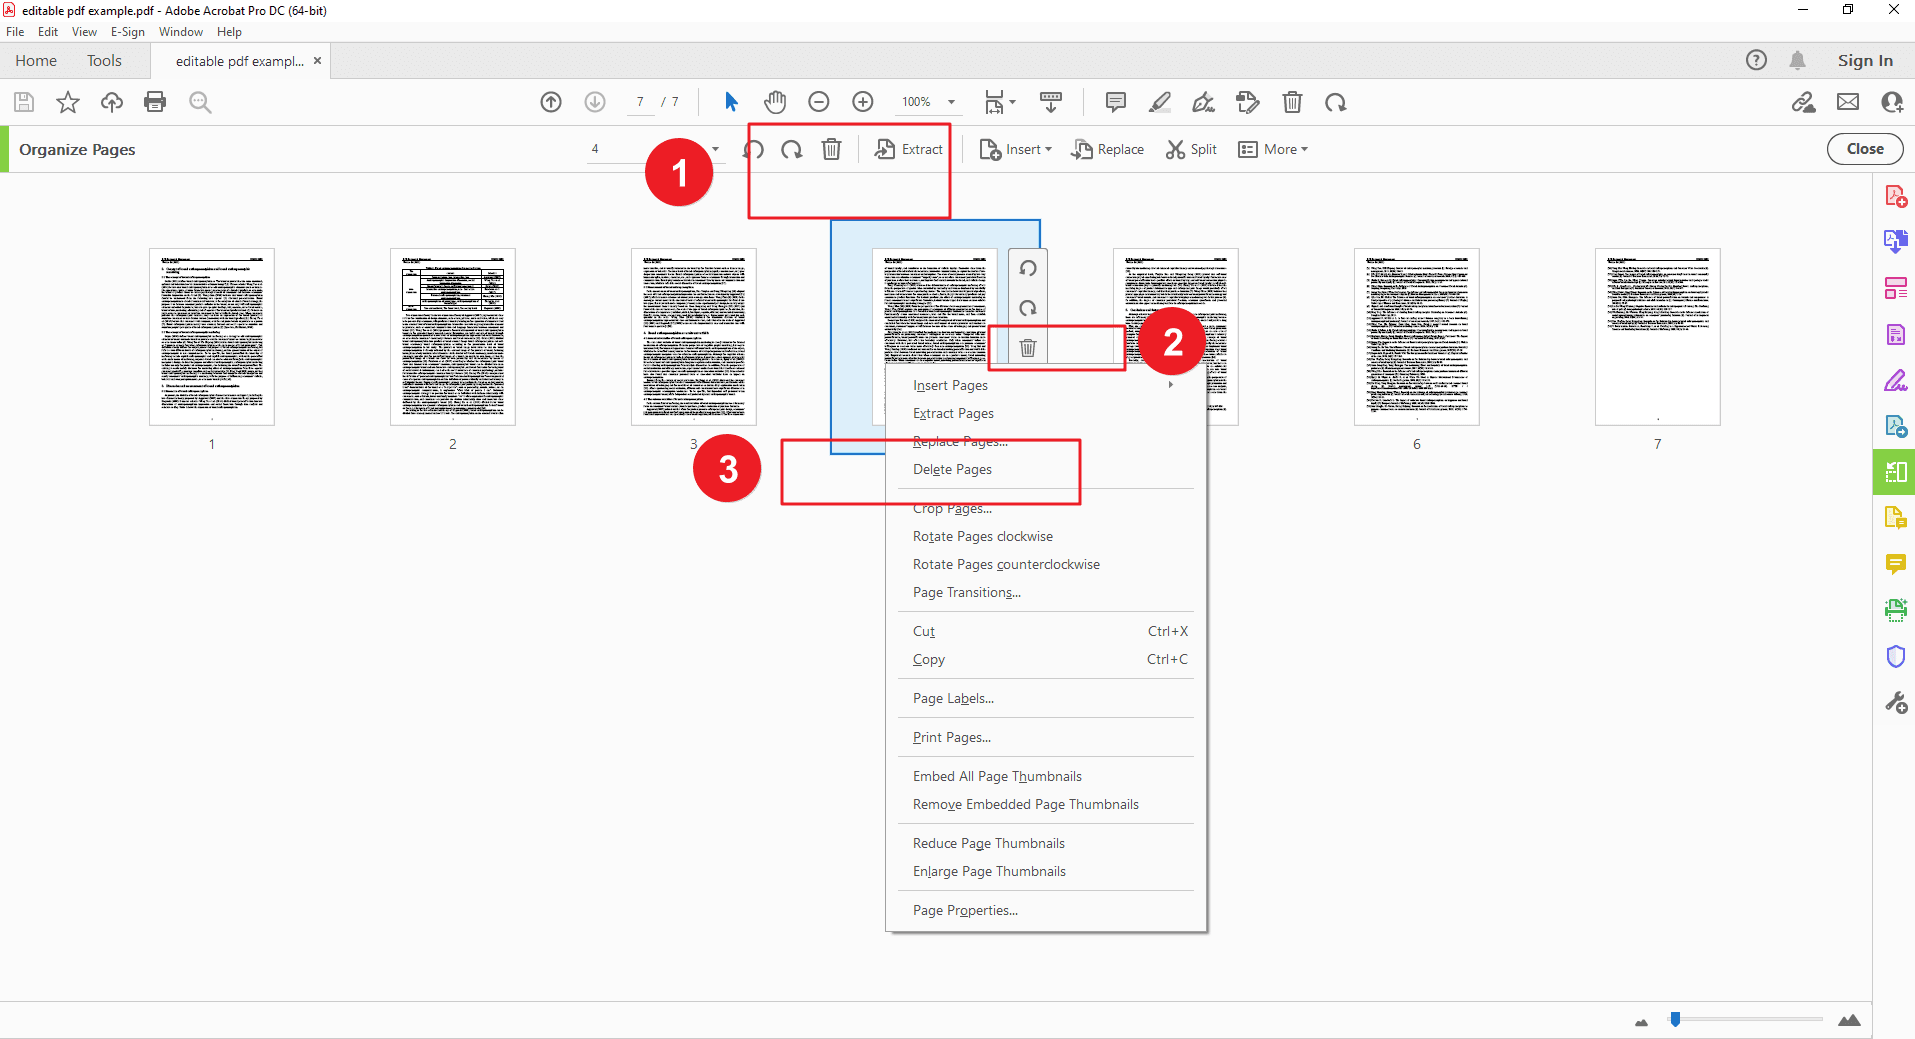
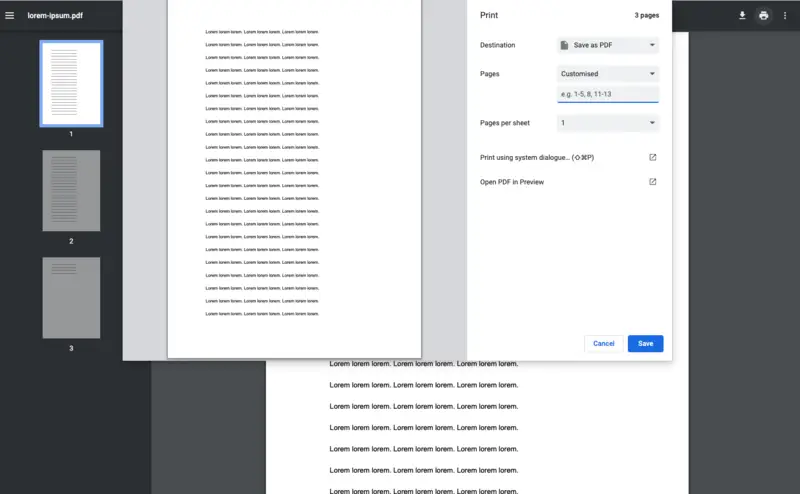
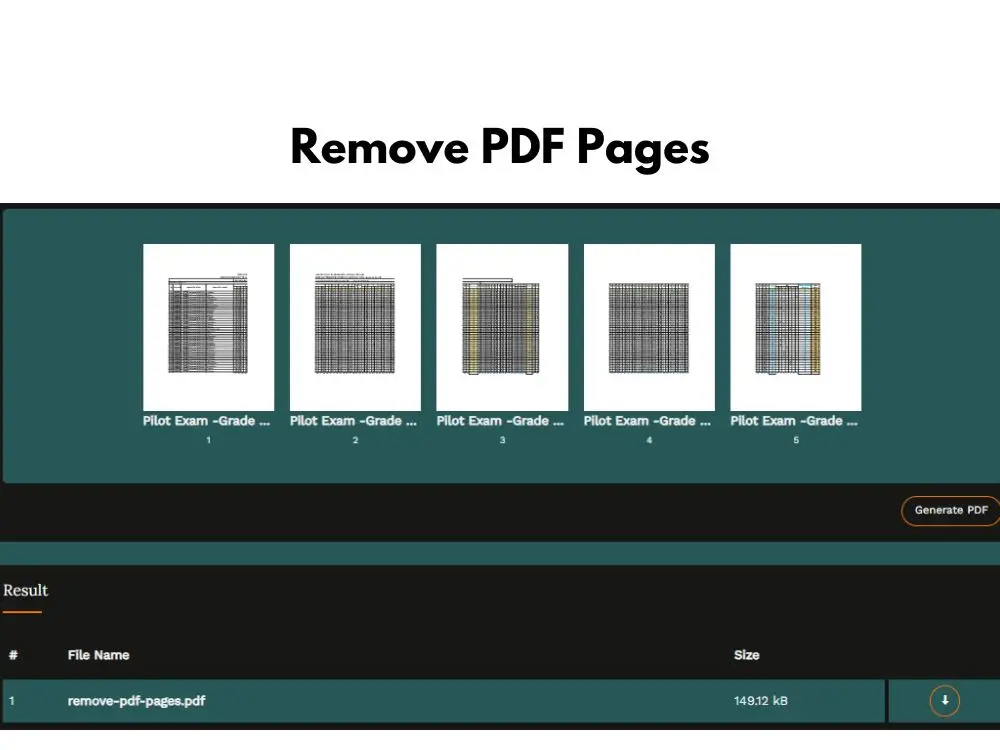
If you just need to strip pages quickly and the PDF is clean, a dedicated tool is your best move. There are several options available online for Page Remove From Pdf, and they generally work the same way: you upload or open the file, tick the pages you want removed, and export. Some of these tools run entirely in the browser using JavaScript-based PDF libraries like pdf-lib or PDF.js. Others require a desktop application that manipulates the raw PDF structure directly. Browser-based tools are convenient but can choke on large files or corrupted documents. Desktop applications tend to handle edge cases better, especially when the PDF has complex internal objects. When I need to do this regularly, I use a combination of command-line tools. Python with PyPDF2 or pypdf, or the qpdf command-line utility, both give you programmatic control. Here's what the actual workflow looks like in practice: Open the PDF, identify which page numbers need to go, run the extraction script, verify the output. That's it in theory. In practice, you also have to check that the page numbers in the visual document match the page numbers in the tool's selection interface. PDFs number pages from zero internally in many libraries, but the viewer shows them from one. This off-by-one error costs me more time than anything else in this process.
What Goes Wrong and How to Fix It
I once worked with a 400-page technical manual that had been assembled by merging three separate PDFs created on different systems. The page ordering was correct visually, but the internal object references were inconsistent. When I used a standard browser-based remover, it dropped the wrong pages because the tool read the page tree structure rather than the logical flow. The workaround was to flatten the document first using qpdf with the --linearize flag, which reorganizes the internal structure into a consistent order before any page manipulation. That took about two minutes on a 12MB file and made the subsequent removal accurate. Another common issue is that some PDFs use form fields or annotations tied to specific pages. When you remove a page, those annotations can become orphaned references that cause readers to display warnings or render the file incorrectly. I always do a quick validation pass after removal by opening the output in a second PDF reader and scrolling through every page to make sure nothing is broken or missing. This catches issues that automated validation often misses.
Get the Full Details

Tools I Actually Use
For one-off jobs, I reach for a browser-based tool like iLovePDF or Smallpdf. They handle most routine cases without requiring any installation. The tradeoff is privacy and file size limits. If the PDF contains sensitive data, I don't upload it anywhere. For that, I use a local tool. PDFescape has a desktop version that works offline. Qpdf is free and runs from the command line, which is why I prefer it for batch operations. Adobe Acrobat remains the most reliable option for complex documents because it understands the full PDF specification, but it's not free and overkill for simple deletions. If you're looking for a direct Page Remove From Pdf solution online, tools like iLovePDF's page removal tool, Smallpdf, or PDF24's page removal utility cover the basics. For offline work, qpdf and pypdf for Python are solid choices.
When Deletion Isn't the Right Move
Sometimes you think you need to remove pages but you actually need to hide them. If the goal is to create a subset for distribution without altering the original file, masking or blocking pages is safer than deletion. You can overlay a white rectangle on the pages you want to hide and save it as a new file. This preserves the original structure and makes it easy to reverse. I've seen people delete pages from a PDF that turned out to be a legally significant document, only to regret it later when they needed the complete record. Never delete from a source file you might need again. Always work on a copy. There's also the case where page removal creates a file that no longer opens correctly in older PDF readers. This happens when the tool removes pages but leaves behind reference entries in the PDF's cross-reference table. The fix is to run the output through a repair tool or re-save it with a full rewrite pass. qpdf handles this automatically with its default behavior, but lighter tools sometimes skip this step to save time, which is where the corruption appears. The whole process usually takes between five and fifteen minutes for a standard document, longer if you're dealing with a problematic file that needs flattening or repair first. If your PDF is simple, browser tools will get it done fast. If it's complex or sensitive, invest the extra ten minutes in a local tool and a validation pass. The difference between a working file and a broken one is almost always in those final verification steps.