Understanding Base Pairing Beyond the Textbook
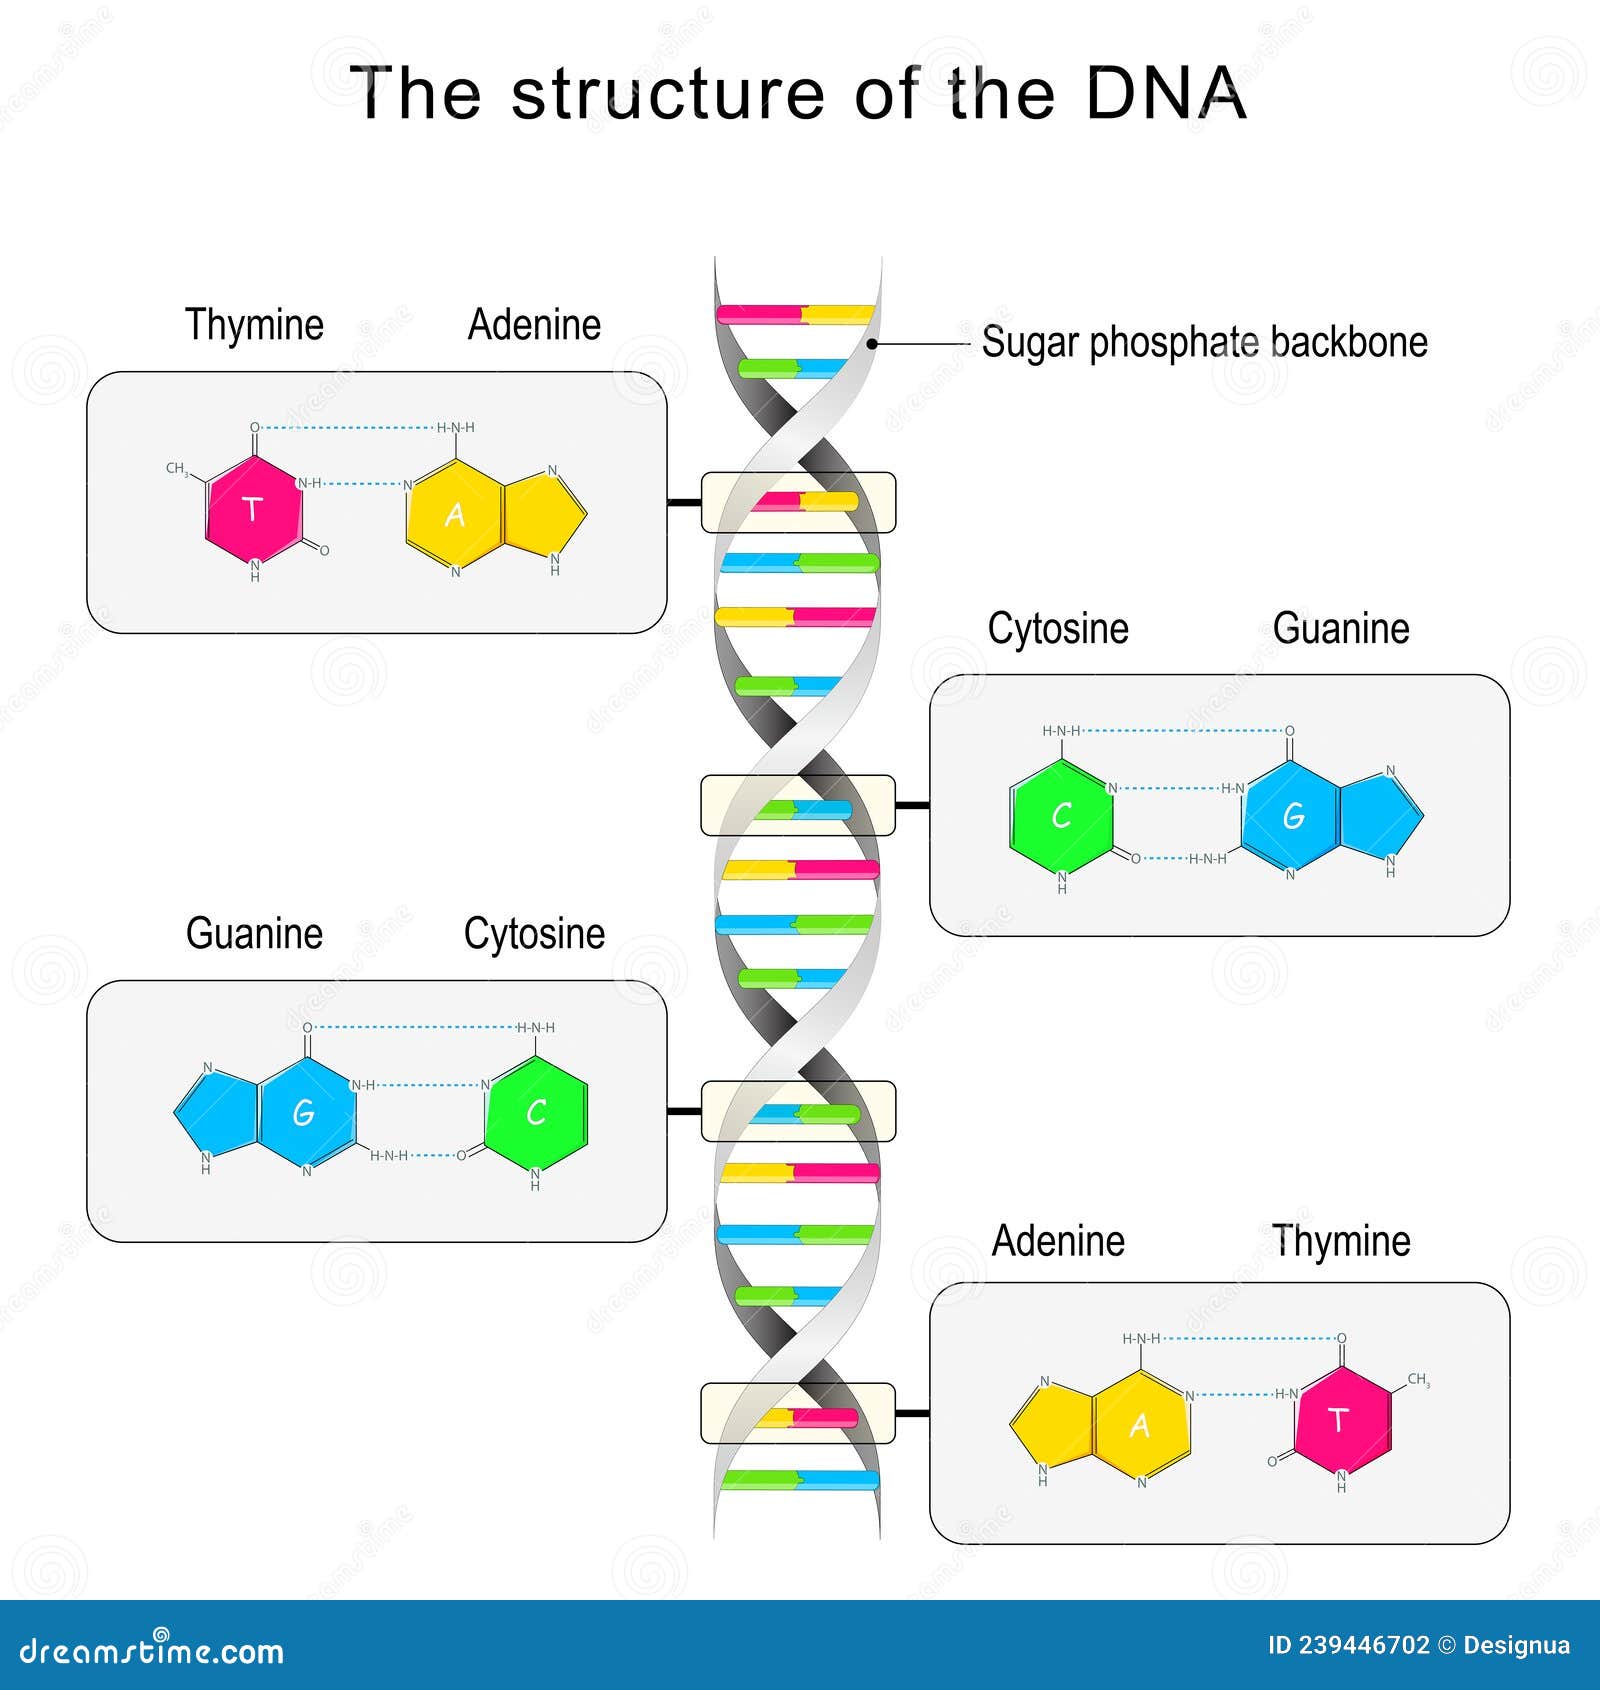
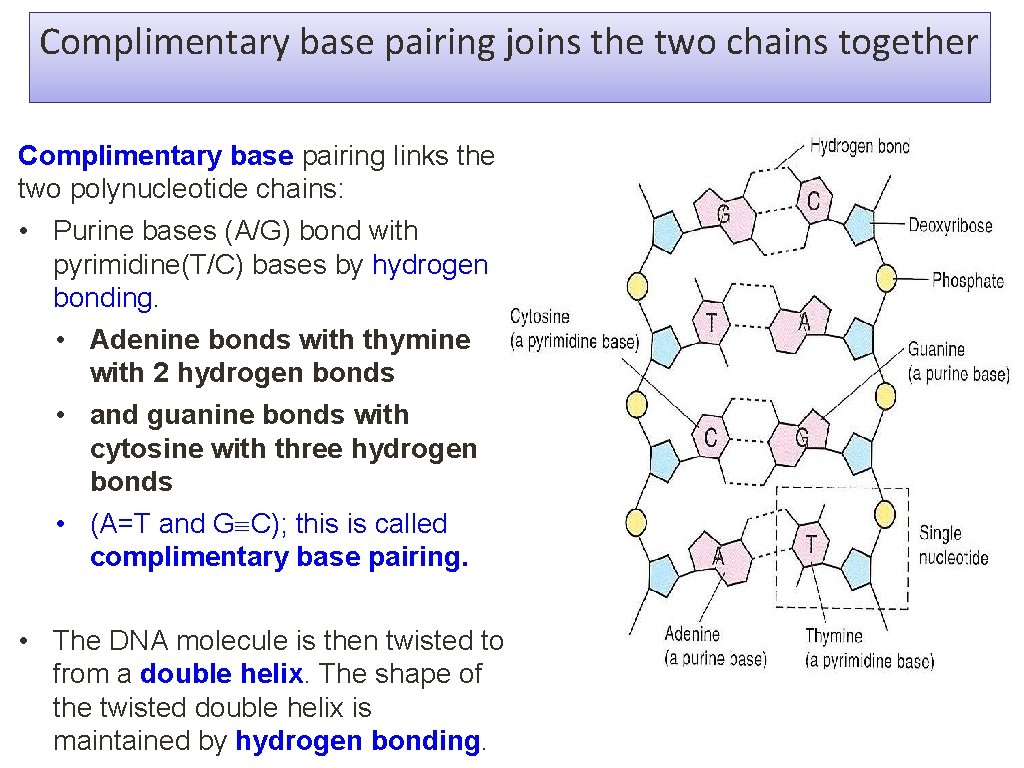
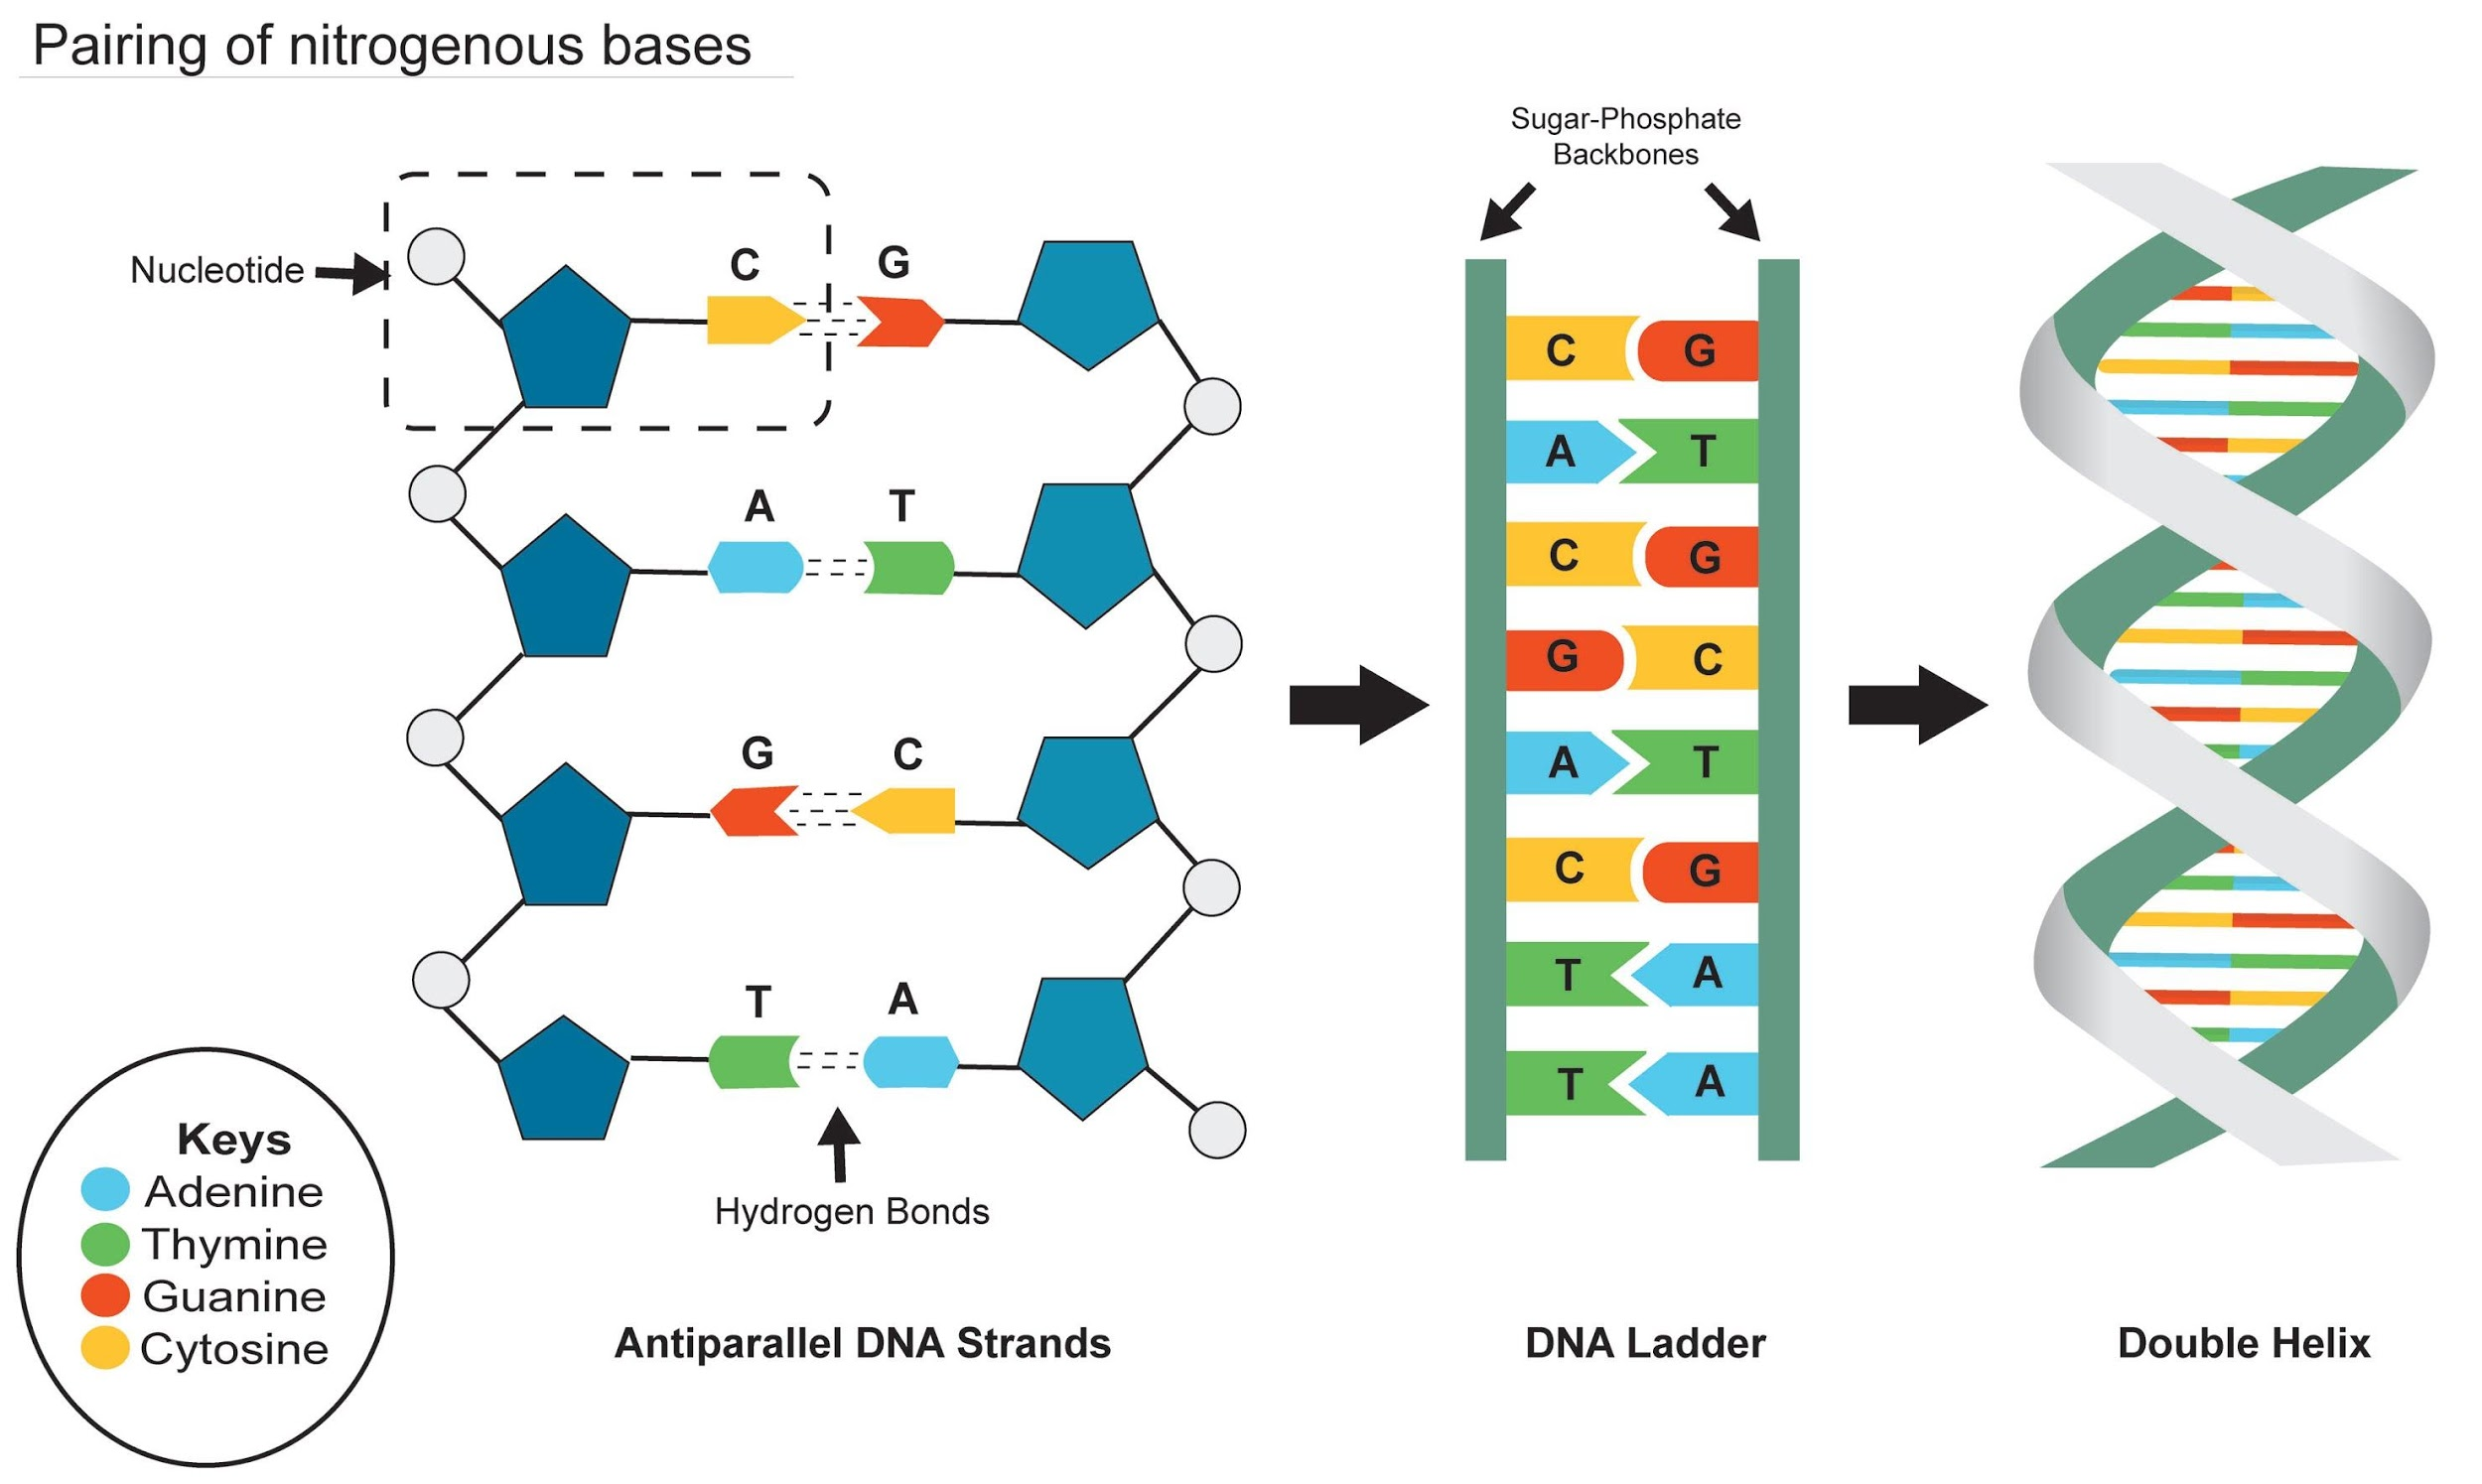
Most people learn about DNA base pairing in high school biology and never really dig deeper. The standard A-T, G-C rule is accurate for normal conditions, but the moment you start working with actual sequencing data or primer design, you quickly run into edge cases that the textbook doesn't cover. I spent years doing primer design and hybridization work, and the things that trip people up are usually the same things that trip me up every time. Watson-Crick pairing (A with T, G with C) is the default model, but wobble pairing exists and it matters. Guanine can pair with uracil in RNA contexts, and mismatches happen more often than people expect, especially at the ends of primers or in repetitive sequences. When I was optimizing PCR conditions for a difficult GC-rich template, I kept getting non-specific bands no matter what I changed. The issue turned out to be that my primer had a G-T mismatch near the 3' end that was being tolerated by the polymerase. Moving that mismatch to the 5' tail completely fixed the specificity. The 3' end of a primer is where extension happens, so even a single mismatched base there can cause real problems. It's one of those things that's not emphasized enough in introductory courses. Melting temperature calculations also get tricky when you're dealing with unusual base compositions. The basic formula Tm = 4(G+C) + 2(A+T) works for short oligos under 14 nucleotides, but once you go longer, you need the more sophisticated nearest-neighbor model. I've seen people use the simple formula for 25-mer primers and wonder why their annealing temperatures were off by five or six degrees. That's a big deal when you're trying to optimize a reaction.
Another thing nobody warns you about: modified bases. If you're working with methylated DNA or any kind of bisulfite-treated sample, cytosine gets converted to uracil during the process. So what you're actually analyzing is a mixture of original cytosines and converted ones, and the pairing behavior changes entirely. Standard alignment tools will misinterpret this if you don't tell them you're working with bisulfite-converted sequences. I wasted about three weeks on a project before someone pointed out that I hadn't specified the conversion in my alignment parameters, which meant the software was trying to match uracil against cytosine as if nothing had happened. The other practical issue is homopolymer runs and secondary structures. If your sequence has a run of four or more identical bases, base pairing becomes unreliable in that region. Polymerases slip, primers form hairpins, and sequencing quality drops off. I've seen whole reads become unusable because a poly-A stretch caused the sequencer to lose phasing. The workaround is usually to redesign the primer to avoid the problematic region entirely, which means you need to look at the actual sequence context rather than just optimizing for generic parameters like length and GC content. Electrophoresis gels also reveal things about base pairing that you wouldn't predict from sequence alone. A perfectly complementary duplex and a duplex with a single internal bulge can migrate at noticeably different rates, but only if you're running the gel at the right voltage and for long enough. Short runs on high-percentage gels make it hard to distinguish. This came up when I was checking ligation products and couldn't tell whether the insert had gone in correctly or not. Running the gel longer at a lower voltage resolved the bands enough to see the size difference.
If you want a practical tool, the IDT OligoAnalyzer is reliable for calculating Tm and checking for secondary structures. For more advanced work, the nearest-neighbor parameters from SantaLucia are the standard reference. Don't rely on older formulas unless you have a good reason. They underestimate Tm for GC-rich sequences and can throw off your entire primer design strategy. I switched to the SantaLucia parameters a while back and noticed my annealing temperatures became much more consistent across different primer sets. It didn't change my results dramatically, but it did save time on optimization runs. Mismatch tolerance also varies depending on the enzyme. Some polymerases are more forgiving of mismatches at the 3' end than others. High-fidelity enzymes tend to be stricter, which is why they're recommended for cloning but can be problematic when you're working with degenerate primers or mutated templates. Taq polymerase, on the other hand, will extend past a mismatch pretty readily, which is useful for certain applications but terrible if you're trying to maintain specificity. Pick your enzyme based on what you actually need rather than what's convenient. The one scenario where all of this breaks down is when you're working with non-canonical base pairs or synthetic nucleotides. Things like 5-methylcytosine or locked nucleic acids have different pairing properties than standard bases, and most online calculators don't account for them properly. I ran into this when a collaborator sent me primers with LNA modifications and the Tm predictions were completely wrong. We ended up determining the actual annealing temperature empirically, running a gradient PCR from fifty-five to sixty-five degrees. It took two days instead of an hour, but at least we got clean results.
Get the Full Details
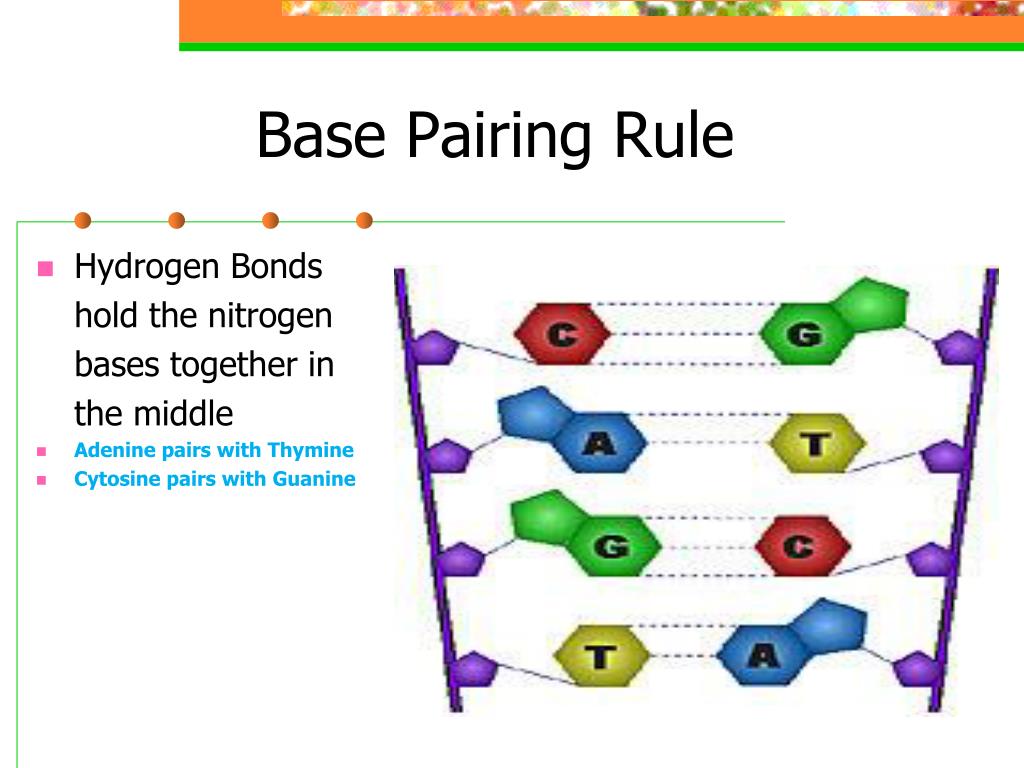
Base pairing in DNA is fundamentally straightforward. The complications come from everything that happens after you leave the idealized classroom model. Real sequences have structure, modifications, and edge cases that no single formula captures. The practical approach is to understand the basics well enough to know when they don't apply, then rely on empirical validation rather than theoretical predictions alone.