Picking The Right Statistical Test
Most people walk into this completely backwards. They look at their data first, then try to figure out which test to run. The correct order is the opposite: define your research question and study design before you even open the dataset. The Parametric And Non Parametric Test decision comes after that, not before. I spent six months last year working on a clinical trial analysis where every single test I ran came out significant. P-values everywhere. Clean forest plot. Beautiful. Then my statistician looked at me and asked one question: "What does your distribution actually look like?" We had about 400 patients, but the outcome variable was heavily right-skewed. The t-tests were valid technically because of the central limit theorem, but the effect sizes were distorted in ways that made clinical interpretation almost meaningless. I switched everything to Mann-Whitney U tests and bootstrapped confidence intervals. The conclusions changed slightly but they were honestly more useful for the people reading the paper. Here is what nobody tells you about parametric tests: they are remarkably robust to violations of normality when your sample size is above 30 or so. The bigger problem is usually heteroscedasticity, or unequal variances between groups. That will bite you far more often than non-normality will. Levene's test for equality of variances should be your first stop, not your afterthought.
How To Actually Decide Between Parametric And Non Parametric Test
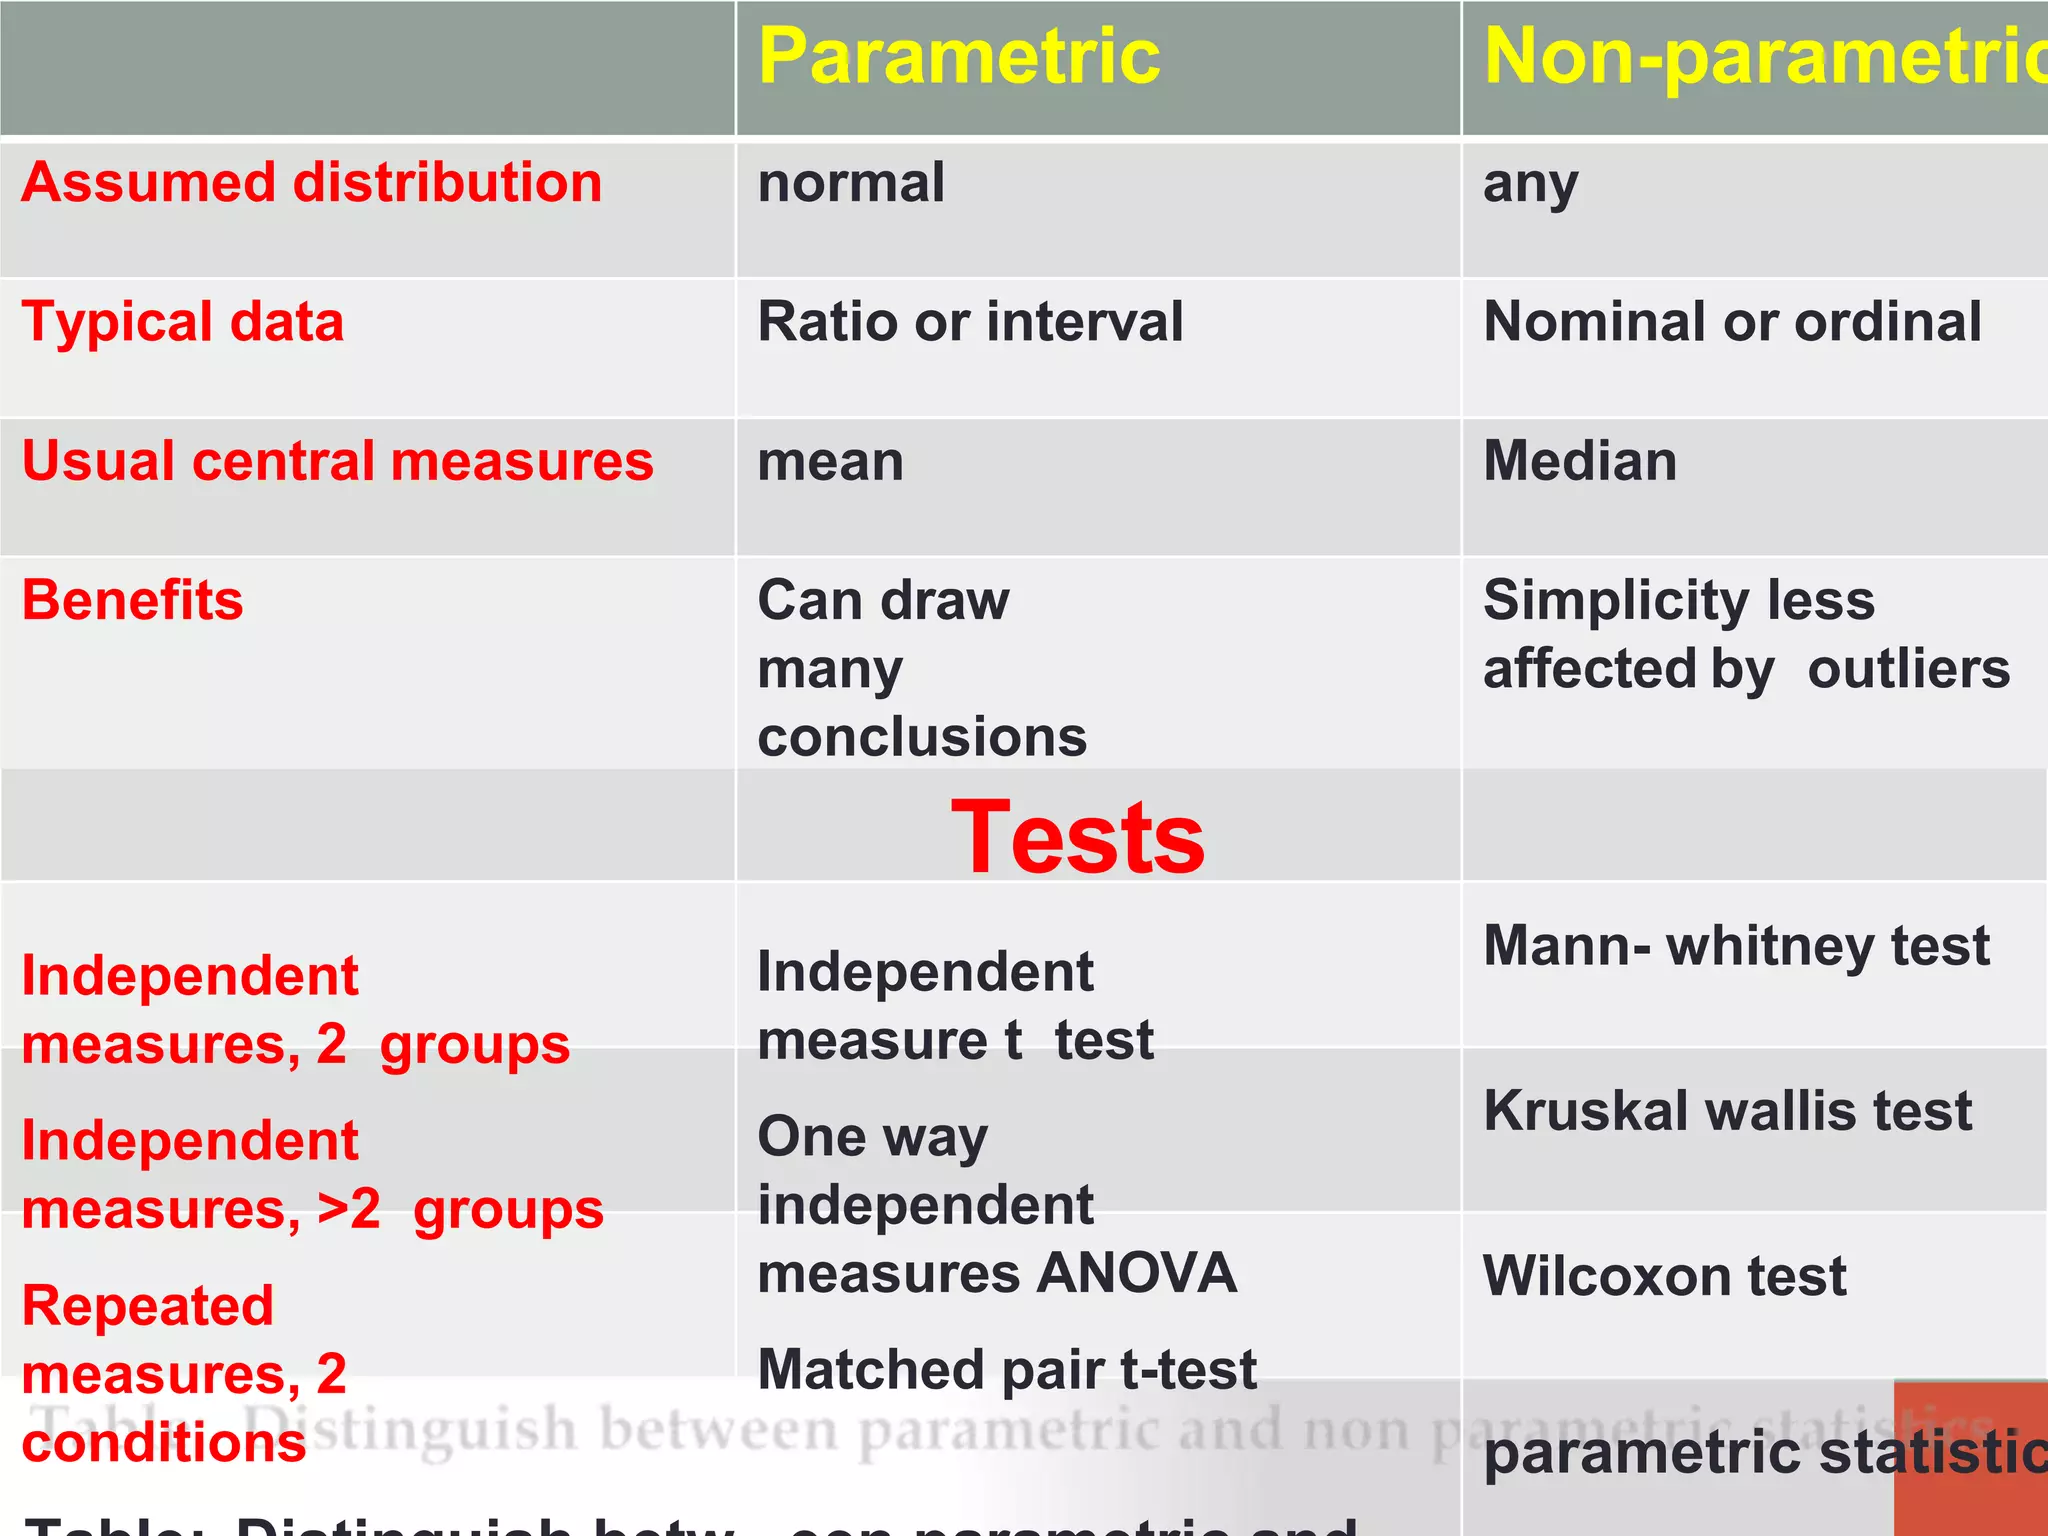
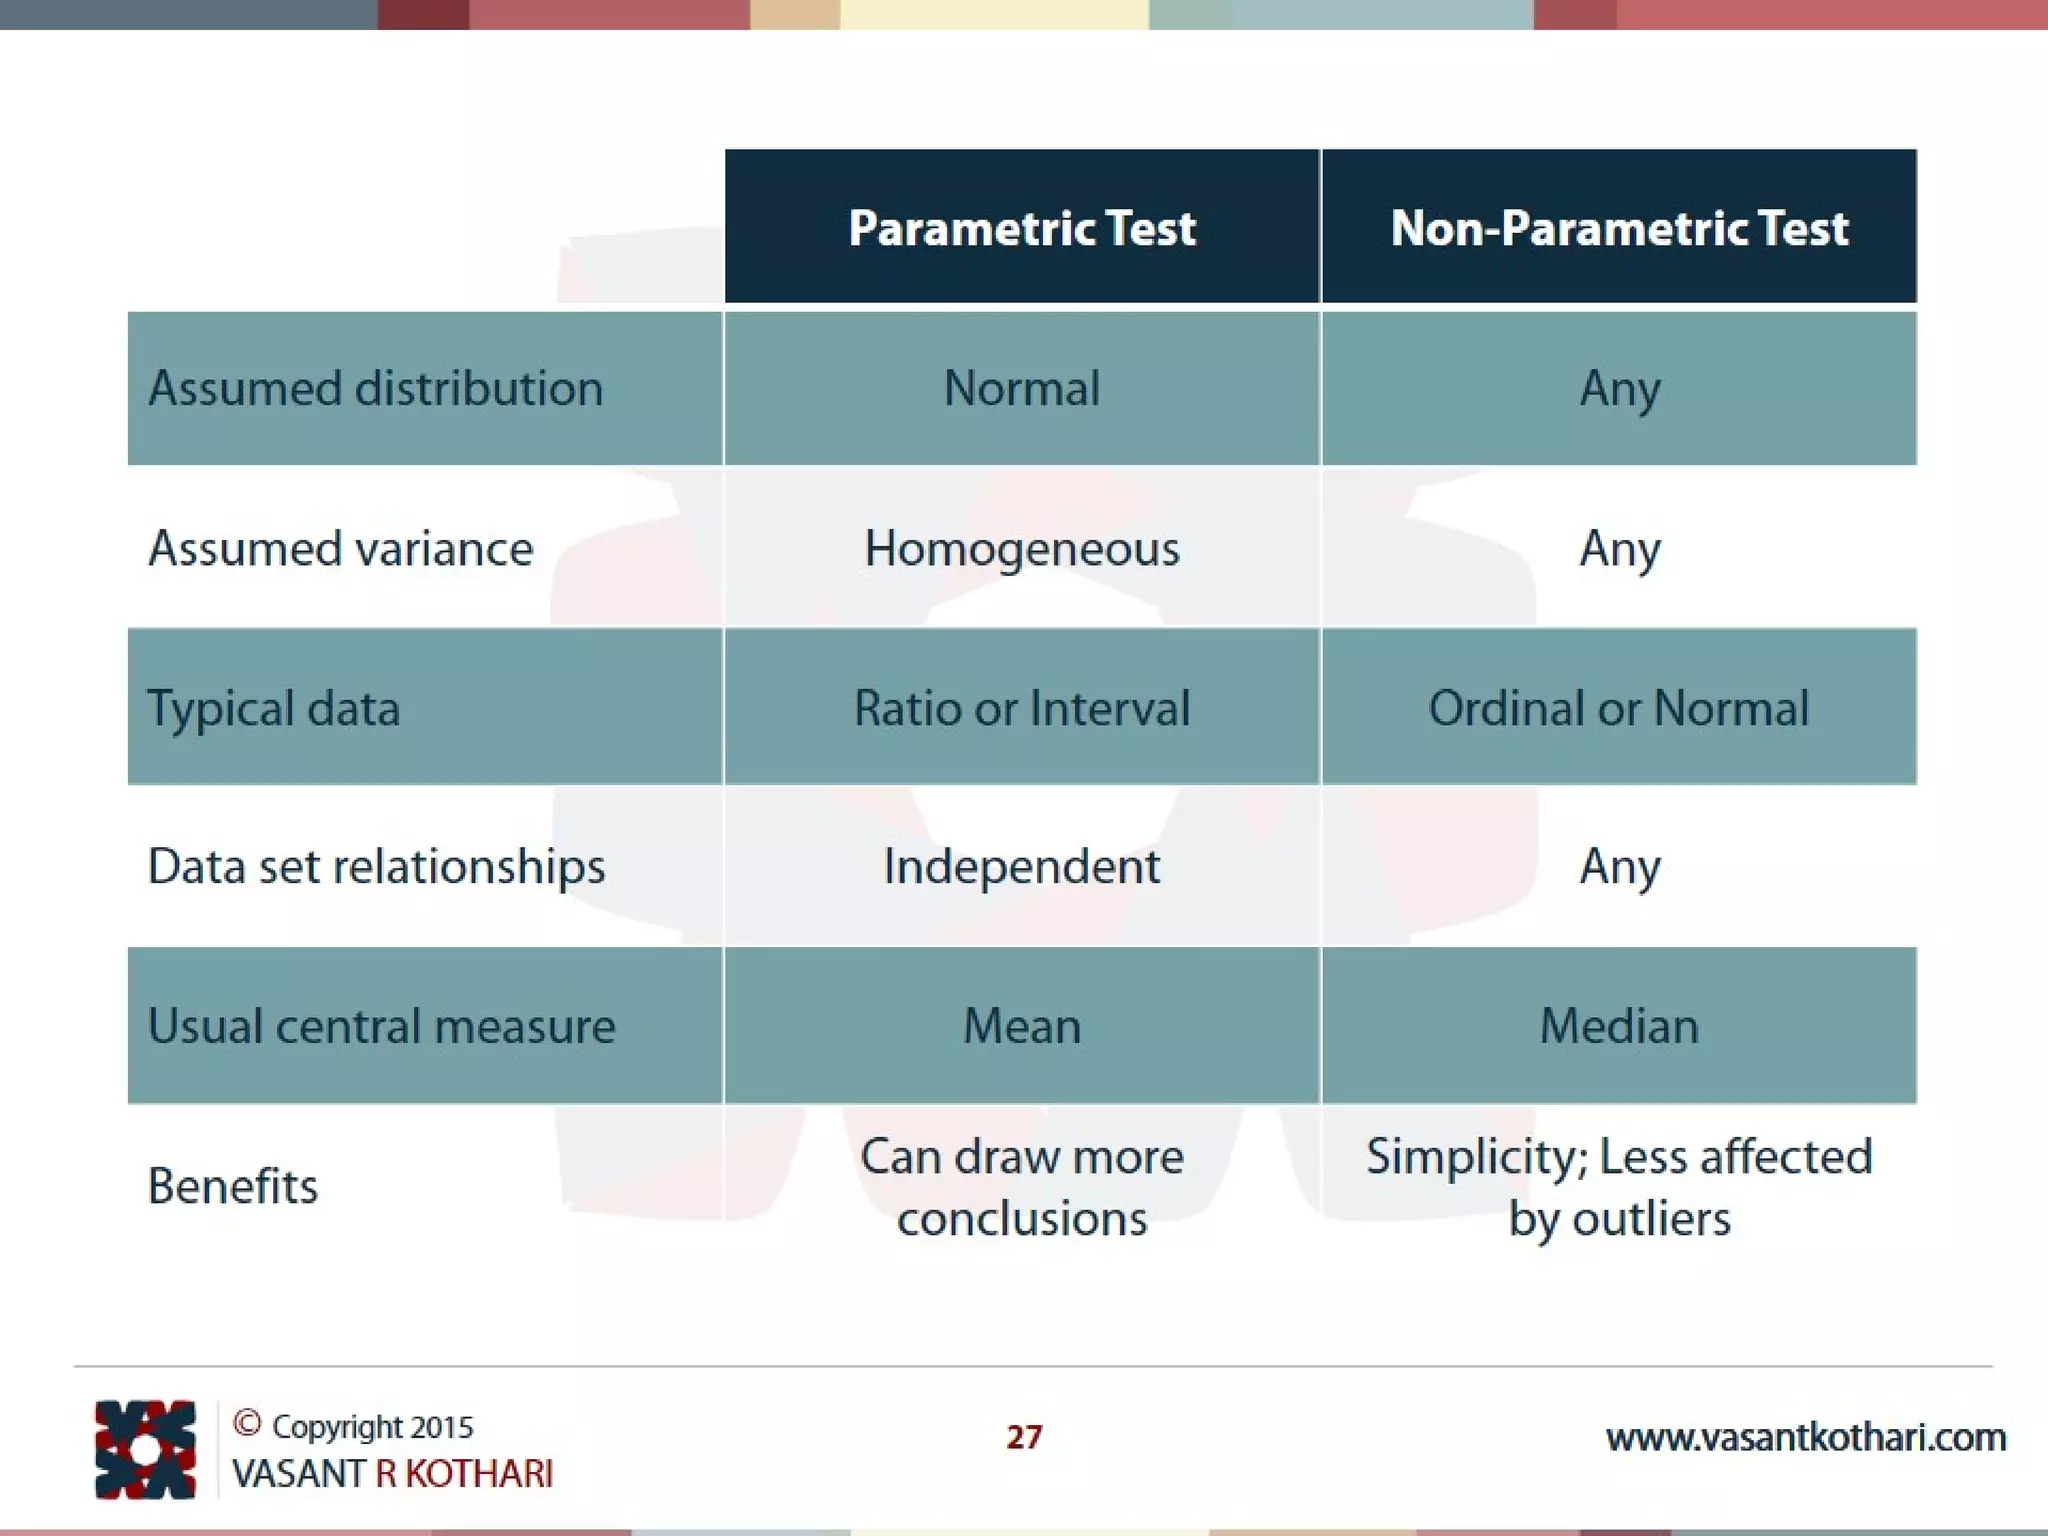
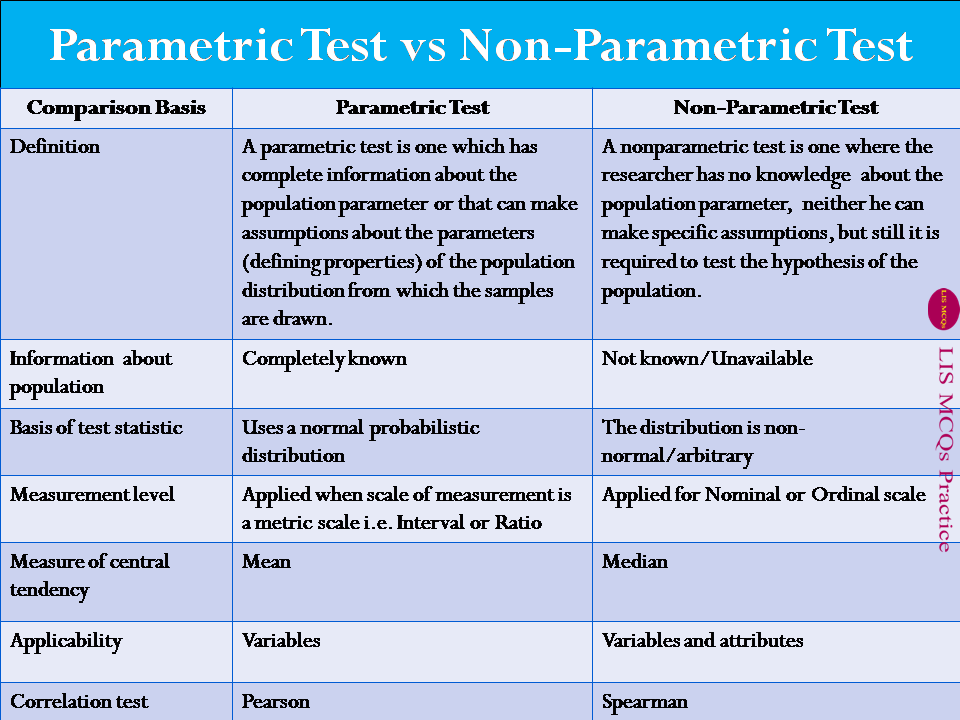
Start by asking yourself three questions. First, what level of measurement are you working with? Ratio and interval data can go either direction. Ordinal data basically forces you toward non-parametric methods unless you have strong reasons to believe the underlying construct is continuous. Second, do you know anything about the population distribution? If you are pulling data from a published database or a previously validated instrument, check the literature. Sometimes the assumption is already documented for you. Third, what is your sample size? Small samples under 20 per group make distributional assumptions much harder to verify and much more consequential. The standard parametric tests you need to know about are the t-test for comparing two means, the ANOVA for comparing three or more means, and Pearson correlation for linear relationships. Each one carries assumptions. Independent samples t-test assumes normality within each group and homogeneity of variance. Paired t-test has the same normality requirement but applies to the difference scores. One-way ANOVA extends all of this to multiple groups and adds the assumption of homogeneity across all groups simultaneously. Violating any of these does not automatically invalidate your results, but it does shift the burden of proof onto you to justify your choice. Non-parametric tests make fewer assumptions about the underlying distribution. The Mann-Whitney U test replaces the independent samples t-test. The Wilcoxon signed-rank test replaces the paired t-test. The Kruskal-Wallis H test replaces one-way ANOVA. Spearman's rho replaces Pearson correlation. They operate on ranks rather than raw values, which is why they are sometimes called rank-based tests. This makes them robust to outliers and distributional shape, but it also means you are testing slightly different hypotheses. Mann-Whitney is not testing whether two means are equal. It is testing whether one distribution is stochastically larger than the other. The distinction matters when you write up your methods section.
Common Pitfalls That Waste Hours Of Analysis
I see the same mistakes repeatedly in papers and in my own early work. The biggest one is applying a parametric test to ordinal data just because it is convenient. Likert scale data is ordinal, not interval. Running a t-test on a five-point scale gives you numbers that look precise but rest on shaky ground. Use Mann-Whitney or ordinal logistic regression instead. Another common error is running multiple parametric tests without adjusting for multiple comparisons. If you run five t-tests at alpha 0.05, your family-wise error rate is roughly 0.23. That is not theoretical, that is basic probability. Bonferroni correction is conservative but simple. Holm-Bonferroni is better. False discovery rate control is best when you have a large number of comparisons and care about discovery rather than strict error control. There is also a persistent myth that non-parametric tests are always "safer" because they have fewer assumptions. That is not true. Every statistical test has assumptions. Non-parametric tests just have different ones. The Mann-Whitney U test assumes that the two distributions have the same shape under the null hypothesis. If your groups differ in variance but not in location, the test can give misleading results. Check that assumption. Box's M test for ANOVA is another thing people skip, and they should not. It detects heterogeneity of covariance matrices, which is the assumption behind MANOVA, not just univariate tests.
Get the Full Details
Practical Workflow For Choosing Your Test
Here is the process I actually use now, after wasting weeks on the wrong approaches early in my career. First, graph your data. Histograms, Q-Q plots, boxplots. A visual inspection catches problems that formal tests miss. Shapiro-Wilk is the standard normality test, but with large samples it will tell you everything is non-normal even when the deviation from normality is trivial. With small samples it lacks power and will happily accept non-normal data as normal. Trust the plot more than the p-value from Shapiro-Wilk. Second, check homogeneity of variance. Levene's test for t-tests and ANOVA. If your variances are significantly different, use Welch's correction for t-tests and Games-Howell post-hoc for ANOVA. These adjustments are built into most statistical software and take about thirty seconds to request. Third, decide on the test. If your data looks approximately normal and variances are equal, go parametric. If not, go non-parametric. If you are borderline, consider bootstrapping. It works with parametric frameworks and gives you empirical confidence intervals without relying on distributional assumptions. Fourth, run the test and report the effect size. P-values alone tell you almost nothing about practical significance. Cohen's d for t-tests, eta-squared or partial eta-squared for ANOVA, r for Mann-Whitney and Spearman. A p-value of 0.001 with a Cohen's d of 0.1 is statistically significant and practically irrelevant. I have seen this exact result published in high-impact journals and it made mequestion the entire field's reliance on null hypothesis significance testing.
When Parametric And Non Parametric Test Choices Get Complicated
Sometimes you have mixed data types. Continuous outcomes with categorical predictors and continuous covariates. That is an ANCOVA situation, and the parametric assumptions apply to the residuals, not to your raw variables. Check the residuals, not the distributions of your inputs. This is a nuance that tripped me up for years. The dependent variable does not need to be normal. The residuals do. Run a regression with your covariates and check the residual distribution instead of testing each variable separately. Another edge case that caught me recently involved survival data. Kaplan-Meier curves looked wildly different between two groups, but the log-rank test gave a marginal p-value around 0.06. I wanted to declare significance. Instead I checked the proportional hazards assumption and found that the hazard functions crossed. The groups were similar for the first six months and then diverged sharply. Log-rank test assumes proportional hazards, which was violated here. I switched to a weighted log-rank test that gave more weight to early differences, and the result became clearly significant. This is the kind of thing that only matters when you care about the actual science and not just the p-value.
Software Notes
R handles all of this well if you know the syntax. spss and jamovi are more beginner-friendly with their point-and-click interfaces. jAMOVI in particular has a nice module for non-parametric tests that shows you the assumptions being checked alongside the results. Python's scipy library covers the basics but feels clunky for anything beyond simple tests. If you are doing a lot of this work, learn R properly. The learning curve is steep but it pays off within a few weeks. The time investment is roughly 20 to 30 hours of focused practice to reach comfort level. Read through your output carefully. Software will happily run a t-test on any two columns you throw at it without warning you about violations. The assumption checks are usually one additional line of code or one checkbox in the GUI. Use them. Your results will be more defensible and your readers will not waste time asking questions you could have answered yourself.