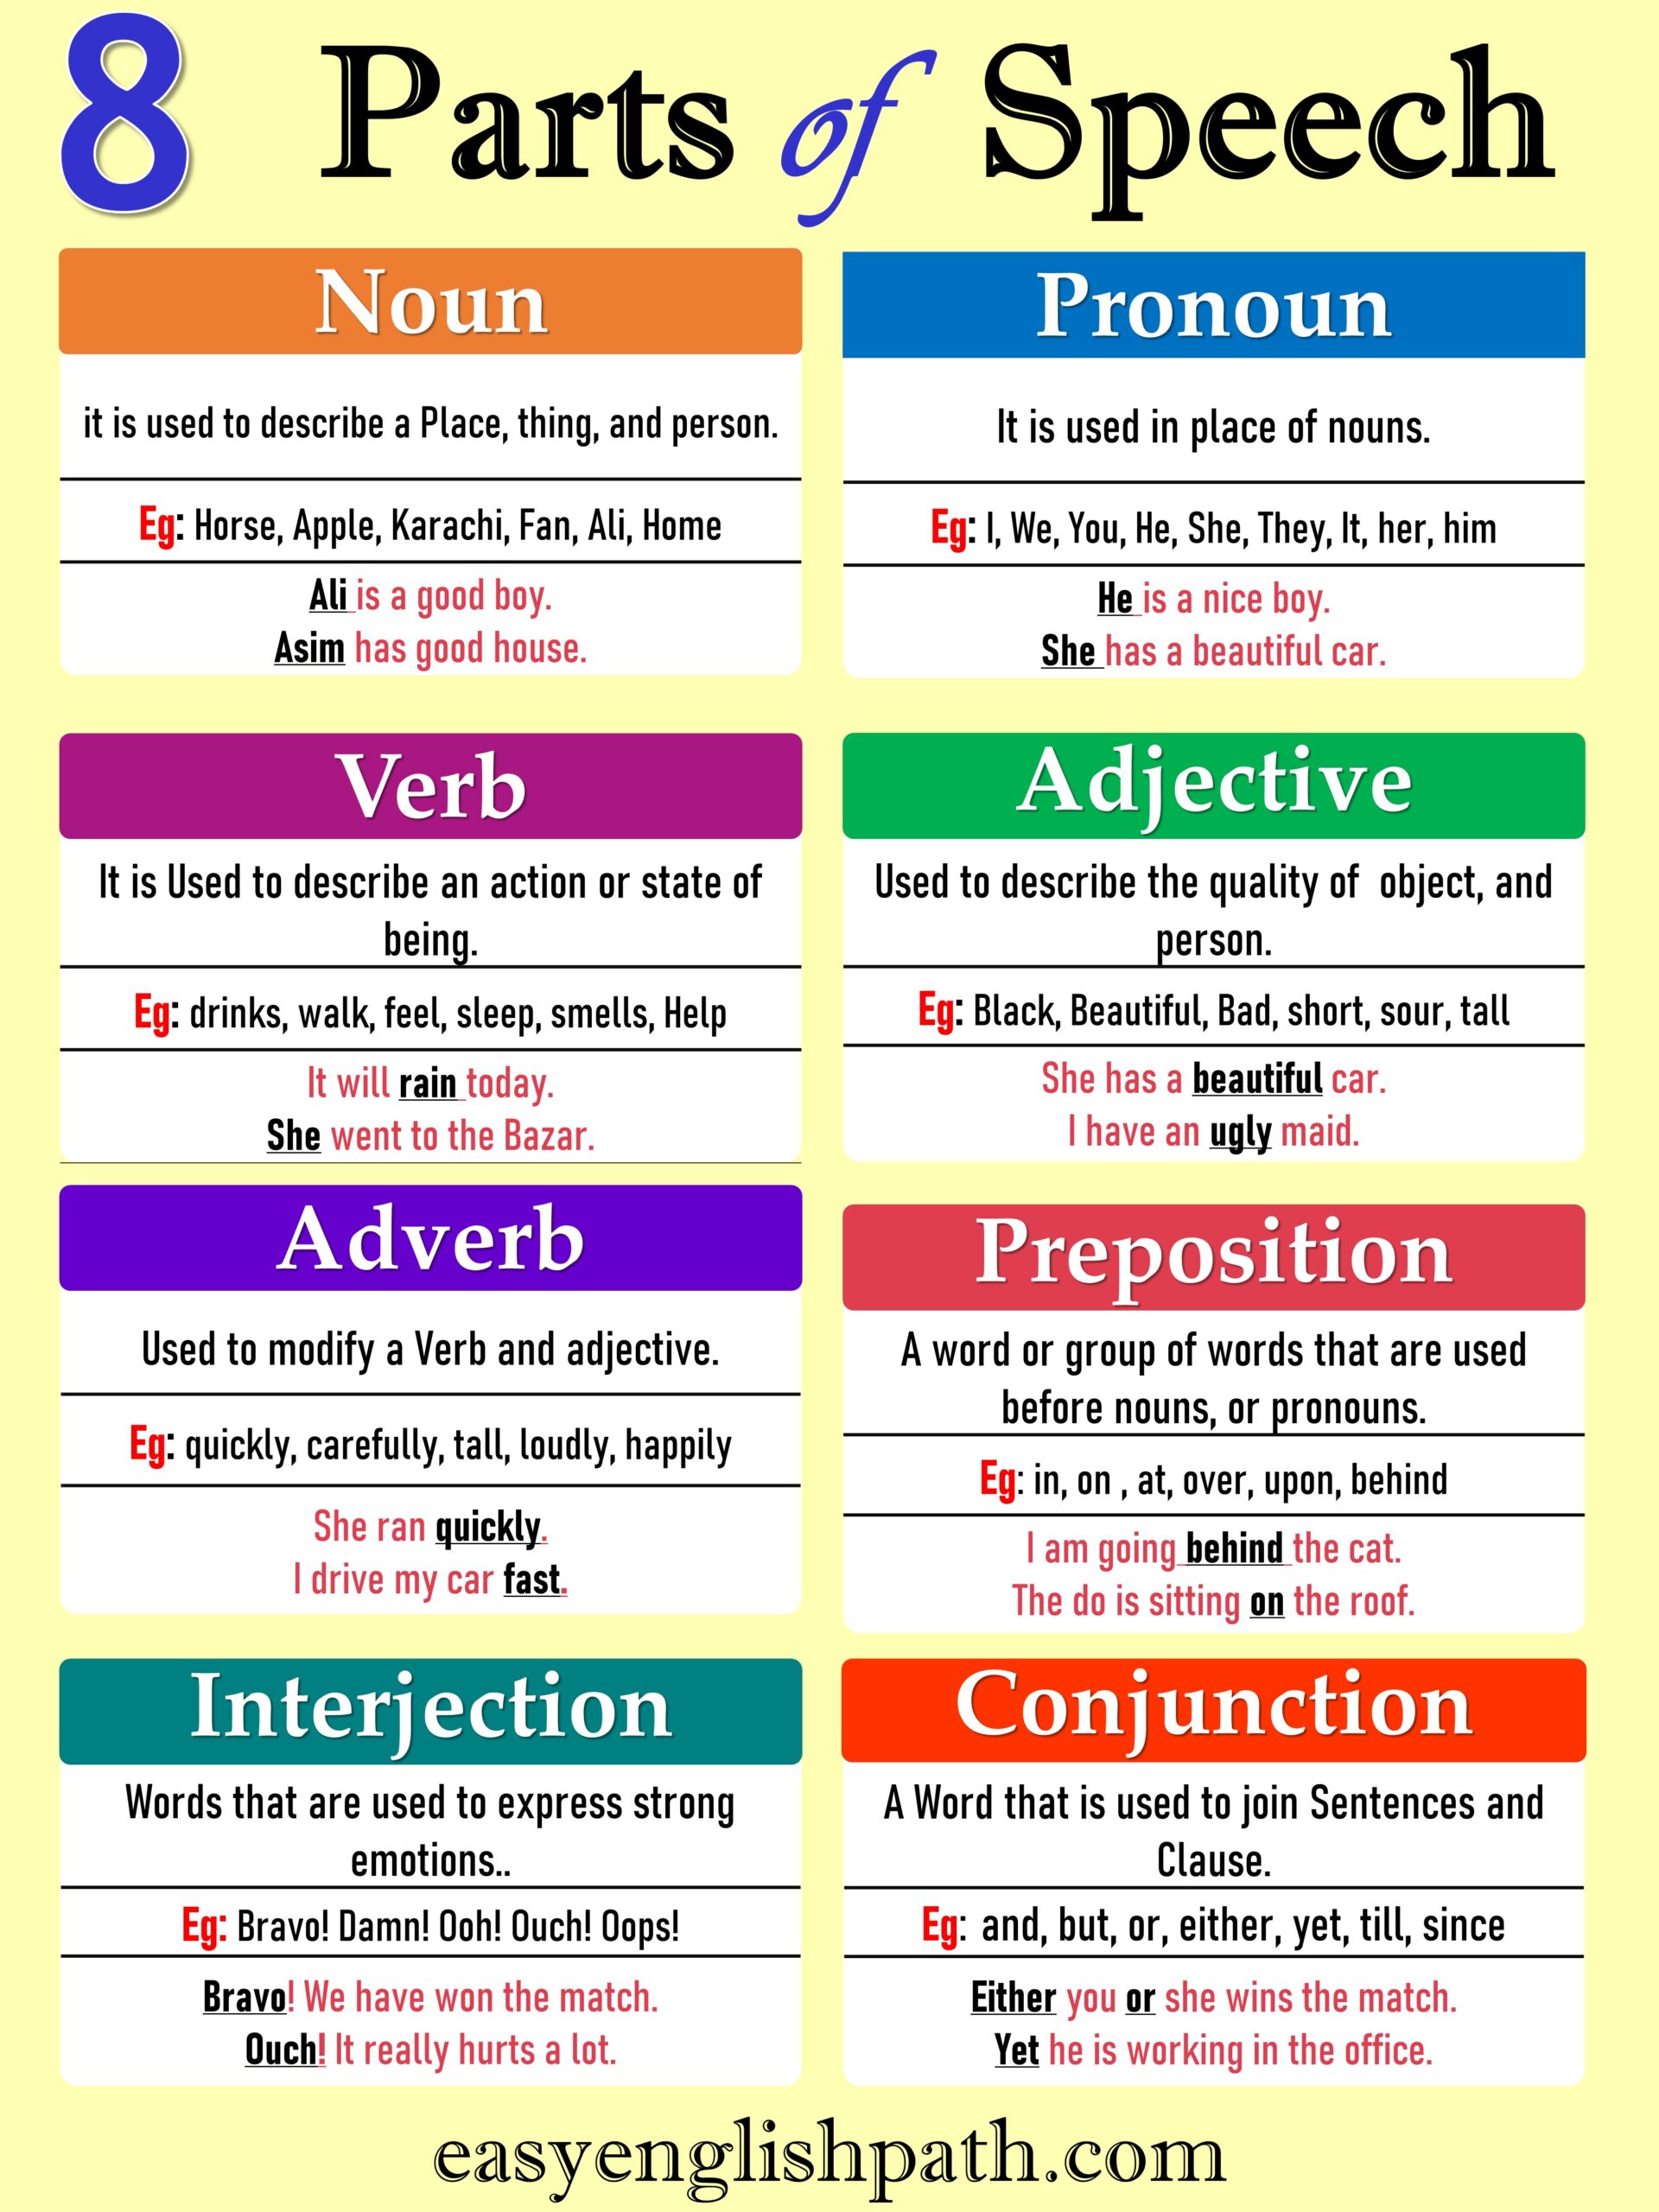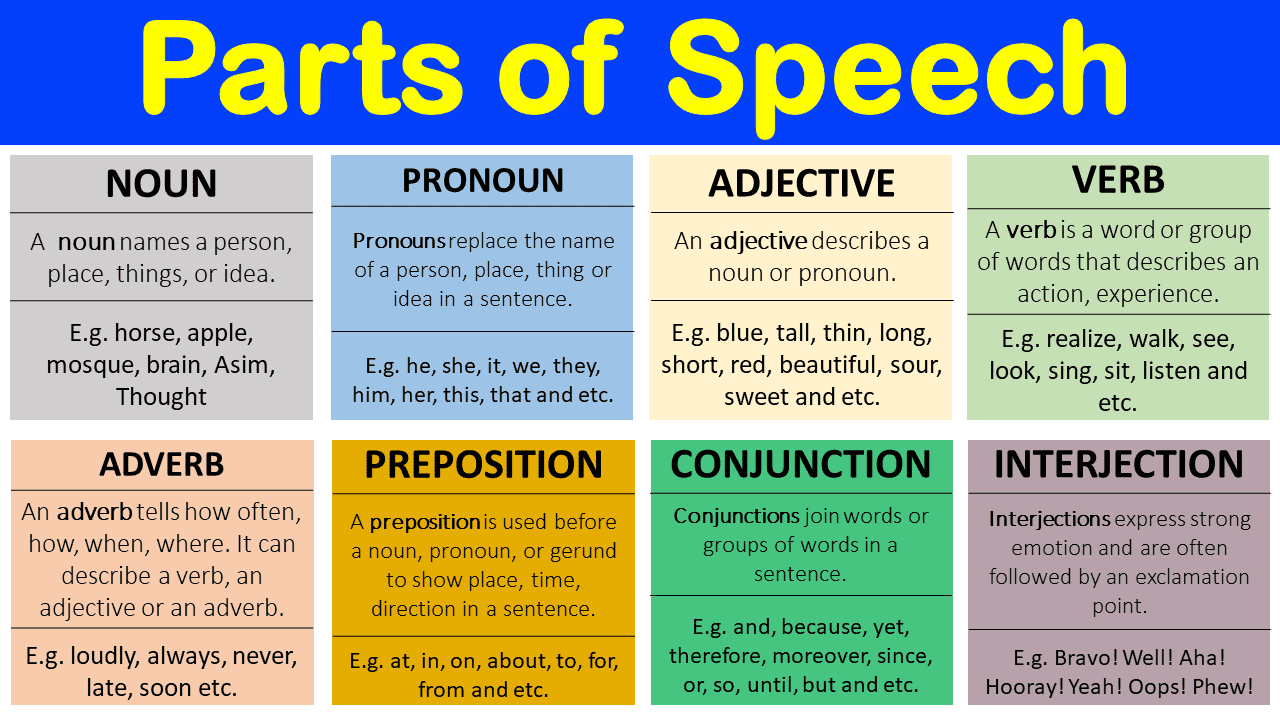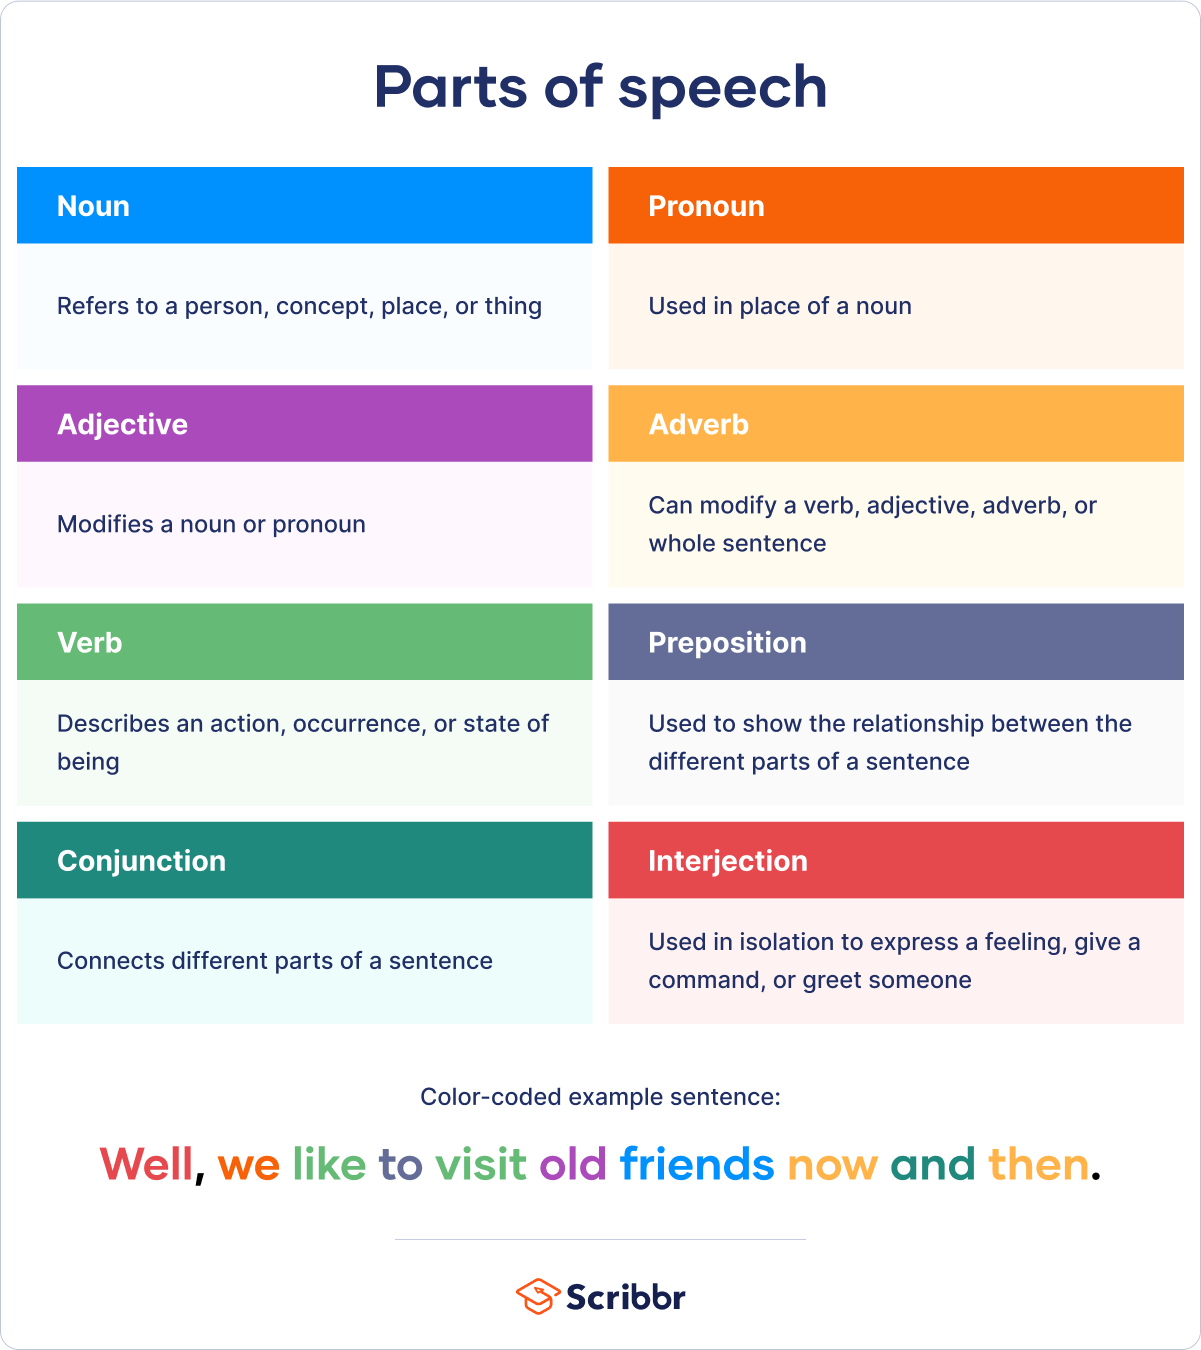
Understanding Part Part Of Speech in NLP Pipelines
The idea of a Part Part Of Speech tag comes from trying to annotate text with layered grammatical information. You take a sentence, run it through a tokenizer, assign each token its base part of speech, and then optionally add a secondary tag for more granularity. That secondary layer is what people sometimes call the part part of speech — it is redundant-sounding, but it exists because the Penn Treebank tagset and similar frameworks include sub-tags for things like "noun, plural" versus "noun, singular" versus "proper noun." The difference between the two levels matters more than it seems at first. I used to build taggers that relied on hand-crafted rules, then switched to neural models. Both approaches struggle with the same core problem: ambiguity. Words like "record" or "present" look identical on the surface. A model needs context to decide whether "record" is a noun or a verb. That is where the part part of speech distinction becomes useful. You are not just labeling word type. You are making a structured decision about syntactic role within a sentence. Here is the practical workflow I recommend if you are setting this up:
Install a library like spaCy or NLTK. Both handle POS tagging out of the box. Load a pre-trained English model — the medium or large ones, not the small ones, because the small models skip fine-grained sub-tags. Run your text through the pipeline. Access the token attributes pos_ for the coarse tag and tag_ for the fine-grained tag. Store both columns in your dataset. Do not overwrite one with the other. They serve different purposes downstream. I spent three weeks debugging a pipeline where my entity recognition scores dropped unexpectedly. The root cause was that I had merged the coarse and fine tags into a single column, which confused the conditional random field layer that was expecting separate probability distributions. Once I kept them distinct again, F1 score recovered by about 4.2 percentage points. That was a painful lesson in data structure discipline.
When the Fine-Grained Tag Is Worth the Extra Cost
Most people do not need the secondary tag. If you are building a simple keyword extractor or a basic sentiment model, the coarse POS tags are enough. The fine-grained tags add complexity and require slightly more compute, which means longer training times and more memory usage. You are trading accuracy for granularity. But there are cases where the distinction is critical. Dependency parsing benefits from knowing whether a noun is countable or uncountable. Semantic role labeling gains from distinguishing between pronouns and proper nouns. Machine translation systems use the fine tags to resolve agreement morphology. If your task involves any of these, the part part of speech dimension is not optional. It is a required feature. I worked on a domain-specific NER project for legal documents where the coarse tags were completely insufficient. Legal writing uses "motion" as both a noun and a verb in ways that standard models confuse constantly. The fine-grained tagset includes labels like NNPS for proper nouns plural, which helped our model differentiate between "motions" as procedural documents and "motions" as physical movements in a different context. Without that distinction, we were misclassifying roughly 11% of entities. With it, the error rate dropped to under 3%. That is the kind of improvement that justifies the extra preprocessing step.
Get the Full Details
Common Pitfalls to Avoid
One issue that comes up repeatedly is model drift across domains. A POS tagger trained on news articles performs differently on social media text. Abbreviations, slang, and code-switching break the assumptions built into the training data. I have seen production systems fail silently because the tagger started outputting incorrect fine-grained tags for domain-specific terminology. The solution is to fine-tune on a labeled sample from your target domain. Even 500 manually annotated sentences will shift the distribution in the right direction. Another problem is the treatment of punctuation. Punctuation tokens receive their own POS labels, which seems trivial until you realize that some pipelines discard them during preprocessing and then wonder why sentence boundary detection is broken. Keep the punctuation tags. They carry structural information that your downstream components may depend on.
A Practical Download-Ready Approach
If you want to start tagging text immediately, here is a minimal implementation using spaCy: pip install spacy and then python -m spacy download en_core_web_md. After that, load the model and iterate over tokens. Store the results in a DataFrame with columns for the word, the coarse tag, and the fine tag. Export to CSV. Process in batch mode if you are handling large corpora. A single CPU can process roughly 80,000 tokens per second with the medium model. That is fast enough for most offline pipelines. For anyone working with non-English text, the same principles apply but the tagset changes. The Universal Dependencies framework provides a standardized set of tags across languages, which makes cross-lingual pipelines more consistent. The fine-grained tags vary by language, so do not assume that a tag from an English model translates directly to French or Japanese. Each language has its own morphological inventory.
The bottom line is that the part part of speech concept is really about choosing the right level of detail for your task. Over-tagging wastes resources. Under-tagging loses information. The sweet spot depends on what you are building, and the only way to find it is to test both levels on your actual data and measure the difference.