
Building a Parts Of Speech Quiz With Answer Key That Actually Works
I spent three years trying to build automated grammar quizzes for a linguistics education platform before I figured out that the standard approaches were broken. The core problem isn't generating questions. It's making sure the answer key is defensible when a noun is also a verb, or when a word like "run" shows up in six different forms across a single test item. A Parts Of Speech Quiz With Answer Key requires two separate but linked data structures: the question bank and the key. Most people combine them into one file and regret it immediately. Keep them as distinct CSVs or JSON objects with matching record IDs. When you update one, the other has to shift with it. I use an internal ID system — not the question text itself — because text-based matching fails the moment someone changes a comma or swaps a conjunction for clarity. You also need a word-level tagset. Penn Treebank works for most purposes. Universal Dependencies is better if your audience spans multiple languages. If you're using NLTK or spaCy under the hood, stick to whatever tagset your NLP library natively resolves, or you'll spend your time converting tags instead of writing questions.
The setup phase usually takes about four to six hours for a basic 50-item quiz. I've seen people blow two weeks on the same scope because they didn't pin down the tagset before writing a single item. Don't do that.
The Question Generation Methods
There are three ways to generate the items, and each has a different failure mode. Rule-based generation. You write grammatical rules and let the parser apply them. A word following a determiner becomes a noun. A word before a verb phrase becomes an adjective. This is the fastest method and costs nearly nothing in compute. The downside is that it produces mechanical questions that native speakers can still answer correctly by pattern-matching rather than actual analysis. Students learn the quiz's structure, not the language. Corpus extraction. You pull sentences from a tagged corpus, strip the tags from target words, and present the sentence as the question. This produces realistic items. The problem is availability. Properly annotated corpora are large, and filtering for the exact POS distribution you need requires SQL queries that most people aren't set up to run. I ended up using the Wall Street Journal section of the Penn Treebank with a custom script that sampled sentences by dependency path length. It took about ten hours to generate 200 candidates and manually triage them down to 80.
Get the Full Details
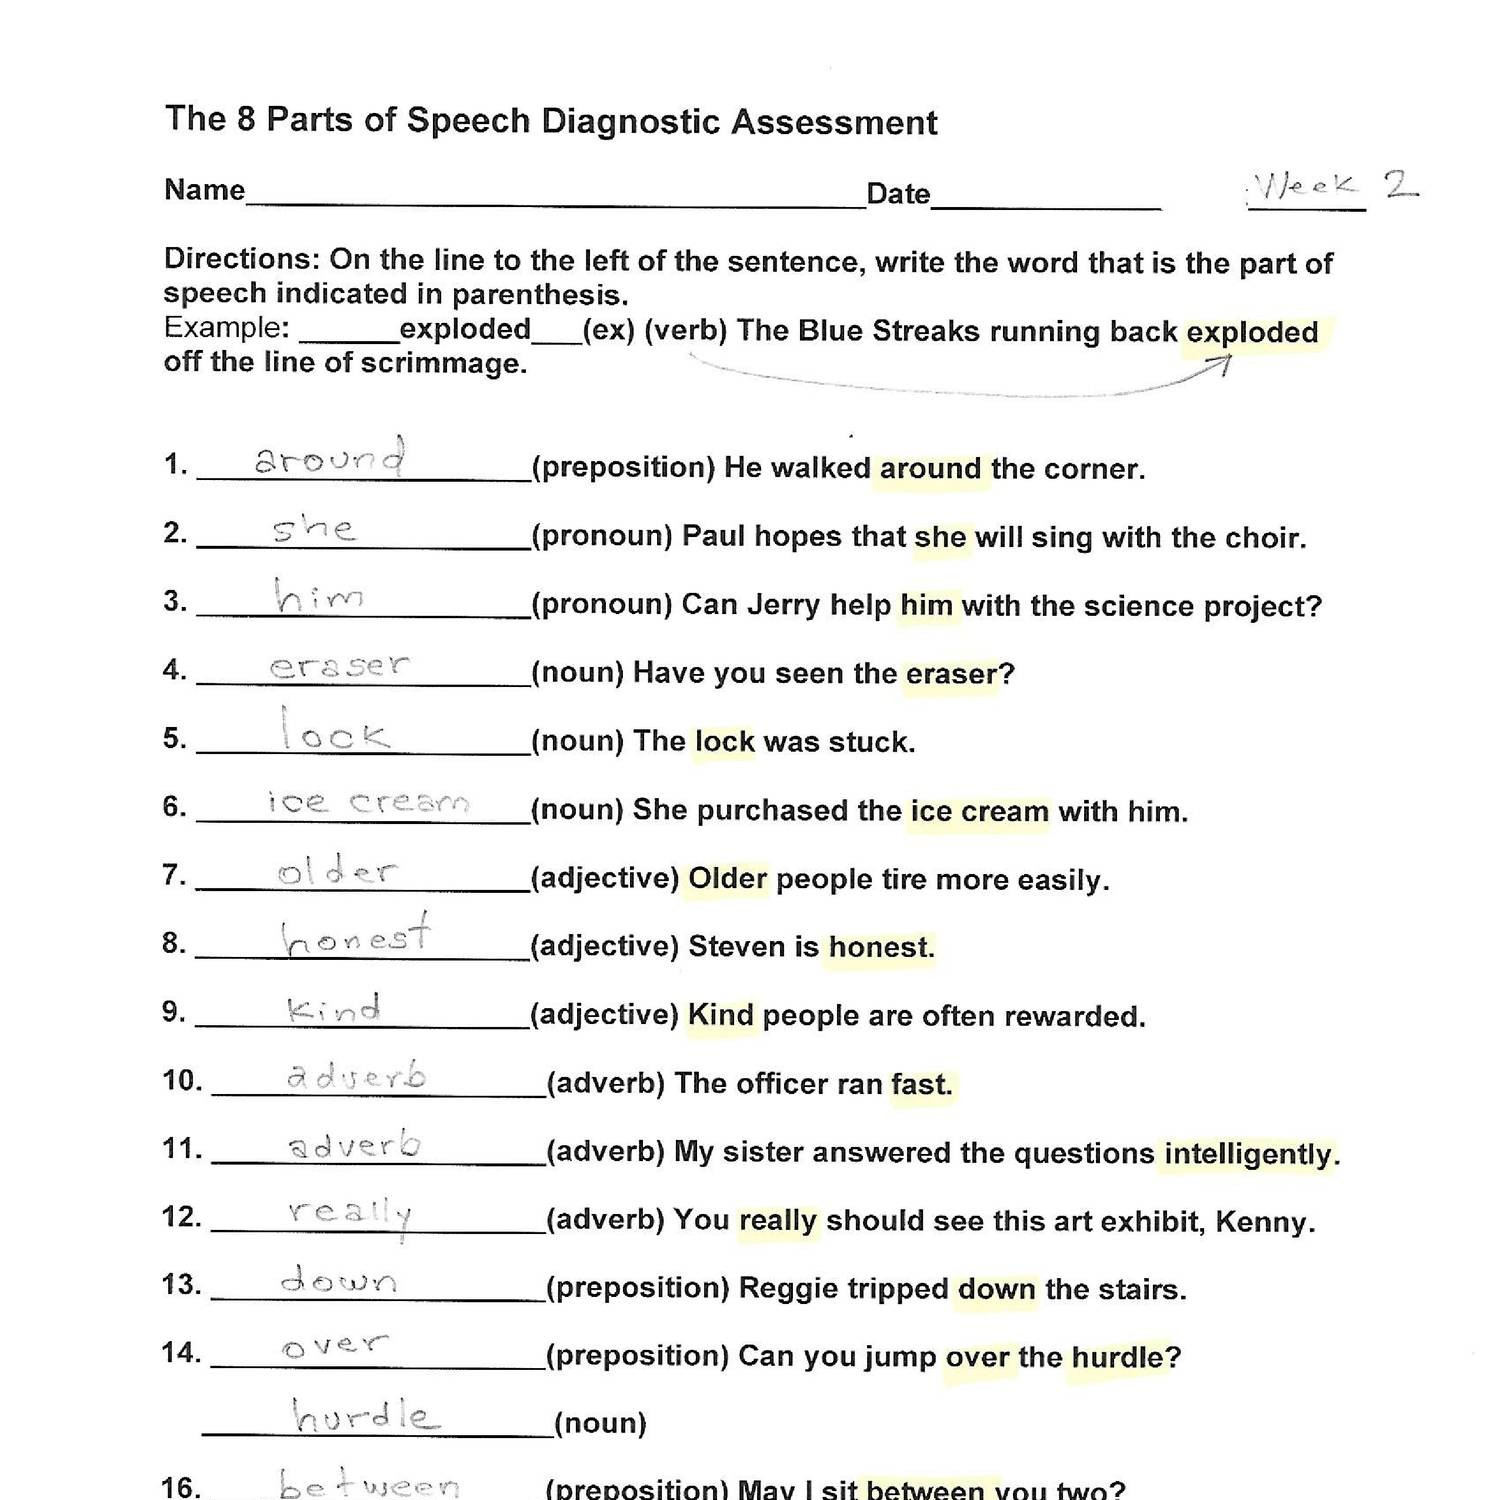
Hybrid approach. This is what I use now. I generate 60 percent of items from the corpus and 40 percent from hand-written templates targeting specific confusion points — gerunds versus participles, subordinate clauses versus relative clauses, prepositions versus subordinating conjunctions. The template items address the edges that corpus sampling naturally misses.
Writing the Answer Key
The answer key isn't just a list of correct choices. It needs to contain the expected POS label, the lemma if relevant, and a reason field. Without the reason field, you can't debug why a student got an item wrong, and without the lemma, you can't handle inflected forms consistently. "Running" and "runs" are both VERB when used predicatively, but a naive string-match key would treat them as different answers. I structure the key as a lookup table keyed by the internal question ID. Each entry has the canonical answer, the accepted variants (including alternate labels like NOUN vs. NN depending on your tagset), and the explanation. This takes longer upfront — maybe three extra hours for a 50-item quiz — but it cuts post-administration debugging from hours to minutes.
Edge Cases That Break Everything
The hardest item I ever encountered involved the word "fast." It can be an adjective ("the fast car"), an adverb ("he ran fast"), or a verb in technical contexts ("to fast from food"). In a sentence like "The clock is fast," a parser will tag it as an adjective. But "fast" as an adverb is actually quite common and often misidentified by both learners and tools. I had to write a custom disambiguation rule that checked whether the word modified a verb or a noun phrase before locking in the answer. This added about 45 minutes to my pipeline but prevented a whole class of false negatives. Another persistent problem is function words. Words like "that," "which," and "where" shift between relative pronouns, subordinating conjunctions, and complementizers depending on syntactic context. The Penn Treebank tags them differently in each role, which means your answer key has to be context-sensitive. A single static answer key can't handle this. I ended up storing the syntactic frame alongside each question so the key could resolve the correct label based on position and dependency relation.

Validation and Error Rates
Before you release anything, run a pilot. I don't mean a quick glance. I mean having at least three people with formal linguistics training take the quiz blind and report which items felt ambiguous or incorrect. In my experience, this catches about 15 to 25 percent of problematic items on the first pass. You then revise and repeat until the inter-rater disagreement drops below 5 percent. Expect to spend roughly equal time on validation as you did on generation. A 50-item quiz that takes four hours to build usually needs another four hours to validate and refine. If you're working solo, budget a full day minimum.
Common Pitfalls to Avoid
Don't mix tagset versions within the same quiz. If your questions use Penn Treebank fine-grained tags and your key uses Universal Dependencies coarse tags, the matching logic will fail silently on about a third of items. Always normalize to one schema before distributing. Don't include items where the part of speech depends on pronunciation. Homographs like "record" (noun vs. verb) create genuinely ambiguous items unless you add audio or explicit pronunciation guides. Most automated systems can't handle this, and even skilled students second-guess themselves. Remove them or mark them as bonus items with dual-key support. Don't rely on auto-generated keys without manual verification. Even spaCy with the best-trained model hits about 94 percent accuracy on POS tagging in the wild. That 6 percent error rate compounds across 100 items. You will have six wrong answers in your key unless you check them yourself.
Putting It Together
The final deliverable should be two files: the question set and the answer key, both exported as JSON for easy integration into any quiz platform. Include the internal IDs in both files so they can be joined programmatically. Add a metadata section that records the tagset used, the generation method, and the date of last review. This matters more than people realize because POS annotation standards evolve, and old keys become inaccurate without a paper trail. If you're distributing this publicly, include a brief methodology note. It doesn't need to be long. Just enough for someone to understand whether your label choices align with their own framework. Mismatches between educational standards and annotation schemes are the silent killer of quiz validity, and they're almost never discussed in documentation. A realistic timeline for a clean, validated 50-item Parts Of Speech Quiz With Answer Key is one to two days of focused work. The process is straightforward until it isn't, and the moments it isn't are the ones that determine whether the quiz actually measures what you think it measures.


